docassert 0.7.0__tar.gz → 0.7.1__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {docassert-0.7.0/docassert.egg-info → docassert-0.7.1}/PKG-INFO +4 -2
- {docassert-0.7.0 → docassert-0.7.1}/README.md +3 -1
- {docassert-0.7.0 → docassert-0.7.1}/docassert/__init__.py +1 -1
- {docassert-0.7.0 → docassert-0.7.1}/docassert/cli.py +7 -6
- {docassert-0.7.0 → docassert-0.7.1}/docassert/report.py +10 -5
- docassert-0.7.1/docassert/status/__init__.py +26 -0
- docassert-0.7.1/docassert/status/derive.py +231 -0
- docassert-0.7.0/docassert/status.py → docassert-0.7.1/docassert/status/render.py +10 -235
- {docassert-0.7.0 → docassert-0.7.1/docassert.egg-info}/PKG-INFO +4 -2
- {docassert-0.7.0 → docassert-0.7.1}/docassert.egg-info/SOURCES.txt +3 -1
- {docassert-0.7.0 → docassert-0.7.1}/pyproject.toml +2 -2
- {docassert-0.7.0 → docassert-0.7.1}/LICENSE +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/NOTICE +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/__main__.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/consistency.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/adr.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/benefits-realization.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/brd.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/business-case.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/charter.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/data-migration-plan.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/frnfr.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/hypercare-plan.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/post-implementation-review.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/prd.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/project.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/qa-test-plan.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/raci-stakeholder.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/release-cutover-plan.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/risk-register.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/rollback-plan.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/runbook.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/status-report.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/test-cases.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/user-story.criteria.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/profiles/agile-delivery.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/profiles/lean-startup.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/profiles/regulated-industry.yaml +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/adr.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/benefits-realization.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/brd.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/business-case.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/charter.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/data-migration-plan.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/frnfr.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/hypercare-plan.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/post-implementation-review.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/prd.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/project.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/qa-test-plan.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/raci-stakeholder.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/release-cutover-plan.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/risk-register.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/rollback-plan.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/runbook.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/status-report.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/test-cases.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/user-story.schema.json +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/skills/doc-to-pmo/SKILL.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/adr.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/benefits-realization.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/brd.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/business-case.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/charter.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/data-migration-plan.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/frnfr.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/hypercare-plan.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/post-implementation-review.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/prd.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/project.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/qa-test-plan.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/raci-stakeholder.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/release-cutover-plan.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/risk-register.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/rollback-plan.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/runbook.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/status-report.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/test-cases.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/user-story.template.md +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/config.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/consistency.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/extract.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/graph.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/loader.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/models.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/profiles.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/projects.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/rtm.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/scaffold.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/semantic.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert/structural.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert.egg-info/dependency_links.txt +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert.egg-info/entry_points.txt +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert.egg-info/requires.txt +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/docassert.egg-info/top_level.txt +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/setup.cfg +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_badge.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_config.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_consistency.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_defects.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_draft_relaxation.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_extract.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_graph.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_json_report.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_kinds_delivery.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_kinds_governance.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_kinds_operate.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_kinds_reporting.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_profiles.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_projects.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_scaffold.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_status.py +0 -0
- {docassert-0.7.0 → docassert-0.7.1}/tests/test_structural.py +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: docassert
|
|
3
|
-
Version: 0.7.
|
|
3
|
+
Version: 0.7.1
|
|
4
4
|
Summary: Unit testing for business documents — validate structured Markdown docs against a configurable audit standard.
|
|
5
5
|
Author: C4G Enterprises Inc.
|
|
6
6
|
License: Apache-2.0
|
|
@@ -44,6 +44,8 @@ Dynamic: license-file
|
|
|
44
44
|
[](https://pypi.org/project/docassert/)
|
|
45
45
|
[](LICENSE)
|
|
46
46
|
|
|
47
|
+
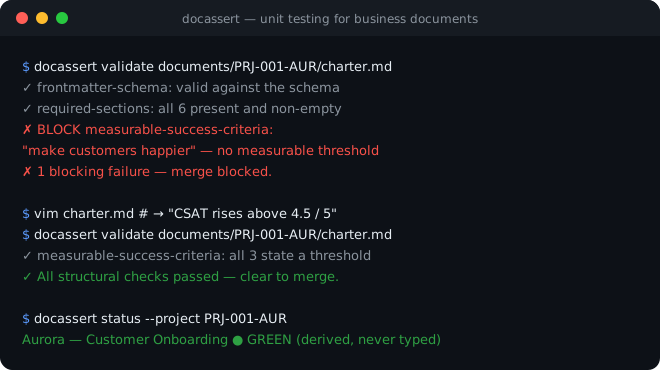
|
|
48
|
+
|
|
47
49
|
**Unit testing for business documents.** Validate structured Markdown documents
|
|
48
50
|
(charters, BRDs, PRDs, risk registers, …) against a configurable audit standard:
|
|
49
51
|
deterministic structural checks that gate a merge, plus optional AI-graded
|
|
@@ -52,7 +54,7 @@ derived from the documents rather than self-reported.
|
|
|
52
54
|
|
|
53
55
|
docassert is the reference implementation of **[PMO as Code](https://c4g-john.github.io/pmo-as-code/)** —
|
|
54
56
|
a vendor-neutral standard for running a PMO from version-controlled, declarative
|
|
55
|
-
files. It implements the [PMO as Code specification](https://github.com/c4g-john/pmo-as-code-spec) **v0.
|
|
57
|
+
files. It implements the [PMO as Code specification](https://github.com/c4g-john/pmo-as-code-spec) **v0.2**.
|
|
56
58
|
|
|
57
59
|
## Install
|
|
58
60
|
|
|
@@ -4,6 +4,8 @@
|
|
|
4
4
|
[](https://pypi.org/project/docassert/)
|
|
5
5
|
[](LICENSE)
|
|
6
6
|
|
|
7
|
+

|
|
8
|
+
|
|
7
9
|
**Unit testing for business documents.** Validate structured Markdown documents
|
|
8
10
|
(charters, BRDs, PRDs, risk registers, …) against a configurable audit standard:
|
|
9
11
|
deterministic structural checks that gate a merge, plus optional AI-graded
|
|
@@ -12,7 +14,7 @@ derived from the documents rather than self-reported.
|
|
|
12
14
|
|
|
13
15
|
docassert is the reference implementation of **[PMO as Code](https://c4g-john.github.io/pmo-as-code/)** —
|
|
14
16
|
a vendor-neutral standard for running a PMO from version-controlled, declarative
|
|
15
|
-
files. It implements the [PMO as Code specification](https://github.com/c4g-john/pmo-as-code-spec) **v0.
|
|
17
|
+
files. It implements the [PMO as Code specification](https://github.com/c4g-john/pmo-as-code-spec) **v0.2**.
|
|
16
18
|
|
|
17
19
|
## Install
|
|
18
20
|
|
|
@@ -300,18 +300,19 @@ def main(argv: list[str] | None = None) -> int:
|
|
|
300
300
|
sp.add_argument("--documents-dir", default=DEFAULT_DOCUMENTS_DIR,
|
|
301
301
|
help=f"Documents tree to read (default: {DEFAULT_DOCUMENTS_DIR}/).")
|
|
302
302
|
|
|
303
|
+
def report_opts(sp: argparse.ArgumentParser) -> None:
|
|
304
|
+
sp.add_argument("--junit", help="Write a JUnit XML report to this path.")
|
|
305
|
+
sp.add_argument("--markdown", help="Write a PR-comment markdown report to this path.")
|
|
306
|
+
sp.add_argument("--json", help="Write a machine-readable JSON report to this path.")
|
|
307
|
+
|
|
303
308
|
v = sub.add_parser("validate", help="Validate documents against their criteria.")
|
|
304
309
|
v.add_argument("paths", nargs="+", help="Markdown files or globs.")
|
|
305
|
-
v
|
|
306
|
-
v.add_argument("--markdown", help="Write a PR-comment markdown report to this path.")
|
|
307
|
-
v.add_argument("--json", help="Write a machine-readable JSON report to this path.")
|
|
310
|
+
report_opts(v)
|
|
308
311
|
docs_dir_opt(v)
|
|
309
312
|
v.set_defaults(func=cmd_validate)
|
|
310
313
|
|
|
311
314
|
c = sub.add_parser("consistency", help="Check cross-document traceability.")
|
|
312
|
-
c
|
|
313
|
-
c.add_argument("--markdown", help="Write a PR-comment markdown report to this path.")
|
|
314
|
-
c.add_argument("--json", help="Write a machine-readable JSON report to this path.")
|
|
315
|
+
report_opts(c)
|
|
315
316
|
c.add_argument("--no-semantic", action="store_true",
|
|
316
317
|
help="Skip AI alignment (structural consistency only).")
|
|
317
318
|
docs_dir_opt(c)
|
|
@@ -12,6 +12,11 @@ _CROSS = "✗"
|
|
|
12
12
|
_DASH = "—"
|
|
13
13
|
|
|
14
14
|
|
|
15
|
+
def _all(results_by_doc: dict[str, list[CheckResult]]) -> list[CheckResult]:
|
|
16
|
+
"""Every result across every document, flattened."""
|
|
17
|
+
return [r for rs in results_by_doc.values() for r in rs]
|
|
18
|
+
|
|
19
|
+
|
|
15
20
|
def _mark(r: CheckResult) -> str:
|
|
16
21
|
if r.kind == "semantic" and r.score is None:
|
|
17
22
|
return "○" # ○ skipped/unavailable
|
|
@@ -31,7 +36,7 @@ def console(results_by_doc: dict[str, list[CheckResult]]) -> str:
|
|
|
31
36
|
|
|
32
37
|
|
|
33
38
|
def summary_line(results_by_doc: dict[str, list[CheckResult]]) -> str:
|
|
34
|
-
blocking = sum(1 for
|
|
39
|
+
blocking = sum(1 for r in _all(results_by_doc) if r.is_blocking_failure)
|
|
35
40
|
docs = len(results_by_doc)
|
|
36
41
|
if blocking:
|
|
37
42
|
return f"{_CROSS} {blocking} blocking failure(s) across {docs} document(s) {_DASH} merge blocked."
|
|
@@ -51,7 +56,7 @@ def json_report(results_by_doc: dict[str, list[CheckResult]]) -> str:
|
|
|
51
56
|
} for r in results]
|
|
52
57
|
for path, results in results_by_doc.items()
|
|
53
58
|
}
|
|
54
|
-
all_results =
|
|
59
|
+
all_results = _all(results_by_doc)
|
|
55
60
|
summary = {
|
|
56
61
|
"documents": len(results_by_doc),
|
|
57
62
|
"checks": len(all_results),
|
|
@@ -89,9 +94,9 @@ def markdown(results_by_doc: dict[str, list[CheckResult]],
|
|
|
89
94
|
|
|
90
95
|
|
|
91
96
|
def junit(results_by_doc: dict[str, list[CheckResult]]) -> str:
|
|
92
|
-
|
|
93
|
-
|
|
94
|
-
|
|
97
|
+
all_results = _all(results_by_doc)
|
|
98
|
+
total = len(all_results)
|
|
99
|
+
failures = sum(1 for r in all_results if r.is_blocking_failure)
|
|
95
100
|
suites = ET.Element("testsuites", tests=str(total), failures=str(failures))
|
|
96
101
|
for path, results in results_by_doc.items():
|
|
97
102
|
suite = ET.SubElement(suites, "testsuite", name=path,
|
|
@@ -0,0 +1,26 @@
|
|
|
1
|
+
"""Status derivation and rendering, split into `derive` (model) and `render`
|
|
2
|
+
(views). This module re-exports the public API so existing imports are unchanged.
|
|
3
|
+
"""
|
|
4
|
+
from .derive import (
|
|
5
|
+
APPROVED,
|
|
6
|
+
DOCUMENTS_DIR,
|
|
7
|
+
build_index,
|
|
8
|
+
build_status,
|
|
9
|
+
completeness_report,
|
|
10
|
+
derive_rag,
|
|
11
|
+
)
|
|
12
|
+
from .render import (
|
|
13
|
+
render_badge_json,
|
|
14
|
+
render_html,
|
|
15
|
+
render_index_html,
|
|
16
|
+
render_index_markdown,
|
|
17
|
+
render_json,
|
|
18
|
+
render_markdown,
|
|
19
|
+
)
|
|
20
|
+
|
|
21
|
+
__all__ = [
|
|
22
|
+
"DOCUMENTS_DIR", "APPROVED",
|
|
23
|
+
"build_status", "build_index", "completeness_report", "derive_rag",
|
|
24
|
+
"render_markdown", "render_json", "render_html",
|
|
25
|
+
"render_index_markdown", "render_index_html", "render_badge_json",
|
|
26
|
+
]
|
|
@@ -0,0 +1,231 @@
|
|
|
1
|
+
"""Derive project and portfolio status from the documents (the model layer).
|
|
2
|
+
|
|
3
|
+
Pure computation: reads the document graph and returns plain dicts. Rendering
|
|
4
|
+
lives in docassert.status.render.
|
|
5
|
+
"""
|
|
6
|
+
from __future__ import annotations
|
|
7
|
+
|
|
8
|
+
from pathlib import Path
|
|
9
|
+
|
|
10
|
+
from .. import config as config_mod
|
|
11
|
+
from .. import profiles as profiles_mod
|
|
12
|
+
from ..graph import build_graph
|
|
13
|
+
from ..loader import load
|
|
14
|
+
from ..structural import _field_value, run_structural
|
|
15
|
+
|
|
16
|
+
DOCUMENTS_DIR = Path("documents")
|
|
17
|
+
APPROVED = {"approved", "baselined"}
|
|
18
|
+
_SEVERITY = {"low": 1, "medium": 2, "high": 3, "critical": 4}
|
|
19
|
+
|
|
20
|
+
|
|
21
|
+
def _doc_passes(doc, id_index) -> bool:
|
|
22
|
+
kind = doc.kind or ""
|
|
23
|
+
if not config_mod.criteria_exists(kind):
|
|
24
|
+
return True
|
|
25
|
+
criteria = config_mod.read_criteria(kind)
|
|
26
|
+
try:
|
|
27
|
+
schema = config_mod.read_schema(kind)
|
|
28
|
+
except FileNotFoundError:
|
|
29
|
+
schema = {}
|
|
30
|
+
ctx = {
|
|
31
|
+
"schema": schema,
|
|
32
|
+
"required_sections": criteria.get("required_sections", []),
|
|
33
|
+
"item_sections": criteria.get("item_sections", []),
|
|
34
|
+
"steps_sections": criteria.get("steps_sections", []),
|
|
35
|
+
"measurable_sections": criteria.get("measurable_sections", []),
|
|
36
|
+
"id_index": id_index,
|
|
37
|
+
}
|
|
38
|
+
for spec in criteria.get("checks", []):
|
|
39
|
+
if spec.get("type") == "structural":
|
|
40
|
+
if run_structural(doc, spec, ctx).is_blocking_failure:
|
|
41
|
+
return False
|
|
42
|
+
return True
|
|
43
|
+
|
|
44
|
+
|
|
45
|
+
# ── signal extractors ───────────────────────────────────────────────────────
|
|
46
|
+
# `code` optionally scopes a signal to one project (by item project code, e.g.
|
|
47
|
+
# "AUR"). The graph itself stays global so cross-project link targets resolve.
|
|
48
|
+
def _coverage(graph, config, code=None):
|
|
49
|
+
out = []
|
|
50
|
+
for rule in config.get("coverage", []):
|
|
51
|
+
parent_prefix, relation = rule["parent"], rule["relation"]
|
|
52
|
+
by_prefix = rule.get("by_prefix")
|
|
53
|
+
parents = graph.by_type.get(parent_prefix, [])
|
|
54
|
+
if code:
|
|
55
|
+
parents = [p for p in parents if p.project == code]
|
|
56
|
+
covered = [p for p in parents if graph.children(p.id, relation, by_prefix)]
|
|
57
|
+
out.append({
|
|
58
|
+
"label": rule.get("label", f"{parent_prefix} → {by_prefix}"),
|
|
59
|
+
"covered": len(covered),
|
|
60
|
+
"total": len(parents),
|
|
61
|
+
"gaps": [p.id for p in parents if p not in covered],
|
|
62
|
+
})
|
|
63
|
+
return out
|
|
64
|
+
|
|
65
|
+
|
|
66
|
+
def _risks(graph, code=None):
|
|
67
|
+
risks = []
|
|
68
|
+
for item in graph.by_type.get("RISK", []):
|
|
69
|
+
if code and item.project != code:
|
|
70
|
+
continue
|
|
71
|
+
prob = (_field_value(item.text, "probability") or "").lower()
|
|
72
|
+
impact = (_field_value(item.text, "impact") or "").lower()
|
|
73
|
+
risks.append({
|
|
74
|
+
"id": item.id,
|
|
75
|
+
"probability": prob or "?",
|
|
76
|
+
"impact": impact or "?",
|
|
77
|
+
"owner": _field_value(item.text, "owner") or "?",
|
|
78
|
+
"score": _SEVERITY.get(prob, 0) * _SEVERITY.get(impact, 0),
|
|
79
|
+
})
|
|
80
|
+
return sorted(risks, key=lambda r: -r["score"])
|
|
81
|
+
|
|
82
|
+
|
|
83
|
+
def _broken_references(graph, code=None):
|
|
84
|
+
broken = []
|
|
85
|
+
for item in graph.all_items():
|
|
86
|
+
if code and item.project != code:
|
|
87
|
+
continue
|
|
88
|
+
for relation, targets in item.links.items():
|
|
89
|
+
for target in targets:
|
|
90
|
+
if not graph.exists(target):
|
|
91
|
+
broken.append(f"{item.id} —{relation}→ {target}")
|
|
92
|
+
return broken
|
|
93
|
+
|
|
94
|
+
|
|
95
|
+
def _latest_report(docs):
|
|
96
|
+
reports = [d for d in docs if d.kind == "status-report"]
|
|
97
|
+
if not reports:
|
|
98
|
+
return None
|
|
99
|
+
reports.sort(key=lambda d: str(d.frontmatter.get("period", "")), reverse=True)
|
|
100
|
+
top = reports[0]
|
|
101
|
+
return {
|
|
102
|
+
"id": top.id,
|
|
103
|
+
"period": str(top.frontmatter.get("period", "")),
|
|
104
|
+
"rag": str(top.frontmatter.get("rag", "")).lower(),
|
|
105
|
+
}
|
|
106
|
+
|
|
107
|
+
|
|
108
|
+
# ── the model + derived RAG ─────────────────────────────────────────────────
|
|
109
|
+
def build_status(documents_dir=DOCUMENTS_DIR, project: str | None = None) -> dict:
|
|
110
|
+
"""Derive the status model for the whole repo, or for one project.
|
|
111
|
+
|
|
112
|
+
`project` is a canonical project id (PRJ-NNN-CODE). When given, documents,
|
|
113
|
+
coverage, risks, broken references and the latest report are all scoped to
|
|
114
|
+
that project; the graph stays global so cross-project targets still resolve.
|
|
115
|
+
"""
|
|
116
|
+
all_docs = [load(p) for p in sorted(Path(documents_dir).rglob("*.md"))]
|
|
117
|
+
graph = build_graph(documents_dir)
|
|
118
|
+
cfg = config_mod.read_consistency_config()
|
|
119
|
+
|
|
120
|
+
code = project.split("-")[-1] if project else None
|
|
121
|
+
if project:
|
|
122
|
+
docs = [d for d in all_docs
|
|
123
|
+
if d.frontmatter.get("project") == project
|
|
124
|
+
or (d.kind == "project" and d.id == project)]
|
|
125
|
+
else:
|
|
126
|
+
docs = all_docs
|
|
127
|
+
|
|
128
|
+
id_index: dict[str, list[str]] = {}
|
|
129
|
+
for d in all_docs: # uniqueness is always global
|
|
130
|
+
id_index.setdefault(d.id or "", []).append(d.path)
|
|
131
|
+
|
|
132
|
+
documents = [{
|
|
133
|
+
"kind": d.kind,
|
|
134
|
+
"id": d.id,
|
|
135
|
+
"title": d.frontmatter.get("title", d.id),
|
|
136
|
+
"status": str(d.frontmatter.get("status", "draft")),
|
|
137
|
+
"passing": _doc_passes(d, id_index),
|
|
138
|
+
} for d in docs]
|
|
139
|
+
|
|
140
|
+
completeness = None
|
|
141
|
+
if project:
|
|
142
|
+
anchor = next((d for d in docs if d.kind == "project"), None)
|
|
143
|
+
title = str(anchor.frontmatter.get("name", project)) if anchor else project
|
|
144
|
+
if anchor is not None:
|
|
145
|
+
completeness = _completeness_for(anchor, documents)
|
|
146
|
+
else:
|
|
147
|
+
title = "Project Status"
|
|
148
|
+
|
|
149
|
+
model = {
|
|
150
|
+
"project": project,
|
|
151
|
+
"title": title,
|
|
152
|
+
"documents": documents,
|
|
153
|
+
"counts": {
|
|
154
|
+
"total": len(documents),
|
|
155
|
+
"kinds": len({d["kind"] for d in documents}),
|
|
156
|
+
"approved": sum(1 for d in documents if d["status"] in APPROVED),
|
|
157
|
+
"failing": sum(1 for d in documents if not d["passing"]),
|
|
158
|
+
},
|
|
159
|
+
"coverage": _coverage(graph, cfg, code),
|
|
160
|
+
"risks": _risks(graph, code),
|
|
161
|
+
"broken_references": _broken_references(graph, code),
|
|
162
|
+
"latest_report": _latest_report(docs),
|
|
163
|
+
"completeness": completeness,
|
|
164
|
+
}
|
|
165
|
+
model["rag"] = derive_rag(model)
|
|
166
|
+
return model
|
|
167
|
+
|
|
168
|
+
|
|
169
|
+
def _completeness_for(anchor, documents: list[dict]) -> dict | None:
|
|
170
|
+
"""Assess a project's documents against the profile its anchor declares."""
|
|
171
|
+
prof_name = anchor.frontmatter.get("profile")
|
|
172
|
+
if not prof_name:
|
|
173
|
+
return None
|
|
174
|
+
profile = profiles_mod.load_profile(prof_name)
|
|
175
|
+
if profile is None:
|
|
176
|
+
return profiles_mod.unknown(prof_name)
|
|
177
|
+
return profiles_mod.completeness(
|
|
178
|
+
profile, documents, str(anchor.frontmatter.get("status", "")))
|
|
179
|
+
|
|
180
|
+
|
|
181
|
+
def completeness_report(documents_dir=DOCUMENTS_DIR) -> list[dict]:
|
|
182
|
+
"""Per-project completeness for every profiled project (used by the
|
|
183
|
+
blocking profile-completeness consistency check)."""
|
|
184
|
+
from .. import projects as projects_mod
|
|
185
|
+
out = []
|
|
186
|
+
for p in projects_mod.load_projects(documents_dir):
|
|
187
|
+
comp = build_status(documents_dir, project=p["id"]).get("completeness")
|
|
188
|
+
if comp:
|
|
189
|
+
out.append({"id": p["id"], "name": p["name"], "lifecycle": p["status"], **comp})
|
|
190
|
+
return out
|
|
191
|
+
|
|
192
|
+
|
|
193
|
+
def build_index(documents_dir=DOCUMENTS_DIR) -> dict:
|
|
194
|
+
"""The multi-project view: each project's derived RAG + headline signals,
|
|
195
|
+
plus the whole-repo rollup."""
|
|
196
|
+
from .. import projects as projects_mod
|
|
197
|
+
cards = []
|
|
198
|
+
for p in projects_mod.load_projects(documents_dir):
|
|
199
|
+
m = build_status(documents_dir, project=p["id"])
|
|
200
|
+
cards.append({
|
|
201
|
+
"id": p["id"], "code": p["code"], "name": p["name"],
|
|
202
|
+
"sponsor": p["sponsor"], "lifecycle": p["status"],
|
|
203
|
+
"rag": m["rag"],
|
|
204
|
+
"total": m["counts"]["total"],
|
|
205
|
+
"failing": m["counts"]["failing"],
|
|
206
|
+
"risks": len(m["risks"]),
|
|
207
|
+
"coverage_gaps": sum(len(c["gaps"]) for c in m["coverage"]),
|
|
208
|
+
"broken": len(m["broken_references"]),
|
|
209
|
+
"completeness": m.get("completeness"),
|
|
210
|
+
})
|
|
211
|
+
return {"projects": cards, "overall": build_status(documents_dir)}
|
|
212
|
+
|
|
213
|
+
|
|
214
|
+
def derive_rag(model) -> str:
|
|
215
|
+
"""Red = something is objectively broken. Amber = carrying risk or
|
|
216
|
+
incompleteness. Green = clean."""
|
|
217
|
+
comp = model.get("completeness")
|
|
218
|
+
approved_failing = any(not d["passing"] for d in model["documents"]
|
|
219
|
+
if d["status"] in APPROVED)
|
|
220
|
+
if approved_failing or model["broken_references"] or (comp and comp["blocks"]):
|
|
221
|
+
return "red"
|
|
222
|
+
coverage_gap = any(c["gaps"] for c in model["coverage"])
|
|
223
|
+
reported = (model["latest_report"] or {}).get("rag")
|
|
224
|
+
completeness_gap = bool(comp and (comp["missing_required"] or comp["incomplete_required"]
|
|
225
|
+
or comp["recommended_gaps"] or comp.get("unknown")))
|
|
226
|
+
if coverage_gap or model["risks"] or reported in {"amber", "red"} or completeness_gap:
|
|
227
|
+
return "amber"
|
|
228
|
+
return "green"
|
|
229
|
+
|
|
230
|
+
|
|
231
|
+
# ── renderers ───────────────────────────────────────────────────────────────
|
|
@@ -1,237 +1,18 @@
|
|
|
1
|
-
"""
|
|
1
|
+
"""Render a status/index model as Markdown, JSON, HTML, or a shields badge.
|
|
2
2
|
|
|
3
|
-
|
|
4
|
-
|
|
5
|
-
page computes its own RAG from real signals rather than trusting a typed field.
|
|
3
|
+
Each function takes an already-built model dict (see docassert.status.derive)
|
|
4
|
+
and returns a string; none touch the document graph.
|
|
6
5
|
"""
|
|
7
6
|
from __future__ import annotations
|
|
8
7
|
|
|
8
|
+
import html as _h
|
|
9
9
|
import json
|
|
10
|
-
|
|
11
|
-
|
|
12
|
-
|
|
13
|
-
|
|
14
|
-
|
|
15
|
-
|
|
16
|
-
from .structural import _field_value, run_structural
|
|
17
|
-
|
|
18
|
-
DOCUMENTS_DIR = Path("documents")
|
|
19
|
-
APPROVED = {"approved", "baselined"}
|
|
20
|
-
_SEVERITY = {"low": 1, "medium": 2, "high": 3, "critical": 4}
|
|
21
|
-
|
|
22
|
-
|
|
23
|
-
# ── per-document validity (blocking structural checks only) ─────────────────
|
|
24
|
-
def _doc_passes(doc, id_index) -> bool:
|
|
25
|
-
kind = doc.kind or ""
|
|
26
|
-
if not config_mod.criteria_exists(kind):
|
|
27
|
-
return True
|
|
28
|
-
criteria = config_mod.read_criteria(kind)
|
|
29
|
-
try:
|
|
30
|
-
schema = config_mod.read_schema(kind)
|
|
31
|
-
except FileNotFoundError:
|
|
32
|
-
schema = {}
|
|
33
|
-
ctx = {
|
|
34
|
-
"schema": schema,
|
|
35
|
-
"required_sections": criteria.get("required_sections", []),
|
|
36
|
-
"item_sections": criteria.get("item_sections", []),
|
|
37
|
-
"steps_sections": criteria.get("steps_sections", []),
|
|
38
|
-
"measurable_sections": criteria.get("measurable_sections", []),
|
|
39
|
-
"id_index": id_index,
|
|
40
|
-
}
|
|
41
|
-
for spec in criteria.get("checks", []):
|
|
42
|
-
if spec.get("type") == "structural":
|
|
43
|
-
if run_structural(doc, spec, ctx).is_blocking_failure:
|
|
44
|
-
return False
|
|
45
|
-
return True
|
|
46
|
-
|
|
47
|
-
|
|
48
|
-
# ── signal extractors ───────────────────────────────────────────────────────
|
|
49
|
-
# `code` optionally scopes a signal to one project (by item project code, e.g.
|
|
50
|
-
# "AUR"). The graph itself stays global so cross-project link targets resolve.
|
|
51
|
-
def _coverage(graph, config, code=None):
|
|
52
|
-
out = []
|
|
53
|
-
for rule in config.get("coverage", []):
|
|
54
|
-
parent_prefix, relation = rule["parent"], rule["relation"]
|
|
55
|
-
by_prefix = rule.get("by_prefix")
|
|
56
|
-
parents = graph.by_type.get(parent_prefix, [])
|
|
57
|
-
if code:
|
|
58
|
-
parents = [p for p in parents if p.project == code]
|
|
59
|
-
covered = [p for p in parents if graph.children(p.id, relation, by_prefix)]
|
|
60
|
-
out.append({
|
|
61
|
-
"label": rule.get("label", f"{parent_prefix} → {by_prefix}"),
|
|
62
|
-
"covered": len(covered),
|
|
63
|
-
"total": len(parents),
|
|
64
|
-
"gaps": [p.id for p in parents if p not in covered],
|
|
65
|
-
})
|
|
66
|
-
return out
|
|
67
|
-
|
|
68
|
-
|
|
69
|
-
def _risks(graph, code=None):
|
|
70
|
-
risks = []
|
|
71
|
-
for item in graph.by_type.get("RISK", []):
|
|
72
|
-
if code and item.project != code:
|
|
73
|
-
continue
|
|
74
|
-
prob = (_field_value(item.text, "probability") or "").lower()
|
|
75
|
-
impact = (_field_value(item.text, "impact") or "").lower()
|
|
76
|
-
risks.append({
|
|
77
|
-
"id": item.id,
|
|
78
|
-
"probability": prob or "?",
|
|
79
|
-
"impact": impact or "?",
|
|
80
|
-
"owner": _field_value(item.text, "owner") or "?",
|
|
81
|
-
"score": _SEVERITY.get(prob, 0) * _SEVERITY.get(impact, 0),
|
|
82
|
-
})
|
|
83
|
-
return sorted(risks, key=lambda r: -r["score"])
|
|
84
|
-
|
|
85
|
-
|
|
86
|
-
def _broken_references(graph, code=None):
|
|
87
|
-
broken = []
|
|
88
|
-
for item in graph.all_items():
|
|
89
|
-
if code and item.project != code:
|
|
90
|
-
continue
|
|
91
|
-
for relation, targets in item.links.items():
|
|
92
|
-
for target in targets:
|
|
93
|
-
if not graph.exists(target):
|
|
94
|
-
broken.append(f"{item.id} —{relation}→ {target}")
|
|
95
|
-
return broken
|
|
96
|
-
|
|
97
|
-
|
|
98
|
-
def _latest_report(docs):
|
|
99
|
-
reports = [d for d in docs if d.kind == "status-report"]
|
|
100
|
-
if not reports:
|
|
101
|
-
return None
|
|
102
|
-
reports.sort(key=lambda d: str(d.frontmatter.get("period", "")), reverse=True)
|
|
103
|
-
top = reports[0]
|
|
104
|
-
return {
|
|
105
|
-
"id": top.id,
|
|
106
|
-
"period": str(top.frontmatter.get("period", "")),
|
|
107
|
-
"rag": str(top.frontmatter.get("rag", "")).lower(),
|
|
108
|
-
}
|
|
109
|
-
|
|
110
|
-
|
|
111
|
-
# ── the model + derived RAG ─────────────────────────────────────────────────
|
|
112
|
-
def build_status(documents_dir=DOCUMENTS_DIR, project: str | None = None) -> dict:
|
|
113
|
-
"""Derive the status model for the whole repo, or for one project.
|
|
114
|
-
|
|
115
|
-
`project` is a canonical project id (PRJ-NNN-CODE). When given, documents,
|
|
116
|
-
coverage, risks, broken references and the latest report are all scoped to
|
|
117
|
-
that project; the graph stays global so cross-project targets still resolve.
|
|
118
|
-
"""
|
|
119
|
-
all_docs = [load(p) for p in sorted(Path(documents_dir).rglob("*.md"))]
|
|
120
|
-
graph = build_graph(documents_dir)
|
|
121
|
-
cfg = config_mod.read_consistency_config()
|
|
122
|
-
|
|
123
|
-
code = project.split("-")[-1] if project else None
|
|
124
|
-
if project:
|
|
125
|
-
docs = [d for d in all_docs
|
|
126
|
-
if d.frontmatter.get("project") == project
|
|
127
|
-
or (d.kind == "project" and d.id == project)]
|
|
128
|
-
else:
|
|
129
|
-
docs = all_docs
|
|
130
|
-
|
|
131
|
-
id_index: dict[str, list[str]] = {}
|
|
132
|
-
for d in all_docs: # uniqueness is always global
|
|
133
|
-
id_index.setdefault(d.id or "", []).append(d.path)
|
|
134
|
-
|
|
135
|
-
documents = [{
|
|
136
|
-
"kind": d.kind,
|
|
137
|
-
"id": d.id,
|
|
138
|
-
"title": d.frontmatter.get("title", d.id),
|
|
139
|
-
"status": str(d.frontmatter.get("status", "draft")),
|
|
140
|
-
"passing": _doc_passes(d, id_index),
|
|
141
|
-
} for d in docs]
|
|
142
|
-
|
|
143
|
-
completeness = None
|
|
144
|
-
if project:
|
|
145
|
-
anchor = next((d for d in docs if d.kind == "project"), None)
|
|
146
|
-
title = str(anchor.frontmatter.get("name", project)) if anchor else project
|
|
147
|
-
if anchor is not None:
|
|
148
|
-
completeness = _completeness_for(anchor, documents)
|
|
149
|
-
else:
|
|
150
|
-
title = "Project Status"
|
|
151
|
-
|
|
152
|
-
model = {
|
|
153
|
-
"project": project,
|
|
154
|
-
"title": title,
|
|
155
|
-
"documents": documents,
|
|
156
|
-
"counts": {
|
|
157
|
-
"total": len(documents),
|
|
158
|
-
"kinds": len({d["kind"] for d in documents}),
|
|
159
|
-
"approved": sum(1 for d in documents if d["status"] in APPROVED),
|
|
160
|
-
"failing": sum(1 for d in documents if not d["passing"]),
|
|
161
|
-
},
|
|
162
|
-
"coverage": _coverage(graph, cfg, code),
|
|
163
|
-
"risks": _risks(graph, code),
|
|
164
|
-
"broken_references": _broken_references(graph, code),
|
|
165
|
-
"latest_report": _latest_report(docs),
|
|
166
|
-
"completeness": completeness,
|
|
167
|
-
}
|
|
168
|
-
model["rag"] = derive_rag(model)
|
|
169
|
-
return model
|
|
170
|
-
|
|
171
|
-
|
|
172
|
-
def _completeness_for(anchor, documents: list[dict]) -> dict | None:
|
|
173
|
-
"""Assess a project's documents against the profile its anchor declares."""
|
|
174
|
-
prof_name = anchor.frontmatter.get("profile")
|
|
175
|
-
if not prof_name:
|
|
176
|
-
return None
|
|
177
|
-
profile = profiles_mod.load_profile(prof_name)
|
|
178
|
-
if profile is None:
|
|
179
|
-
return profiles_mod.unknown(prof_name)
|
|
180
|
-
return profiles_mod.completeness(
|
|
181
|
-
profile, documents, str(anchor.frontmatter.get("status", "")))
|
|
182
|
-
|
|
183
|
-
|
|
184
|
-
def completeness_report(documents_dir=DOCUMENTS_DIR) -> list[dict]:
|
|
185
|
-
"""Per-project completeness for every profiled project (used by the
|
|
186
|
-
blocking profile-completeness consistency check)."""
|
|
187
|
-
from . import projects as projects_mod
|
|
188
|
-
out = []
|
|
189
|
-
for p in projects_mod.load_projects(documents_dir):
|
|
190
|
-
comp = build_status(documents_dir, project=p["id"]).get("completeness")
|
|
191
|
-
if comp:
|
|
192
|
-
out.append({"id": p["id"], "name": p["name"], "lifecycle": p["status"], **comp})
|
|
193
|
-
return out
|
|
194
|
-
|
|
195
|
-
|
|
196
|
-
def build_index(documents_dir=DOCUMENTS_DIR) -> dict:
|
|
197
|
-
"""The multi-project view: each project's derived RAG + headline signals,
|
|
198
|
-
plus the whole-repo rollup."""
|
|
199
|
-
from . import projects as projects_mod
|
|
200
|
-
cards = []
|
|
201
|
-
for p in projects_mod.load_projects(documents_dir):
|
|
202
|
-
m = build_status(documents_dir, project=p["id"])
|
|
203
|
-
cards.append({
|
|
204
|
-
"id": p["id"], "code": p["code"], "name": p["name"],
|
|
205
|
-
"sponsor": p["sponsor"], "lifecycle": p["status"],
|
|
206
|
-
"rag": m["rag"],
|
|
207
|
-
"total": m["counts"]["total"],
|
|
208
|
-
"failing": m["counts"]["failing"],
|
|
209
|
-
"risks": len(m["risks"]),
|
|
210
|
-
"coverage_gaps": sum(len(c["gaps"]) for c in m["coverage"]),
|
|
211
|
-
"broken": len(m["broken_references"]),
|
|
212
|
-
"completeness": m.get("completeness"),
|
|
213
|
-
})
|
|
214
|
-
return {"projects": cards, "overall": build_status(documents_dir)}
|
|
215
|
-
|
|
216
|
-
|
|
217
|
-
def derive_rag(model) -> str:
|
|
218
|
-
"""Red = something is objectively broken. Amber = carrying risk or
|
|
219
|
-
incompleteness. Green = clean."""
|
|
220
|
-
comp = model.get("completeness")
|
|
221
|
-
approved_failing = any(not d["passing"] for d in model["documents"]
|
|
222
|
-
if d["status"] in APPROVED)
|
|
223
|
-
if approved_failing or model["broken_references"] or (comp and comp["blocks"]):
|
|
224
|
-
return "red"
|
|
225
|
-
coverage_gap = any(c["gaps"] for c in model["coverage"])
|
|
226
|
-
reported = (model["latest_report"] or {}).get("rag")
|
|
227
|
-
completeness_gap = bool(comp and (comp["missing_required"] or comp["incomplete_required"]
|
|
228
|
-
or comp["recommended_gaps"] or comp.get("unknown")))
|
|
229
|
-
if coverage_gap or model["risks"] or reported in {"amber", "red"} or completeness_gap:
|
|
230
|
-
return "amber"
|
|
231
|
-
return "green"
|
|
232
|
-
|
|
233
|
-
|
|
234
|
-
# ── renderers ───────────────────────────────────────────────────────────────
|
|
10
|
+
|
|
11
|
+
|
|
12
|
+
def esc(s):
|
|
13
|
+
return _h.escape(str(s))
|
|
14
|
+
|
|
15
|
+
|
|
235
16
|
_EMOJI = {"green": "🟢", "amber": "🟠", "red": "🔴"}
|
|
236
17
|
|
|
237
18
|
|
|
@@ -348,13 +129,10 @@ _INDEX_CSS = """
|
|
|
348
129
|
|
|
349
130
|
def render_html(model) -> str:
|
|
350
131
|
import datetime
|
|
351
|
-
import html as _h
|
|
352
132
|
rag = model["rag"]
|
|
353
133
|
c = model["counts"]
|
|
354
134
|
color = {"green": "var(--ok)", "amber": "var(--amber)", "red": "var(--bad)"}[rag]
|
|
355
135
|
bar_color = {"green": "var(--ok)", "amber": "var(--amber)", "red": "var(--bad)"}[rag]
|
|
356
|
-
def esc(s):
|
|
357
|
-
return _h.escape(str(s))
|
|
358
136
|
|
|
359
137
|
coverage = "".join(
|
|
360
138
|
f'<div class="sig"><div class="sig-h"><span>{esc(cov["label"])}</span>'
|
|
@@ -518,9 +296,6 @@ def render_index_markdown(index) -> str:
|
|
|
518
296
|
def render_index_html(index) -> str:
|
|
519
297
|
"""The multi-project landing page: one linked RAG card per project."""
|
|
520
298
|
import datetime
|
|
521
|
-
import html as _h
|
|
522
|
-
def esc(s):
|
|
523
|
-
return _h.escape(str(s))
|
|
524
299
|
|
|
525
300
|
overall = index["overall"]["rag"]
|
|
526
301
|
ocolor = _RAG_COLOR[overall]
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: docassert
|
|
3
|
-
Version: 0.7.
|
|
3
|
+
Version: 0.7.1
|
|
4
4
|
Summary: Unit testing for business documents — validate structured Markdown docs against a configurable audit standard.
|
|
5
5
|
Author: C4G Enterprises Inc.
|
|
6
6
|
License: Apache-2.0
|
|
@@ -44,6 +44,8 @@ Dynamic: license-file
|
|
|
44
44
|
[](https://pypi.org/project/docassert/)
|
|
45
45
|
[](LICENSE)
|
|
46
46
|
|
|
47
|
+

|
|
48
|
+
|
|
47
49
|
**Unit testing for business documents.** Validate structured Markdown documents
|
|
48
50
|
(charters, BRDs, PRDs, risk registers, …) against a configurable audit standard:
|
|
49
51
|
deterministic structural checks that gate a merge, plus optional AI-graded
|
|
@@ -52,7 +54,7 @@ derived from the documents rather than self-reported.
|
|
|
52
54
|
|
|
53
55
|
docassert is the reference implementation of **[PMO as Code](https://c4g-john.github.io/pmo-as-code/)** —
|
|
54
56
|
a vendor-neutral standard for running a PMO from version-controlled, declarative
|
|
55
|
-
files. It implements the [PMO as Code specification](https://github.com/c4g-john/pmo-as-code-spec) **v0.
|
|
57
|
+
files. It implements the [PMO as Code specification](https://github.com/c4g-john/pmo-as-code-spec) **v0.2**.
|
|
56
58
|
|
|
57
59
|
## Install
|
|
58
60
|
|
|
@@ -17,7 +17,6 @@ docassert/report.py
|
|
|
17
17
|
docassert/rtm.py
|
|
18
18
|
docassert/scaffold.py
|
|
19
19
|
docassert/semantic.py
|
|
20
|
-
docassert/status.py
|
|
21
20
|
docassert/structural.py
|
|
22
21
|
docassert.egg-info/PKG-INFO
|
|
23
22
|
docassert.egg-info/SOURCES.txt
|
|
@@ -90,6 +89,9 @@ docassert/_data/templates/runbook.template.md
|
|
|
90
89
|
docassert/_data/templates/status-report.template.md
|
|
91
90
|
docassert/_data/templates/test-cases.template.md
|
|
92
91
|
docassert/_data/templates/user-story.template.md
|
|
92
|
+
docassert/status/__init__.py
|
|
93
|
+
docassert/status/derive.py
|
|
94
|
+
docassert/status/render.py
|
|
93
95
|
tests/test_badge.py
|
|
94
96
|
tests/test_config.py
|
|
95
97
|
tests/test_consistency.py
|
|
@@ -43,8 +43,8 @@ docassert = "docassert.cli:main"
|
|
|
43
43
|
requires = ["setuptools>=68"]
|
|
44
44
|
build-backend = "setuptools.build_meta"
|
|
45
45
|
|
|
46
|
-
[tool.setuptools]
|
|
47
|
-
|
|
46
|
+
[tool.setuptools.packages.find]
|
|
47
|
+
include = ["docassert*"] # auto-discover subpackages (docassert, docassert.status, …)
|
|
48
48
|
|
|
49
49
|
[tool.setuptools.package-data]
|
|
50
50
|
# Ship the default criteria/schema/profiles/templates/consistency.yaml so
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/benefits-realization.criteria.yaml
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/data-migration-plan.criteria.yaml
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{docassert-0.7.0 → docassert-0.7.1}/docassert/_data/criteria/release-cutover-plan.criteria.yaml
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{docassert-0.7.0 → docassert-0.7.1}/docassert/_data/schema/post-implementation-review.schema.json
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/benefits-realization.template.md
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/data-migration-plan.template.md
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
{docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/post-implementation-review.template.md
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{docassert-0.7.0 → docassert-0.7.1}/docassert/_data/templates/release-cutover-plan.template.md
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|