dbt-preflight 0.2.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- dbt_preflight-0.2.0/LICENSE +21 -0
- dbt_preflight-0.2.0/PKG-INFO +356 -0
- dbt_preflight-0.2.0/README.md +313 -0
- dbt_preflight-0.2.0/dbt_preflight/__init__.py +8 -0
- dbt_preflight-0.2.0/dbt_preflight/checks.py +238 -0
- dbt_preflight-0.2.0/dbt_preflight/cli.py +593 -0
- dbt_preflight-0.2.0/dbt_preflight/config.py +212 -0
- dbt_preflight-0.2.0/dbt_preflight/conventions.py +159 -0
- dbt_preflight-0.2.0/dbt_preflight/dbt_runner.py +311 -0
- dbt_preflight-0.2.0/dbt_preflight/diff.py +543 -0
- dbt_preflight-0.2.0/dbt_preflight/fixtures.py +187 -0
- dbt_preflight-0.2.0/dbt_preflight/git.py +93 -0
- dbt_preflight-0.2.0/dbt_preflight/github.py +85 -0
- dbt_preflight-0.2.0/dbt_preflight/manifest.py +332 -0
- dbt_preflight-0.2.0/dbt_preflight/metrics.py +511 -0
- dbt_preflight-0.2.0/dbt_preflight/report.py +747 -0
- dbt_preflight-0.2.0/dbt_preflight/schema.py +741 -0
- dbt_preflight-0.2.0/dbt_preflight/summary.py +191 -0
- dbt_preflight-0.2.0/dbt_preflight/transpile.py +177 -0
- dbt_preflight-0.2.0/dbt_preflight.egg-info/PKG-INFO +356 -0
- dbt_preflight-0.2.0/dbt_preflight.egg-info/SOURCES.txt +38 -0
- dbt_preflight-0.2.0/dbt_preflight.egg-info/dependency_links.txt +1 -0
- dbt_preflight-0.2.0/dbt_preflight.egg-info/entry_points.txt +2 -0
- dbt_preflight-0.2.0/dbt_preflight.egg-info/requires.txt +17 -0
- dbt_preflight-0.2.0/dbt_preflight.egg-info/top_level.txt +1 -0
- dbt_preflight-0.2.0/pyproject.toml +98 -0
- dbt_preflight-0.2.0/setup.cfg +4 -0
- dbt_preflight-0.2.0/tests/test_big_project.py +67 -0
- dbt_preflight-0.2.0/tests/test_checks.py +85 -0
- dbt_preflight-0.2.0/tests/test_config.py +64 -0
- dbt_preflight-0.2.0/tests/test_conventions.py +114 -0
- dbt_preflight-0.2.0/tests/test_diff.py +583 -0
- dbt_preflight-0.2.0/tests/test_end_to_end.py +295 -0
- dbt_preflight-0.2.0/tests/test_fixtures.py +70 -0
- dbt_preflight-0.2.0/tests/test_manifest.py +45 -0
- dbt_preflight-0.2.0/tests/test_metrics.py +378 -0
- dbt_preflight-0.2.0/tests/test_report.py +782 -0
- dbt_preflight-0.2.0/tests/test_schema.py +599 -0
- dbt_preflight-0.2.0/tests/test_summary.py +179 -0
- dbt_preflight-0.2.0/tests/test_transpile.py +75 -0
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
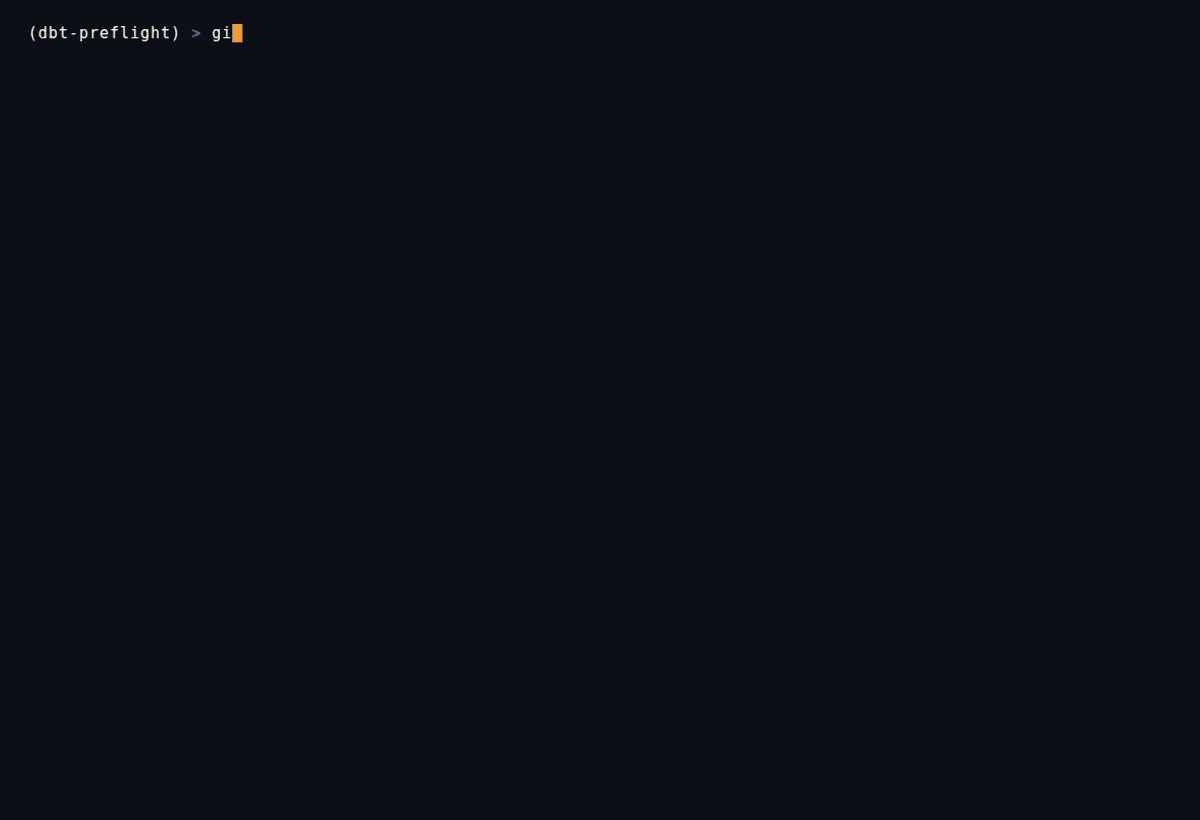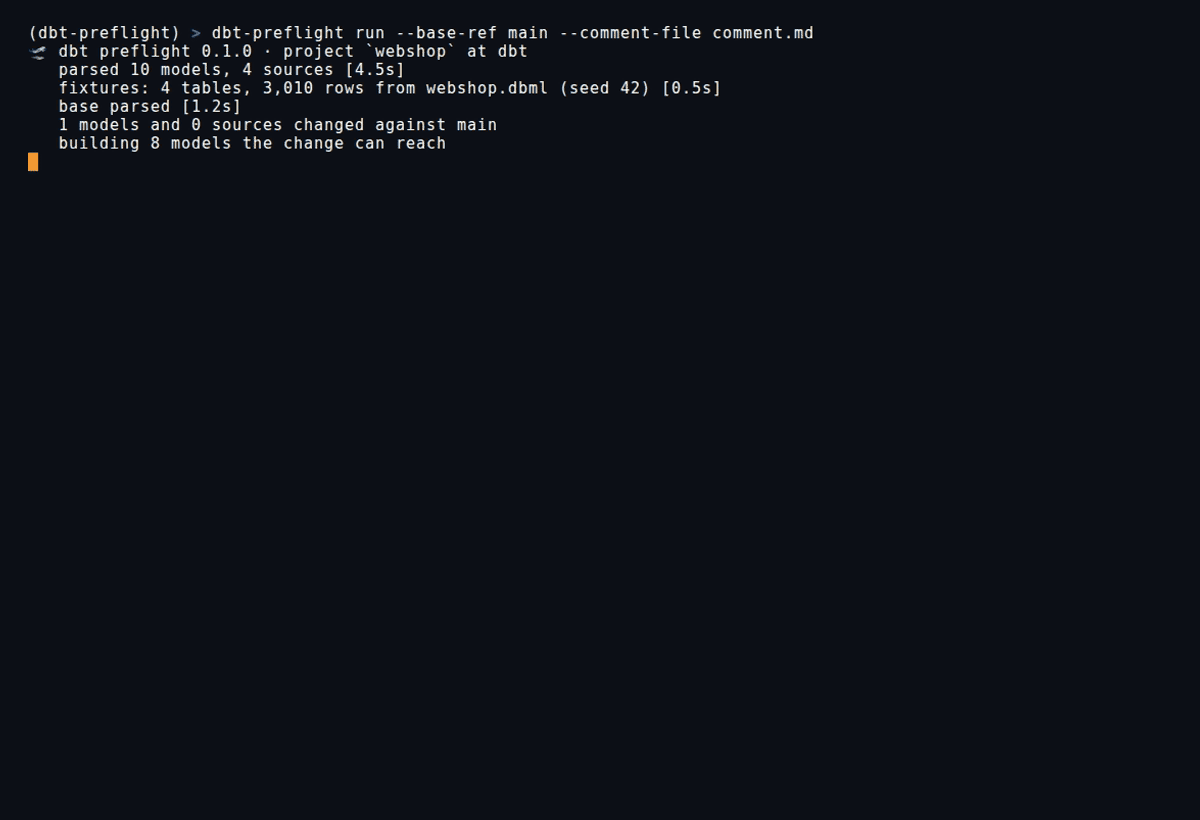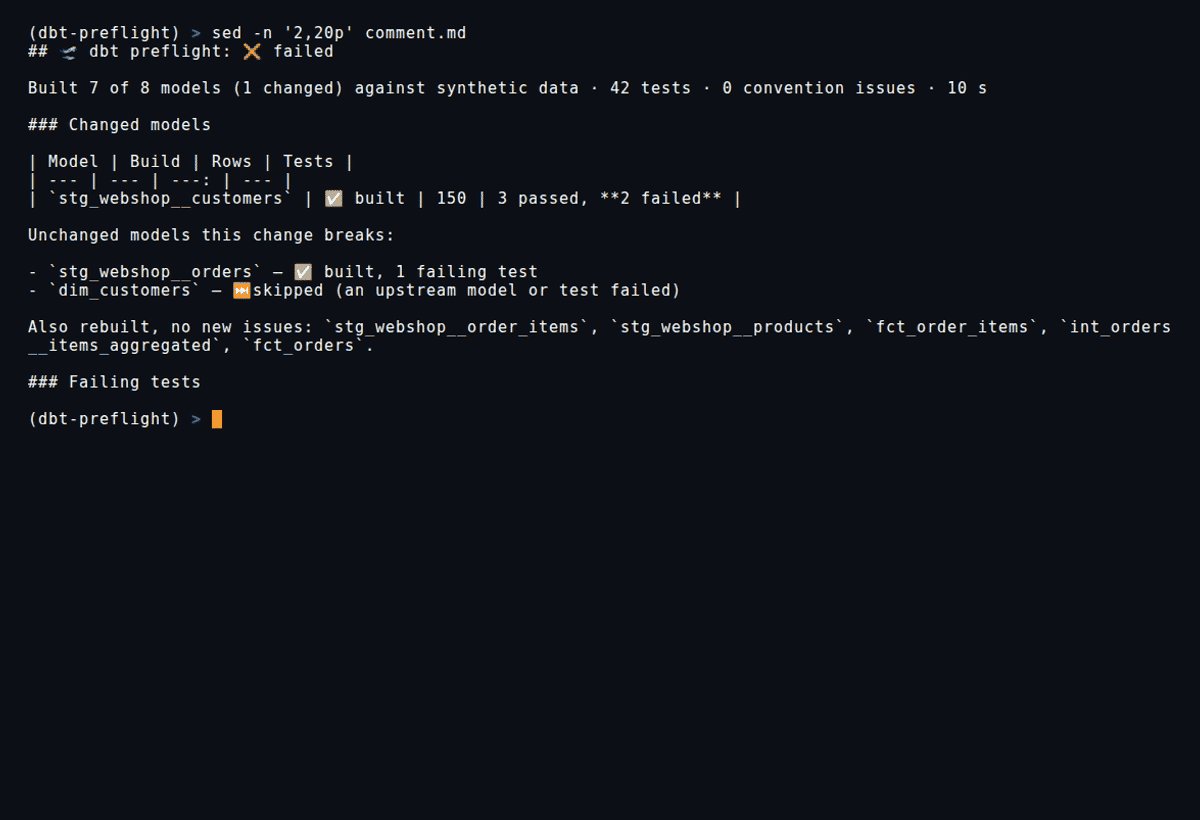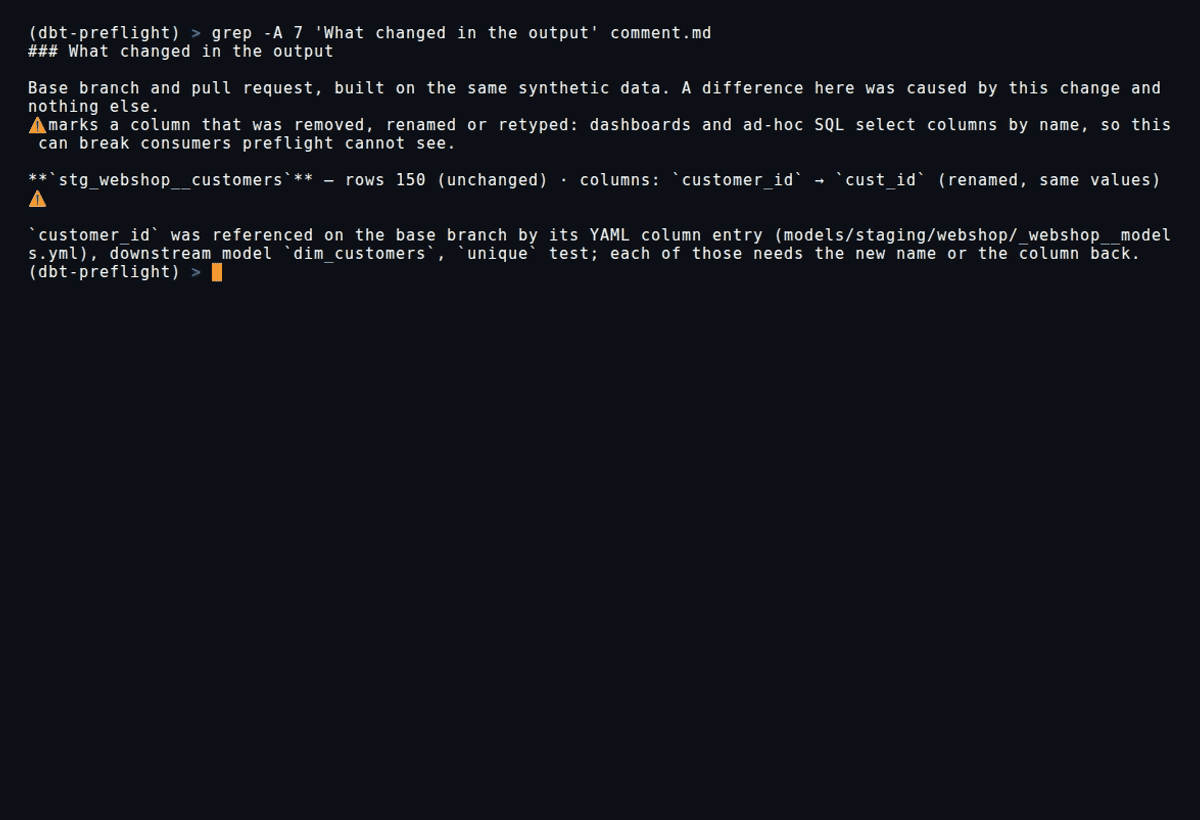
Copyright (c) 2026 JB Analytica
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,356 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: dbt-preflight
|
|
3
|
+
Version: 0.2.0
|
|
4
|
+
Summary: Warehouse-free CI for dbt pull requests: build and test the changed models against synthetic data, check house conventions, leave one review comment.
|
|
5
|
+
Author: JB Analytica
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/JB-Analytica/dbt-preflight
|
|
8
|
+
Project-URL: Repository, https://github.com/JB-Analytica/dbt-preflight
|
|
9
|
+
Project-URL: Issues, https://github.com/JB-Analytica/dbt-preflight/issues
|
|
10
|
+
Project-URL: Changelog, https://github.com/JB-Analytica/dbt-preflight/blob/main/CHANGELOG.md
|
|
11
|
+
Keywords: dbt,ci,github-actions,synthetic-data,analytics-engineering,data-engineering,duckdb,code-review
|
|
12
|
+
Classifier: Development Status :: 3 - Alpha
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: Operating System :: OS Independent
|
|
15
|
+
Classifier: Programming Language :: Python :: 3
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
20
|
+
Classifier: Topic :: Database
|
|
21
|
+
Classifier: Topic :: Software Development :: Testing
|
|
22
|
+
Classifier: Topic :: Software Development :: Quality Assurance
|
|
23
|
+
Requires-Python: >=3.10
|
|
24
|
+
Description-Content-Type: text/markdown
|
|
25
|
+
License-File: LICENSE
|
|
26
|
+
Requires-Dist: dbt-core<2,>=1.11
|
|
27
|
+
Requires-Dist: dbt-duckdb>=1.11
|
|
28
|
+
Requires-Dist: duckdb>=1.1
|
|
29
|
+
Requires-Dist: model2data>=1.3.1
|
|
30
|
+
Requires-Dist: pandas>=2.2
|
|
31
|
+
Requires-Dist: pyyaml>=6.0
|
|
32
|
+
Requires-Dist: sqlglot>=30.18.0
|
|
33
|
+
Requires-Dist: typer>=0.12
|
|
34
|
+
Provides-Extra: dev
|
|
35
|
+
Requires-Dist: pytest; extra == "dev"
|
|
36
|
+
Requires-Dist: pytest-cov; extra == "dev"
|
|
37
|
+
Requires-Dist: pre-commit; extra == "dev"
|
|
38
|
+
Requires-Dist: ruff>=0.1.0; extra == "dev"
|
|
39
|
+
Requires-Dist: ty>=0.0.4; extra == "dev"
|
|
40
|
+
Requires-Dist: types-pyyaml; extra == "dev"
|
|
41
|
+
Requires-Dist: poethepoet>=0.38.0; extra == "dev"
|
|
42
|
+
Dynamic: license-file
|
|
43
|
+
|
|
44
|
+
# dbt-preflight
|
|
45
|
+
|
|
46
|
+
[](https://pypi.org/project/dbt-preflight/)
|
|
47
|
+
[](https://pypi.org/project/dbt-preflight/)
|
|
48
|
+
[](https://github.com/JB-Analytica/dbt-preflight/actions/workflows/ci.yml)
|
|
49
|
+
[](https://github.com/JB-Analytica/dbt-preflight/blob/main/LICENSE)
|
|
50
|
+
|
|
51
|
+
Built and maintained by [JB Analytica](https://www.jbanalytica.com/) — data platform
|
|
52
|
+
architecture and analytics engineering.
|
|
53
|
+
|
|
54
|
+
**Warehouse-free CI for dbt pull requests.** On every pull request, preflight generates
|
|
55
|
+
synthetic source data from your schema, builds the models the change can reach on DuckDB,
|
|
56
|
+
runs their tests, checks house conventions, and leaves one review comment. No warehouse
|
|
57
|
+
credentials anywhere in the workflow.
|
|
58
|
+
|
|
59
|
+
|
|
60
|
+
|
|
61
|
+
This is what a reviewer sees when a pull request renames `customer_id` in a staging model:
|
|
62
|
+
|
|
63
|
+
> ## 🛫 dbt preflight: ❌ failed
|
|
64
|
+
>
|
|
65
|
+
> Built 7 of 8 models (1 changed) against synthetic data · 42 tests · 0 convention issues · 11 s
|
|
66
|
+
>
|
|
67
|
+
> ### Changed models
|
|
68
|
+
>
|
|
69
|
+
> | Model | Build | Rows | Tests |
|
|
70
|
+
> | --- | --- | ---: | --- |
|
|
71
|
+
> | `stg_webshop__customers` | ✅ built | 150 | 3 passed, **2 failed** |
|
|
72
|
+
>
|
|
73
|
+
> Unchanged models this change breaks:
|
|
74
|
+
>
|
|
75
|
+
> - `stg_webshop__orders` — ✅ built, 1 failing test
|
|
76
|
+
> - `dim_customers` — ⏭️ skipped (an upstream model or test failed)
|
|
77
|
+
>
|
|
78
|
+
> Also rebuilt, no new issues: `stg_webshop__products`, `stg_webshop__order_items`, `fct_order_items`, `int_orders__items_aggregated`, `fct_orders`.
|
|
79
|
+
>
|
|
80
|
+
> ### Failing tests
|
|
81
|
+
>
|
|
82
|
+
> - ❌ `unique` on `stg_webshop__customers.customer_id`: Binder Error: Referenced column "customer_id" not found in FROM clause!
|
|
83
|
+
> - ❌ `not_null` on `stg_webshop__customers.customer_id`: Binder Error: Referenced column "customer_id" not found in FROM clause!
|
|
84
|
+
> - ❌ relationships `stg_webshop__orders.customer_id` → `stg_webshop__customers.customer_id`: Binder Error: Referenced column "customer_id" not found in FROM clause!
|
|
85
|
+
|
|
86
|
+
Each failing test folds a `<details>` block under it with a plain-English reading of the
|
|
87
|
+
error (*this model has no column `customer_id`: renamed or dropped upstream?*), dbt's own
|
|
88
|
+
test name, and the compiled SQL that failed.
|
|
89
|
+
|
|
90
|
+
The comment is updated in place on every push, so a pull request carries one preflight
|
|
91
|
+
comment, not a stack of them.
|
|
92
|
+
|
|
93
|
+
Six pull-request shapes, four that must fail and two that must pass, are recorded
|
|
94
|
+
with the comments they produced in [docs/scenarios](https://github.com/JB-Analytica/dbt-preflight/blob/main/docs/scenarios/README.md). If you are
|
|
95
|
+
pointing a coding agent at a dbt project, [docs/agents.md](https://github.com/JB-Analytica/dbt-preflight/blob/main/docs/agents.md) says what to tell it.
|
|
96
|
+
|
|
97
|
+
## Why this exists
|
|
98
|
+
|
|
99
|
+
Letting a person, or a coding agent, change a dbt project without a warehouse to test
|
|
100
|
+
against is guesswork. The usual fixes need production data in CI (a credential most teams
|
|
101
|
+
will not hand out) or a dbt Cloud seat. Preflight needs neither: the data is synthetic and
|
|
102
|
+
relationship-preserving, generated by [model2data](https://github.com/JB-Analytica/model2data)
|
|
103
|
+
from your schema, and the warehouse is a DuckDB file that lives for the length of the job.
|
|
104
|
+
|
|
105
|
+
## What it checks, and what it cannot
|
|
106
|
+
|
|
107
|
+
**Checks**
|
|
108
|
+
|
|
109
|
+
- The changed models, everything downstream of them, and every model whose tests read them,
|
|
110
|
+
compile and run against a schema-faithful dataset.
|
|
111
|
+
- Their schema, relationship and accepted-values tests pass or fail, and which rows fail.
|
|
112
|
+
- Column renames, dropped `ref()`s and broken joins are caught before merge. dbt unit tests
|
|
113
|
+
run too, and a failing one fails the check.
|
|
114
|
+
- What the change did to the output. The base branch is built on the same fixtures, and the
|
|
115
|
+
changed models plus everything downstream are compared: columns added, removed or
|
|
116
|
+
retyped; row counts; rows whose values differ; and every metric the project defines,
|
|
117
|
+
evaluated on both sides. A refactor that moves net revenue by 4 percent shows up as a
|
|
118
|
+
number before a reviewer has to reason about the SQL.
|
|
119
|
+
- The change follows the house conventions (below).
|
|
120
|
+
|
|
121
|
+
**Cannot check**
|
|
122
|
+
|
|
123
|
+
- That production numbers are unchanged. A metric that does not move on synthetic data
|
|
124
|
+
can still move on production, because the fixtures do not carry production's
|
|
125
|
+
distribution. The diff proves the logic changed, not the size of the effect on real data.
|
|
126
|
+
- Warehouse-specific SQL that survives transpiling. Model SQL is rewritten from the
|
|
127
|
+
project's dialect to DuckDB with sqlglot (see below); a model that still fails because
|
|
128
|
+
DuckDB lacks something is reported as *not verified*, not as broken.
|
|
129
|
+
- Incremental behaviour across runs. Every preflight run is a full build on a fresh file.
|
|
130
|
+
|
|
131
|
+
## Setup
|
|
132
|
+
|
|
133
|
+
Add a workflow to the repository that holds the dbt project:
|
|
134
|
+
|
|
135
|
+
```yaml
|
|
136
|
+
# .github/workflows/preflight.yml
|
|
137
|
+
name: dbt preflight
|
|
138
|
+
on:
|
|
139
|
+
pull_request:
|
|
140
|
+
|
|
141
|
+
permissions:
|
|
142
|
+
contents: read
|
|
143
|
+
pull-requests: write
|
|
144
|
+
|
|
145
|
+
jobs:
|
|
146
|
+
preflight:
|
|
147
|
+
runs-on: ubuntu-latest
|
|
148
|
+
steps:
|
|
149
|
+
- uses: actions/checkout@v4
|
|
150
|
+
- uses: JB-Analytica/dbt-preflight@v0
|
|
151
|
+
```
|
|
152
|
+
|
|
153
|
+
`@v0` follows the latest 0.x release; pin `@v0.2.0` for an exact version. Pull requests
|
|
154
|
+
from forks run with a read-only token, so for those the report lands in the job summary
|
|
155
|
+
only, with a note saying so.
|
|
156
|
+
|
|
157
|
+
If the dbt project is not at the repository root, or its `sources.yml` reads environment
|
|
158
|
+
variables, add a `.dbt-preflight.yml` next to it:
|
|
159
|
+
|
|
160
|
+
```yaml
|
|
161
|
+
project_dir: dbt # folder holding dbt_project.yml (default: .)
|
|
162
|
+
schema: source_system/webshop.dbml # DBML describing the sources (default: derive from sources.yml)
|
|
163
|
+
rows: 200 # rows per source table
|
|
164
|
+
rows_for: # per-table overrides, for realistic fact-to-dimension ratios
|
|
165
|
+
orders: 800
|
|
166
|
+
order_items: 2000
|
|
167
|
+
seed: 42 # same seed, same data, on every run
|
|
168
|
+
locale: nl_BE # Faker locale for names and addresses
|
|
169
|
+
env: # variables your profiles.yml / sources.yml expect
|
|
170
|
+
GCP_PROJECT: preflight
|
|
171
|
+
dialect: bigquery # SQL dialect to transpile from (default: read from profiles.yml)
|
|
172
|
+
metrics: # extra metrics to compare, for projects with none defined elsewhere
|
|
173
|
+
- name: gross_revenue
|
|
174
|
+
model: fct_orders
|
|
175
|
+
sql: sum(gross_amount_eur)
|
|
176
|
+
```
|
|
177
|
+
|
|
178
|
+
That is the whole setup. Preflight writes its own `profiles.yml`, so the project's real
|
|
179
|
+
profile and its credentials are never read.
|
|
180
|
+
|
|
181
|
+
### Where the schema comes from
|
|
182
|
+
|
|
183
|
+
Preflight needs to know what the source tables look like. Three options:
|
|
184
|
+
|
|
185
|
+
1. **A DBML file** (`schema:`). If the repository already describes its source system in
|
|
186
|
+
DBML, point at it. Note hints in the DBML (weighted statuses, skewed foreign keys, null
|
|
187
|
+
rates) carry through to the fixtures, so the data behaves like a business. A change to
|
|
188
|
+
the DBML file counts as a change to every source, so everything is rebuilt.
|
|
189
|
+
2. **Derived from `sources.yml`.** With no `schema:` set, preflight reads the project's
|
|
190
|
+
sources. `unique` and `not_null` tests become keys, and `relationships` tests between
|
|
191
|
+
sources become foreign keys.
|
|
192
|
+
3. **Inferred from the staging models that read a source**, for any table `sources.yml`
|
|
193
|
+
leaves without columns, or without a `data_type` on them. Real projects (jaffle-shop, for
|
|
194
|
+
one) often declare a source with no columns at all; the staging model that does
|
|
195
|
+
`select id as customer_id, ... from {{ source(...) }}` already names every column it
|
|
196
|
+
needs, so preflight reads that instead of asking for YAML nobody wrote. An explicit
|
|
197
|
+
`cast(x as date)` or `x::date` sets the type first; failing that, how the staging SQL
|
|
198
|
+
uses the column is read next - an operand of `/`, `*`, `+`, `-` against a numeric
|
|
199
|
+
literal, or wrapped in `sum(`/`avg(`/`round(`, is numeric, while a comparison to a
|
|
200
|
+
string literal or a `lower(`/`upper(`/`trim(`/`concat(` argument is varchar. Only then
|
|
201
|
+
does the column's own name decide: `_at`/`_timestamp`/`_datetime` a timestamp,
|
|
202
|
+
`_date`/`_on` a date, `id`/`_id` an integer, `is_`/`has_`/`_flag`/`enabled`/`active` a
|
|
203
|
+
boolean, a name built from `paid`, `cost`, `tax`, `fee`, `discount`, `revenue`, `amount`,
|
|
204
|
+
`price`, `total`, `rate` and the like a decimal, one built from `count`, `number`, `qty`,
|
|
205
|
+
`quantity`, `units`, `age`, `year`, `month`, `day` an integer, and a handful of common
|
|
206
|
+
attribute names (`email`, `phone`, `name`, `status`, `type`, `sku`, ...) always varchar.
|
|
207
|
+
A name shaped like a foreign key - `customer_id`, or a bare `customer` when a
|
|
208
|
+
`raw_customers` source exists - is typed as an integer and gets a `ref:` to that table's
|
|
209
|
+
`id` when one can be found, the same referential integrity an explicit `relationships`
|
|
210
|
+
test would have set up. The comment says which columns were guessed, so a reviewer can
|
|
211
|
+
tighten them in `sources.yml` if a guess is wrong. Only a column no model reads either is
|
|
212
|
+
reported rather than guessed, because a fixture with the wrong type is worse than no
|
|
213
|
+
fixture.
|
|
214
|
+
|
|
215
|
+
A source column named `id` is always the primary key. A staging model's own `unique`/
|
|
216
|
+
`not_null` tests on the alias it gave a source column (`id as customer_id`, tested as
|
|
217
|
+
`customer_id`) carry back to that source column too - `pk` when both are declared,
|
|
218
|
+
`unique`/`not null` alone otherwise - so a project that tests its staging models instead
|
|
219
|
+
of its sources still gets keys in the derived schema.
|
|
220
|
+
|
|
221
|
+
Sources declared with `loader: dlt` get `_dlt_load_id` and `_dlt_id` added to their
|
|
222
|
+
fixtures. Other loaders can be declared under `loader_columns:` in the config.
|
|
223
|
+
|
|
224
|
+
A project with no sources at all, one whose input is its seeds, needs neither: dbt loads
|
|
225
|
+
the seeds during the build and preflight generates nothing.
|
|
226
|
+
|
|
227
|
+
### Your warehouse's SQL, on DuckDB
|
|
228
|
+
|
|
229
|
+
A project written for BigQuery says `timestamp_diff(a, b, hour)` and `initcap(x)`; DuckDB
|
|
230
|
+
has neither. Preflight transpiles each compiled model from the project's dialect to DuckDB
|
|
231
|
+
with [sqlglot](https://github.com/tobymao/sqlglot) before it runs, after dbt has resolved
|
|
232
|
+
every `ref()` and `source()`. The dialect is read from a `profiles.yml` checked into the
|
|
233
|
+
project directory (the adapter `type` of its default target), or set explicitly:
|
|
234
|
+
|
|
235
|
+
```yaml
|
|
236
|
+
dialect: bigquery # or snowflake, redshift, databricks, trino, ... ; duckdb/none to disable
|
|
237
|
+
```
|
|
238
|
+
|
|
239
|
+
A model sqlglot cannot parse runs as written and the comment says so. dbt's own SQL, and
|
|
240
|
+
generic tests rendered from macros, are never transpiled; only model bodies and singular
|
|
241
|
+
tests are.
|
|
242
|
+
|
|
243
|
+
### Metrics, from wherever the project defines them
|
|
244
|
+
|
|
245
|
+
The comment's "What changed in the output" section evaluates every metric the project
|
|
246
|
+
defines, on the base branch and on the pull request, and lists the ones that moved. Three
|
|
247
|
+
sources are read, and a project needs only one of them:
|
|
248
|
+
|
|
249
|
+
1. **dbt's semantic layer.** Semantic models and metrics in the project's YAML: `simple`
|
|
250
|
+
metrics with measure and metric filters, `ratio` and `derived` metrics, including ones
|
|
251
|
+
whose inputs sit on different models (orders per customer reads `fct_orders` and
|
|
252
|
+
`dim_customers`; each side is evaluated on its own model and the comment names both).
|
|
253
|
+
A `cumulative` metric with no window and no grain to date is a running total over all
|
|
254
|
+
time, and its final value is the plain total, so it is evaluated as one. This is the
|
|
255
|
+
route for a project that uses dbt and nothing else. A windowed or grain-to-date
|
|
256
|
+
`cumulative` metric and a `conversion` metric need a time spine and are reported as
|
|
257
|
+
not evaluated.
|
|
258
|
+
2. **Lightdash `meta.metrics`.** Aggregate metrics on columns (`sum`, `count_distinct`,
|
|
259
|
+
`average`, ... with their `filters`) and `number` metrics on the model whose `sql`
|
|
260
|
+
references other metrics with `${...}`.
|
|
261
|
+
3. **`metrics:` in `.dbt-preflight.yml`.** A name, a model and an aggregate SQL expression,
|
|
262
|
+
for teams with neither of the above.
|
|
263
|
+
|
|
264
|
+
With no metrics defined, columns, row counts and differing rows are still compared, and the
|
|
265
|
+
comment says where metrics can be defined.
|
|
266
|
+
|
|
267
|
+
## Conventions
|
|
268
|
+
|
|
269
|
+
The convention checks encode the JB Analytica warehouse conventions. They run on the
|
|
270
|
+
changed models only, so existing debt does not resurface on every pull request.
|
|
271
|
+
|
|
272
|
+
| Rule | Severity | What it wants |
|
|
273
|
+
| --- | --- | --- |
|
|
274
|
+
| `naming` | error | `staging/` models named `stg_<source>__<entity>`, `intermediate/` named `int_<entity>__<verb>`, `marts/` named `dim_<entity>` or `fct_<event>` |
|
|
275
|
+
| `layering` | error | A staging model reads exactly one `source()` and no `ref()`; nothing outside staging reads a `source()` |
|
|
276
|
+
| `primary_key` | error | At least one column tested `unique` and `not_null` |
|
|
277
|
+
| `description` | warn | The model has a description |
|
|
278
|
+
| `column_naming` | warn | snake_case; timestamps end in `_at`, dates in `_date`, booleans start with `is_` or `has_` (read from the built table's real types) |
|
|
279
|
+
|
|
280
|
+
Models outside those three folders are exempt from the naming and layering rules.
|
|
281
|
+
|
|
282
|
+
That is the `jba` preset, at full strength when the repository has a `.dbt-preflight.yml`.
|
|
283
|
+
A repository without one gets the same rules as warnings only: it never signed up for
|
|
284
|
+
anyone's conventions, and a warning is advice where an error would be a demand. A project
|
|
285
|
+
with its own conventions adjusts them in the config:
|
|
286
|
+
|
|
287
|
+
```yaml
|
|
288
|
+
conventions:
|
|
289
|
+
preset: jba # jba (default) or none
|
|
290
|
+
rules:
|
|
291
|
+
description: off # off | warn | error, per rule
|
|
292
|
+
column_naming: warn
|
|
293
|
+
layers: # folder under models/ -> regex a model name must match
|
|
294
|
+
staging: "^stg_[a-z0-9]+__[a-z0-9_]+$"
|
|
295
|
+
marts: "^(dim|fct|rpt)_[a-z0-9_]+$"
|
|
296
|
+
source_layer: staging # the only folder allowed to read source(); null allows any
|
|
297
|
+
```
|
|
298
|
+
|
|
299
|
+
## Running it locally
|
|
300
|
+
|
|
301
|
+
```bash
|
|
302
|
+
uv tool install dbt-preflight # or: pipx install dbt-preflight, pip install dbt-preflight
|
|
303
|
+
cd your-repo
|
|
304
|
+
dbt-preflight run --base-ref origin/main
|
|
305
|
+
```
|
|
306
|
+
|
|
307
|
+
Without `--base-ref`, every model counts as changed and the whole project is built. Add
|
|
308
|
+
`--comment-file preflight.md` to write the comment to a file instead of stdout, and
|
|
309
|
+
`--keep-workdir` to leave `.preflight/` (fixtures, DuckDB file, dbt artefacts) behind for
|
|
310
|
+
inspection.
|
|
311
|
+
|
|
312
|
+
## Integrating
|
|
313
|
+
|
|
314
|
+
`--summary-file preflight-summary.json` writes a JSON document alongside the comment, with
|
|
315
|
+
the verdict, counts and every finding as structured data, for a hook, a bot or a plugin to
|
|
316
|
+
act on without parsing Markdown. [docs/integration.md](https://github.com/JB-Analytica/dbt-preflight/blob/main/docs/integration.md) has the full
|
|
317
|
+
contract: every flag, the exit code, the JSON schema, and a worked pre-pull-request hook.
|
|
318
|
+
|
|
319
|
+
## How it works
|
|
320
|
+
|
|
321
|
+
1. `dbt parse` on the pull request, to learn the sources, models and tests.
|
|
322
|
+
2. Fixtures: model2data generates data for every source table, cast to the declared types,
|
|
323
|
+
loaded into a DuckDB file whose catalog is named after the sources' `database`.
|
|
324
|
+
3. `dbt parse` on the base branch in a temporary worktree, then `dbt ls --select
|
|
325
|
+
state:modified` to find what changed.
|
|
326
|
+
4. Each compiled model is transpiled from the project's dialect to DuckDB with sqlglot.
|
|
327
|
+
5. The selection is closed: downstream models, models whose tests read a changed model,
|
|
328
|
+
and all their ancestors. `dbt build` runs on that set with `--indirect-selection
|
|
329
|
+
cautious`, so every test that runs has all its inputs built.
|
|
330
|
+
6. Conventions are checked on the changed models, column rules against the built tables.
|
|
331
|
+
7. The changed models and everything downstream are built on the base branch too, into
|
|
332
|
+
their own schemas on the same fixtures, and compared: columns, row counts, differing rows
|
|
333
|
+
and metric values.
|
|
334
|
+
8. One Markdown comment, posted or updated through the GitHub API.
|
|
335
|
+
|
|
336
|
+
The bundled example in `examples/webshop/` is the JB Analytica
|
|
337
|
+
[reference architecture](https://github.com/JB-Analytica/reference-architecture)'s dbt
|
|
338
|
+
project, made portable with two `adapter.dispatch` macros. It is what the test suite and
|
|
339
|
+
the action's self-check run against.
|
|
340
|
+
|
|
341
|
+
## Development
|
|
342
|
+
|
|
343
|
+
```bash
|
|
344
|
+
uv sync --extra dev
|
|
345
|
+
uv run poe check # ruff, ty, pytest
|
|
346
|
+
```
|
|
347
|
+
|
|
348
|
+
Bugs and feature requests belong in
|
|
349
|
+
[the issue tracker](https://github.com/JB-Analytica/dbt-preflight/issues). A pull request
|
|
350
|
+
is welcome; `poe check` has to be green and, if you change what the comment says,
|
|
351
|
+
`uv run python scripts/scenarios.py` re-records the six scenarios so the change shows up
|
|
352
|
+
in `docs/scenarios/`.
|
|
353
|
+
|
|
354
|
+
## Licence
|
|
355
|
+
|
|
356
|
+
MIT. See [LICENSE](https://github.com/JB-Analytica/dbt-preflight/blob/main/LICENSE).
|