codex-transcript-viewer 0.4.0__tar.gz → 0.5.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/CHANGELOG.md +10 -0
- codex_transcript_viewer-0.4.0/README.md → codex_transcript_viewer-0.5.0/PKG-INFO +35 -1
- codex_transcript_viewer-0.4.0/PKG-INFO → codex_transcript_viewer-0.5.0/README.md +9 -23
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/pyproject.toml +5 -1
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/scripts/visual_review.py +9 -3
- codex_transcript_viewer-0.5.0/src/codex_transcript_viewer/highlight.py +108 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/html_builder.py +92 -20
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/markdown.py +82 -13
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/parser.py +40 -2
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/style.css +19 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_markdown.py +88 -1
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_output_cap.py +14 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_session_events.py +48 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/.gitignore +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/LICENSE +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/scripts/audit_sessions.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/__init__.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/cli.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/formatting.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/viewer.js +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_audit_sessions.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_custom_tools.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_exec_status.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_html_builder.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_image_budget.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_inherited_history.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_null_payload_fields.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_parser_dedup_density.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_parser_reconciliation_edge_cases.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_parser_stream_reconciliation.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_prompt_images.py +0 -0
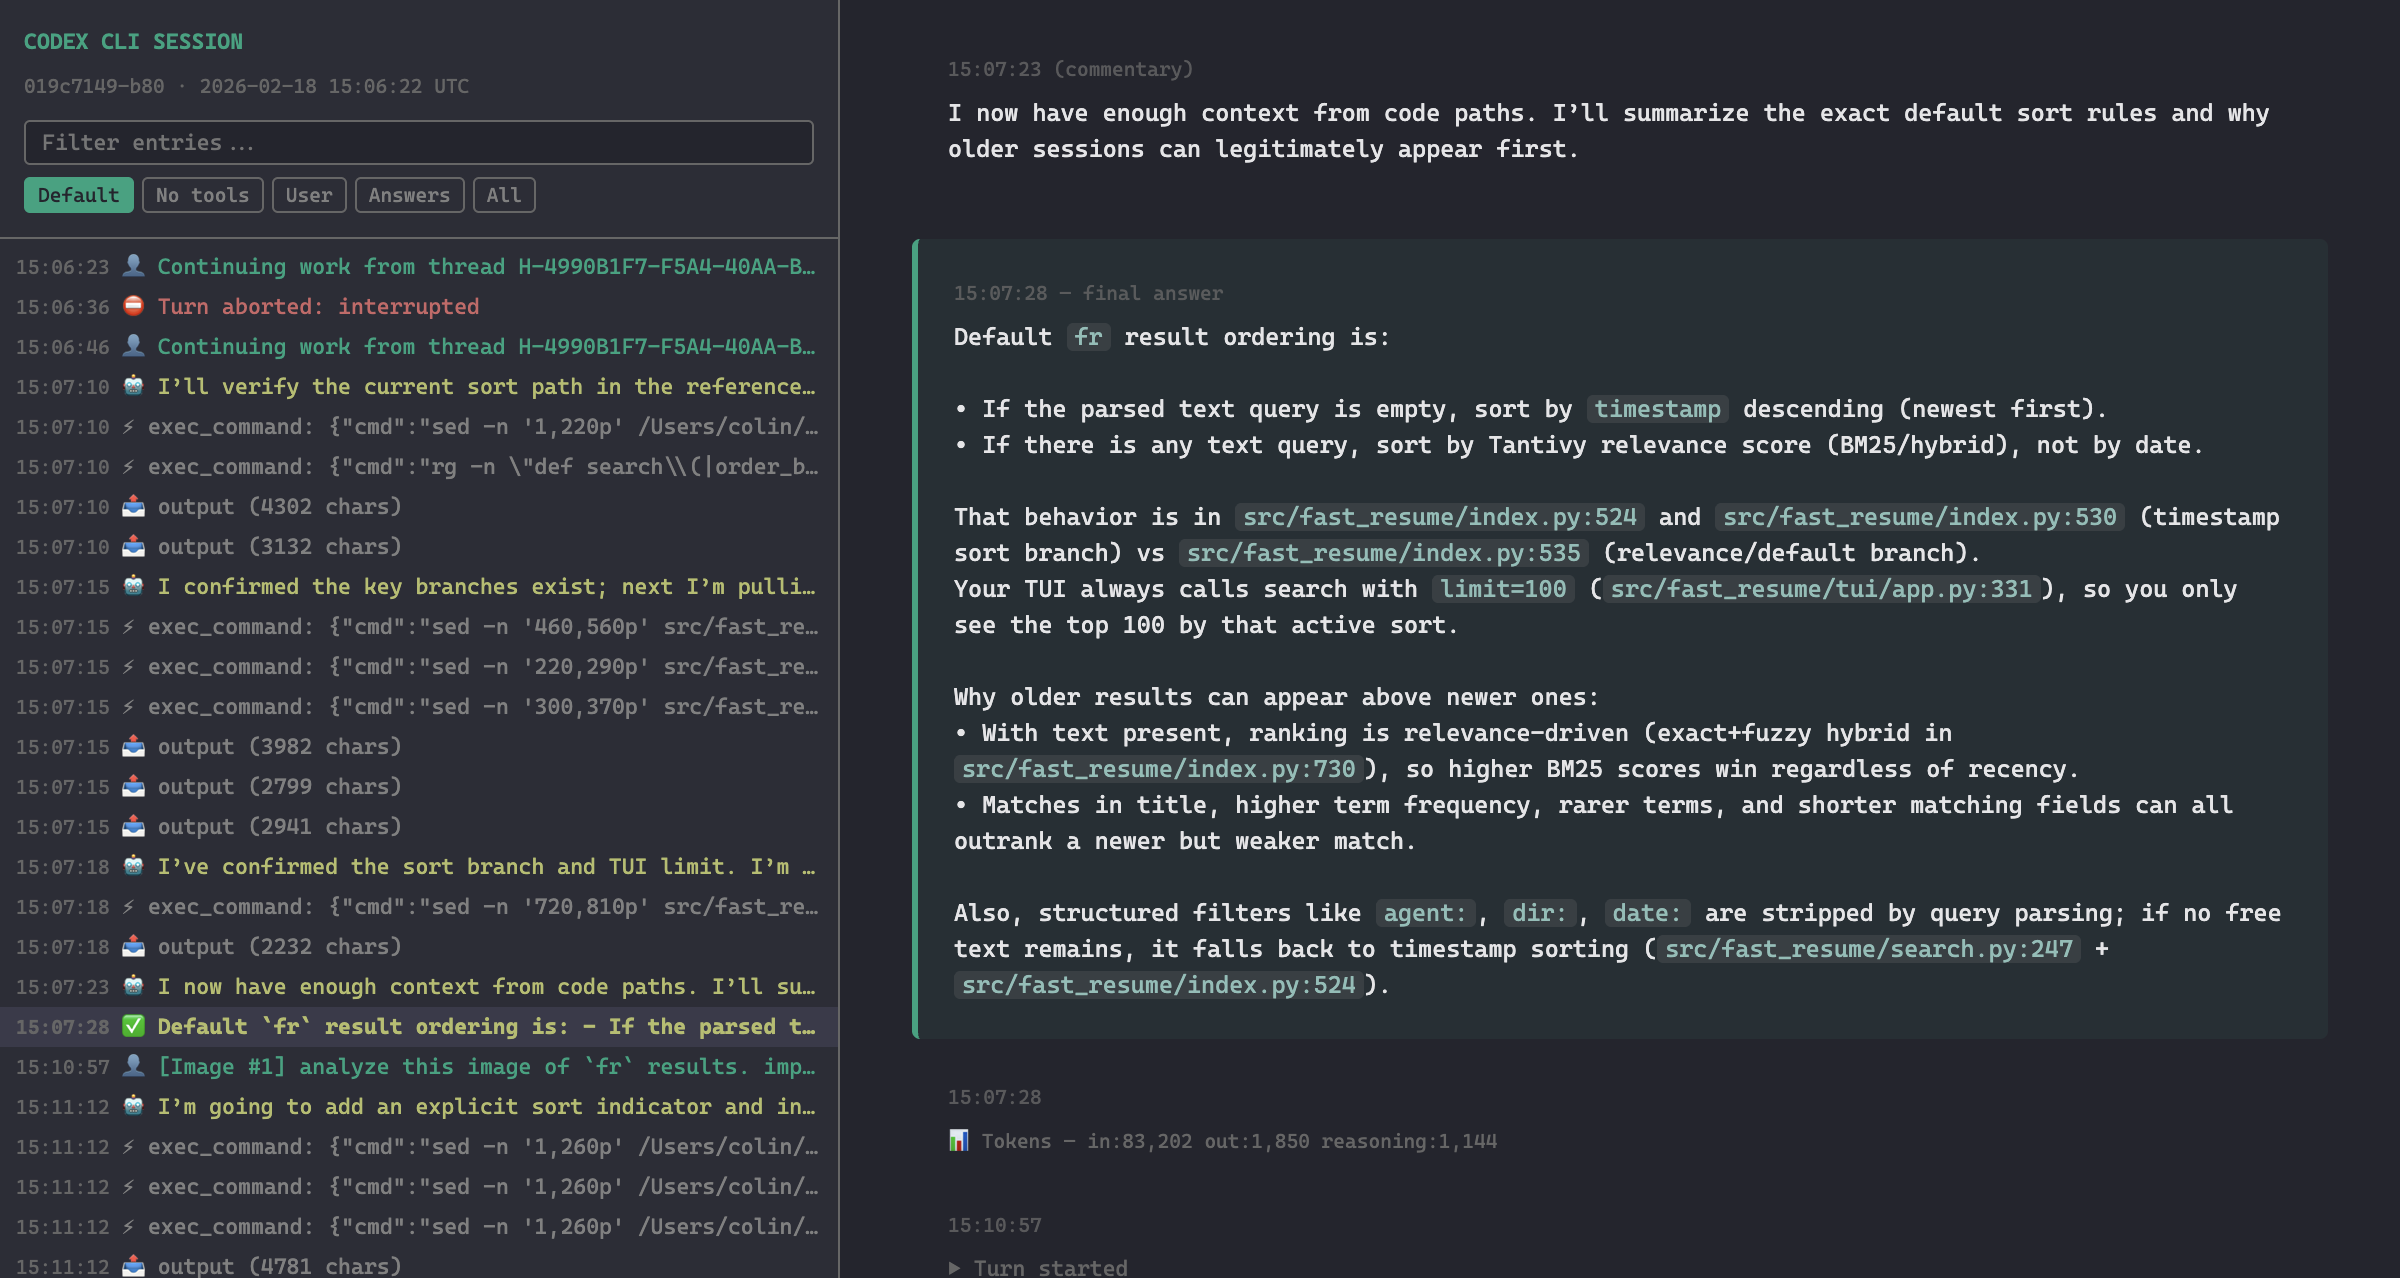
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_session_meta.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_tool_output_shapes.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_tool_search.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_tool_status.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_unrecognized_records.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_user_prompts.py +0 -0
- {codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_web_search.py +0 -0
|
@@ -1,5 +1,15 @@
|
|
|
1
1
|
# Changelog
|
|
2
2
|
|
|
3
|
+
## 0.5.0
|
|
4
|
+
|
|
5
|
+
- Short tool outputs no longer appear twice. Every output under 2,000 characters has shown its text twice since the first release; only long outputs were meant to have a preview and a full copy.
|
|
6
|
+
- Memory citations at the end of an answer fold into a small "Memory citations" section, listing each cited note and the sessions it came from, instead of printing Codex's raw citation block.
|
|
7
|
+
- The header shows the model and reasoning effort the session started with, not just "openai", and a row marks each turn that switches model or effort.
|
|
8
|
+
- Code blocks get syntax highlighting for Python, shell, JavaScript and TypeScript, JSON, TOML and YAML, SQL, diffs, and C-like languages. It's built in, so pages stay self-contained.
|
|
9
|
+
- Nested and numbered lists and blockquotes render, and reasoning summaries render as markdown instead of showing literal `**`.
|
|
10
|
+
- The demo page is rebuilt around a made-up session that shows every kind of entry, with a script to regenerate its screenshots.
|
|
11
|
+
- Dependabot keeps the workflow actions current, and the README has PyPI, Python version and test badges.
|
|
12
|
+
|
|
3
13
|
## 0.4.0
|
|
4
14
|
|
|
5
15
|
- The viewer is on PyPI: `uv tool install codex-transcript-viewer`, `pipx install codex-transcript-viewer`, or `uvx codex-transcript-viewer <session.jsonl>` to run it once.
|
|
@@ -1,5 +1,35 @@
|
|
|
1
|
+
Metadata-Version: 2.5
|
|
2
|
+
Name: codex-transcript-viewer
|
|
3
|
+
Version: 0.5.0
|
|
4
|
+
Summary: Convert Codex CLI JSONL session transcripts to self-contained HTML viewers
|
|
5
|
+
Project-URL: Homepage, https://github.com/masonc15/codex-transcript-viewer
|
|
6
|
+
Project-URL: Issues, https://github.com/masonc15/codex-transcript-viewer/issues
|
|
7
|
+
Project-URL: Changelog, https://github.com/masonc15/codex-transcript-viewer/blob/main/CHANGELOG.md
|
|
8
|
+
Author: Colin Mason
|
|
9
|
+
License-Expression: MIT
|
|
10
|
+
License-File: LICENSE
|
|
11
|
+
Keywords: codex,html,jsonl,openai,transcript,viewer
|
|
12
|
+
Classifier: Development Status :: 4 - Beta
|
|
13
|
+
Classifier: Environment :: Console
|
|
14
|
+
Classifier: Intended Audience :: Developers
|
|
15
|
+
Classifier: Operating System :: OS Independent
|
|
16
|
+
Classifier: Programming Language :: Python :: 3
|
|
17
|
+
Classifier: Programming Language :: Python :: 3 :: Only
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.14
|
|
22
|
+
Classifier: Topic :: Software Development
|
|
23
|
+
Classifier: Topic :: Utilities
|
|
24
|
+
Requires-Python: >=3.11
|
|
25
|
+
Description-Content-Type: text/markdown
|
|
26
|
+
|
|
1
27
|
# codex-transcript-viewer
|
|
2
28
|
|
|
29
|
+
[](https://pypi.org/project/codex-transcript-viewer/)
|
|
30
|
+
[](https://pypi.org/project/codex-transcript-viewer/)
|
|
31
|
+
[](https://github.com/masonc15/codex-transcript-viewer/actions/workflows/tests.yml)
|
|
32
|
+
|
|
3
33
|
Converts Codex CLI JSONL session transcripts into single-file HTML viewers with sidebar navigation, search, and filtering. No external dependencies. Just open the `.html` in any browser.
|
|
4
34
|
|
|
5
35
|
|
|
@@ -53,7 +83,7 @@ If the log contains record types the viewer doesn't know about, it says so on st
|
|
|
53
83
|
|
|
54
84
|
## What the viewer shows
|
|
55
85
|
|
|
56
|
-
The page has a sticky sidebar with a searchable event tree on the left and the transcript on the right. Your prompts get a green border, with any attached images shown as thumbnails you can click to enlarge. Final answers sit on a faint green background, commentary is italic with a muted border, and reasoning summaries are gray. Each tool call shows its command or arguments, and its result is colored by what actually happened: green when the exit code was 0, red when it failed, and neutral when the log doesn't record a status, so nothing looks successful by accident. Long outputs expand on click. Markdown in prompts and
|
|
86
|
+
The page has a sticky sidebar with a searchable event tree on the left and the transcript on the right. Your prompts get a green border, with any attached images shown as thumbnails you can click to enlarge. Final answers sit on a faint green background, commentary is italic with a muted border, and reasoning summaries are gray. Each tool call shows its command or arguments, and its result is colored by what actually happened: green when the exit code was 0, red when it failed, and neutral when the log doesn't record a status, so nothing looks successful by accident. Long outputs expand on click. Markdown in prompts, answers and reasoning renders, including tables, nested lists, blockquotes and syntax-highlighted code; web links open in a new tab, and links to local files show their full path on hover. When Codex ends an answer with a memory-citation block, it's folded into a small "Memory citations" section instead of printed raw. Generated images show up as the result of their `image_generation` call, next to the prompt the model used. Turn starts, aborts, rollbacks and token counts show up as dim system lines. The header shows the model and reasoning effort the session started with, and a highlighted row marks any turn that switches either.
|
|
57
87
|
|
|
58
88
|
Some things Codex only sends to the model, so the viewer shows them as their own highlighted entries: the objective and status changes of a `/goal`, text a hook sent back (a rejected plan, for example), review start and result markers, and errors such as hitting a usage limit. A review's findings appear in full when no reply repeats them. Newer models repeat the turn's earlier reasoning headings each time they add one, so each heading is shown once, at the point it first appeared.
|
|
59
89
|
|
|
@@ -89,6 +119,7 @@ Inspired by the HTML session export in [pi](https://github.com/badlogic/pi-mono/
|
|
|
89
119
|
src/codex_transcript_viewer/
|
|
90
120
|
parser.py - JSONL parsing and event extraction
|
|
91
121
|
markdown.py - lightweight markdown-to-HTML conversion
|
|
122
|
+
highlight.py - small built-in syntax highlighter for code blocks
|
|
92
123
|
formatting.py - timestamp formatting helpers
|
|
93
124
|
html_builder.py - assembles the final HTML from events
|
|
94
125
|
style.css - all CSS for the viewer
|
|
@@ -97,4 +128,7 @@ src/codex_transcript_viewer/
|
|
|
97
128
|
scripts/
|
|
98
129
|
audit_sessions.py - checks the parser against real sessions
|
|
99
130
|
visual_review.py - renders sessions and screenshots the sidebar
|
|
131
|
+
docs/demo/
|
|
132
|
+
make_session.py - writes the synthetic session behind docs/demo.md
|
|
133
|
+
screenshots.py - renders it and saves the demo screenshots
|
|
100
134
|
```
|
|
@@ -1,27 +1,9 @@
|
|
|
1
|
-
Metadata-Version: 2.5
|
|
2
|
-
Name: codex-transcript-viewer
|
|
3
|
-
Version: 0.4.0
|
|
4
|
-
Summary: Convert Codex CLI JSONL session transcripts to self-contained HTML viewers
|
|
5
|
-
Project-URL: Homepage, https://github.com/masonc15/codex-transcript-viewer
|
|
6
|
-
Project-URL: Issues, https://github.com/masonc15/codex-transcript-viewer/issues
|
|
7
|
-
Project-URL: Changelog, https://github.com/masonc15/codex-transcript-viewer/blob/main/CHANGELOG.md
|
|
8
|
-
Author: Colin Mason
|
|
9
|
-
License-Expression: MIT
|
|
10
|
-
License-File: LICENSE
|
|
11
|
-
Keywords: codex,html,jsonl,openai,transcript,viewer
|
|
12
|
-
Classifier: Development Status :: 4 - Beta
|
|
13
|
-
Classifier: Environment :: Console
|
|
14
|
-
Classifier: Intended Audience :: Developers
|
|
15
|
-
Classifier: Operating System :: OS Independent
|
|
16
|
-
Classifier: Programming Language :: Python :: 3
|
|
17
|
-
Classifier: Programming Language :: Python :: 3 :: Only
|
|
18
|
-
Classifier: Topic :: Software Development
|
|
19
|
-
Classifier: Topic :: Utilities
|
|
20
|
-
Requires-Python: >=3.11
|
|
21
|
-
Description-Content-Type: text/markdown
|
|
22
|
-
|
|
23
1
|
# codex-transcript-viewer
|
|
24
2
|
|
|
3
|
+
[](https://pypi.org/project/codex-transcript-viewer/)
|
|
4
|
+
[](https://pypi.org/project/codex-transcript-viewer/)
|
|
5
|
+
[](https://github.com/masonc15/codex-transcript-viewer/actions/workflows/tests.yml)
|
|
6
|
+
|
|
25
7
|
Converts Codex CLI JSONL session transcripts into single-file HTML viewers with sidebar navigation, search, and filtering. No external dependencies. Just open the `.html` in any browser.
|
|
26
8
|
|
|
27
9
|

|
|
@@ -75,7 +57,7 @@ If the log contains record types the viewer doesn't know about, it says so on st
|
|
|
75
57
|
|
|
76
58
|
## What the viewer shows
|
|
77
59
|
|
|
78
|
-
The page has a sticky sidebar with a searchable event tree on the left and the transcript on the right. Your prompts get a green border, with any attached images shown as thumbnails you can click to enlarge. Final answers sit on a faint green background, commentary is italic with a muted border, and reasoning summaries are gray. Each tool call shows its command or arguments, and its result is colored by what actually happened: green when the exit code was 0, red when it failed, and neutral when the log doesn't record a status, so nothing looks successful by accident. Long outputs expand on click. Markdown in prompts and
|
|
60
|
+
The page has a sticky sidebar with a searchable event tree on the left and the transcript on the right. Your prompts get a green border, with any attached images shown as thumbnails you can click to enlarge. Final answers sit on a faint green background, commentary is italic with a muted border, and reasoning summaries are gray. Each tool call shows its command or arguments, and its result is colored by what actually happened: green when the exit code was 0, red when it failed, and neutral when the log doesn't record a status, so nothing looks successful by accident. Long outputs expand on click. Markdown in prompts, answers and reasoning renders, including tables, nested lists, blockquotes and syntax-highlighted code; web links open in a new tab, and links to local files show their full path on hover. When Codex ends an answer with a memory-citation block, it's folded into a small "Memory citations" section instead of printed raw. Generated images show up as the result of their `image_generation` call, next to the prompt the model used. Turn starts, aborts, rollbacks and token counts show up as dim system lines. The header shows the model and reasoning effort the session started with, and a highlighted row marks any turn that switches either.
|
|
79
61
|
|
|
80
62
|
Some things Codex only sends to the model, so the viewer shows them as their own highlighted entries: the objective and status changes of a `/goal`, text a hook sent back (a rejected plan, for example), review start and result markers, and errors such as hitting a usage limit. A review's findings appear in full when no reply repeats them. Newer models repeat the turn's earlier reasoning headings each time they add one, so each heading is shown once, at the point it first appeared.
|
|
81
63
|
|
|
@@ -111,6 +93,7 @@ Inspired by the HTML session export in [pi](https://github.com/badlogic/pi-mono/
|
|
|
111
93
|
src/codex_transcript_viewer/
|
|
112
94
|
parser.py - JSONL parsing and event extraction
|
|
113
95
|
markdown.py - lightweight markdown-to-HTML conversion
|
|
96
|
+
highlight.py - small built-in syntax highlighter for code blocks
|
|
114
97
|
formatting.py - timestamp formatting helpers
|
|
115
98
|
html_builder.py - assembles the final HTML from events
|
|
116
99
|
style.css - all CSS for the viewer
|
|
@@ -119,4 +102,7 @@ src/codex_transcript_viewer/
|
|
|
119
102
|
scripts/
|
|
120
103
|
audit_sessions.py - checks the parser against real sessions
|
|
121
104
|
visual_review.py - renders sessions and screenshots the sidebar
|
|
105
|
+
docs/demo/
|
|
106
|
+
make_session.py - writes the synthetic session behind docs/demo.md
|
|
107
|
+
screenshots.py - renders it and saves the demo screenshots
|
|
122
108
|
```
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
[project]
|
|
2
2
|
name = "codex-transcript-viewer"
|
|
3
|
-
version = "0.
|
|
3
|
+
version = "0.5.0"
|
|
4
4
|
description = "Convert Codex CLI JSONL session transcripts to self-contained HTML viewers"
|
|
5
5
|
readme = "README.md"
|
|
6
6
|
requires-python = ">=3.11"
|
|
@@ -15,6 +15,10 @@ classifiers = [
|
|
|
15
15
|
"Operating System :: OS Independent",
|
|
16
16
|
"Programming Language :: Python :: 3",
|
|
17
17
|
"Programming Language :: Python :: 3 :: Only",
|
|
18
|
+
"Programming Language :: Python :: 3.11",
|
|
19
|
+
"Programming Language :: Python :: 3.12",
|
|
20
|
+
"Programming Language :: Python :: 3.13",
|
|
21
|
+
"Programming Language :: Python :: 3.14",
|
|
18
22
|
"Topic :: Software Development",
|
|
19
23
|
"Topic :: Utilities",
|
|
20
24
|
]
|
|
@@ -10,7 +10,8 @@ format the archive contains gets looked at before a release.
|
|
|
10
10
|
|
|
11
11
|
For each session this writes <name>-sidebar-N.png tiles covering the first
|
|
12
12
|
--rows sidebar entries, and prints any turn where two message entries carry the
|
|
13
|
-
same text in the rendered page
|
|
13
|
+
same text in the rendered page, plus any tool output that shows two visible
|
|
14
|
+
copies of its text. A repeat between two kinds of entry in the
|
|
14
15
|
same role (commentary and a final answer, say) is how an event_msg copy
|
|
15
16
|
slipping past dedup looks, and fails the run. Other repeats are listed for the
|
|
16
17
|
reviewer: within one kind it is usually the model repeating itself, and across
|
|
@@ -66,6 +67,9 @@ FIND_REPEATS = """
|
|
|
66
67
|
}
|
|
67
68
|
seen.set(text, kind);
|
|
68
69
|
}
|
|
70
|
+
// A tool output must show one block of text; two visible copies is a render bug.
|
|
71
|
+
const doubled = [...document.querySelectorAll('.tool-output')].filter(out =>
|
|
72
|
+
[...out.querySelectorAll('pre')].filter(pre => pre.offsetParent !== null).length > 1).length;
|
|
69
73
|
// Let the entry list grow to its full height so it can be screenshotted.
|
|
70
74
|
const sidebar = document.getElementById('sidebar');
|
|
71
75
|
sidebar.style.position = 'static';
|
|
@@ -75,7 +79,7 @@ FIND_REPEATS = """
|
|
|
75
79
|
tree.style.overflow = 'visible';
|
|
76
80
|
tree.style.flex = 'none';
|
|
77
81
|
nodes.filter(n => n.style.display !== 'none').slice(maxRows).forEach(n => n.style.display = 'none');
|
|
78
|
-
return {rows: nodes.length, repeats};
|
|
82
|
+
return {rows: nodes.length, repeats, doubled};
|
|
79
83
|
}
|
|
80
84
|
"""
|
|
81
85
|
|
|
@@ -141,7 +145,9 @@ def main(argv: list[str] | None = None) -> int:
|
|
|
141
145
|
page.set_viewport_size({"width": 1440, "height": 900})
|
|
142
146
|
|
|
143
147
|
cross = [r for r in result["repeats"] if r["cross"]]
|
|
144
|
-
found += len(cross)
|
|
148
|
+
found += len(cross) + result["doubled"]
|
|
149
|
+
if result["doubled"]:
|
|
150
|
+
print(f" {result['doubled']} tool outputs show their text twice")
|
|
145
151
|
print(f"== {session.name}: {result['rows']} sidebar rows, {len(tiles)} tiles in {args.out}")
|
|
146
152
|
print(f" {len(cross)} repeats between entry kinds in one role, "
|
|
147
153
|
f"{len(result['repeats']) - len(cross)} other repeats")
|
|
@@ -0,0 +1,108 @@
|
|
|
1
|
+
"""A small built-in syntax highlighter for fenced code blocks.
|
|
2
|
+
|
|
3
|
+
Pages stay self-contained with no dependencies, so this is a regex tokenizer
|
|
4
|
+
for the languages Codex writes most, not a real lexer. It colors comments,
|
|
5
|
+
strings, numbers and keywords; diffs get added, removed and hunk lines.
|
|
6
|
+
"""
|
|
7
|
+
|
|
8
|
+
from __future__ import annotations
|
|
9
|
+
|
|
10
|
+
import html
|
|
11
|
+
import re
|
|
12
|
+
|
|
13
|
+
_PY_KEYWORDS = (
|
|
14
|
+
"False None True and as assert async await break class continue def del elif else "
|
|
15
|
+
"except finally for from global if import in is lambda match nonlocal not or pass "
|
|
16
|
+
"raise return try while with yield case self"
|
|
17
|
+
)
|
|
18
|
+
_SHELL_KEYWORDS = (
|
|
19
|
+
"if then else elif fi for while until do done case esac function in select return "
|
|
20
|
+
"export local readonly declare set unset source exit break continue"
|
|
21
|
+
)
|
|
22
|
+
_JS_KEYWORDS = (
|
|
23
|
+
"async await break case catch class const continue debugger default delete do else "
|
|
24
|
+
"enum export extends false finally for from function if implements import in "
|
|
25
|
+
"instanceof interface let new null of private protected public readonly return static "
|
|
26
|
+
"super switch this throw true try type typeof undefined var void while with yield as"
|
|
27
|
+
)
|
|
28
|
+
_C_LIKE_KEYWORDS = (
|
|
29
|
+
"as async await break case catch class const continue crate default defer do else enum "
|
|
30
|
+
"extension extern false fileprivate final fn for func func go guard if impl import in "
|
|
31
|
+
"init interface internal let loop match mod move mut nil null override package private "
|
|
32
|
+
"protocol pub public return select self Self static struct super switch throw throws "
|
|
33
|
+
"trait true try type typealias unsafe use var void where while"
|
|
34
|
+
)
|
|
35
|
+
_SQL_KEYWORDS = (
|
|
36
|
+
"select from where and or not insert into values update set delete create table index "
|
|
37
|
+
"drop alter join left right inner outer on group by order having limit offset as "
|
|
38
|
+
"distinct union all null is in like between case when then else end primary key"
|
|
39
|
+
)
|
|
40
|
+
|
|
41
|
+
_STRINGS = r'"(?:[^"\\\n]|\\.)*"|\'(?:[^\'\\\n]|\\.)*\''
|
|
42
|
+
_NUMBER = r"\b(?:0[xX][0-9a-fA-F]+|\d+(?:\.\d+)?(?:[eE][+-]?\d+)?)\b"
|
|
43
|
+
|
|
44
|
+
|
|
45
|
+
def _spec(comment: str, strings: str, keywords: str, flags: int = 0) -> re.Pattern:
|
|
46
|
+
words = "|".join(sorted(set(keywords.split()), key=len, reverse=True))
|
|
47
|
+
return re.compile(
|
|
48
|
+
rf"(?P<comment>{comment})|(?P<string>{strings})|(?P<number>{_NUMBER})"
|
|
49
|
+
rf"|(?P<keyword>\b(?:{words})\b)",
|
|
50
|
+
flags,
|
|
51
|
+
)
|
|
52
|
+
|
|
53
|
+
|
|
54
|
+
_PYTHON = _spec(r"#[^\n]*", r'[rRbBfFuU]{0,2}(?:"""[\s\S]*?"""|\'\'\'[\s\S]*?\'\'\'|' + _STRINGS + ")", _PY_KEYWORDS)
|
|
55
|
+
_SHELL = _spec(r"(?<![\w$\\{])#[^\n]*", _STRINGS, _SHELL_KEYWORDS)
|
|
56
|
+
_JS = _spec(r"//[^\n]*|/\*[\s\S]*?\*/", _STRINGS + r"|`(?:[^`\\]|\\.)*`", _JS_KEYWORDS)
|
|
57
|
+
_C_LIKE = _spec(r"//[^\n]*|/\*[\s\S]*?\*/", _STRINGS, _C_LIKE_KEYWORDS)
|
|
58
|
+
_JSON = _spec(r"(?!)", r'"(?:[^"\\\n]|\\.)*"', "true false null")
|
|
59
|
+
_CONFIG = _spec(r"#[^\n]*", _STRINGS, "true false yes no null on off")
|
|
60
|
+
_SQL = _spec(r"--[^\n]*", _STRINGS, _SQL_KEYWORDS, re.IGNORECASE)
|
|
61
|
+
|
|
62
|
+
_LANGUAGES = {
|
|
63
|
+
**dict.fromkeys(("python", "py", "python3"), _PYTHON),
|
|
64
|
+
**dict.fromkeys(("bash", "sh", "shell", "zsh", "console", "shellscript"), _SHELL),
|
|
65
|
+
**dict.fromkeys(("javascript", "js", "jsx", "mjs", "cjs", "typescript", "ts", "tsx"), _JS),
|
|
66
|
+
**dict.fromkeys(
|
|
67
|
+
("rust", "rs", "go", "golang", "swift", "c", "cpp", "h", "java", "kotlin", "kt", "cs", "csharp"),
|
|
68
|
+
_C_LIKE,
|
|
69
|
+
),
|
|
70
|
+
**dict.fromkeys(("json", "jsonc", "jsonl"), _JSON),
|
|
71
|
+
**dict.fromkeys(("toml", "yaml", "yml", "ini", "conf"), _CONFIG),
|
|
72
|
+
"sql": _SQL,
|
|
73
|
+
}
|
|
74
|
+
|
|
75
|
+
|
|
76
|
+
def highlight(code: str, lang: str) -> str | None:
|
|
77
|
+
"""Escaped, highlighted HTML for ``code``, or None for an unknown language."""
|
|
78
|
+
lang = lang.lower()
|
|
79
|
+
if lang in ("diff", "patch"):
|
|
80
|
+
return _highlight_diff(code)
|
|
81
|
+
pattern = _LANGUAGES.get(lang)
|
|
82
|
+
if pattern is None:
|
|
83
|
+
return None
|
|
84
|
+
out: list[str] = []
|
|
85
|
+
last = 0
|
|
86
|
+
for match in pattern.finditer(code):
|
|
87
|
+
out.append(html.escape(code[last : match.start()]))
|
|
88
|
+
out.append(f'<span class="tok-{match.lastgroup}">{html.escape(match.group())}</span>')
|
|
89
|
+
last = match.end()
|
|
90
|
+
out.append(html.escape(code[last:]))
|
|
91
|
+
return "".join(out)
|
|
92
|
+
|
|
93
|
+
|
|
94
|
+
def _highlight_diff(code: str) -> str:
|
|
95
|
+
lines = []
|
|
96
|
+
for line in code.split("\n"):
|
|
97
|
+
kind = None
|
|
98
|
+
if line.startswith(("+++", "---")):
|
|
99
|
+
kind = "meta"
|
|
100
|
+
elif line.startswith("+"):
|
|
101
|
+
kind = "added"
|
|
102
|
+
elif line.startswith("-"):
|
|
103
|
+
kind = "removed"
|
|
104
|
+
elif line.startswith("@@"):
|
|
105
|
+
kind = "hunk"
|
|
106
|
+
escaped = html.escape(line)
|
|
107
|
+
lines.append(f'<span class="tok-{kind}">{escaped}</span>' if kind else escaped)
|
|
108
|
+
return "\n".join(lines)
|
|
@@ -9,7 +9,7 @@ from datetime import datetime
|
|
|
9
9
|
from importlib import resources
|
|
10
10
|
|
|
11
11
|
from .formatting import format_ts, format_ts_full
|
|
12
|
-
from .markdown import escape, render_markdown
|
|
12
|
+
from .markdown import escape, render_markdown, split_memory_citations
|
|
13
13
|
|
|
14
14
|
|
|
15
15
|
def _load_asset(name: str) -> str:
|
|
@@ -66,7 +66,7 @@ def build_html(
|
|
|
66
66
|
elif evt["type"] == "tool_call":
|
|
67
67
|
ctx.names_by_call.setdefault(call_id, evt.get("name", ""))
|
|
68
68
|
session_id = meta.get("id", "unknown") if meta else "unknown"
|
|
69
|
-
model = meta
|
|
69
|
+
model = _session_model(meta, events)
|
|
70
70
|
cli_version = meta.get("cli_version", "") if meta else ""
|
|
71
71
|
cwd = meta.get("cwd", "") if meta else ""
|
|
72
72
|
branch = meta.get("git", {}).get("branch", "") if meta else ""
|
|
@@ -134,6 +134,19 @@ def build_html(
|
|
|
134
134
|
)
|
|
135
135
|
|
|
136
136
|
|
|
137
|
+
def _session_model(meta: dict | None, events: list[dict]) -> str:
|
|
138
|
+
"""The first turn's model and effort, falling back to the provider name.
|
|
139
|
+
|
|
140
|
+
A forked subagent's copied parent turns come first, so its own turns win.
|
|
141
|
+
"""
|
|
142
|
+
settings = [e for e in events if e.get("type") == "turn_settings"]
|
|
143
|
+
first = next((e for e in settings if not e.get("inherited")), settings[0] if settings else None)
|
|
144
|
+
if first:
|
|
145
|
+
effort = f" ({first['effort']} effort)" if first.get("effort") else ""
|
|
146
|
+
return first["model"] + effort
|
|
147
|
+
return meta.get("model_provider", "") if meta else ""
|
|
148
|
+
|
|
149
|
+
|
|
137
150
|
def _subagent_info_html(meta: dict | None, events: list[dict]) -> str:
|
|
138
151
|
"""Header rows that identify a subagent thread and its parent."""
|
|
139
152
|
source = meta.get("source") if isinstance(meta, dict) else None
|
|
@@ -304,12 +317,12 @@ def _render_reasoning(evt, ts, anchor, sidebar, messages, ctx):
|
|
|
304
317
|
sidebar.append(
|
|
305
318
|
f'<a class="tree-node tree-role-thinking" href="#{anchor}">'
|
|
306
319
|
f'<span class="tree-ts">{ts}</span> '
|
|
307
|
-
f'<span class="tree-content">\U0001f4ad {escape(evt["text"][:60])}</span></a>'
|
|
320
|
+
f'<span class="tree-content">\U0001f4ad {escape(evt["text"].replace("**", "")[:60])}</span></a>'
|
|
308
321
|
)
|
|
309
322
|
messages.append(
|
|
310
323
|
f'<div class="thinking-block" id="{anchor}">'
|
|
311
324
|
f'<div class="message-timestamp">{ts}</div>'
|
|
312
|
-
f'<div class="thinking-text">{
|
|
325
|
+
f'<div class="thinking-text markdown-content">{render_markdown(evt["text"])}</div>'
|
|
313
326
|
f"</div>"
|
|
314
327
|
)
|
|
315
328
|
|
|
@@ -318,12 +331,12 @@ def _render_agent_commentary(evt, ts, anchor, sidebar, messages, ctx):
|
|
|
318
331
|
sidebar.append(
|
|
319
332
|
f'<a class="tree-node tree-role-assistant" href="#{anchor}">'
|
|
320
333
|
f'<span class="tree-ts">{ts}</span> '
|
|
321
|
-
f'<span class="tree-content">\U0001f4ac {escape(evt["text"]
|
|
334
|
+
f'<span class="tree-content">\U0001f4ac {escape(_reply_preview(evt["text"]))}</span></a>'
|
|
322
335
|
)
|
|
323
336
|
messages.append(
|
|
324
337
|
f'<div class="commentary-message" id="{anchor}">'
|
|
325
338
|
f'<div class="message-timestamp">{ts}</div>'
|
|
326
|
-
f
|
|
339
|
+
f"{_render_reply(evt['text'])}"
|
|
327
340
|
f"</div>"
|
|
328
341
|
)
|
|
329
342
|
|
|
@@ -333,7 +346,7 @@ def _render_assistant_text(evt, ts, anchor, sidebar, messages, ctx):
|
|
|
333
346
|
_render_task_complete(evt, ts, anchor, sidebar, messages, ctx)
|
|
334
347
|
return
|
|
335
348
|
phase_label = f' ({evt["phase"]})' if evt.get("phase") else ""
|
|
336
|
-
preview = evt["text"]
|
|
349
|
+
preview = _reply_preview(evt["text"])
|
|
337
350
|
sidebar.append(
|
|
338
351
|
f'<a class="tree-node tree-role-assistant" data-kind="assistant" href="#{anchor}">'
|
|
339
352
|
f'<span class="tree-ts">{ts}</span> '
|
|
@@ -342,11 +355,44 @@ def _render_assistant_text(evt, ts, anchor, sidebar, messages, ctx):
|
|
|
342
355
|
messages.append(
|
|
343
356
|
f'<div class="assistant-message" id="{anchor}">'
|
|
344
357
|
f'<div class="message-timestamp">{ts}{escape(phase_label)}</div>'
|
|
345
|
-
f'
|
|
358
|
+
f'{_render_reply(evt["text"], "assistant-text ")}'
|
|
346
359
|
f"</div>"
|
|
347
360
|
)
|
|
348
361
|
|
|
349
362
|
|
|
363
|
+
def _reply_preview(text: str) -> str:
|
|
364
|
+
"""Sidebar text for an assistant message, without its memory citations."""
|
|
365
|
+
return split_memory_citations(text)[0][:60].replace("\n", " ")
|
|
366
|
+
|
|
367
|
+
|
|
368
|
+
def _render_reply(text: str, extra_class: str = "") -> str:
|
|
369
|
+
"""An assistant message, with its memory citations folded away at the end."""
|
|
370
|
+
body, entries, rollouts = split_memory_citations(text)
|
|
371
|
+
html = f'<div class="{extra_class}markdown-content">{render_markdown(body)}</div>'
|
|
372
|
+
if not entries and not rollouts:
|
|
373
|
+
return html
|
|
374
|
+
items = "".join(
|
|
375
|
+
f'<li><span class="citation-location">{escape(entry["location"])}</span>'
|
|
376
|
+
+ (f" \u2014 {escape(entry['note'])}" if entry["note"] else "")
|
|
377
|
+
+ "</li>"
|
|
378
|
+
for entry in entries
|
|
379
|
+
)
|
|
380
|
+
parts = [f"{len(entries)} memory entr{'y' if len(entries) == 1 else 'ies'}"] if entries else []
|
|
381
|
+
if rollouts:
|
|
382
|
+
parts.append(f"{len(rollouts)} earlier session{'' if len(rollouts) == 1 else 's'}")
|
|
383
|
+
sessions = (
|
|
384
|
+
'<div class="citation-rollouts">Sessions: '
|
|
385
|
+
+ ", ".join(f"<code>{escape(r)}</code>" for r in rollouts)
|
|
386
|
+
+ "</div>"
|
|
387
|
+
if rollouts
|
|
388
|
+
else ""
|
|
389
|
+
)
|
|
390
|
+
return (
|
|
391
|
+
f'{html}<details class="memory-citations"><summary>Memory citations: '
|
|
392
|
+
f'{" from ".join(parts)}</summary><ul>{items}</ul>{sessions}</details>'
|
|
393
|
+
)
|
|
394
|
+
|
|
395
|
+
|
|
350
396
|
def _compact_json(value):
|
|
351
397
|
return json.dumps(value, ensure_ascii=False, separators=(",", ":"))
|
|
352
398
|
|
|
@@ -486,12 +532,16 @@ def _render_tool_output(evt, ts, anchor, sidebar, messages, ctx):
|
|
|
486
532
|
f'<span class="tree-content">\U0001f4e4 output ({size_label}){marker}</span></a>'
|
|
487
533
|
)
|
|
488
534
|
|
|
489
|
-
|
|
490
|
-
|
|
491
|
-
|
|
492
|
-
|
|
493
|
-
|
|
494
|
-
|
|
535
|
+
if truncated:
|
|
536
|
+
# A long output shows its first 2,000 characters until clicked.
|
|
537
|
+
body = (
|
|
538
|
+
'<div class="tool-output expandable" onclick="this.classList.toggle(\'expanded\')">'
|
|
539
|
+
f'<div class="output-preview"><pre>{escape(preview)}\n'
|
|
540
|
+
f'<span class="expand-hint">[click to expand {len(output)} chars]</span></pre></div>'
|
|
541
|
+
f'<div class="output-full"><pre>{escape(shown)}{escape(omitted)}</pre></div></div>'
|
|
542
|
+
)
|
|
543
|
+
else:
|
|
544
|
+
body = f'<div class="tool-output"><pre>{escape(shown)}{escape(omitted)}</pre></div>'
|
|
495
545
|
|
|
496
546
|
output_images = _render_attachments(
|
|
497
547
|
attachments, ctx, default_label="image output", budgeted=True
|
|
@@ -502,15 +552,12 @@ def _render_tool_output(evt, ts, anchor, sidebar, messages, ctx):
|
|
|
502
552
|
f'<div class="tool-execution {status}" id="{anchor}">'
|
|
503
553
|
f'<div class="tool-header"><span class="tool-name">{label}</span>'
|
|
504
554
|
f"{_status_badge(evt, status)}</div>"
|
|
505
|
-
f
|
|
506
|
-
f'<div class="output-preview"><pre>{escape(preview)}{expand_hint}</pre></div>'
|
|
507
|
-
f'<div class="output-full"><pre>{escape(shown)}{escape(omitted)}</pre></div>'
|
|
508
|
-
f"</div>{output_images}</div>"
|
|
555
|
+
f"{body}{output_images}</div>"
|
|
509
556
|
)
|
|
510
557
|
|
|
511
558
|
|
|
512
559
|
def _render_task_complete(evt, ts, anchor, sidebar, messages, ctx):
|
|
513
|
-
preview = evt["text"]
|
|
560
|
+
preview = _reply_preview(evt["text"])
|
|
514
561
|
sidebar.append(
|
|
515
562
|
f'<a class="tree-node tree-role-assistant" data-kind="final-answer" href="#{anchor}">'
|
|
516
563
|
f'<span class="tree-ts">{ts}</span> '
|
|
@@ -519,7 +566,7 @@ def _render_task_complete(evt, ts, anchor, sidebar, messages, ctx):
|
|
|
519
566
|
messages.append(
|
|
520
567
|
f'<div class="assistant-message final-answer" id="{anchor}">'
|
|
521
568
|
f'<div class="message-timestamp">{ts} \u2014 final answer</div>'
|
|
522
|
-
f'
|
|
569
|
+
f'{_render_reply(evt["text"], "assistant-text ")}'
|
|
523
570
|
f"</div>"
|
|
524
571
|
)
|
|
525
572
|
|
|
@@ -691,6 +738,30 @@ def _render_hook_prompt(evt, ts, anchor, sidebar, messages, ctx):
|
|
|
691
738
|
label=f"\U0001fa9d {hook}: {preview}", title=f"\U0001fa9d {hook}", body=body)
|
|
692
739
|
|
|
693
740
|
|
|
741
|
+
def _render_turn_settings(evt, ts, anchor, sidebar, messages, ctx):
|
|
742
|
+
effort = evt.get("effort")
|
|
743
|
+
if evt.get("first"):
|
|
744
|
+
label = f"\u2699 {evt['model']}" + (f", {effort} effort" if effort else "")
|
|
745
|
+
sidebar.append(
|
|
746
|
+
f'<a class="tree-node tree-role-system" href="#{anchor}">'
|
|
747
|
+
f'<span class="tree-ts">{ts}</span> '
|
|
748
|
+
f'<span class="tree-content">{escape(label)}</span></a>'
|
|
749
|
+
)
|
|
750
|
+
messages.append(
|
|
751
|
+
f'<div class="system-event" id="{anchor}">'
|
|
752
|
+
f'<div class="message-timestamp">{ts}</div>'
|
|
753
|
+
f'<span class="event-label">{escape(label)}</span></div>'
|
|
754
|
+
)
|
|
755
|
+
return
|
|
756
|
+
changes = []
|
|
757
|
+
if evt["model"] != evt.get("previous_model"):
|
|
758
|
+
changes.append(f"model {evt.get('previous_model')} \u2192 {evt['model']}")
|
|
759
|
+
if effort != evt.get("previous_effort"):
|
|
760
|
+
changes.append(f"effort {evt.get('previous_effort') or 'default'} \u2192 {effort or 'default'}")
|
|
761
|
+
_event_row(anchor, ts, sidebar, messages, role="event", kind="settings",
|
|
762
|
+
label="\u2699 Switched " + ", ".join(changes))
|
|
763
|
+
|
|
764
|
+
|
|
694
765
|
def _render_error(evt, ts, anchor, sidebar, messages, ctx):
|
|
695
766
|
_event_row(anchor, ts, sidebar, messages, role="error", kind="",
|
|
696
767
|
label=f"\u26a0 {evt.get('message') or 'Error'}")
|
|
@@ -713,6 +784,7 @@ _EVENT_HANDLERS = {
|
|
|
713
784
|
"review_finished": _render_review_finished,
|
|
714
785
|
"hook_prompt": _render_hook_prompt,
|
|
715
786
|
"error": _render_error,
|
|
787
|
+
"turn_settings": _render_turn_settings,
|
|
716
788
|
}
|
|
717
789
|
|
|
718
790
|
|
|
@@ -5,6 +5,8 @@ from __future__ import annotations
|
|
|
5
5
|
import html
|
|
6
6
|
import re
|
|
7
7
|
|
|
8
|
+
from .highlight import highlight
|
|
9
|
+
|
|
8
10
|
|
|
9
11
|
def escape(text: str | None) -> str:
|
|
10
12
|
"""HTML-escape text, returning empty string for None."""
|
|
@@ -27,9 +29,10 @@ _TABLE_SEPARATOR_RE = re.compile(r"^\s*\|?\s*:?-+:?\s*(\|\s*:?-+:?\s*)*\|?\s*$")
|
|
|
27
29
|
def render_markdown(text: str) -> str:
|
|
28
30
|
"""Convert the markdown Codex writes to HTML.
|
|
29
31
|
|
|
30
|
-
Handles fenced code blocks
|
|
31
|
-
|
|
32
|
-
|
|
32
|
+
Handles fenced code blocks (highlighted for common languages), inline code,
|
|
33
|
+
bold, italic, headers, bullet and numbered lists at any depth, blockquotes,
|
|
34
|
+
links and pipe tables. Intended for session transcript content where full
|
|
35
|
+
CommonMark compliance is unnecessary.
|
|
33
36
|
"""
|
|
34
37
|
slots: list[str] = []
|
|
35
38
|
|
|
@@ -40,12 +43,7 @@ def render_markdown(text: str) -> str:
|
|
|
40
43
|
escaped = escape(text)
|
|
41
44
|
|
|
42
45
|
# Fenced code blocks (```lang ... ```)
|
|
43
|
-
escaped = re.sub(
|
|
44
|
-
r"```(\w*)\n(.*?)```",
|
|
45
|
-
lambda m: park(f'<pre><code class="language-{m.group(1)}">{m.group(2)}</code></pre>'),
|
|
46
|
-
escaped,
|
|
47
|
-
flags=re.DOTALL,
|
|
48
|
-
)
|
|
46
|
+
escaped = re.sub(r"```([\w+#-]*)\n(.*?)```", lambda m: park(_code_block(*m.groups())), escaped, flags=re.DOTALL)
|
|
49
47
|
|
|
50
48
|
# Inline code
|
|
51
49
|
escaped = re.sub(r"`([^`\n]+)`", lambda m: park(f"<code>{m.group(1)}</code>"), escaped)
|
|
@@ -55,6 +53,15 @@ def render_markdown(text: str) -> str:
|
|
|
55
53
|
escaped = _AUTOLINK_RE.sub(lambda m: park(_link(m.group(1), m.group(1))), escaped)
|
|
56
54
|
escaped = _BARE_URL_RE.sub(lambda m: park(_link(m.group(1), m.group(1))), escaped)
|
|
57
55
|
|
|
56
|
+
# List items, before emphasis so a "* " bullet is not read as italics
|
|
57
|
+
escaped = re.sub(r"^( *)[-*+] (?=\S)", _bullet, escaped, flags=re.MULTILINE)
|
|
58
|
+
escaped = re.sub(
|
|
59
|
+
r"^( *)(\d+)[.)] (?=\S)",
|
|
60
|
+
lambda m: park(f'{m.group(1)}<span class="md-list-number">{m.group(2)}.</span> '),
|
|
61
|
+
escaped,
|
|
62
|
+
flags=re.MULTILINE,
|
|
63
|
+
)
|
|
64
|
+
|
|
58
65
|
# Bold
|
|
59
66
|
escaped = re.sub(r"\*\*(.+?)\*\*", r"<strong>\1</strong>", escaped)
|
|
60
67
|
|
|
@@ -74,15 +81,77 @@ def render_markdown(text: str) -> str:
|
|
|
74
81
|
r"^# (.+)$", r"<h1>\1</h1>", escaped, flags=re.MULTILINE
|
|
75
82
|
)
|
|
76
83
|
|
|
77
|
-
|
|
78
|
-
escaped = re.sub(r"^- (.+)$", r"• \1", escaped, flags=re.MULTILINE)
|
|
79
|
-
|
|
84
|
+
escaped = _render_blockquotes(escaped)
|
|
80
85
|
escaped = _render_tables(escaped)
|
|
81
86
|
|
|
82
87
|
# Restore parked markup; link text may itself hold parked inline code.
|
|
83
88
|
while _SLOT_RE.search(escaped):
|
|
84
89
|
escaped = _SLOT_RE.sub(lambda m: slots[int(m.group(1))], escaped)
|
|
85
|
-
|
|
90
|
+
# A code block has its own margins, so the line breaks around it only add gaps;
|
|
91
|
+
# a paragraph break after one would otherwise render as an extra blank line.
|
|
92
|
+
return re.sub(r"\n?(<pre><code[^>]*>.*?</code></pre>)\n{0,2}", r"\1", escaped, flags=re.S)
|
|
93
|
+
|
|
94
|
+
|
|
95
|
+
def _code_block(lang: str, escaped_code: str) -> str:
|
|
96
|
+
highlighted = highlight(html.unescape(escaped_code), lang) if lang else None
|
|
97
|
+
return f'<pre><code class="language-{lang}">{highlighted or escaped_code}</code></pre>'
|
|
98
|
+
|
|
99
|
+
|
|
100
|
+
_BULLETS = ("\u2022", "\u25e6", "\u25aa")
|
|
101
|
+
|
|
102
|
+
|
|
103
|
+
def _bullet(match: re.Match) -> str:
|
|
104
|
+
"""Bullets change shape with depth: two spaces of indent per level."""
|
|
105
|
+
indent = match.group(1)
|
|
106
|
+
return indent + _BULLETS[min(len(indent) // 2, len(_BULLETS) - 1)] + " "
|
|
107
|
+
|
|
108
|
+
|
|
109
|
+
def _render_blockquotes(text: str) -> str:
|
|
110
|
+
"""Group consecutive "> " lines into one blockquote."""
|
|
111
|
+
out: list[str] = []
|
|
112
|
+
quote: list[str] = []
|
|
113
|
+
|
|
114
|
+
def flush() -> None:
|
|
115
|
+
if quote:
|
|
116
|
+
out.append("<blockquote>" + "\n".join(quote) + "</blockquote>")
|
|
117
|
+
quote.clear()
|
|
118
|
+
|
|
119
|
+
for line in text.split("\n"):
|
|
120
|
+
if line.startswith(">"):
|
|
121
|
+
quote.append(line[4:][1:] if line[4:5] == " " else line[4:])
|
|
122
|
+
else:
|
|
123
|
+
flush()
|
|
124
|
+
out.append(line)
|
|
125
|
+
flush()
|
|
126
|
+
return re.sub("(</blockquote>)\n", r"\1", "\n".join(out))
|
|
127
|
+
|
|
128
|
+
|
|
129
|
+
_CITATION_BLOCK_RE = re.compile(r"\s*<oai-mem-citation>(.*?)(?:</oai-mem-citation>|\Z)", re.S)
|
|
130
|
+
_CITATION_SECTION_RE = re.compile(r"<(citation_entries|rollout_ids)>(.*?)(?:</\w+>|\Z)", re.S)
|
|
131
|
+
|
|
132
|
+
|
|
133
|
+
def split_memory_citations(text: str) -> tuple[str, list[dict], list[str]]:
|
|
134
|
+
"""Take Codex's memory-citation blocks out of an answer.
|
|
135
|
+
|
|
136
|
+
Returns the answer without them, the cited entries as
|
|
137
|
+
{"location", "note"} dicts, and the ids of the sessions they came from.
|
|
138
|
+
"""
|
|
139
|
+
entries: list[dict] = []
|
|
140
|
+
rollouts: list[str] = []
|
|
141
|
+
for block in _CITATION_BLOCK_RE.finditer(text):
|
|
142
|
+
for section, body in _CITATION_SECTION_RE.findall(block.group(1)):
|
|
143
|
+
for line in body.splitlines():
|
|
144
|
+
line = line.strip()
|
|
145
|
+
if not line or line.startswith("<"):
|
|
146
|
+
continue
|
|
147
|
+
if section == "rollout_ids":
|
|
148
|
+
rollouts.append(line)
|
|
149
|
+
continue
|
|
150
|
+
location, _, note = line.partition("|note=")
|
|
151
|
+
entries.append({"location": location.strip(), "note": note.strip().strip("[]")})
|
|
152
|
+
if not entries and not rollouts:
|
|
153
|
+
return text, [], []
|
|
154
|
+
return _CITATION_BLOCK_RE.sub("", text).rstrip(), entries, rollouts
|
|
86
155
|
|
|
87
156
|
|
|
88
157
|
def _link(label: str, target: str) -> str:
|
|
@@ -87,10 +87,26 @@ def extract_conversation(
|
|
|
87
87
|
_handle_response_item(payload, ts, raw_events, turn_seq)
|
|
88
88
|
continue
|
|
89
89
|
|
|
90
|
+
if etype == "turn_context":
|
|
91
|
+
model = _as_text(payload.get("model"))
|
|
92
|
+
if model:
|
|
93
|
+
raw_events.append(
|
|
94
|
+
{
|
|
95
|
+
"type": "turn_settings",
|
|
96
|
+
"ts": ts,
|
|
97
|
+
"model": model,
|
|
98
|
+
"effort": _as_text(payload.get("effort") or payload.get("reasoning_effort")),
|
|
99
|
+
"_source": "turn_context",
|
|
100
|
+
"_turn_seq": turn_seq,
|
|
101
|
+
}
|
|
102
|
+
)
|
|
103
|
+
continue
|
|
104
|
+
|
|
90
105
|
raw_events = _attach_model_input_images(raw_events)
|
|
91
106
|
raw_events = _apply_exec_status(raw_events)
|
|
92
107
|
raw_events = _drop_repeated_reasoning_summaries(raw_events)
|
|
93
108
|
raw_events = _drop_unchanged_goal_updates(raw_events)
|
|
109
|
+
raw_events = _keep_turn_settings_changes(raw_events)
|
|
94
110
|
reconciled = _mark_reviews_repeated_by_reply(_reconcile_events(raw_events))
|
|
95
111
|
for event in reconciled:
|
|
96
112
|
if event.get("_turn_seq") in inherited_turns:
|
|
@@ -163,8 +179,9 @@ _HANDLED_RESPONSE_ITEM = {
|
|
|
163
179
|
"tool_search_output", "message", "reasoning", "image_generation_call",
|
|
164
180
|
}
|
|
165
181
|
_IGNORED_RESPONSE_ITEM = {"ghost_snapshot", "agent_message"}
|
|
182
|
+
_HANDLED_TOP_LEVEL = {"session_meta", "event_msg", "response_item", "turn_context"}
|
|
166
183
|
_IGNORED_TOP_LEVEL = {
|
|
167
|
-
"token_usage_record", "
|
|
184
|
+
"token_usage_record", "compacted", "world_state",
|
|
168
185
|
"inter_agent_communication_metadata", "realtime_item",
|
|
169
186
|
}
|
|
170
187
|
|
|
@@ -191,7 +208,7 @@ def unrecognized_record_kinds(entries: list[dict]) -> Counter:
|
|
|
191
208
|
elif etype == "response_item":
|
|
192
209
|
if subtype not in _HANDLED_RESPONSE_ITEM and subtype not in _IGNORED_RESPONSE_ITEM:
|
|
193
210
|
unknown[f"response_item/{subtype}"] += 1
|
|
194
|
-
elif etype not in _IGNORED_TOP_LEVEL:
|
|
211
|
+
elif etype not in _HANDLED_TOP_LEVEL and etype not in _IGNORED_TOP_LEVEL:
|
|
195
212
|
unknown[str(etype)] += 1
|
|
196
213
|
return unknown
|
|
197
214
|
|
|
@@ -361,6 +378,27 @@ def _drop_unchanged_goal_updates(events: list[dict]) -> list[dict]:
|
|
|
361
378
|
return kept
|
|
362
379
|
|
|
363
380
|
|
|
381
|
+
def _keep_turn_settings_changes(events: list[dict]) -> list[dict]:
|
|
382
|
+
"""Keep the first turn's model and effort, then only turns that change them.
|
|
383
|
+
|
|
384
|
+
Codex records both at the start of every turn; most sessions never change.
|
|
385
|
+
"""
|
|
386
|
+
kept = []
|
|
387
|
+
last: tuple[str, str] | None = None
|
|
388
|
+
for event in events:
|
|
389
|
+
if event.get("type") == "turn_settings":
|
|
390
|
+
key = (event["model"], event["effort"])
|
|
391
|
+
if key == last:
|
|
392
|
+
continue
|
|
393
|
+
if last is None:
|
|
394
|
+
event["first"] = True
|
|
395
|
+
else:
|
|
396
|
+
event["previous_model"], event["previous_effort"] = last
|
|
397
|
+
last = key
|
|
398
|
+
kept.append(event)
|
|
399
|
+
return kept
|
|
400
|
+
|
|
401
|
+
|
|
364
402
|
def _review_started_event(payload: dict, ts: str, turn_seq: int) -> dict:
|
|
365
403
|
hint = _as_text(payload.get("user_facing_hint")) or _as_text(payload.get("prompt"))
|
|
366
404
|
return {
|
|
@@ -534,6 +534,25 @@ body {
|
|
|
534
534
|
font-weight: bold;
|
|
535
535
|
}
|
|
536
536
|
|
|
537
|
+
.markdown-content .md-list-number { color: var(--mdListBullet); }
|
|
538
|
+
|
|
539
|
+
/* Syntax highlighting in fenced code */
|
|
540
|
+
.tok-keyword { color: #c792ea; }
|
|
541
|
+
.tok-string { color: var(--success); }
|
|
542
|
+
.tok-number { color: var(--mdHeading); }
|
|
543
|
+
.tok-comment { color: var(--muted); font-style: italic; }
|
|
544
|
+
.tok-added { color: var(--success); }
|
|
545
|
+
.tok-removed { color: var(--error); }
|
|
546
|
+
.tok-hunk { color: var(--mdLink); }
|
|
547
|
+
.tok-meta { color: var(--muted); font-weight: bold; }
|
|
548
|
+
|
|
549
|
+
/* Memory citations folded under an answer */
|
|
550
|
+
.memory-citations { margin-top: 8px; color: var(--muted); font-size: 11px; white-space: normal; }
|
|
551
|
+
.memory-citations summary { cursor: pointer; }
|
|
552
|
+
.memory-citations ul { margin: 4px 0 0 20px; }
|
|
553
|
+
.memory-citations .citation-location { color: var(--mdLink); }
|
|
554
|
+
.memory-citations .citation-rollouts { margin-top: 4px; }
|
|
555
|
+
|
|
537
556
|
/* Footer */
|
|
538
557
|
.footer {
|
|
539
558
|
margin-top: 48px;
|
|
@@ -2,7 +2,8 @@ from __future__ import annotations
|
|
|
2
2
|
|
|
3
3
|
import unittest
|
|
4
4
|
|
|
5
|
-
from codex_transcript_viewer.
|
|
5
|
+
from codex_transcript_viewer.highlight import highlight
|
|
6
|
+
from codex_transcript_viewer.markdown import render_markdown, split_memory_citations
|
|
6
7
|
|
|
7
8
|
|
|
8
9
|
class LinkTests(unittest.TestCase):
|
|
@@ -100,5 +101,91 @@ class ExistingFormattingTests(unittest.TestCase):
|
|
|
100
101
|
self.assertEqual(render_markdown("<script>x</script>"), "<script>x</script>")
|
|
101
102
|
|
|
102
103
|
|
|
104
|
+
class ListAndQuoteTests(unittest.TestCase):
|
|
105
|
+
def test_nested_bullets_change_shape_by_depth(self) -> None:
|
|
106
|
+
html = render_markdown("- a\n - b\n - c\n - d\n* e\n+ f")
|
|
107
|
+
self.assertEqual(html, "\u2022 a\n \u25e6 b\n \u25aa c\n \u25aa d\n\u2022 e\n\u2022 f")
|
|
108
|
+
|
|
109
|
+
def test_star_bullet_is_not_italics(self) -> None:
|
|
110
|
+
html = render_markdown("* one\n* two")
|
|
111
|
+
self.assertNotIn("<em>", html)
|
|
112
|
+
|
|
113
|
+
def test_numbered_items_get_styled_numbers(self) -> None:
|
|
114
|
+
html = render_markdown("1. first\n 2) nested")
|
|
115
|
+
self.assertEqual(
|
|
116
|
+
html,
|
|
117
|
+
'<span class="md-list-number">1.</span> first\n <span class="md-list-number">2.</span> nested',
|
|
118
|
+
)
|
|
119
|
+
|
|
120
|
+
def test_blockquote_groups_lines(self) -> None:
|
|
121
|
+
html = render_markdown("before\n> one **bold**\n>two\nafter")
|
|
122
|
+
self.assertEqual(html, "before\n<blockquote>one <strong>bold</strong>\ntwo</blockquote>after")
|
|
123
|
+
|
|
124
|
+
|
|
125
|
+
class HighlightTests(unittest.TestCase):
|
|
126
|
+
def test_python_tokens(self) -> None:
|
|
127
|
+
html = highlight('def f(): # hi\n return "x" + 1', "python")
|
|
128
|
+
self.assertIn('<span class="tok-keyword">def</span>', html)
|
|
129
|
+
self.assertIn('<span class="tok-comment"># hi</span>', html)
|
|
130
|
+
self.assertIn('<span class="tok-string">"x"</span>', html)
|
|
131
|
+
self.assertIn('<span class="tok-number">1</span>', html)
|
|
132
|
+
|
|
133
|
+
def test_strings_hide_comment_markers(self) -> None:
|
|
134
|
+
html = highlight('url = "http://x#y"', "py")
|
|
135
|
+
self.assertNotIn("tok-comment", html)
|
|
136
|
+
|
|
137
|
+
def test_shell_hash_inside_variable_is_not_a_comment(self) -> None:
|
|
138
|
+
html = highlight("echo ${#arr[@]} # count", "bash")
|
|
139
|
+
self.assertEqual(html.count("tok-comment"), 1)
|
|
140
|
+
self.assertIn("${#arr[@]}", html)
|
|
141
|
+
|
|
142
|
+
def test_diff_lines(self) -> None:
|
|
143
|
+
html = highlight("--- a\n+++ b\n@@ -1 +1 @@\n-old\n+new\n same", "diff")
|
|
144
|
+
for kind in ("meta", "hunk", "removed", "added"):
|
|
145
|
+
self.assertIn(f"tok-{kind}", html)
|
|
146
|
+
|
|
147
|
+
def test_unknown_language_is_left_alone(self) -> None:
|
|
148
|
+
self.assertIsNone(highlight("x", "brainfuck"))
|
|
149
|
+
self.assertEqual(render_markdown("```brainfuck\n<+>\n```"),
|
|
150
|
+
'<pre><code class="language-brainfuck"><+>\n</code></pre>')
|
|
151
|
+
|
|
152
|
+
def test_code_is_escaped_in_highlighted_blocks(self) -> None:
|
|
153
|
+
html = render_markdown("```js\nif (a < b) { x = '<b>' }\n```")
|
|
154
|
+
self.assertIn("<", html)
|
|
155
|
+
self.assertNotIn("<b>", html)
|
|
156
|
+
|
|
157
|
+
|
|
158
|
+
class CodeBlockSpacingTests(unittest.TestCase):
|
|
159
|
+
def test_line_breaks_around_code_blocks_are_dropped(self) -> None:
|
|
160
|
+
html = render_markdown("Before:\n\n```\nx\n```\n\nAfter")
|
|
161
|
+
self.assertEqual(html, 'Before:\n<pre><code class="language-">x\n</code></pre>After')
|
|
162
|
+
|
|
163
|
+
|
|
164
|
+
class MemoryCitationTests(unittest.TestCase):
|
|
165
|
+
BLOCK = (
|
|
166
|
+
"<oai-mem-citation>\n<citation_entries>\n"
|
|
167
|
+
"MEMORY.md:383-405|note=[slack digest source of truth]\n"
|
|
168
|
+
"extensions/x/resources/a.md:1-2|note=[other]\n"
|
|
169
|
+
"</citation_entries>\n<rollout_ids>\n019e-a\n019e-b\n</rollout_ids>\n</oai-mem-citation>"
|
|
170
|
+
)
|
|
171
|
+
|
|
172
|
+
def test_split_citations(self) -> None:
|
|
173
|
+
text, entries, rollouts = split_memory_citations("Done.\n\n" + self.BLOCK)
|
|
174
|
+
self.assertEqual(text, "Done.")
|
|
175
|
+
self.assertEqual(entries[0], {"location": "MEMORY.md:383-405", "note": "slack digest source of truth"})
|
|
176
|
+
self.assertEqual(len(entries), 2)
|
|
177
|
+
self.assertEqual(rollouts, ["019e-a", "019e-b"])
|
|
178
|
+
|
|
179
|
+
def test_unclosed_block_and_typo_close_tag(self) -> None:
|
|
180
|
+
text, entries, rollouts = split_memory_citations(
|
|
181
|
+
"Done.\n<oai-mem-citation>\n<citation_entries>\nMEMORY.md:1-2|note=[n]\n"
|
|
182
|
+
"</citation_entries>\n<rollout_ids>\nr1\n</rollup_ids>"
|
|
183
|
+
)
|
|
184
|
+
self.assertEqual((text, len(entries), rollouts), ("Done.", 1, ["r1"]))
|
|
185
|
+
|
|
186
|
+
def test_text_without_citations_is_unchanged(self) -> None:
|
|
187
|
+
self.assertEqual(split_memory_citations("plain\n"), ("plain\n", [], []))
|
|
188
|
+
|
|
189
|
+
|
|
103
190
|
if __name__ == "__main__":
|
|
104
191
|
unittest.main()
|
|
@@ -33,5 +33,19 @@ class OutputCapTests(unittest.TestCase):
|
|
|
33
33
|
self.assertIn("[50,000 characters omitted]", _html("z" * 300_000))
|
|
34
34
|
|
|
35
35
|
|
|
36
|
+
class OutputShownOnceTests(unittest.TestCase):
|
|
37
|
+
def test_short_output_is_rendered_once(self) -> None:
|
|
38
|
+
html = _html("12 passed in 0.34s")
|
|
39
|
+
self.assertEqual(html.count("12 passed in 0.34s"), 1)
|
|
40
|
+
self.assertNotIn('class="output-preview"', html)
|
|
41
|
+
|
|
42
|
+
def test_long_output_has_preview_and_full_copy(self) -> None:
|
|
43
|
+
html = _html("line\n" * 1000)
|
|
44
|
+
self.assertIn('class="tool-output expandable"', html)
|
|
45
|
+
self.assertIn("output-preview", html)
|
|
46
|
+
self.assertIn("output-full", html)
|
|
47
|
+
self.assertIn("[click to expand 5000 chars]", html)
|
|
48
|
+
|
|
49
|
+
|
|
36
50
|
if __name__ == "__main__":
|
|
37
51
|
unittest.main()
|
{codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_session_events.py
RENAMED
|
@@ -219,6 +219,53 @@ class ImageGenerationTests(unittest.TestCase):
|
|
|
219
219
|
self.assertIs(output["failed"], True)
|
|
220
220
|
|
|
221
221
|
|
|
222
|
+
class TurnSettingsTests(unittest.TestCase):
|
|
223
|
+
def _context(self, model: str, effort: str) -> dict:
|
|
224
|
+
return {"type": "turn_context", "timestamp": "2026-09-27T01:00:00Z",
|
|
225
|
+
"payload": {"model": model, "effort": effort, "cwd": "/x"}}
|
|
226
|
+
|
|
227
|
+
def test_only_changes_are_kept_and_header_shows_first_model(self) -> None:
|
|
228
|
+
entries = [
|
|
229
|
+
_turn(), self._context("gpt-5.6-sol", "high"),
|
|
230
|
+
_turn(), self._context("gpt-5.6-sol", "high"),
|
|
231
|
+
_turn(), self._context("gpt-6-astra", "high"),
|
|
232
|
+
_turn(), self._context("gpt-6-astra", "xhigh"),
|
|
233
|
+
]
|
|
234
|
+
settings = [e for e in _events(*entries) if e["type"] == "turn_settings"]
|
|
235
|
+
self.assertEqual([(s["model"], s["effort"]) for s in settings],
|
|
236
|
+
[("gpt-5.6-sol", "high"), ("gpt-6-astra", "high"), ("gpt-6-astra", "xhigh")])
|
|
237
|
+
html = _html(*entries)
|
|
238
|
+
self.assertIn('<span class="info-value">gpt-5.6-sol (high effort)</span>', html)
|
|
239
|
+
self.assertIn("Switched model gpt-5.6-sol \u2192 gpt-6-astra", html)
|
|
240
|
+
self.assertIn("Switched effort high \u2192 xhigh", html)
|
|
241
|
+
self.assertIn('data-kind="settings"', html)
|
|
242
|
+
|
|
243
|
+
def test_header_falls_back_to_provider(self) -> None:
|
|
244
|
+
meta, events = extract_conversation(
|
|
245
|
+
[{"type": "session_meta", "payload": {"id": "s", "model_provider": "openai"}}, _turn()]
|
|
246
|
+
)
|
|
247
|
+
self.assertIn('<span class="info-value">openai</span>', build_html(meta, events))
|
|
248
|
+
|
|
249
|
+
|
|
250
|
+
class MemoryCitationRenderTests(unittest.TestCase):
|
|
251
|
+
def test_citations_fold_under_the_answer(self) -> None:
|
|
252
|
+
answer = ("All set.\n\n<oai-mem-citation>\n<citation_entries>\nMEMORY.md:1-2|note=[why]\n"
|
|
253
|
+
"</citation_entries>\n<rollout_ids>\nr1\n</rollout_ids>\n</oai-mem-citation>")
|
|
254
|
+
html = _html(_turn(), _response_item({"type": "message", "role": "assistant", "phase": "final_answer",
|
|
255
|
+
"content": [{"type": "output_text", "text": answer}]}))
|
|
256
|
+
self.assertNotIn("oai-mem-citation", html)
|
|
257
|
+
self.assertIn("Memory citations: 1 memory entry from 1 earlier session", html)
|
|
258
|
+
self.assertIn('<span class="citation-location">MEMORY.md:1-2</span> \u2014 why', html)
|
|
259
|
+
|
|
260
|
+
|
|
261
|
+
class ReasoningMarkdownTests(unittest.TestCase):
|
|
262
|
+
def test_reasoning_renders_markdown(self) -> None:
|
|
263
|
+
html = _html(_turn(), _reasoning("**Planning the CSV writer**\n\nUse `csv.writer`."))
|
|
264
|
+
self.assertIn("<strong>Planning the CSV writer</strong>", html)
|
|
265
|
+
self.assertIn("<code>csv.writer</code>", html)
|
|
266
|
+
self.assertIn("\U0001f4ad Planning the CSV writer", html)
|
|
267
|
+
|
|
268
|
+
|
|
222
269
|
class RecordKindTests(unittest.TestCase):
|
|
223
270
|
def test_new_kinds_are_handled_or_ignored(self) -> None:
|
|
224
271
|
entries = [
|
|
@@ -230,6 +277,7 @@ class RecordKindTests(unittest.TestCase):
|
|
|
230
277
|
_item({"type": kind}) for kind in ("EnteredReviewMode", "ExitedReviewMode", "HookPrompt")
|
|
231
278
|
] + [
|
|
232
279
|
{"type": "realtime_item", "payload": {"type": "realtime_session_started"}},
|
|
280
|
+
{"type": "turn_context", "payload": {"model": "m"}},
|
|
233
281
|
_response_item({"type": "image_generation_call"}),
|
|
234
282
|
]
|
|
235
283
|
self.assertEqual(unrecognized_record_kinds(entries), Counter())
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/src/codex_transcript_viewer/cli.py
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
{codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_audit_sessions.py
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_inherited_history.py
RENAMED
|
File without changes
|
{codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_null_payload_fields.py
RENAMED
|
File without changes
|
{codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_parser_dedup_density.py
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
{codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_tool_output_shapes.py
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|
{codex_transcript_viewer-0.4.0 → codex_transcript_viewer-0.5.0}/tests/test_unrecognized_records.py
RENAMED
|
File without changes
|
|
File without changes
|
|
File without changes
|