cholops 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- cholops-0.1.0/CHANGELOG.md +5 -0
- cholops-0.1.0/CONTRIBUTING.md +67 -0
- cholops-0.1.0/LICENSE +21 -0
- cholops-0.1.0/PKG-INFO +149 -0
- cholops-0.1.0/README.md +129 -0
- cholops-0.1.0/ROADMAP.md +18 -0
- cholops-0.1.0/TESTING.md +60 -0
- cholops-0.1.0/benchmarks/README.md +224 -0
- cholops-0.1.0/benchmarks/__init__.py +1 -0
- cholops-0.1.0/benchmarks/_environment.py +91 -0
- cholops-0.1.0/benchmarks/_naive.py +43 -0
- cholops-0.1.0/benchmarks/_recompute.py +19 -0
- cholops-0.1.0/benchmarks/_support.py +93 -0
- cholops-0.1.0/benchmarks/plot.py +369 -0
- cholops-0.1.0/benchmarks/run.py +326 -0
- cholops-0.1.0/benchmarks/suite.py +149 -0
- cholops-0.1.0/benchmarks/workloads.py +330 -0
- cholops-0.1.0/docs/adjoints.md +144 -0
- cholops-0.1.0/docs/assets/cholops-logo.svg +13 -0
- cholops-0.1.0/docs/factors.md +201 -0
- cholops-0.1.0/docs/numerics.md +127 -0
- cholops-0.1.0/docs/tensors.md +72 -0
- cholops-0.1.0/examples/basic_factor.py +94 -0
- cholops-0.1.0/examples/online_least_squares.py +76 -0
- cholops-0.1.0/examples/streaming_gp.py +127 -0
- cholops-0.1.0/examples/tensor_operations.py +85 -0
- cholops-0.1.0/pyproject.toml +85 -0
- cholops-0.1.0/pyproject.toml.orig +65 -0
- cholops-0.1.0/src/cholops/__init__.py +28 -0
- cholops-0.1.0/src/cholops/factors/__init__.py +6 -0
- cholops-0.1.0/src/cholops/factors/_consumers.py +28 -0
- cholops-0.1.0/src/cholops/factors/cholesky.py +133 -0
- cholops-0.1.0/src/cholops/factors/permuted.py +182 -0
- cholops-0.1.0/src/cholops/py.typed +0 -0
- cholops-0.1.0/src/cholops/tensors/__init__.py +25 -0
- cholops-0.1.0/src/cholops/tensors/_autodiff.py +78 -0
- cholops-0.1.0/src/cholops/tensors/_indexing.py +51 -0
- cholops-0.1.0/src/cholops/tensors/_validation.py +55 -0
- cholops-0.1.0/src/cholops/tensors/append.py +30 -0
- cholops-0.1.0/src/cholops/tensors/deletion.py +110 -0
- cholops-0.1.0/src/cholops/tensors/factorization.py +57 -0
- cholops-0.1.0/src/cholops/tensors/rank_one.py +199 -0
- cholops-0.1.0/src/cholops/tensors/replacement.py +212 -0
- cholops-0.1.0/tests/__init__.py +0 -0
- cholops-0.1.0/tests/conftest.py +44 -0
- cholops-0.1.0/tests/reference/__init__.py +0 -0
- cholops-0.1.0/tests/reference/decimal_ad.py +180 -0
- cholops-0.1.0/tests/reference/decimal_gp.py +71 -0
- cholops-0.1.0/tests/reference/gp_sequences.py +142 -0
- cholops-0.1.0/tests/reference/gradient_sequences.py +65 -0
- cholops-0.1.0/tests/test_benchmarks.py +206 -0
- cholops-0.1.0/tests/test_block.py +79 -0
- cholops-0.1.0/tests/test_cholesky.py +256 -0
- cholops-0.1.0/tests/test_forward_ad.py +295 -0
- cholops-0.1.0/tests/test_gp_decimal_reference.py +94 -0
- cholops-0.1.0/tests/test_gp_stability.py +69 -0
- cholops-0.1.0/tests/test_operations.py +381 -0
- cholops-0.1.0/tests/test_permuted.py +339 -0
- cholops-0.1.0/tests/test_release_numerics.py +116 -0
- cholops-0.1.0/tests/test_replace.py +234 -0
- cholops-0.1.0/tests/test_sequences.py +113 -0
- cholops-0.1.0/tests/test_symmetric_cholesky.py +111 -0
- cholops-0.1.0/tests/test_updates.py +182 -0
- cholops-0.1.0/tests/wheel_smoke.py +55 -0
- cholops-0.1.0/uv.lock +1021 -0
|
@@ -0,0 +1,67 @@
|
|
|
1
|
+
# Contributing
|
|
2
|
+
|
|
3
|
+
## Setup and checks
|
|
4
|
+
|
|
5
|
+
Use Python 3.12 or newer and the locked environment:
|
|
6
|
+
|
|
7
|
+
```sh
|
|
8
|
+
uv sync --locked --all-groups
|
|
9
|
+
uv lock --check
|
|
10
|
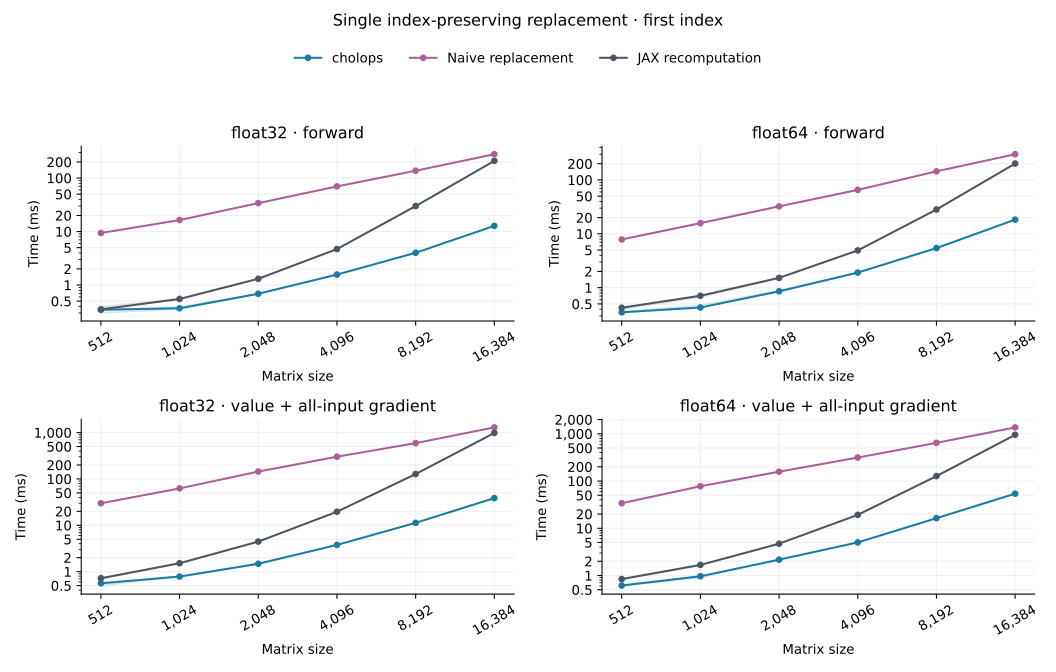
+
uv run --locked ruff check .
|
|
11
|
+
uv run --locked ruff format --check .
|
|
12
|
+
JAX_PLATFORMS=cpu JAX_ENABLE_X64=0 uv run --locked python -m pytest
|
|
13
|
+
JAX_PLATFORMS=cpu JAX_ENABLE_X64=1 uv run --locked python -m pytest
|
|
14
|
+
```
|
|
15
|
+
|
|
16
|
+
Run each precision in a separate process, selecting x64 before collection.
|
|
17
|
+
Examples inherit that setting:
|
|
18
|
+
|
|
19
|
+
```sh
|
|
20
|
+
JAX_ENABLE_X64=1 uv run --locked python examples/basic_factor.py
|
|
21
|
+
JAX_ENABLE_X64=1 uv run --locked python examples/streaming_gp.py
|
|
22
|
+
JAX_ENABLE_X64=1 uv run --locked python examples/online_least_squares.py
|
|
23
|
+
JAX_ENABLE_X64=1 uv run --locked python examples/tensor_operations.py
|
|
24
|
+
```
|
|
25
|
+
|
|
26
|
+
The default suite is the small CI layer. Keep each case within a few seconds,
|
|
27
|
+
including compilation. Small numerical and gradient regressions belong here.
|
|
28
|
+
The manual release suite adds larger matrices, long sequences, high-precision
|
|
29
|
+
references and benchmark comparisons:
|
|
30
|
+
|
|
31
|
+
```sh
|
|
32
|
+
JAX_PLATFORMS=cpu JAX_ENABLE_X64=0 uv run --locked python -m pytest --full
|
|
33
|
+
JAX_PLATFORMS=cpu JAX_ENABLE_X64=1 uv run --locked python -m pytest --full
|
|
34
|
+
JAX_PLATFORMS=cuda JAX_ENABLE_X64=0 uv run --locked python -m pytest --full --require-gpu
|
|
35
|
+
JAX_PLATFORMS=cuda JAX_ENABLE_X64=1 uv run --locked python -m pytest --full --require-gpu
|
|
36
|
+
```
|
|
37
|
+
|
|
38
|
+
CUDA requires the configured GPU environment (`uv sync --locked --all-groups
|
|
39
|
+
--extra cuda13` on supported Linux hosts). CPU full runs explicitly skip the
|
|
40
|
+
GPU-only storage check. `--require-gpu` prevents accidental CPU validation.
|
|
41
|
+
Use `--full -m full` to run only additional release tests. See
|
|
42
|
+
[testing guide](TESTING.md) and the [benchmark guide](benchmarks/README.md).
|
|
43
|
+
|
|
44
|
+
## Design
|
|
45
|
+
|
|
46
|
+
The public API is exported from `cholops` and grouped into `cholops.factors`
|
|
47
|
+
and `cholops.tensors`. Leading-underscore modules are private.
|
|
48
|
+
|
|
49
|
+
`factors/` contains the two factor classes and their shared matrix calculations.
|
|
50
|
+
The classes own factor storage and, for `PermutedCholesky`, permutation state.
|
|
51
|
+
`tensors/` contains factorization, append, rank-one updates, deletion and
|
|
52
|
+
replacement. Each algorithm stays with its derivative rules. Private modules
|
|
53
|
+
provide shared validation, indexing and JAX differentiation support.
|
|
54
|
+
|
|
55
|
+
Dependencies run from factor objects to tensor operations. Tensor code does not
|
|
56
|
+
import the factor classes. Reuse the tensor implementations rather than
|
|
57
|
+
duplicating them in containers.
|
|
58
|
+
|
|
59
|
+
State is immutable. No hidden precision changes, jitter, clipping, retry,
|
|
60
|
+
occupancy tracking, memory pool or buffer donation. Test meaningful numerical
|
|
61
|
+
behavior against independent dense or high-precision references. A small factor
|
|
62
|
+
residual alone does not establish accurate gradients. Preserve signed
|
|
63
|
+
zero-weight derivatives and visible numerical failures.
|
|
64
|
+
|
|
65
|
+
Keep supported transformations and shape/order explicit in docstrings
|
|
66
|
+
and the [API guides](docs/tensors.md). Any new numerical algorithm needs both
|
|
67
|
+
correctness evidence and representative measurements before performance claims.
|
cholops-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Alexander von Rohr
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
cholops-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,149 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: cholops
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Fast and differentiable Cholesky factor modifications in JAX.
|
|
5
|
+
Keywords: jax,cholesky,linear-algebra,automatic-differentiation
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
License-File: LICENSE
|
|
8
|
+
Classifier: Development Status :: 3 - Alpha
|
|
9
|
+
Classifier: Intended Audience :: Science/Research
|
|
10
|
+
Classifier: Programming Language :: Python :: 3
|
|
11
|
+
Classifier: Topic :: Scientific/Engineering :: Mathematics
|
|
12
|
+
Requires-Dist: jax==0.11.2
|
|
13
|
+
Requires-Dist: jax[cuda13]==0.11.2 ; sys_platform == 'linux' and extra == 'cuda13'
|
|
14
|
+
Requires-Python: >=3.12
|
|
15
|
+
Project-URL: Repository, https://github.com/avrohr/cholops
|
|
16
|
+
Project-URL: Documentation, https://github.com/avrohr/cholops/tree/main/docs
|
|
17
|
+
Project-URL: Issues, https://github.com/avrohr/cholops/issues
|
|
18
|
+
Provides-Extra: cuda13
|
|
19
|
+
Description-Content-Type: text/markdown
|
|
20
|
+
|
|
21
|
+
<p align="center">
|
|
22
|
+
<img src="https://raw.githubusercontent.com/avrohr/cholops/main/docs/assets/cholops-logo.svg" alt="cholops logo: an eye with three diagonal squares" width="240">
|
|
23
|
+
</p>
|
|
24
|
+
|
|
25
|
+
# cholops
|
|
26
|
+
|
|
27
|
+
Cholesky modifications in JAX, with differentiable tensor operations and
|
|
28
|
+
immutable factor objects. cholops provides fast appends, deletions and updates
|
|
29
|
+
of a dense positive-definite matrix's factor, directly or through a factor
|
|
30
|
+
object.
|
|
31
|
+
|
|
32
|
+
## Install
|
|
33
|
+
|
|
34
|
+
Install with `pip install cholops`. On Linux with a compatible CUDA 13 driver,
|
|
35
|
+
use `pip install "cholops[cuda13]"`. The initial release targets **JAX 0.11.2** and
|
|
36
|
+
Python 3.12 or newer.
|
|
37
|
+
|
|
38
|
+
We recommend using float64; see [JAX's precision settings](https://docs.jax.dev/en/latest/101/default_dtypes.html).
|
|
39
|
+
|
|
40
|
+
Set the `JAX_ENABLE_X64` shell environment variable before starting Python:
|
|
41
|
+
|
|
42
|
+
```bash
|
|
43
|
+
export JAX_ENABLE_X64=1
|
|
44
|
+
```
|
|
45
|
+
|
|
46
|
+
Alternatively, enable it in Python before creating arrays:
|
|
47
|
+
|
|
48
|
+
```python
|
|
49
|
+
import jax
|
|
50
|
+
|
|
51
|
+
jax.config.update("jax_enable_x64", True)
|
|
52
|
+
```
|
|
53
|
+
|
|
54
|
+
## Example
|
|
55
|
+
|
|
56
|
+
```python
|
|
57
|
+
import jax
|
|
58
|
+
import jax.numpy as jnp
|
|
59
|
+
from cholops import Cholesky, PermutedCholesky
|
|
60
|
+
|
|
61
|
+
A = jnp.array([[2.0, 0.3, 0.1], [0.3, 1.5, 0.2], [0.1, 0.2, 1.2]])
|
|
62
|
+
b = jnp.array([1.0, -0.5, 0.2])
|
|
63
|
+
|
|
64
|
+
# Create a Cholesky factor from a positive-definite matrix.
|
|
65
|
+
factor = Cholesky.from_matrix(A)
|
|
66
|
+
factor = factor.append(jnp.array([0.2, 0.1, 0.05]), 1.3)
|
|
67
|
+
L = factor.factor
|
|
68
|
+
x = factor.solve(
|
|
69
|
+
jnp.append(b, 0.4)
|
|
70
|
+
) # One RHS entry per variable, including the new one.
|
|
71
|
+
|
|
72
|
+
# PermutedCholesky replaces by deletion and appending,
|
|
73
|
+
# while managing logical ordering transparently.
|
|
74
|
+
managed = PermutedCholesky.from_matrix(A)
|
|
75
|
+
updated = managed.replace(1, jnp.array([0.2, 0.1]), 1.3)
|
|
76
|
+
x_new = updated.solve(b) # Inputs and outputs remain in logical order.
|
|
77
|
+
|
|
78
|
+
|
|
79
|
+
# Zero-mean Gaussian log likelihood and its covariance/data gradients.
|
|
80
|
+
@jax.jit
|
|
81
|
+
def log_likelihood(A, b):
|
|
82
|
+
state = Cholesky.from_matrix(A)
|
|
83
|
+
return -0.5 * (state.logdet() + state.quadratic(b) + b.size * jnp.log(2 * jnp.pi))
|
|
84
|
+
|
|
85
|
+
|
|
86
|
+
logp, (grad_A, grad_b) = jax.value_and_grad(log_likelihood, argnums=(0, 1))(A, b)
|
|
87
|
+
```
|
|
88
|
+
|
|
89
|
+
See the [factor guide](https://github.com/avrohr/cholops/blob/main/docs/factors.md) for more information. The executable
|
|
90
|
+
examples explain each step and check their results against dense calculations:
|
|
91
|
+
|
|
92
|
+
- [Basic factor operations](https://github.com/avrohr/cholops/blob/main/examples/basic_factor.py): add, replace and remove
|
|
93
|
+
observations, then solve a system and calculate a Gaussian log likelihood.
|
|
94
|
+
- [Streaming Gaussian process](https://github.com/avrohr/cholops/blob/main/examples/streaming_gp.py): maintain a fixed-size
|
|
95
|
+
observation window with `PermutedCholesky` and differentiate through the
|
|
96
|
+
replacement sequence with respect to a kernel parameter.
|
|
97
|
+
- [Online least squares](https://github.com/avrohr/cholops/blob/main/examples/online_least_squares.py): update a regression
|
|
98
|
+
fit with `rank1_positive` as measurements arrive.
|
|
99
|
+
- [Direct tensor operations](https://github.com/avrohr/cholops/blob/main/examples/tensor_operations.py): compare replacement
|
|
100
|
+
orderings and arrange the right-hand side for each returned factor.
|
|
101
|
+
|
|
102
|
+
## Tensor operations
|
|
103
|
+
|
|
104
|
+
The factor objects use the following tensor operations, which can also be
|
|
105
|
+
imported directly from `cholops`:
|
|
106
|
+
|
|
107
|
+
| Operation | Description |
|
|
108
|
+
| --- | --- |
|
|
109
|
+
| `cholesky` | Factor a positive-definite matrix. |
|
|
110
|
+
| `chol_append` | Append one covariance row and column. |
|
|
111
|
+
| `chol_delete` | Delete one covariance row and column, preserving survivor order. |
|
|
112
|
+
| `chol_replace` | Replace one covariance row and column at the same index. |
|
|
113
|
+
| `chol_delete_append` | Delete one variable and append its replacement last. |
|
|
114
|
+
| `chol_replace_last` | Replace a trailing block of variables. |
|
|
115
|
+
| `chol_diag_update` | Add a signed value to one covariance diagonal entry. |
|
|
116
|
+
| `chol_rank1` | Apply a rank-one update with a signed weight. |
|
|
117
|
+
| `chol_rank1_positive` | Apply a positive rank-one update using the optimized path. |
|
|
118
|
+
|
|
119
|
+
See the [tensor guide](https://github.com/avrohr/cholops/blob/main/docs/tensors.md) for shapes, ordering and preconditions.
|
|
120
|
+
All operations support `jit`, `vmap` and first-order forward and reverse
|
|
121
|
+
differentiation. Higher-order derivatives have not been validated for general use.
|
|
122
|
+
|
|
123
|
+
## Performance
|
|
124
|
+
|
|
125
|
+
We benchmark a single index-preserving `chol_replace` call against a naive JAX
|
|
126
|
+
implementation and full matrix refactorization on an NVIDIA H100. All methods
|
|
127
|
+
receive the existing factor and replacement covariances.
|
|
128
|
+
|
|
129
|
+
|
|
130
|
+
|
|
131
|
+
Replacing the first index of a **16,384 × 16,384** matrix gives the following
|
|
132
|
+
speedups after compilation:
|
|
133
|
+
|
|
134
|
+
| Precision | Forward: vs recompute / naive replacement | Value + gradient: vs recompute / naive replacement |
|
|
135
|
+
| --- | ---: | ---: |
|
|
136
|
+
| float32 | 15.7× / 21.3× | 22.7× / 30.3× |
|
|
137
|
+
| float64 | 10.2× / 16.1× | 15.6× / 22.9× |
|
|
138
|
+
|
|
139
|
+
[Recomputation](https://github.com/avrohr/cholops/blob/main/benchmarks/_recompute.py) forms `L @ L.T`, changes its row/column
|
|
140
|
+
and calls native JAX Cholesky. The [naive replacement](https://github.com/avrohr/cholops/blob/main/benchmarks/_naive.py)
|
|
141
|
+
baseline uses two signed rank-one scans with standard JAX autodiff.
|
|
142
|
+
|
|
143
|
+
See [the complete benchmark results](https://github.com/avrohr/cholops/blob/main/benchmarks/README.md) for
|
|
144
|
+
the measurement protocol, additional timings and memory usage.
|
|
145
|
+
|
|
146
|
+
## Numerical limitations
|
|
147
|
+
|
|
148
|
+
Near-singular covariances can produce inaccurate factors and gradients.
|
|
149
|
+
See [numerical limits](https://github.com/avrohr/cholops/blob/main/docs/numerics.md).
|
cholops-0.1.0/README.md
ADDED
|
@@ -0,0 +1,129 @@
|
|
|
1
|
+
<p align="center">
|
|
2
|
+
<img src="https://raw.githubusercontent.com/avrohr/cholops/main/docs/assets/cholops-logo.svg" alt="cholops logo: an eye with three diagonal squares" width="240">
|
|
3
|
+
</p>
|
|
4
|
+
|
|
5
|
+
# cholops
|
|
6
|
+
|
|
7
|
+
Cholesky modifications in JAX, with differentiable tensor operations and
|
|
8
|
+
immutable factor objects. cholops provides fast appends, deletions and updates
|
|
9
|
+
of a dense positive-definite matrix's factor, directly or through a factor
|
|
10
|
+
object.
|
|
11
|
+
|
|
12
|
+
## Install
|
|
13
|
+
|
|
14
|
+
Install with `pip install cholops`. On Linux with a compatible CUDA 13 driver,
|
|
15
|
+
use `pip install "cholops[cuda13]"`. The initial release targets **JAX 0.11.2** and
|
|
16
|
+
Python 3.12 or newer.
|
|
17
|
+
|
|
18
|
+
We recommend using float64; see [JAX's precision settings](https://docs.jax.dev/en/latest/101/default_dtypes.html).
|
|
19
|
+
|
|
20
|
+
Set the `JAX_ENABLE_X64` shell environment variable before starting Python:
|
|
21
|
+
|
|
22
|
+
```bash
|
|
23
|
+
export JAX_ENABLE_X64=1
|
|
24
|
+
```
|
|
25
|
+
|
|
26
|
+
Alternatively, enable it in Python before creating arrays:
|
|
27
|
+
|
|
28
|
+
```python
|
|
29
|
+
import jax
|
|
30
|
+
|
|
31
|
+
jax.config.update("jax_enable_x64", True)
|
|
32
|
+
```
|
|
33
|
+
|
|
34
|
+
## Example
|
|
35
|
+
|
|
36
|
+
```python
|
|
37
|
+
import jax
|
|
38
|
+
import jax.numpy as jnp
|
|
39
|
+
from cholops import Cholesky, PermutedCholesky
|
|
40
|
+
|
|
41
|
+
A = jnp.array([[2.0, 0.3, 0.1], [0.3, 1.5, 0.2], [0.1, 0.2, 1.2]])
|
|
42
|
+
b = jnp.array([1.0, -0.5, 0.2])
|
|
43
|
+
|
|
44
|
+
# Create a Cholesky factor from a positive-definite matrix.
|
|
45
|
+
factor = Cholesky.from_matrix(A)
|
|
46
|
+
factor = factor.append(jnp.array([0.2, 0.1, 0.05]), 1.3)
|
|
47
|
+
L = factor.factor
|
|
48
|
+
x = factor.solve(
|
|
49
|
+
jnp.append(b, 0.4)
|
|
50
|
+
) # One RHS entry per variable, including the new one.
|
|
51
|
+
|
|
52
|
+
# PermutedCholesky replaces by deletion and appending,
|
|
53
|
+
# while managing logical ordering transparently.
|
|
54
|
+
managed = PermutedCholesky.from_matrix(A)
|
|
55
|
+
updated = managed.replace(1, jnp.array([0.2, 0.1]), 1.3)
|
|
56
|
+
x_new = updated.solve(b) # Inputs and outputs remain in logical order.
|
|
57
|
+
|
|
58
|
+
|
|
59
|
+
# Zero-mean Gaussian log likelihood and its covariance/data gradients.
|
|
60
|
+
@jax.jit
|
|
61
|
+
def log_likelihood(A, b):
|
|
62
|
+
state = Cholesky.from_matrix(A)
|
|
63
|
+
return -0.5 * (state.logdet() + state.quadratic(b) + b.size * jnp.log(2 * jnp.pi))
|
|
64
|
+
|
|
65
|
+
|
|
66
|
+
logp, (grad_A, grad_b) = jax.value_and_grad(log_likelihood, argnums=(0, 1))(A, b)
|
|
67
|
+
```
|
|
68
|
+
|
|
69
|
+
See the [factor guide](https://github.com/avrohr/cholops/blob/main/docs/factors.md) for more information. The executable
|
|
70
|
+
examples explain each step and check their results against dense calculations:
|
|
71
|
+
|
|
72
|
+
- [Basic factor operations](https://github.com/avrohr/cholops/blob/main/examples/basic_factor.py): add, replace and remove
|
|
73
|
+
observations, then solve a system and calculate a Gaussian log likelihood.
|
|
74
|
+
- [Streaming Gaussian process](https://github.com/avrohr/cholops/blob/main/examples/streaming_gp.py): maintain a fixed-size
|
|
75
|
+
observation window with `PermutedCholesky` and differentiate through the
|
|
76
|
+
replacement sequence with respect to a kernel parameter.
|
|
77
|
+
- [Online least squares](https://github.com/avrohr/cholops/blob/main/examples/online_least_squares.py): update a regression
|
|
78
|
+
fit with `rank1_positive` as measurements arrive.
|
|
79
|
+
- [Direct tensor operations](https://github.com/avrohr/cholops/blob/main/examples/tensor_operations.py): compare replacement
|
|
80
|
+
orderings and arrange the right-hand side for each returned factor.
|
|
81
|
+
|
|
82
|
+
## Tensor operations
|
|
83
|
+
|
|
84
|
+
The factor objects use the following tensor operations, which can also be
|
|
85
|
+
imported directly from `cholops`:
|
|
86
|
+
|
|
87
|
+
| Operation | Description |
|
|
88
|
+
| --- | --- |
|
|
89
|
+
| `cholesky` | Factor a positive-definite matrix. |
|
|
90
|
+
| `chol_append` | Append one covariance row and column. |
|
|
91
|
+
| `chol_delete` | Delete one covariance row and column, preserving survivor order. |
|
|
92
|
+
| `chol_replace` | Replace one covariance row and column at the same index. |
|
|
93
|
+
| `chol_delete_append` | Delete one variable and append its replacement last. |
|
|
94
|
+
| `chol_replace_last` | Replace a trailing block of variables. |
|
|
95
|
+
| `chol_diag_update` | Add a signed value to one covariance diagonal entry. |
|
|
96
|
+
| `chol_rank1` | Apply a rank-one update with a signed weight. |
|
|
97
|
+
| `chol_rank1_positive` | Apply a positive rank-one update using the optimized path. |
|
|
98
|
+
|
|
99
|
+
See the [tensor guide](https://github.com/avrohr/cholops/blob/main/docs/tensors.md) for shapes, ordering and preconditions.
|
|
100
|
+
All operations support `jit`, `vmap` and first-order forward and reverse
|
|
101
|
+
differentiation. Higher-order derivatives have not been validated for general use.
|
|
102
|
+
|
|
103
|
+
## Performance
|
|
104
|
+
|
|
105
|
+
We benchmark a single index-preserving `chol_replace` call against a naive JAX
|
|
106
|
+
implementation and full matrix refactorization on an NVIDIA H100. All methods
|
|
107
|
+
receive the existing factor and replacement covariances.
|
|
108
|
+
|
|
109
|
+

|
|
110
|
+
|
|
111
|
+
Replacing the first index of a **16,384 × 16,384** matrix gives the following
|
|
112
|
+
speedups after compilation:
|
|
113
|
+
|
|
114
|
+
| Precision | Forward: vs recompute / naive replacement | Value + gradient: vs recompute / naive replacement |
|
|
115
|
+
| --- | ---: | ---: |
|
|
116
|
+
| float32 | 15.7× / 21.3× | 22.7× / 30.3× |
|
|
117
|
+
| float64 | 10.2× / 16.1× | 15.6× / 22.9× |
|
|
118
|
+
|
|
119
|
+
[Recomputation](https://github.com/avrohr/cholops/blob/main/benchmarks/_recompute.py) forms `L @ L.T`, changes its row/column
|
|
120
|
+
and calls native JAX Cholesky. The [naive replacement](https://github.com/avrohr/cholops/blob/main/benchmarks/_naive.py)
|
|
121
|
+
baseline uses two signed rank-one scans with standard JAX autodiff.
|
|
122
|
+
|
|
123
|
+
See [the complete benchmark results](https://github.com/avrohr/cholops/blob/main/benchmarks/README.md) for
|
|
124
|
+
the measurement protocol, additional timings and memory usage.
|
|
125
|
+
|
|
126
|
+
## Numerical limitations
|
|
127
|
+
|
|
128
|
+
Near-singular covariances can produce inaccurate factors and gradients.
|
|
129
|
+
See [numerical limits](https://github.com/avrohr/cholops/blob/main/docs/numerics.md).
|
cholops-0.1.0/ROADMAP.md
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
1
|
+
# Roadmap
|
|
2
|
+
|
|
3
|
+
## Initial release
|
|
4
|
+
|
|
5
|
+
- [ ] Finish the API and documentation review.
|
|
6
|
+
- [ ] Complete CPU/GPU tests and package checks, then publish the first release.
|
|
7
|
+
|
|
8
|
+
## Differentiation
|
|
9
|
+
|
|
10
|
+
- [ ] Add tested support for Hessian-vector products.
|
|
11
|
+
- [ ] Extend to other second-order derivatives while preserving first-order
|
|
12
|
+
accuracy and performance.
|
|
13
|
+
|
|
14
|
+
## Possible extensions
|
|
15
|
+
|
|
16
|
+
- [ ] Block append and deletion.
|
|
17
|
+
- [ ] Rank-k updates.
|
|
18
|
+
- [ ] Faster signed updates and downdates.
|
cholops-0.1.0/TESTING.md
ADDED
|
@@ -0,0 +1,60 @@
|
|
|
1
|
+
# Testing
|
|
2
|
+
|
|
3
|
+
The tests check factors, solves and derivatives against dense recomputation and
|
|
4
|
+
independent high-precision references. This guide describes the test groups and
|
|
5
|
+
how to run them. See [contributing](CONTRIBUTING.md) for environment setup.
|
|
6
|
+
|
|
7
|
+
## Running tests
|
|
8
|
+
|
|
9
|
+
Run float32 and float64 in separate processes:
|
|
10
|
+
|
|
11
|
+
```sh
|
|
12
|
+
JAX_PLATFORMS=cpu JAX_ENABLE_X64=0 uv run --locked python -m pytest
|
|
13
|
+
JAX_PLATFORMS=cpu JAX_ENABLE_X64=1 uv run --locked python -m pytest
|
|
14
|
+
```
|
|
15
|
+
|
|
16
|
+
The default suite runs in CI on Python 3.12 and 3.13. Additional tests are marked
|
|
17
|
+
`full` and run before releases:
|
|
18
|
+
|
|
19
|
+
| Option | What runs |
|
|
20
|
+
| --- | --- |
|
|
21
|
+
| No option | Small functional, numerical and derivative tests. |
|
|
22
|
+
| `--full` | Default tests plus larger matrices, longer sequences and benchmark checks. |
|
|
23
|
+
| `--full -m full` | Only the additional tests. |
|
|
24
|
+
| `--full --require-gpu` | Full suite, failing immediately if no GPU is active. |
|
|
25
|
+
|
|
26
|
+
For CUDA, install the `cuda13` extra and set `JAX_PLATFORMS=cuda`. Run both
|
|
27
|
+
precisions as on CPU. GPU storage checks are skipped on CPU; inspect the test
|
|
28
|
+
summary for failures and skips.
|
|
29
|
+
|
|
30
|
+
## What is checked
|
|
31
|
+
|
|
32
|
+
- **Operations and factor objects:** reconstruction of the expected covariance,
|
|
33
|
+
solves, log determinants, quadratic forms and logical ordering after updates.
|
|
34
|
+
- **JAX transformations:** JIT, batching, runtime indices, first-order JVPs and
|
|
35
|
+
VJPs, and combinations such as differentiation through replacement scans.
|
|
36
|
+
- **Derivative accuracy:** comparison with dense derivatives, JVP/VJP duality,
|
|
37
|
+
and independent Decimal calculations in [tests/reference](tests/reference).
|
|
38
|
+
- **Sequences and larger matrices:** accumulated factor and gradient errors over
|
|
39
|
+
repeated replacements, plus scan lengths absent from the small CI cases.
|
|
40
|
+
- **GPU storage:** compiler-reported temporary memory for deletion gradients at
|
|
41
|
+
several matrix sizes.
|
|
42
|
+
- **Benchmark comparisons:** matching inputs, outputs and derivatives across
|
|
43
|
+
implementations, including the naive replacement baseline.
|
|
44
|
+
|
|
45
|
+
Tolerances are chosen per test and precision. Higher-order derivatives are not
|
|
46
|
+
part of the tested API. See [numerical limits](docs/numerics.md) for limitations
|
|
47
|
+
that passing these tests does not remove.
|
|
48
|
+
|
|
49
|
+
## Writing tests
|
|
50
|
+
|
|
51
|
+
Each test should establish a desired behavior and have a name that explains
|
|
52
|
+
what a failure means. Compare numerical results with an independent calculation.
|
|
53
|
+
For derivatives, choose an objective that depends on the inputs being tested.
|
|
54
|
+
|
|
55
|
+
Keep setup and assertions direct. Split unrelated checks into separate tests,
|
|
56
|
+
and use parameter names that identify the failing case. Check logical results
|
|
57
|
+
and documented behavior without requiring a particular internal arrangement.
|
|
58
|
+
Keep numerical regression cases and their precision-specific tolerances when
|
|
59
|
+
consolidating tests.
|
|
60
|
+
|
|
@@ -0,0 +1,224 @@
|
|
|
1
|
+
# Benchmarks
|
|
2
|
+
|
|
3
|
+
This page presents H100 results for all six operations in the main benchmark:
|
|
4
|
+
append, delete, positive rank-one update, replacement, delete-and-append, and
|
|
5
|
+
trailing-block replacement. Each is measured in float32 and float64, in forward,
|
|
6
|
+
reverse and JVP modes, at matrix sizes 512–16,384.
|
|
7
|
+
|
|
8
|
+
All six operations were faster than dense JAX recomputation on the measured
|
|
9
|
+
fixtures. The advantage generally grows with matrix size. The plots show the
|
|
10
|
+
full range, and the tables give absolute times at **16,384 × 16,384**.
|
|
11
|
+
|
|
12
|
+
## What the timings include
|
|
13
|
+
|
|
14
|
+
Every operation starts from an existing Cholesky factor. The JAX baseline
|
|
15
|
+
reconstructs `L @ L.T`, applies the change and factors the resulting covariance.
|
|
16
|
+
Replacement also includes a naive baseline using two signed rank-one JAX scans
|
|
17
|
+
with standard autodiff. See [_recompute.py](_recompute.py), [_naive.py](_naive.py)
|
|
18
|
+
and the operation references in [workloads.py](workloads.py).
|
|
19
|
+
|
|
20
|
+
**Forward** returns the updated factor. **Value + gradient** evaluates a fixed
|
|
21
|
+
weighted sum of that factor and differentiates it with respect to every
|
|
22
|
+
continuous input. Both the primal calculation and reverse pass are timed.
|
|
23
|
+
**Directional derivative (JVP)** evaluates the factor and its derivative along
|
|
24
|
+
one input direction.
|
|
25
|
+
Indexed operations modify the first variable. Trailing-block replacement
|
|
26
|
+
changes four variables.
|
|
27
|
+
|
|
28
|
+
These are warm execution times. Each point is the median of three process
|
|
29
|
+
medians, and shading spans their minimum and maximum. Compilation and cold
|
|
30
|
+
first use are recorded separately in [summary.csv](summary.csv).
|
|
31
|
+
[Speedups](speedups.csv) are calculated within each process before taking their
|
|
32
|
+
median.
|
|
33
|
+
|
|
34
|
+
## Float32 results
|
|
35
|
+
|
|
36
|
+

|
|
37
|
+
|
|
38
|
+
At **16,384**, times in milliseconds:
|
|
39
|
+
|
|
40
|
+
| Operation | Forward cholops / JAX (ms) | Value + gradient cholops / JAX (ms) |
|
|
41
|
+
| --- | ---: | ---: |
|
|
42
|
+
| `chol_append` | 5.17 / 242.58 | 8.23 / 1021.03 |
|
|
43
|
+
| `chol_delete` | 7.57 / 241.39 | 20.40 / 1032.96 |
|
|
44
|
+
| `chol_rank1_positive` | 4.65 / 213.10 | 17.55 / 1000.16 |
|
|
45
|
+
| `chol_replace` | 13.31 / 209.73 | 43.30 / 984.93 |
|
|
46
|
+
| `chol_delete_append` | 8.39 / 215.69 | 23.95 / 1012.61 |
|
|
47
|
+
| `chol_replace_last` | 5.87 / 214.33 | 13.62 / 999.27 |
|
|
48
|
+
|
|
49
|
+
## Float64 results
|
|
50
|
+
|
|
51
|
+

|
|
52
|
+
|
|
53
|
+
At **16,384**, times in milliseconds:
|
|
54
|
+
|
|
55
|
+
| Operation | Forward cholops / JAX (ms) | Value + gradient cholops / JAX (ms) |
|
|
56
|
+
| --- | ---: | ---: |
|
|
57
|
+
| `chol_append` | 8.39 / 218.90 | 9.75 / 1106.23 |
|
|
58
|
+
| `chol_delete` | 11.51 / 222.41 | 28.78 / 1096.31 |
|
|
59
|
+
| `chol_rank1_positive` | 7.80 / 213.09 | 26.75 / 977.39 |
|
|
60
|
+
| `chol_replace` | 19.84 / 202.27 | 61.60 / 961.97 |
|
|
61
|
+
| `chol_delete_append` | 13.02 / 217.27 | 32.31 / 998.61 |
|
|
62
|
+
| `chol_replace_last` | 10.44 / 211.73 | 20.94 / 979.77 |
|
|
63
|
+
|
|
64
|
+
The two tables compare cholops with dense recomputation. For single-variable
|
|
65
|
+
replacement, the plots also show the naive baseline. At 16,384, its forward and
|
|
66
|
+
value-plus-gradient times are 283.58 / 1295.88 ms in float32 and
|
|
67
|
+
319.26 / 1413.17 ms in float64. The compact [summary](summary.csv) contains all
|
|
68
|
+
sizes, modes and implementations.
|
|
69
|
+
|
|
70
|
+
A caller that already stores its covariance can avoid reconstructing `L @ L.T`.
|
|
71
|
+
These factor-input timings therefore describe individual operations, rather
|
|
72
|
+
than a complete GP calculation. The campaign also provides sequence benchmarks
|
|
73
|
+
whose recomputation baseline retains the covariance between steps.
|
|
74
|
+
|
|
75
|
+
## Memory
|
|
76
|
+
|
|
77
|
+
Faster execution does not always mean lower memory use. The following compiler
|
|
78
|
+
working-set estimates are for **float64 at 16,384**:
|
|
79
|
+
|
|
80
|
+
| Operation | Forward cholops / JAX (GiB) | Value + gradient cholops / JAX (GiB) |
|
|
81
|
+
| --- | ---: | ---: |
|
|
82
|
+
| `chol_append` | 6.00 / 8.00 | 4.00 / 12.00 |
|
|
83
|
+
| `chol_delete` | 6.13 / 8.00 | 12.02 / 12.03 |
|
|
84
|
+
| `chol_rank1_positive` | 6.13 / 8.00 | 12.14 / 10.03 |
|
|
85
|
+
| `chol_replace` | 10.13 / 8.00 | 18.25 / 14.50 |
|
|
86
|
+
| `chol_delete_append` | 6.13 / 6.03 | 12.02 / 16.50 |
|
|
87
|
+
| `chol_replace_last` | 6.00 / 8.00 | 6.00 / 12.00 |
|
|
88
|
+
|
|
89
|
+
The working set is arguments + outputs + temporaries - aliases. These are
|
|
90
|
+
compiler estimates, not measured peak GPU allocations. Values are the largest
|
|
91
|
+
estimate across process repeats. [summary.csv](summary.csv) includes both
|
|
92
|
+
precisions and separates temporary storage from the whole working set. The
|
|
93
|
+
[replacement memory plot](figures/memory.svg) also includes the naive baseline.
|
|
94
|
+
|
|
95
|
+
## Numerical accuracy
|
|
96
|
+
|
|
97
|
+
Numerical differences are recorded alongside timings without filtering samples
|
|
98
|
+
or changing outputs. The [numerical tests](../TESTING.md) check factors and
|
|
99
|
+
gradients on specified fixtures.
|
|
100
|
+
|
|
101
|
+
One float32 delete-and-append case at 8,192 illustrates why disagreement with
|
|
102
|
+
recomputation needs interpretation. Its weighted scalar loss differed by about
|
|
103
|
+
0.00071 relative. Promoting the same inputs and loss weights to float64 showed
|
|
104
|
+
that cancellation in the float32 baseline caused most of the discrepancy:
|
|
105
|
+
|
|
106
|
+
| Relative error against the same-input float64 reference | cholops float32 | JAX float32 |
|
|
107
|
+
| --- | ---: | ---: |
|
|
108
|
+
| Factor | 1.31e-7 | 1.23e-5 |
|
|
109
|
+
| Weighted scalar value | 1.10e-5 | 6.99e-4 |
|
|
110
|
+
| Largest gradient-leaf error | 3.16e-7 | 1.71e-5 |
|
|
111
|
+
|
|
112
|
+
This is a diagnostic for that case. Accuracy requirements still depend on the
|
|
113
|
+
application and conditioning of its matrices.
|
|
114
|
+
|
|
115
|
+
## Reproduce the results
|
|
116
|
+
|
|
117
|
+
The recorded campaign used an NVIDIA H100 with 95,830 MiB reported memory,
|
|
118
|
+
32 CPU threads per process, JAX/JAXlib 0.11.2, NumPy 2.5.4 and Python 3.13.17.
|
|
119
|
+
Float32 and float64 ran in separate processes with matrix multiplication
|
|
120
|
+
precision set to `highest`. All 720 planned cases completed without skips.
|
|
121
|
+
|
|
122
|
+
### Run the campaign
|
|
123
|
+
|
|
124
|
+
From a checkout on a configured Linux GPU host:
|
|
125
|
+
|
|
126
|
+
```sh
|
|
127
|
+
uv sync --locked --all-groups --extra cuda13
|
|
128
|
+
|
|
129
|
+
# Write a plan to inspect before running measurements.
|
|
130
|
+
uv run --locked python -m benchmarks.suite --backend gpu \
|
|
131
|
+
--memory-budget-gib 64 --output results/benchmarks/main-plan
|
|
132
|
+
|
|
133
|
+
# Create and execute a new plan on this host.
|
|
134
|
+
uv run --locked python -m benchmarks.suite --backend gpu \
|
|
135
|
+
--memory-budget-gib 64 --output results/benchmarks/main --execute
|
|
136
|
+
|
|
137
|
+
# Generate figures and summary tables from that campaign.
|
|
138
|
+
uv run --locked python -m benchmarks.plot results/benchmarks/main \
|
|
139
|
+
--output results/benchmarks/main/plots
|
|
140
|
+
```
|
|
141
|
+
|
|
142
|
+
The default plan contains 720 cases: 648 for the six operation curves and
|
|
143
|
+
72 for the additional workloads below. It uses six sizes, two precisions,
|
|
144
|
+
forward, reverse and JVP modes, and three process repeats. Output directories
|
|
145
|
+
for plans and cases must be new. Use `--backend cpu` for a CPU campaign and omit
|
|
146
|
+
the CUDA extra when installing its environment. Select `--sizes` and `--dtypes` for smaller runs.
|
|
147
|
+
|
|
148
|
+
Each case runs in a fresh process. After compilation and the first synchronized
|
|
149
|
+
call, every implementation receives two warmups and fifteen timed calls.
|
|
150
|
+
Implementation order is shuffled within each round and saved. Timing waits for
|
|
151
|
+
the entire output. Inputs are already on the device, and buffers are not donated.
|
|
152
|
+
The seed is fixed, using a dense Gram covariance from at most 16 features plus
|
|
153
|
+
an identity term. Process repeats measure timing variability on the same matrix.
|
|
154
|
+
|
|
155
|
+
Choose a memory budget below available device RAM. The runner checks memory
|
|
156
|
+
before preparing fixtures and before executing compiled code. Cases that exceed
|
|
157
|
+
the budget appear as explicit skips in `coverage.csv`. Execution errors stop the
|
|
158
|
+
campaign and leave a case log to inspect. Optional sizes 32,768 and 65,536 need
|
|
159
|
+
substantially more memory and are outside the default plan.
|
|
160
|
+
|
|
161
|
+
### Where results are stored
|
|
162
|
+
|
|
163
|
+
Raw campaigns belong in the gitignored **`results/benchmarks/`** directory at
|
|
164
|
+
the repository root. Each campaign contains its plan, case directories, logs,
|
|
165
|
+
timing samples, numerical diagnostics and source metadata. The existing H100
|
|
166
|
+
campaign is retained locally as `results/benchmarks/release-reduced-9e03d8b/`.
|
|
167
|
+
|
|
168
|
+
The repository keeps the report in this README, selected figures in
|
|
169
|
+
[`figures/`](figures/), and the compact `summary.csv` and `speedups.csv` tables.
|
|
170
|
+
Raw measurements are not included in a fresh checkout. To regenerate plots,
|
|
171
|
+
run a campaign or use a retained local campaign as the input to `benchmarks.plot`.
|
|
172
|
+
For example, the saved H100 campaign can be rendered with:
|
|
173
|
+
|
|
174
|
+
```sh
|
|
175
|
+
uv run --locked python -m benchmarks.plot results/benchmarks/release-reduced-9e03d8b \
|
|
176
|
+
--output results/benchmarks/release-reduced-9e03d8b/plots
|
|
177
|
+
```
|
|
178
|
+
|
|
179
|
+
New runs measure the current checkout and record its source hashes and
|
|
180
|
+
environment. The plotter checks that cases match the plan and use consistent
|
|
181
|
+
hardware and JAX versions. Combining source versions requires a source audit
|
|
182
|
+
for each case. Use `--allow-partial` to preview an incomplete campaign.
|
|
183
|
+
|
|
184
|
+
### Check the setup with one small case
|
|
185
|
+
|
|
186
|
+
```sh
|
|
187
|
+
uv run --locked python -m benchmarks.run --backend cpu --dtype float64 \
|
|
188
|
+
--workload operations --operation replace --mode full_vjp \
|
|
189
|
+
--implementations tensor naive recompute --n 8 --position first \
|
|
190
|
+
--samples 3 --memory-budget-gib 4 --output results/benchmarks/smoke
|
|
191
|
+
```
|
|
192
|
+
|
|
193
|
+
This checks execution and output files. Use the declared campaign sizes for
|
|
194
|
+
performance comparisons. Add `--dump-hlo` when profiling an individual case.
|
|
195
|
+
|
|
196
|
+
## Additional workloads
|
|
197
|
+
|
|
198
|
+
The campaign also measures:
|
|
199
|
+
|
|
200
|
+
- Signed rank-one and diagonal updates at size 4,096, using weight `-0.2`.
|
|
201
|
+
These compare tensor calls with dense recomputation.
|
|
202
|
+
- 16-step replacement sequences at sizes 2,048 and 8,192, comparing `Cholesky`,
|
|
203
|
+
`PermutedCholesky` and dense recomputation. Each includes initialization and
|
|
204
|
+
a Gaussian loss at every step. Recomputation retains the covariance between
|
|
205
|
+
steps. All methods use four-step checkpoint blocks.
|
|
206
|
+
|
|
207
|
+
Both workloads use float32 and float64, forward, reverse and JVP modes, and
|
|
208
|
+
three process repeats, giving 36 cases each. Indexed updates start at the first
|
|
209
|
+
position. Sequences advance the index after each step. Reverse mode differentiates
|
|
210
|
+
the mean sequence loss with respect to initial features, incoming features and
|
|
211
|
+
scale. Their measurements are included in [summary.csv](summary.csv).
|
|
212
|
+
|
|
213
|
+
At size 4,096, both signed updates were slower than dense recomputation. In
|
|
214
|
+
float64, their forward times were about 102 ms versus 4.84 ms for recomputation.
|
|
215
|
+
Value + gradient took 481–485 ms versus 18.64–18.83 ms.
|
|
216
|
+
|
|
217
|
+
## Code layout
|
|
218
|
+
|
|
219
|
+
`suite.py` defines and launches cases. `workloads.py` builds the computations and
|
|
220
|
+
reference results that `run.py` compiles and times. `plot.py` reads the saved
|
|
221
|
+
campaign and produces summaries and figures. `_support.py` supplies fixtures,
|
|
222
|
+
diagnostics and checkpointing. `_environment.py` records source and environment
|
|
223
|
+
information. The full pytest suite checks the workload calculations against
|
|
224
|
+
their references.
|