cehrbert-data 0.0.1__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- cehrbert_data-0.0.1/.github/workflows/tests.yml +39 -0
- cehrbert_data-0.0.1/.gitignore +6 -0
- cehrbert_data-0.0.1/.pre-commit-config.yaml +83 -0
- cehrbert_data-0.0.1/LICENSE +21 -0
- cehrbert_data-0.0.1/PKG-INFO +116 -0
- cehrbert_data-0.0.1/README.md +88 -0
- cehrbert_data-0.0.1/pyproject.toml +54 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept/.part-00000-4b12270c-f6c8-4b59-8e0f-fd588bd79386-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept/.part-00003-4b12270c-f6c8-4b59-8e0f-fd588bd79386-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept/.part-00010-4b12270c-f6c8-4b59-8e0f-fd588bd79386-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept/_SUCCESS +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept/part-00000-4b12270c-f6c8-4b59-8e0f-fd588bd79386-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept/part-00003-4b12270c-f6c8-4b59-8e0f-fd588bd79386-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept/part-00010-4b12270c-f6c8-4b59-8e0f-fd588bd79386-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/.part-00000-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/.part-00002-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/.part-00006-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/.part-00011-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/.part-00013-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/_SUCCESS +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/part-00000-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/part-00002-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/part-00006-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/part-00011-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_ancestor/part-00013-eafbd8be-3337-46da-89d3-20f79c2565d4-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/.part-00000-5752b472-8ba7-4189-ab69-8c92e46443aa-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/.part-00002-5752b472-8ba7-4189-ab69-8c92e46443aa-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/.part-00007-5752b472-8ba7-4189-ab69-8c92e46443aa-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/.part-00012-5752b472-8ba7-4189-ab69-8c92e46443aa-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/_SUCCESS +0 -0
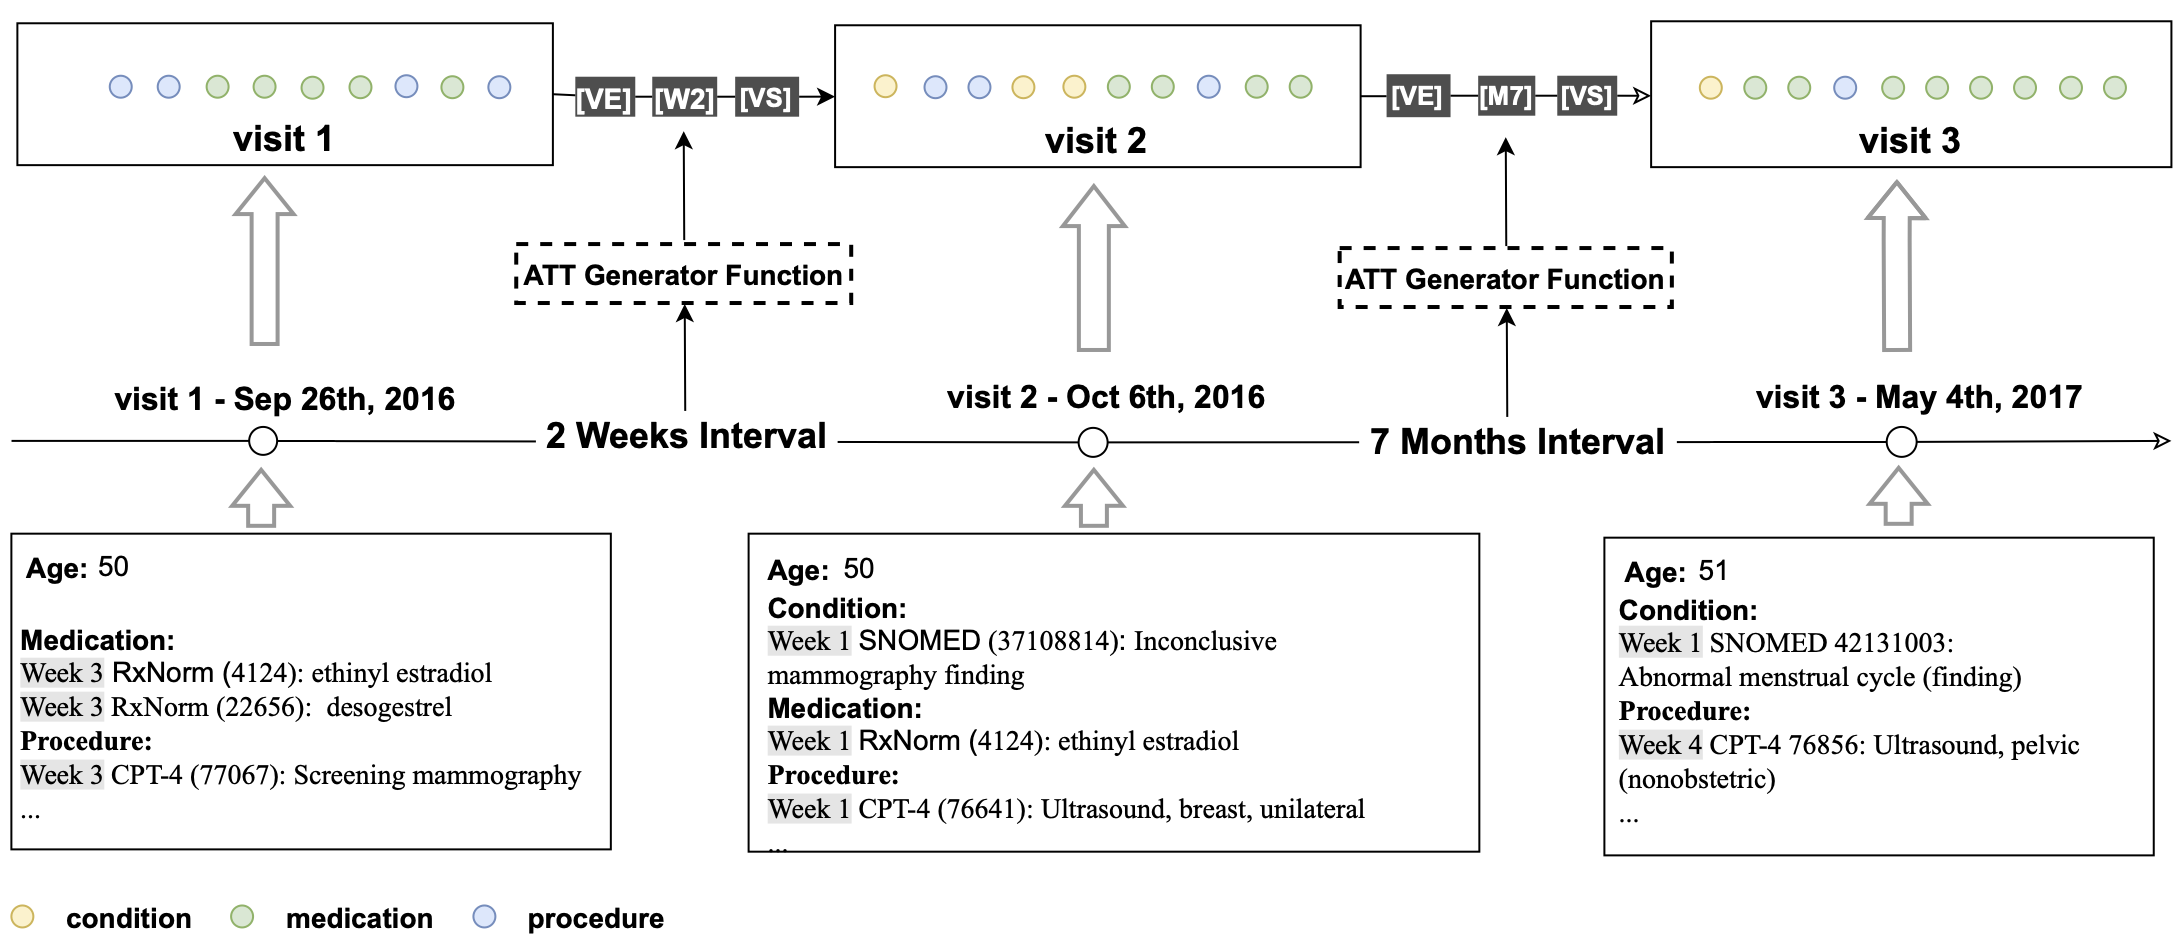
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/part-00000-5752b472-8ba7-4189-ab69-8c92e46443aa-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/part-00002-5752b472-8ba7-4189-ab69-8c92e46443aa-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/part-00007-5752b472-8ba7-4189-ab69-8c92e46443aa-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/concept_relationship/part-00012-5752b472-8ba7-4189-ab69-8c92e46443aa-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/condition_occurrence/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/condition_occurrence/.part-00000-4eff03a1-cdcf-4c89-b0cd-9ce590b9b1eb-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/condition_occurrence/_SUCCESS +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/condition_occurrence/part-00000-4eff03a1-cdcf-4c89-b0cd-9ce590b9b1eb-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/drug_exposure/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/drug_exposure/.part-00000-10bbf1a4-a7da-416e-9703-58609c7edfad-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/drug_exposure/_SUCCESS +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/drug_exposure/part-00000-10bbf1a4-a7da-416e-9703-58609c7edfad-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/observation_period/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/observation_period/.part-00000-694316e5-cc95-49f1-9fad-5a7f377e2602-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/observation_period/_SUCCESS +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/observation_period/part-00000-694316e5-cc95-49f1-9fad-5a7f377e2602-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/person/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/person/.part-00000-7d789011-f361-48da-af6f-cfe102978b3a-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/person/_SUCCESS +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/person/part-00000-7d789011-f361-48da-af6f-cfe102978b3a-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/procedure_occurrence/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/procedure_occurrence/.part-00000-e73003c1-aed5-41c0-b2d4-eaccaccf044a-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/procedure_occurrence/_SUCCESS +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/procedure_occurrence/part-00000-e73003c1-aed5-41c0-b2d4-eaccaccf044a-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/visit_occurrence/._SUCCESS.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/visit_occurrence/.part-00000-e874b5f1-bf9e-4cb9-93bf-c309a47b0476-c000.snappy.parquet.crc +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/visit_occurrence/_SUCCESS +0 -0
- cehrbert_data-0.0.1/sample_data/omop_sample/visit_occurrence/part-00000-e874b5f1-bf9e-4cb9-93bf-c309a47b0476-c000.snappy.parquet +0 -0
- cehrbert_data-0.0.1/setup.cfg +4 -0
- cehrbert_data-0.0.1/src/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/apps/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/apps/generate_concept_similarity_table.py +423 -0
- cehrbert_data-0.0.1/src/cehrbert_data/apps/generate_hierarchical_bert_training_data.py +238 -0
- cehrbert_data-0.0.1/src/cehrbert_data/apps/generate_included_concept_list.py +116 -0
- cehrbert_data-0.0.1/src/cehrbert_data/apps/generate_information_content.py +131 -0
- cehrbert_data-0.0.1/src/cehrbert_data/apps/generate_required_labs.py +112 -0
- cehrbert_data-0.0.1/src/cehrbert_data/apps/generate_training_data.py +337 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/atrial_fibrillation.py +45 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/cabg.py +72 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/coronary_artery_disease.py +84 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/covid.py +43 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/covid_inpatient.py +84 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/death.py +46 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/heart_failure.py +423 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/ischemic_stroke.py +45 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/last_visit_discharged_home.py +35 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/query_builder.py +153 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/spark_app_base.py +745 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/type_two_diabietes.py +166 -0
- cehrbert_data-0.0.1/src/cehrbert_data/cohorts/ventilation.py +22 -0
- cehrbert_data-0.0.1/src/cehrbert_data/config/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/config/output_names.py +9 -0
- cehrbert_data-0.0.1/src/cehrbert_data/const/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/const/__pycache__/__init__.cpython-311.pyc +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/const/__pycache__/common.cpython-311.pyc +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/const/common.py +28 -0
- cehrbert_data-0.0.1/src/cehrbert_data/decorators/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/decorators/__pycache__/__init__.cpython-311.pyc +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/decorators/__pycache__/patient_event_decorator.cpython-311.pyc +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/decorators/patient_event_decorator.py +759 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/afib_ischemic_stroke.py +14 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/cad_cabg_cohort.py +19 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/cad_hf_cohort.py +14 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/copd_readmission.py +76 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/covid_death.py +14 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/covid_ventilation.py +14 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/discharge_home_death.py +18 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/hf_readmission.py +82 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/hospitalization.py +100 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/hospitalization_mortality.py +77 -0
- cehrbert_data-0.0.1/src/cehrbert_data/prediction_cohorts/t2dm_hf_cohort.py +14 -0
- cehrbert_data-0.0.1/src/cehrbert_data/queries/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/queries/measurement_unit_stats_query.py +42 -0
- cehrbert_data-0.0.1/src/cehrbert_data/tools/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/tools/download_omop_tables.py +141 -0
- cehrbert_data-0.0.1/src/cehrbert_data/utils/__init__.py +0 -0
- cehrbert_data-0.0.1/src/cehrbert_data/utils/spark_parse_args.py +350 -0
- cehrbert_data-0.0.1/src/cehrbert_data/utils/spark_utils.py +1405 -0
- cehrbert_data-0.0.1/src/cehrbert_data.egg-info/PKG-INFO +116 -0
- cehrbert_data-0.0.1/src/cehrbert_data.egg-info/SOURCES.txt +122 -0
- cehrbert_data-0.0.1/src/cehrbert_data.egg-info/dependency_links.txt +1 -0
- cehrbert_data-0.0.1/src/cehrbert_data.egg-info/requires.txt +13 -0
- cehrbert_data-0.0.1/src/cehrbert_data.egg-info/top_level.txt +2 -0
- cehrbert_data-0.0.1/tests/__init__.py +0 -0
- cehrbert_data-0.0.1/tests/integration_tests/__init__.py +0 -0
- cehrbert_data-0.0.1/tests/integration_tests/test_generate_training_data.py +31 -0
- cehrbert_data-0.0.1/tests/integration_tests/test_hf_readmission.py +49 -0
- cehrbert_data-0.0.1/tests/pyspark_test_base.py +45 -0
|
@@ -0,0 +1,39 @@
|
|
|
1
|
+
# This workflow will install Python dependencies, run tests and lint with a single version of Python
|
|
2
|
+
# For more information see: https://docs.github.com/en/actions/automating-builds-and-tests/building-and-testing-python
|
|
3
|
+
|
|
4
|
+
name: Tests
|
|
5
|
+
|
|
6
|
+
on:
|
|
7
|
+
push:
|
|
8
|
+
branches: [ "main" ]
|
|
9
|
+
pull_request:
|
|
10
|
+
branches: [ "main" ]
|
|
11
|
+
|
|
12
|
+
permissions:
|
|
13
|
+
contents: read
|
|
14
|
+
|
|
15
|
+
jobs:
|
|
16
|
+
build:
|
|
17
|
+
|
|
18
|
+
runs-on: ubuntu-latest
|
|
19
|
+
|
|
20
|
+
steps:
|
|
21
|
+
- uses: actions/checkout@v3
|
|
22
|
+
- name: Set up Python 3.10.0
|
|
23
|
+
uses: actions/setup-python@v3
|
|
24
|
+
with:
|
|
25
|
+
python-version: "3.10"
|
|
26
|
+
- name: Install dependencies
|
|
27
|
+
run: |
|
|
28
|
+
python -m pip install --upgrade pip
|
|
29
|
+
pip install flake8 pytest
|
|
30
|
+
pip install -e .
|
|
31
|
+
- name: Lint with flake8
|
|
32
|
+
run: |
|
|
33
|
+
# stop the build if there are Python syntax errors or undefined names
|
|
34
|
+
flake8 . --count --select=E9,F63,F7,F82 --show-source --statistics
|
|
35
|
+
# exit-zero treats all errors as warnings. The GitHub editor is 127 chars wide
|
|
36
|
+
flake8 . --count --exit-zero --max-complexity=10 --max-line-length=127 --statistics
|
|
37
|
+
- name: Test with pytest
|
|
38
|
+
run: |
|
|
39
|
+
PYTHONPATH=./: pytest
|
|
@@ -0,0 +1,83 @@
|
|
|
1
|
+
# For documentation on pre-commit usage, see https://pre-commit.com/
|
|
2
|
+
# This file should be updated quarterly by a developer running `pre-commit autoupdate`
|
|
3
|
+
# with changes added and committed.
|
|
4
|
+
# This will run all defined formatters prior to adding a commit.
|
|
5
|
+
default_language_version:
|
|
6
|
+
python: python3 # or python3.10 to set a specific default version
|
|
7
|
+
|
|
8
|
+
repos:
|
|
9
|
+
- repo: https://github.com/pre-commit/pre-commit-hooks
|
|
10
|
+
rev: v4.6.0
|
|
11
|
+
hooks:
|
|
12
|
+
- id: check-yaml
|
|
13
|
+
- id: end-of-file-fixer
|
|
14
|
+
- id: trailing-whitespace
|
|
15
|
+
|
|
16
|
+
- repo: https://github.com/DanielNoord/pydocstringformatter
|
|
17
|
+
rev: 'v0.7.3'
|
|
18
|
+
hooks:
|
|
19
|
+
- id: pydocstringformatter
|
|
20
|
+
|
|
21
|
+
- repo: https://github.com/PyCQA/autoflake
|
|
22
|
+
rev: v2.2.0
|
|
23
|
+
hooks:
|
|
24
|
+
- id: autoflake
|
|
25
|
+
|
|
26
|
+
- repo: https://github.com/psf/black
|
|
27
|
+
rev: '24.1.1'
|
|
28
|
+
hooks:
|
|
29
|
+
- id: black
|
|
30
|
+
# It is recommended to specify the latest version of Python
|
|
31
|
+
# supported by your project here, or alternatively use
|
|
32
|
+
# pre-commit's default_language_version, see
|
|
33
|
+
# https://pre-commit.com/#top_level-default_language_version
|
|
34
|
+
# Pre-commit hook info from: https://black.readthedocs.io/en/stable/integrations/source_version_control.html
|
|
35
|
+
# Editor integration here: https://black.readthedocs.io/en/stable/integrations/editors.html
|
|
36
|
+
|
|
37
|
+
- repo: https://github.com/adamchainz/blacken-docs
|
|
38
|
+
rev: "v1.12.1" # replace with latest tag on GitHub
|
|
39
|
+
hooks:
|
|
40
|
+
- id: blacken-docs
|
|
41
|
+
additional_dependencies:
|
|
42
|
+
- black>=22.12.0
|
|
43
|
+
|
|
44
|
+
- repo: https://github.com/pre-commit/pre-commit-hooks
|
|
45
|
+
rev: 'v4.5.0'
|
|
46
|
+
hooks:
|
|
47
|
+
- id: trailing-whitespace
|
|
48
|
+
exclude: .git/COMMIT_EDITMSG
|
|
49
|
+
- id: end-of-file-fixer
|
|
50
|
+
exclude: .git/COMMIT_EDITMSG
|
|
51
|
+
- id: detect-private-key
|
|
52
|
+
- id: debug-statements
|
|
53
|
+
- id: check-json
|
|
54
|
+
- id: pretty-format-json
|
|
55
|
+
- id: check-yaml
|
|
56
|
+
- id: name-tests-test
|
|
57
|
+
- id: requirements-txt-fixer
|
|
58
|
+
|
|
59
|
+
- repo: https://github.com/pre-commit/pygrep-hooks
|
|
60
|
+
rev: 'v1.10.0'
|
|
61
|
+
hooks:
|
|
62
|
+
- id: python-no-eval
|
|
63
|
+
- id: python-no-log-warn
|
|
64
|
+
- id: python-use-type-annotations
|
|
65
|
+
|
|
66
|
+
- repo: https://github.com/Lucas-C/pre-commit-hooks
|
|
67
|
+
rev: v1.5.4
|
|
68
|
+
hooks:
|
|
69
|
+
- id: remove-crlf
|
|
70
|
+
- id: remove-tabs # defaults to: 4
|
|
71
|
+
exclude: .git/COMMIT_EDITMSG
|
|
72
|
+
|
|
73
|
+
- repo: https://github.com/PyCQA/isort.git
|
|
74
|
+
rev: 5.13.2
|
|
75
|
+
hooks:
|
|
76
|
+
- id: isort
|
|
77
|
+
args: [ "--profile", "black" ]
|
|
78
|
+
|
|
79
|
+
- repo: https://github.com/PyCQA/bandit
|
|
80
|
+
rev: '1.7.7'
|
|
81
|
+
hooks:
|
|
82
|
+
- id: bandit
|
|
83
|
+
args: ["--skip", "B101,B106,B107,B301,B311,B105,B608,B403"]
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2023 Department of Biomedical Informatics
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,116 @@
|
|
|
1
|
+
Metadata-Version: 2.1
|
|
2
|
+
Name: cehrbert_data
|
|
3
|
+
Version: 0.0.1
|
|
4
|
+
Summary: The Spark ETL tools for generating the CEHR-BERT and CEHR-GPT pre-training and finetuning data
|
|
5
|
+
Author-email: Chao Pang <chaopang229@gmail.com>, Xinzhuo Jiang <xj2193@cumc.columbia.edu>, Krishna Kalluri <kk3326@cumc.columbia.edu>, Nishanth Parameshwar Pavinkurve <np2689@cumc.columbia.edu>, Karthik Natarajan <kn2174@cumc.columbia.edu>
|
|
6
|
+
License: MIT License
|
|
7
|
+
Project-URL: Homepage, https://github.com/knatarajan-lab/cehrbert_data
|
|
8
|
+
Classifier: Development Status :: 5 - Production/Stable
|
|
9
|
+
Classifier: Intended Audience :: Developers
|
|
10
|
+
Classifier: Intended Audience :: Science/Research
|
|
11
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
12
|
+
Classifier: Programming Language :: Python :: 3
|
|
13
|
+
Requires-Python: >=3.10.0
|
|
14
|
+
Description-Content-Type: text/markdown
|
|
15
|
+
License-File: LICENSE
|
|
16
|
+
Requires-Dist: numpy==1.24.3
|
|
17
|
+
Requires-Dist: packaging==23.2
|
|
18
|
+
Requires-Dist: pandas==2.2.0
|
|
19
|
+
Requires-Dist: pyspark==3.1.2
|
|
20
|
+
Provides-Extra: dev
|
|
21
|
+
Requires-Dist: pre-commit; extra == "dev"
|
|
22
|
+
Requires-Dist: pytest; extra == "dev"
|
|
23
|
+
Requires-Dist: pytest-cov; extra == "dev"
|
|
24
|
+
Requires-Dist: pytest-subtests; extra == "dev"
|
|
25
|
+
Requires-Dist: rootutils; extra == "dev"
|
|
26
|
+
Requires-Dist: hypothesis; extra == "dev"
|
|
27
|
+
Requires-Dist: black; extra == "dev"
|
|
28
|
+
|
|
29
|
+
# cehrbert_data
|
|
30
|
+
|
|
31
|
+
cehrbert_data is the ETL tool that generates the pretraining and finetuning datasets for CEHRbERT, which is a large language model developed for the structured EHR data, the work has been published
|
|
32
|
+
at https://proceedings.mlr.press/v158/pang21a.html.
|
|
33
|
+
|
|
34
|
+
## Patient Representation
|
|
35
|
+
For each patient, all medical codes were aggregated and constructed into a sequence chronologically.
|
|
36
|
+
In order to incorporate temporal information, we inserted an artificial time token (ATT) between two neighboring visits
|
|
37
|
+
based on their time interval.
|
|
38
|
+
The following logic was used for creating ATTs based on the following time intervals between visits, if less than 28
|
|
39
|
+
days, ATTs take on the form of $W_n$ where n represents the week number ranging from 0-3 (e.g. $W_1$); 2) if between 28
|
|
40
|
+
days and 365 days, ATTs are in the form of **$M_n$** where n represents the month number ranging from 1-11 e.g $M_{11}$;
|
|
41
|
+
|
|
42
|
+
3) beyond 365 days then a **LT** (Long Term) token is inserted. In addition, we added two more special tokens — **VS**
|
|
43
|
+
and **VE** to represent the start and the end of a visit to explicitly define the visit segment, where all the
|
|
44
|
+
concepts
|
|
45
|
+
associated with the visit are subsumed by **VS** and **VE**.
|
|
46
|
+
|
|
47
|
+
|
|
48
|
+
|
|
49
|
+
## Pre-requisite
|
|
50
|
+
The project is built in python 3.10, and project dependency needs to be installed
|
|
51
|
+
|
|
52
|
+
Create a new Python virtual environment
|
|
53
|
+
|
|
54
|
+
```console
|
|
55
|
+
python3.10 -m venv .venv;
|
|
56
|
+
source .venv/bin/activate;
|
|
57
|
+
```
|
|
58
|
+
|
|
59
|
+
Build the project
|
|
60
|
+
|
|
61
|
+
```console
|
|
62
|
+
pip install -e .
|
|
63
|
+
```
|
|
64
|
+
|
|
65
|
+
Download [jtds-1.3.1.jar](jtds-1.3.1.jar) into the spark jars folder in the python environment
|
|
66
|
+
```console
|
|
67
|
+
cp jtds-1.3.1.jar .venv/lib/python3.10/site-packages/pyspark/jars/
|
|
68
|
+
```
|
|
69
|
+
## Instructions for Use
|
|
70
|
+
|
|
71
|
+
### 1. Download OMOP tables as parquet files
|
|
72
|
+
|
|
73
|
+
We created a spark app to download OMOP tables from SQL Server as parquet files. You need adjust the properties
|
|
74
|
+
in `db_properties.ini` to match with your database setup.
|
|
75
|
+
|
|
76
|
+
```console
|
|
77
|
+
PYTHONPATH=./: spark-submit tools/download_omop_tables.py -c db_properties.ini -tc person visit_occurrence condition_occurrence procedure_occurrence drug_exposure measurement observation_period concept concept_relationship concept_ancestor -o ~/Documents/omop_test/
|
|
78
|
+
```
|
|
79
|
+
|
|
80
|
+
We have prepared a synthea dataset with 1M patients for you to test, you could download it
|
|
81
|
+
at [omop_synthea.tar.gz](https://drive.google.com/file/d/1k7-cZACaDNw8A1JRI37mfMAhEErxKaQJ/view?usp=share_link)
|
|
82
|
+
|
|
83
|
+
```console
|
|
84
|
+
tar -xvf omop_synthea.tar ~/Document/omop_test/
|
|
85
|
+
```
|
|
86
|
+
|
|
87
|
+
### 2. Generate training data for CEHR-BERT
|
|
88
|
+
We order the patient events in chronological order and put all data points in a sequence. We insert artificial tokens
|
|
89
|
+
VS (visit start) and VE (visit end) to the start and the end of the visit. In addition, we insert artificial time
|
|
90
|
+
tokens (ATT) between visits to indicate the time interval between visits. This approach allows us to apply BERT to
|
|
91
|
+
structured EHR as-is.
|
|
92
|
+
The sequence can be seen conceptually as [VS] [V1] [VE] [ATT] [VS] [V2] [VE], where [V1] and [V2] represent a list of
|
|
93
|
+
concepts associated with those visits.
|
|
94
|
+
|
|
95
|
+
```console
|
|
96
|
+
PYTHONPATH=./: spark-submit spark_apps/generate_training_data.py -i ~/Documents/omop_test/ -o ~/Documents/omop_test/cehr-bert -tc condition_occurrence procedure_occurrence drug_exposure -d 1985-01-01 --is_new_patient_representation -iv
|
|
97
|
+
```
|
|
98
|
+
### 3. Generate hf readmission prediction task
|
|
99
|
+
If you don't have your own OMOP instance, we have provided a sample of patient sequence data generated using Synthea
|
|
100
|
+
at `sample/hf_readmissioon` in the repo
|
|
101
|
+
|
|
102
|
+
```console
|
|
103
|
+
PYTHONPATH=./:$PYTHONPATH spark-submit spark_apps/prediction_cohorts/hf_readmission.py -c hf_readmission -i ~/Documents/omop_test/ -o ~/Documents/omop_test/cehr-bert -dl 1985-01-01 -du 2020-12-31 -l 18 -u 100 -ow 360 -ps 0 -pw 30 --is_new_patient_representation
|
|
104
|
+
```
|
|
105
|
+
|
|
106
|
+
## Contact us
|
|
107
|
+
If you have any questions, feel free to contact us at CEHR-BERT@lists.cumc.columbia.edu
|
|
108
|
+
|
|
109
|
+
## Citation
|
|
110
|
+
Please acknowledge the following work in papers
|
|
111
|
+
|
|
112
|
+
Chao Pang, Xinzhuo Jiang, Krishna S. Kalluri, Matthew Spotnitz, RuiJun Chen, Adler
|
|
113
|
+
Perotte, and Karthik Natarajan. "Cehr-bert: Incorporating temporal information from
|
|
114
|
+
structured ehr data to improve prediction tasks." In Proceedings of Machine Learning for
|
|
115
|
+
Health, volume 158 of Proceedings of Machine Learning Research, pages 239–260. PMLR,
|
|
116
|
+
04 Dec 2021.
|
|
@@ -0,0 +1,88 @@
|
|
|
1
|
+
# cehrbert_data
|
|
2
|
+
|
|
3
|
+
cehrbert_data is the ETL tool that generates the pretraining and finetuning datasets for CEHRbERT, which is a large language model developed for the structured EHR data, the work has been published
|
|
4
|
+
at https://proceedings.mlr.press/v158/pang21a.html.
|
|
5
|
+
|
|
6
|
+
## Patient Representation
|
|
7
|
+
For each patient, all medical codes were aggregated and constructed into a sequence chronologically.
|
|
8
|
+
In order to incorporate temporal information, we inserted an artificial time token (ATT) between two neighboring visits
|
|
9
|
+
based on their time interval.
|
|
10
|
+
The following logic was used for creating ATTs based on the following time intervals between visits, if less than 28
|
|
11
|
+
days, ATTs take on the form of $W_n$ where n represents the week number ranging from 0-3 (e.g. $W_1$); 2) if between 28
|
|
12
|
+
days and 365 days, ATTs are in the form of **$M_n$** where n represents the month number ranging from 1-11 e.g $M_{11}$;
|
|
13
|
+
|
|
14
|
+
3) beyond 365 days then a **LT** (Long Term) token is inserted. In addition, we added two more special tokens — **VS**
|
|
15
|
+
and **VE** to represent the start and the end of a visit to explicitly define the visit segment, where all the
|
|
16
|
+
concepts
|
|
17
|
+
associated with the visit are subsumed by **VS** and **VE**.
|
|
18
|
+
|
|
19
|
+

|
|
20
|
+
|
|
21
|
+
## Pre-requisite
|
|
22
|
+
The project is built in python 3.10, and project dependency needs to be installed
|
|
23
|
+
|
|
24
|
+
Create a new Python virtual environment
|
|
25
|
+
|
|
26
|
+
```console
|
|
27
|
+
python3.10 -m venv .venv;
|
|
28
|
+
source .venv/bin/activate;
|
|
29
|
+
```
|
|
30
|
+
|
|
31
|
+
Build the project
|
|
32
|
+
|
|
33
|
+
```console
|
|
34
|
+
pip install -e .
|
|
35
|
+
```
|
|
36
|
+
|
|
37
|
+
Download [jtds-1.3.1.jar](jtds-1.3.1.jar) into the spark jars folder in the python environment
|
|
38
|
+
```console
|
|
39
|
+
cp jtds-1.3.1.jar .venv/lib/python3.10/site-packages/pyspark/jars/
|
|
40
|
+
```
|
|
41
|
+
## Instructions for Use
|
|
42
|
+
|
|
43
|
+
### 1. Download OMOP tables as parquet files
|
|
44
|
+
|
|
45
|
+
We created a spark app to download OMOP tables from SQL Server as parquet files. You need adjust the properties
|
|
46
|
+
in `db_properties.ini` to match with your database setup.
|
|
47
|
+
|
|
48
|
+
```console
|
|
49
|
+
PYTHONPATH=./: spark-submit tools/download_omop_tables.py -c db_properties.ini -tc person visit_occurrence condition_occurrence procedure_occurrence drug_exposure measurement observation_period concept concept_relationship concept_ancestor -o ~/Documents/omop_test/
|
|
50
|
+
```
|
|
51
|
+
|
|
52
|
+
We have prepared a synthea dataset with 1M patients for you to test, you could download it
|
|
53
|
+
at [omop_synthea.tar.gz](https://drive.google.com/file/d/1k7-cZACaDNw8A1JRI37mfMAhEErxKaQJ/view?usp=share_link)
|
|
54
|
+
|
|
55
|
+
```console
|
|
56
|
+
tar -xvf omop_synthea.tar ~/Document/omop_test/
|
|
57
|
+
```
|
|
58
|
+
|
|
59
|
+
### 2. Generate training data for CEHR-BERT
|
|
60
|
+
We order the patient events in chronological order and put all data points in a sequence. We insert artificial tokens
|
|
61
|
+
VS (visit start) and VE (visit end) to the start and the end of the visit. In addition, we insert artificial time
|
|
62
|
+
tokens (ATT) between visits to indicate the time interval between visits. This approach allows us to apply BERT to
|
|
63
|
+
structured EHR as-is.
|
|
64
|
+
The sequence can be seen conceptually as [VS] [V1] [VE] [ATT] [VS] [V2] [VE], where [V1] and [V2] represent a list of
|
|
65
|
+
concepts associated with those visits.
|
|
66
|
+
|
|
67
|
+
```console
|
|
68
|
+
PYTHONPATH=./: spark-submit spark_apps/generate_training_data.py -i ~/Documents/omop_test/ -o ~/Documents/omop_test/cehr-bert -tc condition_occurrence procedure_occurrence drug_exposure -d 1985-01-01 --is_new_patient_representation -iv
|
|
69
|
+
```
|
|
70
|
+
### 3. Generate hf readmission prediction task
|
|
71
|
+
If you don't have your own OMOP instance, we have provided a sample of patient sequence data generated using Synthea
|
|
72
|
+
at `sample/hf_readmissioon` in the repo
|
|
73
|
+
|
|
74
|
+
```console
|
|
75
|
+
PYTHONPATH=./:$PYTHONPATH spark-submit spark_apps/prediction_cohorts/hf_readmission.py -c hf_readmission -i ~/Documents/omop_test/ -o ~/Documents/omop_test/cehr-bert -dl 1985-01-01 -du 2020-12-31 -l 18 -u 100 -ow 360 -ps 0 -pw 30 --is_new_patient_representation
|
|
76
|
+
```
|
|
77
|
+
|
|
78
|
+
## Contact us
|
|
79
|
+
If you have any questions, feel free to contact us at CEHR-BERT@lists.cumc.columbia.edu
|
|
80
|
+
|
|
81
|
+
## Citation
|
|
82
|
+
Please acknowledge the following work in papers
|
|
83
|
+
|
|
84
|
+
Chao Pang, Xinzhuo Jiang, Krishna S. Kalluri, Matthew Spotnitz, RuiJun Chen, Adler
|
|
85
|
+
Perotte, and Karthik Natarajan. "Cehr-bert: Incorporating temporal information from
|
|
86
|
+
structured ehr data to improve prediction tasks." In Proceedings of Machine Learning for
|
|
87
|
+
Health, volume 158 of Proceedings of Machine Learning Research, pages 239–260. PMLR,
|
|
88
|
+
04 Dec 2021.
|
|
@@ -0,0 +1,54 @@
|
|
|
1
|
+
[build-system]
|
|
2
|
+
requires = ["setuptools", "wheel", "setuptools_scm"]
|
|
3
|
+
build-backend = "setuptools.build_meta"
|
|
4
|
+
|
|
5
|
+
[project]
|
|
6
|
+
name = "cehrbert_data"
|
|
7
|
+
dynamic = ["version"]
|
|
8
|
+
authors = [
|
|
9
|
+
{ name = "Chao Pang", email = "chaopang229@gmail.com" },
|
|
10
|
+
{ name = "Xinzhuo Jiang", email = "xj2193@cumc.columbia.edu" },
|
|
11
|
+
{ name = "Krishna Kalluri", email = "kk3326@cumc.columbia.edu" },
|
|
12
|
+
{ name = "Nishanth Parameshwar Pavinkurve", email = "np2689@cumc.columbia.edu" },
|
|
13
|
+
{ name = "Karthik Natarajan", email = "kn2174@cumc.columbia.edu" }
|
|
14
|
+
]
|
|
15
|
+
description = "The Spark ETL tools for generating the CEHR-BERT and CEHR-GPT pre-training and finetuning data"
|
|
16
|
+
readme = "README.md"
|
|
17
|
+
license = { text = "MIT License" }
|
|
18
|
+
requires-python = ">=3.10.0"
|
|
19
|
+
|
|
20
|
+
classifiers = [
|
|
21
|
+
"Development Status :: 5 - Production/Stable",
|
|
22
|
+
"Intended Audience :: Developers",
|
|
23
|
+
"Intended Audience :: Science/Research",
|
|
24
|
+
"License :: OSI Approved :: MIT License",
|
|
25
|
+
"Programming Language :: Python :: 3"
|
|
26
|
+
]
|
|
27
|
+
|
|
28
|
+
dependencies = [
|
|
29
|
+
"numpy==1.24.3",
|
|
30
|
+
"packaging==23.2",
|
|
31
|
+
"pandas==2.2.0",
|
|
32
|
+
"pyspark==3.1.2"
|
|
33
|
+
]
|
|
34
|
+
|
|
35
|
+
[tool.setuptools_scm]
|
|
36
|
+
|
|
37
|
+
[project.urls]
|
|
38
|
+
Homepage = "https://github.com/knatarajan-lab/cehrbert_data"
|
|
39
|
+
|
|
40
|
+
[project.optional-dependencies]
|
|
41
|
+
dev = [
|
|
42
|
+
"pre-commit", "pytest", "pytest-cov", "pytest-subtests", "rootutils", "hypothesis", "black"
|
|
43
|
+
]
|
|
44
|
+
|
|
45
|
+
[tool.isort]
|
|
46
|
+
multi_line_output = 3
|
|
47
|
+
include_trailing_comma = true
|
|
48
|
+
force_grid_wrap = 0
|
|
49
|
+
use_parentheses = true
|
|
50
|
+
ensure_newline_before_comments = true
|
|
51
|
+
line_length = 120
|
|
52
|
+
|
|
53
|
+
[tool.black]
|
|
54
|
+
line_length = 120
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
Binary file
|
|
File without changes
|
|
Binary file
|
|
File without changes
|
|
File without changes
|
|
File without changes
|