cachemaxxing 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- cachemaxxing-0.1.0/LICENSE +21 -0
- cachemaxxing-0.1.0/PKG-INFO +84 -0
- cachemaxxing-0.1.0/README.md +52 -0
- cachemaxxing-0.1.0/pyproject.toml +91 -0
- cachemaxxing-0.1.0/pyproject.toml.orig +66 -0
- cachemaxxing-0.1.0/src/cachemaxxing/__init__.py +23 -0
- cachemaxxing-0.1.0/src/cachemaxxing/canon.py +42 -0
- cachemaxxing-0.1.0/src/cachemaxxing/cli.py +73 -0
- cachemaxxing-0.1.0/src/cachemaxxing/diff.py +127 -0
- cachemaxxing-0.1.0/src/cachemaxxing/economics.py +51 -0
- cachemaxxing-0.1.0/src/cachemaxxing/facts.py +114 -0
- cachemaxxing-0.1.0/src/cachemaxxing/gemini.py +84 -0
- cachemaxxing-0.1.0/src/cachemaxxing/prompt.py +295 -0
- cachemaxxing-0.1.0/src/cachemaxxing/py.typed +0 -0
- cachemaxxing-0.1.0/src/cachemaxxing/usage.py +139 -0
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Ashhad Ahsan
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
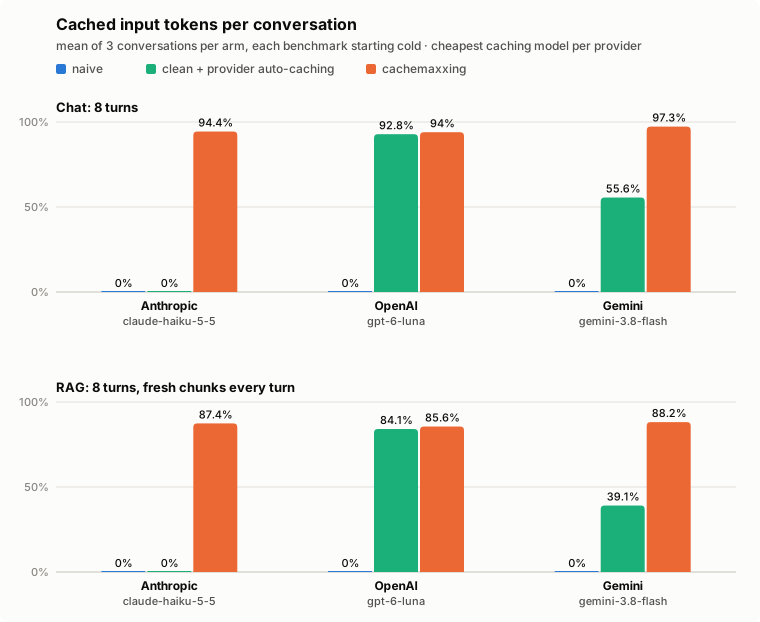
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,84 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: cachemaxxing
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Stop paying full price for the same tokens: measure, diagnose and fix prompt-cache misses on Anthropic, OpenAI, Gemini and LiteLLM.
|
|
5
|
+
Keywords: llm,prompt-caching,anthropic,openai,gemini,litellm,cost
|
|
6
|
+
Author: Ashhad Ahsan
|
|
7
|
+
Author-email: Ashhad Ahsan <ashhadahsan@gmail.com>
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Classifier: Development Status :: 3 - Alpha
|
|
11
|
+
Classifier: Intended Audience :: Developers
|
|
12
|
+
Classifier: Programming Language :: Python :: 3 :: Only
|
|
13
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
14
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
15
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.14
|
|
17
|
+
Classifier: Programming Language :: Python :: 3.15
|
|
18
|
+
Classifier: Typing :: Typed
|
|
19
|
+
Requires-Dist: anthropic>=2.3 ; extra == 'anthropic'
|
|
20
|
+
Requires-Dist: google-genai>=2.34 ; extra == 'gemini'
|
|
21
|
+
Requires-Dist: litellm>=1.106 ; extra == 'litellm'
|
|
22
|
+
Requires-Dist: openai>=3.41 ; extra == 'openai'
|
|
23
|
+
Requires-Python: >=3.11
|
|
24
|
+
Project-URL: Homepage, https://ashhadahsan.github.io/cachemaxxing/
|
|
25
|
+
Project-URL: Source, https://github.com/ashhadahsan/cachemaxxing
|
|
26
|
+
Project-URL: Changelog, https://github.com/ashhadahsan/cachemaxxing/blob/main/CHANGELOG.md
|
|
27
|
+
Provides-Extra: anthropic
|
|
28
|
+
Provides-Extra: gemini
|
|
29
|
+
Provides-Extra: litellm
|
|
30
|
+
Provides-Extra: openai
|
|
31
|
+
Description-Content-Type: text/markdown
|
|
32
|
+
|
|
33
|
+
# cachemaxxing
|
|
34
|
+
|
|
35
|
+
[](https://pypi.org/project/cachemaxxing/)
|
|
36
|
+
[](https://pypi.org/project/cachemaxxing/)
|
|
37
|
+
[](https://github.com/ashhadahsan/cachemaxxing/actions/workflows/ci.yml)
|
|
38
|
+
[](https://github.com/ashhadahsan/cachemaxxing/blob/main/LICENSE)
|
|
39
|
+
|
|
40
|
+
**Stop paying full price for the same tokens.**
|
|
41
|
+
|
|
42
|
+
Anthropic, OpenAI and Gemini bill a repeated prompt prefix at a fraction of the input price, but only when the bytes really repeat. cachemaxxing finds where they don't, tells you what it costs, and lays your prompts out so they do.
|
|
43
|
+
|
|
44
|
+
- **Measure.** `usage()` normalizes every provider's usage, and `cachemaxxing report` gives hit rate and $ per call site.
|
|
45
|
+
- **Diagnose.** `cachemaxxing diff` shows the first byte where two requests diverge, and why.
|
|
46
|
+
- **Fix.** `Prompt` orders segments from most to least stable and places each provider's cache markers.
|
|
47
|
+
|
|
48
|
+
```python
|
|
49
|
+
from cachemaxxing import Prompt, usage
|
|
50
|
+
|
|
51
|
+
p = Prompt(call_site="support.answer")
|
|
52
|
+
p.tools(TOOLS).system(SYSTEM).context(DOCS).history(messages).user(question)
|
|
53
|
+
|
|
54
|
+
resp = client.messages.create(max_tokens=1024, **p.anthropic("claude-haiku-5-5"))
|
|
55
|
+
|
|
56
|
+
u = usage(resp)
|
|
57
|
+
print(f"{u.hit_rate:.0%} of input from cache, ~${u.est_cost or 0:.4f}")
|
|
58
|
+
```
|
|
59
|
+
|
|
60
|
+
A full multi-turn RAG chat lives in [`examples/rag_chat.py`](examples/rag_chat.py).
|
|
61
|
+
The API works the same with `p.openai(...)`, `p.openai_chat(...)`, `p.gemini(...)` and `p.litellm(...)`. It is a thin library, not a proxy, and has zero runtime dependencies.
|
|
62
|
+
|
|
63
|
+
## Benchmark
|
|
64
|
+
|
|
65
|
+
|
|
66
|
+
|
|
67
|
+
| Provider | Model | Cached input | $ per conversation | Saving |
|
|
68
|
+
|---|---|---|---|---|
|
|
69
|
+
| Anthropic | `claude-haiku-5-5` | 0.0% → **94.8%** | $0.0092 → $0.0017 | **82%** |
|
|
70
|
+
| OpenAI | `gpt-6-luna` | 0.0% → **93.1%** | $0.0070 → $0.0012 | **83%** |
|
|
71
|
+
| Gemini | `gemini-3.8-flash` | 0.0% → **97.5%** | $0.0484 → $0.0094 | **80%** |
|
|
72
|
+
|
|
73
|
+
The same 8-turn conversation, 3 customers per arm, starting from a cold cache, with costs estimated at list price. The naive arm has four common habits: a timestamp at the top of the prompt, tool order that varies, JSON key order that varies, and history re-rendered every turn. The Gemini row uses an explicit cache, creation and storage cost included; with implicit caching alone it reached 40.0%. Data: [`benchmarks/results/`](benchmarks/results/), 2026-10-30.
|
|
74
|
+
|
|
75
|
+
## Install
|
|
76
|
+
|
|
77
|
+
```console
|
|
78
|
+
pip install cachemaxxing # or: uv add cachemaxxing
|
|
79
|
+
pip install "cachemaxxing[anthropic]" # extras: anthropic, openai, gemini, litellm
|
|
80
|
+
```
|
|
81
|
+
|
|
82
|
+
**Docs:** https://ashhadahsan.github.io/cachemaxxing/ covers the quickstart, how caching works per provider, diagnosing a low hit rate, the API reference, and how it compares.
|
|
83
|
+
|
|
84
|
+
MIT licensed.
|
|
@@ -0,0 +1,52 @@
|
|
|
1
|
+
# cachemaxxing
|
|
2
|
+
|
|
3
|
+
[](https://pypi.org/project/cachemaxxing/)
|
|
4
|
+
[](https://pypi.org/project/cachemaxxing/)
|
|
5
|
+
[](https://github.com/ashhadahsan/cachemaxxing/actions/workflows/ci.yml)
|
|
6
|
+
[](https://github.com/ashhadahsan/cachemaxxing/blob/main/LICENSE)
|
|
7
|
+
|
|
8
|
+
**Stop paying full price for the same tokens.**
|
|
9
|
+
|
|
10
|
+
Anthropic, OpenAI and Gemini bill a repeated prompt prefix at a fraction of the input price, but only when the bytes really repeat. cachemaxxing finds where they don't, tells you what it costs, and lays your prompts out so they do.
|
|
11
|
+
|
|
12
|
+
- **Measure.** `usage()` normalizes every provider's usage, and `cachemaxxing report` gives hit rate and $ per call site.
|
|
13
|
+
- **Diagnose.** `cachemaxxing diff` shows the first byte where two requests diverge, and why.
|
|
14
|
+
- **Fix.** `Prompt` orders segments from most to least stable and places each provider's cache markers.
|
|
15
|
+
|
|
16
|
+
```python
|
|
17
|
+
from cachemaxxing import Prompt, usage
|
|
18
|
+
|
|
19
|
+
p = Prompt(call_site="support.answer")
|
|
20
|
+
p.tools(TOOLS).system(SYSTEM).context(DOCS).history(messages).user(question)
|
|
21
|
+
|
|
22
|
+
resp = client.messages.create(max_tokens=1024, **p.anthropic("claude-haiku-5-5"))
|
|
23
|
+
|
|
24
|
+
u = usage(resp)
|
|
25
|
+
print(f"{u.hit_rate:.0%} of input from cache, ~${u.est_cost or 0:.4f}")
|
|
26
|
+
```
|
|
27
|
+
|
|
28
|
+
A full multi-turn RAG chat lives in [`examples/rag_chat.py`](examples/rag_chat.py).
|
|
29
|
+
The API works the same with `p.openai(...)`, `p.openai_chat(...)`, `p.gemini(...)` and `p.litellm(...)`. It is a thin library, not a proxy, and has zero runtime dependencies.
|
|
30
|
+
|
|
31
|
+
## Benchmark
|
|
32
|
+
|
|
33
|
+

|
|
34
|
+
|
|
35
|
+
| Provider | Model | Cached input | $ per conversation | Saving |
|
|
36
|
+
|---|---|---|---|---|
|
|
37
|
+
| Anthropic | `claude-haiku-5-5` | 0.0% → **94.8%** | $0.0092 → $0.0017 | **82%** |
|
|
38
|
+
| OpenAI | `gpt-6-luna` | 0.0% → **93.1%** | $0.0070 → $0.0012 | **83%** |
|
|
39
|
+
| Gemini | `gemini-3.8-flash` | 0.0% → **97.5%** | $0.0484 → $0.0094 | **80%** |
|
|
40
|
+
|
|
41
|
+
The same 8-turn conversation, 3 customers per arm, starting from a cold cache, with costs estimated at list price. The naive arm has four common habits: a timestamp at the top of the prompt, tool order that varies, JSON key order that varies, and history re-rendered every turn. The Gemini row uses an explicit cache, creation and storage cost included; with implicit caching alone it reached 40.0%. Data: [`benchmarks/results/`](benchmarks/results/), 2026-10-30.
|
|
42
|
+
|
|
43
|
+
## Install
|
|
44
|
+
|
|
45
|
+
```console
|
|
46
|
+
pip install cachemaxxing # or: uv add cachemaxxing
|
|
47
|
+
pip install "cachemaxxing[anthropic]" # extras: anthropic, openai, gemini, litellm
|
|
48
|
+
```
|
|
49
|
+
|
|
50
|
+
**Docs:** https://ashhadahsan.github.io/cachemaxxing/ covers the quickstart, how caching works per provider, diagnosing a low hit rate, the API reference, and how it compares.
|
|
51
|
+
|
|
52
|
+
MIT licensed.
|
|
@@ -0,0 +1,91 @@
|
|
|
1
|
+
[project]
|
|
2
|
+
name = "cachemaxxing"
|
|
3
|
+
version = "0.1.0"
|
|
4
|
+
description = "Stop paying full price for the same tokens: measure, diagnose and fix prompt-cache misses on Anthropic, OpenAI, Gemini and LiteLLM."
|
|
5
|
+
readme = "README.md"
|
|
6
|
+
license = "MIT"
|
|
7
|
+
license-files = ["LICENSE"]
|
|
8
|
+
requires-python = ">=3.11"
|
|
9
|
+
dependencies = []
|
|
10
|
+
keywords = [
|
|
11
|
+
"llm",
|
|
12
|
+
"prompt-caching",
|
|
13
|
+
"anthropic",
|
|
14
|
+
"openai",
|
|
15
|
+
"gemini",
|
|
16
|
+
"litellm",
|
|
17
|
+
"cost",
|
|
18
|
+
]
|
|
19
|
+
classifiers = [
|
|
20
|
+
"Development Status :: 3 - Alpha",
|
|
21
|
+
"Intended Audience :: Developers",
|
|
22
|
+
"Programming Language :: Python :: 3 :: Only",
|
|
23
|
+
"Programming Language :: Python :: 3.11",
|
|
24
|
+
"Programming Language :: Python :: 3.12",
|
|
25
|
+
"Programming Language :: Python :: 3.13",
|
|
26
|
+
"Programming Language :: Python :: 3.14",
|
|
27
|
+
"Programming Language :: Python :: 3.15",
|
|
28
|
+
"Typing :: Typed",
|
|
29
|
+
]
|
|
30
|
+
|
|
31
|
+
[[project.authors]]
|
|
32
|
+
name = "Ashhad Ahsan"
|
|
33
|
+
email = "ashhadahsan@gmail.com"
|
|
34
|
+
|
|
35
|
+
[project.optional-dependencies]
|
|
36
|
+
anthropic = ["anthropic>=2.3"]
|
|
37
|
+
openai = ["openai>=3.41"]
|
|
38
|
+
gemini = ["google-genai>=2.34"]
|
|
39
|
+
litellm = ["litellm>=1.106"]
|
|
40
|
+
|
|
41
|
+
[project.urls]
|
|
42
|
+
Homepage = "https://ashhadahsan.github.io/cachemaxxing/"
|
|
43
|
+
Source = "https://github.com/ashhadahsan/cachemaxxing"
|
|
44
|
+
Changelog = "https://github.com/ashhadahsan/cachemaxxing/blob/main/CHANGELOG.md"
|
|
45
|
+
|
|
46
|
+
[project.scripts]
|
|
47
|
+
cachemaxxing = "cachemaxxing.cli:main"
|
|
48
|
+
|
|
49
|
+
[build-system]
|
|
50
|
+
requires = ["uv_build>=0.13.6,<0.14"]
|
|
51
|
+
build-backend = "uv_build"
|
|
52
|
+
|
|
53
|
+
[dependency-groups]
|
|
54
|
+
dev = [
|
|
55
|
+
"pytest>=9.2",
|
|
56
|
+
"ruff>=0.17.3",
|
|
57
|
+
"mypy>=2.4.1",
|
|
58
|
+
"anthropic>=2.3",
|
|
59
|
+
"openai>=3.41",
|
|
60
|
+
"google-genai>=2.34",
|
|
61
|
+
"httpx>=0.28",
|
|
62
|
+
]
|
|
63
|
+
docs = [
|
|
64
|
+
"mkdocstrings-python>=2.0.10",
|
|
65
|
+
"zensical==0.0.73",
|
|
66
|
+
]
|
|
67
|
+
|
|
68
|
+
[tool.ruff]
|
|
69
|
+
line-length = 120
|
|
70
|
+
|
|
71
|
+
[tool.ruff.format]
|
|
72
|
+
exclude = ["docs/*.md"]
|
|
73
|
+
|
|
74
|
+
[tool.ruff.lint]
|
|
75
|
+
select = [
|
|
76
|
+
"E",
|
|
77
|
+
"F",
|
|
78
|
+
"I",
|
|
79
|
+
"UP",
|
|
80
|
+
"B",
|
|
81
|
+
]
|
|
82
|
+
|
|
83
|
+
[tool.ruff.lint.per-file-ignores]
|
|
84
|
+
"benchmarks/chart.py" = ["E501"]
|
|
85
|
+
|
|
86
|
+
[tool.mypy]
|
|
87
|
+
strict = true
|
|
88
|
+
files = ["src"]
|
|
89
|
+
|
|
90
|
+
[tool.pytest.ini_options]
|
|
91
|
+
testpaths = ["tests"]
|
|
@@ -0,0 +1,66 @@
|
|
|
1
|
+
[project]
|
|
2
|
+
name = "cachemaxxing"
|
|
3
|
+
version = "0.1.0"
|
|
4
|
+
description = "Stop paying full price for the same tokens: measure, diagnose and fix prompt-cache misses on Anthropic, OpenAI, Gemini and LiteLLM."
|
|
5
|
+
readme = "README.md"
|
|
6
|
+
license = "MIT"
|
|
7
|
+
license-files = ["LICENSE"]
|
|
8
|
+
authors = [{ name = "Ashhad Ahsan", email = "ashhadahsan@gmail.com" }]
|
|
9
|
+
requires-python = ">=3.11"
|
|
10
|
+
dependencies = []
|
|
11
|
+
keywords = ["llm", "prompt-caching", "anthropic", "openai", "gemini", "litellm", "cost"]
|
|
12
|
+
classifiers = [
|
|
13
|
+
"Development Status :: 3 - Alpha",
|
|
14
|
+
"Intended Audience :: Developers",
|
|
15
|
+
"Programming Language :: Python :: 3 :: Only",
|
|
16
|
+
"Programming Language :: Python :: 3.11",
|
|
17
|
+
"Programming Language :: Python :: 3.12",
|
|
18
|
+
"Programming Language :: Python :: 3.13",
|
|
19
|
+
"Programming Language :: Python :: 3.14",
|
|
20
|
+
"Programming Language :: Python :: 3.15",
|
|
21
|
+
"Typing :: Typed",
|
|
22
|
+
]
|
|
23
|
+
|
|
24
|
+
[project.optional-dependencies]
|
|
25
|
+
anthropic = ["anthropic>=2.3"]
|
|
26
|
+
openai = ["openai>=3.41"]
|
|
27
|
+
gemini = ["google-genai>=2.34"]
|
|
28
|
+
litellm = ["litellm>=1.106"] # never 1.82.7/1.82.8 (compromised 2026-03-24)
|
|
29
|
+
|
|
30
|
+
[project.urls]
|
|
31
|
+
Homepage = "https://ashhadahsan.github.io/cachemaxxing/"
|
|
32
|
+
Source = "https://github.com/ashhadahsan/cachemaxxing"
|
|
33
|
+
Changelog = "https://github.com/ashhadahsan/cachemaxxing/blob/main/CHANGELOG.md"
|
|
34
|
+
|
|
35
|
+
[project.scripts]
|
|
36
|
+
cachemaxxing = "cachemaxxing.cli:main"
|
|
37
|
+
|
|
38
|
+
[build-system]
|
|
39
|
+
requires = ["uv_build>=0.13.6,<0.14"]
|
|
40
|
+
build-backend = "uv_build"
|
|
41
|
+
|
|
42
|
+
[dependency-groups]
|
|
43
|
+
dev = ["pytest>=9.2", "ruff>=0.17.3", "mypy>=2.4.1", "anthropic>=2.3", "openai>=3.41", "google-genai>=2.34", "httpx>=0.28"]
|
|
44
|
+
docs = [
|
|
45
|
+
"mkdocstrings-python>=2.0.10",
|
|
46
|
+
"zensical==0.0.73",
|
|
47
|
+
]
|
|
48
|
+
|
|
49
|
+
[tool.ruff]
|
|
50
|
+
line-length = 120
|
|
51
|
+
|
|
52
|
+
[tool.ruff.format]
|
|
53
|
+
exclude = ["docs/*.md"] # hand-aligned examples and --8<-- snippet includes
|
|
54
|
+
|
|
55
|
+
[tool.ruff.lint]
|
|
56
|
+
select = ["E", "F", "I", "UP", "B"]
|
|
57
|
+
|
|
58
|
+
[tool.ruff.lint.per-file-ignores]
|
|
59
|
+
"benchmarks/chart.py" = ["E501"] # SVG markup lines
|
|
60
|
+
|
|
61
|
+
[tool.mypy]
|
|
62
|
+
strict = true
|
|
63
|
+
files = ["src"]
|
|
64
|
+
|
|
65
|
+
[tool.pytest.ini_options]
|
|
66
|
+
testpaths = ["tests"]
|
|
@@ -0,0 +1,23 @@
|
|
|
1
|
+
"""Stop paying full price for the same tokens."""
|
|
2
|
+
|
|
3
|
+
from .canon import canonical_json
|
|
4
|
+
from .diff import Divergence, diff
|
|
5
|
+
from .economics import Decision, should_cache
|
|
6
|
+
from .gemini import gemini_cache, gemini_cache_async
|
|
7
|
+
from .prompt import Prompt
|
|
8
|
+
from .usage import Stats, Usage, record, usage
|
|
9
|
+
|
|
10
|
+
__all__ = [
|
|
11
|
+
"Decision",
|
|
12
|
+
"Divergence",
|
|
13
|
+
"Prompt",
|
|
14
|
+
"Stats",
|
|
15
|
+
"Usage",
|
|
16
|
+
"canonical_json",
|
|
17
|
+
"diff",
|
|
18
|
+
"gemini_cache",
|
|
19
|
+
"gemini_cache_async",
|
|
20
|
+
"record",
|
|
21
|
+
"should_cache",
|
|
22
|
+
"usage",
|
|
23
|
+
]
|
|
@@ -0,0 +1,42 @@
|
|
|
1
|
+
"""Deterministic serialization helpers."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import json
|
|
6
|
+
from typing import Any
|
|
7
|
+
|
|
8
|
+
|
|
9
|
+
def canonical_json(obj: Any) -> str:
|
|
10
|
+
"""Same data, same bytes: sorted keys, fixed separators, non-ASCII kept."""
|
|
11
|
+
return json.dumps(obj, sort_keys=True, separators=(",", ":"), ensure_ascii=False)
|
|
12
|
+
|
|
13
|
+
|
|
14
|
+
def normalize_ws(text: str) -> str:
|
|
15
|
+
"""LF line endings, no trailing whitespace per line, no blank lines at either end."""
|
|
16
|
+
lines = text.replace("\r\n", "\n").replace("\r", "\n").split("\n")
|
|
17
|
+
return "\n".join(line.rstrip() for line in lines).strip("\n")
|
|
18
|
+
|
|
19
|
+
|
|
20
|
+
def plain(obj: Any) -> Any:
|
|
21
|
+
"""An SDK (pydantic) object as a plain dict; anything else unchanged."""
|
|
22
|
+
dump = getattr(obj, "model_dump", None)
|
|
23
|
+
return dump(mode="json", exclude_none=True) if callable(dump) else obj
|
|
24
|
+
|
|
25
|
+
|
|
26
|
+
def jsonable(obj: Any) -> Any:
|
|
27
|
+
"""`plain`, applied recursively; tuples become lists."""
|
|
28
|
+
obj = plain(obj)
|
|
29
|
+
if isinstance(obj, dict):
|
|
30
|
+
return {k: jsonable(v) for k, v in obj.items()}
|
|
31
|
+
if isinstance(obj, list | tuple):
|
|
32
|
+
return [jsonable(v) for v in obj]
|
|
33
|
+
return obj
|
|
34
|
+
|
|
35
|
+
|
|
36
|
+
def tool_name(tool: Any) -> str:
|
|
37
|
+
"""Name of an Anthropic, OpenAI (Responses or Chat) or Gemini function tool; '' if none."""
|
|
38
|
+
t = plain(tool)
|
|
39
|
+
if not isinstance(t, dict):
|
|
40
|
+
return ""
|
|
41
|
+
fn = t.get("function")
|
|
42
|
+
return str(fn.get("name", "") if isinstance(fn, dict) else t.get("name", ""))
|
|
@@ -0,0 +1,73 @@
|
|
|
1
|
+
"""cachemaxxing diff A.json B.json | cachemaxxing report LOG.jsonl [--min-hit-rate X]"""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import argparse
|
|
6
|
+
import json
|
|
7
|
+
import re
|
|
8
|
+
import sys
|
|
9
|
+
from collections import Counter
|
|
10
|
+
from pathlib import Path
|
|
11
|
+
from typing import Any
|
|
12
|
+
|
|
13
|
+
from .diff import diff
|
|
14
|
+
from .usage import Stats, usage
|
|
15
|
+
|
|
16
|
+
NO_READ = "prefix ok, no cache read (TTL expired, below minimum, or routing)"
|
|
17
|
+
|
|
18
|
+
|
|
19
|
+
def _load(path: str) -> Any:
|
|
20
|
+
return json.loads(Path(path).read_text(encoding="utf-8"))
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
def _report(log: str, min_hit_rate: float | None) -> int:
|
|
24
|
+
stats = Stats()
|
|
25
|
+
last: dict[str, Any] = {}
|
|
26
|
+
drift: dict[str, Counter[str]] = {}
|
|
27
|
+
for line in Path(log).read_text(encoding="utf-8").splitlines():
|
|
28
|
+
if not line.strip():
|
|
29
|
+
continue
|
|
30
|
+
rec = json.loads(line)
|
|
31
|
+
site, u = rec.get("call_site", "default"), usage(rec["response"])
|
|
32
|
+
stats.add(site, u)
|
|
33
|
+
if site in last:
|
|
34
|
+
div = diff(last[site], rec["request"])
|
|
35
|
+
if (div is None or div.hint == "last turn") and u.cache_read == 0:
|
|
36
|
+
drift.setdefault(site, Counter())[NO_READ] += 1
|
|
37
|
+
elif div is not None and div.hint != "last turn":
|
|
38
|
+
path = re.sub(r"\[\d+\]", "[]", div.path) # group growing conversations together
|
|
39
|
+
drift.setdefault(site, Counter())[f"{path} ({div.hint or '?'})"] += 1
|
|
40
|
+
last[site] = rec["request"]
|
|
41
|
+
if not stats.totals:
|
|
42
|
+
raise ValueError(f"no records in {log}")
|
|
43
|
+
notes = {site: f"{key} x{n}" for site, c in drift.items() for key, n in c.most_common(1)}
|
|
44
|
+
print(stats.table(notes))
|
|
45
|
+
low = sorted(s for s, u in stats.totals.items() if min_hit_rate is not None and u.hit_rate < min_hit_rate)
|
|
46
|
+
for s in low:
|
|
47
|
+
print(f"{s}: hit rate {stats.totals[s].hit_rate:.1%} is below --min-hit-rate {min_hit_rate}", file=sys.stderr)
|
|
48
|
+
return 1 if low else 0
|
|
49
|
+
|
|
50
|
+
|
|
51
|
+
def main(argv: list[str] | None = None) -> int:
|
|
52
|
+
ap = argparse.ArgumentParser(prog="cachemaxxing", description="Find and price prompt-cache misses.")
|
|
53
|
+
sub = ap.add_subparsers(dest="cmd", required=True)
|
|
54
|
+
d = sub.add_parser("diff", help="first point where request B stops repeating request A")
|
|
55
|
+
d.add_argument("a")
|
|
56
|
+
d.add_argument("b")
|
|
57
|
+
r = sub.add_parser("report", help="hit rate, $ and top drift per call site from a JSONL log")
|
|
58
|
+
r.add_argument("log")
|
|
59
|
+
r.add_argument("--min-hit-rate", type=float, help="exit 1 if any call site is below this (0-1)")
|
|
60
|
+
args = ap.parse_args(argv)
|
|
61
|
+
try:
|
|
62
|
+
if args.cmd == "diff":
|
|
63
|
+
div = diff(_load(args.a), _load(args.b))
|
|
64
|
+
print(div if div else "no divergence: B repeats all of A")
|
|
65
|
+
return 1 if div else 0
|
|
66
|
+
return _report(args.log, args.min_hit_rate)
|
|
67
|
+
except (OSError, ValueError, KeyError) as e:
|
|
68
|
+
print(f"cachemaxxing: {e}", file=sys.stderr)
|
|
69
|
+
return 2
|
|
70
|
+
|
|
71
|
+
|
|
72
|
+
if __name__ == "__main__":
|
|
73
|
+
raise SystemExit(main())
|
|
@@ -0,0 +1,127 @@
|
|
|
1
|
+
"""Find where request b stops repeating request a's cacheable prefix."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import json
|
|
6
|
+
import os
|
|
7
|
+
import re
|
|
8
|
+
from collections.abc import Iterator
|
|
9
|
+
from dataclasses import dataclass
|
|
10
|
+
from typing import Any
|
|
11
|
+
|
|
12
|
+
from .canon import jsonable
|
|
13
|
+
|
|
14
|
+
_ORDER = ("model", "tools", "system", "instructions", "config", "messages", "input", "contents")
|
|
15
|
+
_GEMINI_PREFIX = ("cached_content", "system_instruction", "tools", "tool_config")
|
|
16
|
+
_LISTS = ("messages", "input", "contents")
|
|
17
|
+
_MARKERS = {"cache_control", "prompt_cache_breakpoint"}
|
|
18
|
+
_TEXT_TYPES = {"text", "input_text", "output_text"}
|
|
19
|
+
_TOOL_NAME = re.compile(r"(?:config\.)?tools\[\d+\](?:\.function|\.function_declarations\[\d+\])?\.name")
|
|
20
|
+
_HINTS = (
|
|
21
|
+
("uuid", re.compile(r"[0-9a-fA-F]{8}-(?:[0-9a-fA-F]{4}-){3}[0-9a-fA-F]{12}")),
|
|
22
|
+
("timestamp", re.compile(r"\d{4}-\d\d-\d\d[T ]\d\d:\d\d|\b\d{1,2}:\d\d:\d\d\b|\b1\d{9}(?:\d{3})?\b")),
|
|
23
|
+
("hex id", re.compile(r"\b[0-9a-f]{16,}\b")),
|
|
24
|
+
)
|
|
25
|
+
|
|
26
|
+
|
|
27
|
+
@dataclass(frozen=True)
|
|
28
|
+
class Divergence:
|
|
29
|
+
path: str # where the two requests differ, e.g. "system[0].text"
|
|
30
|
+
offset: int # characters into that value
|
|
31
|
+
a: str # text around the divergence in request a
|
|
32
|
+
b: str # ... and in request b
|
|
33
|
+
hint: str | None # model, tool order, key order, removed, last turn, whitespace, uuid, timestamp, hex id
|
|
34
|
+
prefix_chars: int # identical characters before it (about 4 per token)
|
|
35
|
+
|
|
36
|
+
def __str__(self) -> str:
|
|
37
|
+
why = f" ({self.hint})" if self.hint else ""
|
|
38
|
+
return (
|
|
39
|
+
f"diverges at {self.path} char {self.offset}{why}, after ~{self.prefix_chars // 4:,} matching tokens\n"
|
|
40
|
+
f" a: {self.a!r}\n b: {self.b!r}"
|
|
41
|
+
)
|
|
42
|
+
|
|
43
|
+
|
|
44
|
+
def _leaves(x: Any, path: str) -> Iterator[tuple[str, str]]:
|
|
45
|
+
if isinstance(x, dict):
|
|
46
|
+
if isinstance(x.get("content"), str): # "hi" renders like [{"type": "text", "text": "hi"}]
|
|
47
|
+
x = {**x, "content": [{"type": "text", "text": x["content"]}]}
|
|
48
|
+
for k, v in x.items():
|
|
49
|
+
if k not in _MARKERS and not (k == "type" and v in _TEXT_TYPES):
|
|
50
|
+
yield from _leaves(v, f"{path}.{k}")
|
|
51
|
+
elif isinstance(x, list):
|
|
52
|
+
for i, v in enumerate(x):
|
|
53
|
+
yield from _leaves(v, f"{path}[{i}]")
|
|
54
|
+
else:
|
|
55
|
+
yield path, x if isinstance(x, str) else json.dumps(x)
|
|
56
|
+
|
|
57
|
+
|
|
58
|
+
def _snake(key: str) -> str:
|
|
59
|
+
return re.sub(r"(?<!^)([A-Z])", r"_\1", key).lower()
|
|
60
|
+
|
|
61
|
+
|
|
62
|
+
def _request(r: Any) -> dict[str, Any]:
|
|
63
|
+
r = jsonable(r)
|
|
64
|
+
if not isinstance(r, dict):
|
|
65
|
+
raise ValueError("expected a request object (a JSON dict) or a record() line")
|
|
66
|
+
inner = r.get("request")
|
|
67
|
+
return inner if isinstance(inner, dict) else r
|
|
68
|
+
|
|
69
|
+
|
|
70
|
+
def _flat(req: dict[str, Any]) -> list[tuple[str, str]]:
|
|
71
|
+
out: list[tuple[str, str]] = []
|
|
72
|
+
for k in _ORDER:
|
|
73
|
+
if k in req:
|
|
74
|
+
v = req[k]
|
|
75
|
+
if k == "config" and isinstance(v, dict): # google-genai accepts camelCase keys too
|
|
76
|
+
snake = {_snake(key): x for key, x in v.items()}
|
|
77
|
+
v = {c: snake[c] for c in _GEMINI_PREFIX if c in snake}
|
|
78
|
+
if isinstance(v.get("system_instruction"), str):
|
|
79
|
+
v["system_instruction"] = {"parts": [{"text": v["system_instruction"]}]}
|
|
80
|
+
elif k == "system" and isinstance(v, str): # "S" renders like [{"type": "text", "text": "S"}]
|
|
81
|
+
v = [{"type": "text", "text": v}]
|
|
82
|
+
out += _leaves(v, k)
|
|
83
|
+
return out
|
|
84
|
+
|
|
85
|
+
|
|
86
|
+
def diff(a: Any, b: Any) -> Divergence | None:
|
|
87
|
+
"""First point where b stops repeating a's prompt; None when b repeats all of a.
|
|
88
|
+
Accepts request kwargs, SDK objects, or record() lines."""
|
|
89
|
+
ra, rb = _request(a), _request(b)
|
|
90
|
+
fa, fb = _flat(ra), _flat(rb)
|
|
91
|
+
seen = 0
|
|
92
|
+
for i, (pa, va) in enumerate(fa):
|
|
93
|
+
if i == len(fb):
|
|
94
|
+
return Divergence(pa, 0, va[:60], "", "removed", seen)
|
|
95
|
+
pb, vb = fb[i]
|
|
96
|
+
if pa != pb:
|
|
97
|
+
parent = pa.rsplit(".", 1)[0]
|
|
98
|
+
same = pb.rsplit(".", 1)[0] == parent and {x for x in fa if x[0].startswith(parent)} == {
|
|
99
|
+
x for x in fb if x[0].startswith(parent)
|
|
100
|
+
}
|
|
101
|
+
return Divergence(f"{pa} / {pb}", 0, va[:60], vb[:60], "key order" if same else None, seen)
|
|
102
|
+
if va != vb:
|
|
103
|
+
off = len(os.path.commonprefix([va, vb]))
|
|
104
|
+
lo = max(0, off - 30)
|
|
105
|
+
hint = _hint(pa, va, vb, off, fa, fb, ra)
|
|
106
|
+
return Divergence(pa, off, va[lo : off + 30], vb[lo : off + 30], hint, seen + off)
|
|
107
|
+
seen += len(va)
|
|
108
|
+
return None
|
|
109
|
+
|
|
110
|
+
|
|
111
|
+
def _hint(
|
|
112
|
+
path: str, va: str, vb: str, off: int, fa: list[tuple[str, str]], fb: list[tuple[str, str]], ra: dict[str, Any]
|
|
113
|
+
) -> str | None:
|
|
114
|
+
if path == "model":
|
|
115
|
+
return "model"
|
|
116
|
+
names_a = [v for p, v in fa if _TOOL_NAME.fullmatch(p)]
|
|
117
|
+
names_b = [v for p, v in fb if _TOOL_NAME.fullmatch(p)]
|
|
118
|
+
if "tools" in path.split("[")[0] and names_a != names_b and sorted(names_a) == sorted(names_b):
|
|
119
|
+
return "tool order"
|
|
120
|
+
for k in _LISTS:
|
|
121
|
+
items = ra.get(k)
|
|
122
|
+
if isinstance(items, list) and items and path.startswith(f"{k}[{len(items) - 1}]"):
|
|
123
|
+
return "last turn"
|
|
124
|
+
if va.split() == vb.split():
|
|
125
|
+
return "whitespace"
|
|
126
|
+
wa, wb = va[max(0, off - 40) : off + 40], vb[max(0, off - 40) : off + 40]
|
|
127
|
+
return next((name for name, rx in _HINTS if rx.search(wa) and rx.search(wb)), None)
|
|
@@ -0,0 +1,51 @@
|
|
|
1
|
+
"""Does explicit caching pay? Pure arithmetic over facts.MODELS."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import math
|
|
6
|
+
from dataclasses import dataclass
|
|
7
|
+
|
|
8
|
+
from . import facts
|
|
9
|
+
|
|
10
|
+
TTL_SECONDS = {"5m": 300, "1h": 3600, "30m": 1800, "12h": 43200}
|
|
11
|
+
|
|
12
|
+
|
|
13
|
+
@dataclass(frozen=True)
|
|
14
|
+
class Decision:
|
|
15
|
+
cache: bool
|
|
16
|
+
ttl: str | None # "5m"/"1h" (Anthropic), "30m"/"12h" (OpenAI), "<n>s" (Gemini explicit cache)
|
|
17
|
+
saving: float # expected USD saved versus not caching; negative means caching loses money
|
|
18
|
+
reason: str
|
|
19
|
+
|
|
20
|
+
|
|
21
|
+
def should_cache(
|
|
22
|
+
prefix_tokens: int, expected_reuses: int, provider: str, model: str, *, interval_s: float = 60.0
|
|
23
|
+
) -> Decision:
|
|
24
|
+
"""Whether caching a prefix of `prefix_tokens` pays when it is reused `expected_reuses` times,
|
|
25
|
+
`interval_s` seconds apart (start to start)."""
|
|
26
|
+
m = facts.find(model)
|
|
27
|
+
if m is None or m.provider != provider:
|
|
28
|
+
raise ValueError(f"unknown {provider} model {model!r}; add it to cachemaxxing.facts.MODELS")
|
|
29
|
+
if m.long_context and prefix_tokens > m.long_context[0]:
|
|
30
|
+
m = m.long_context[1]
|
|
31
|
+
if prefix_tokens < m.min_tokens:
|
|
32
|
+
return Decision(False, None, 0.0, f"{prefix_tokens} tokens is below the {m.min_tokens}-token minimum")
|
|
33
|
+
t, n = prefix_tokens / 1e6, expected_reuses
|
|
34
|
+
ttl: str | None
|
|
35
|
+
if provider == "gemini":
|
|
36
|
+
if m.storage_hour is None:
|
|
37
|
+
return Decision(False, None, 0.0, f"{model} has no explicit caching; implicit caching is automatic")
|
|
38
|
+
seconds = max(60, math.ceil(interval_s * n))
|
|
39
|
+
ttl, cost = f"{seconds}s", t * m.input + n * t * m.cache_read + t * m.storage_hour * seconds / 3600
|
|
40
|
+
elif not m.cache_write: # automatic caching without a write premium
|
|
41
|
+
ttl, cost = None, t * m.input + n * t * m.cache_read
|
|
42
|
+
else:
|
|
43
|
+
fits = [k for k in m.cache_write if TTL_SECONDS[k] >= interval_s]
|
|
44
|
+
if not fits:
|
|
45
|
+
return Decision(False, None, 0.0, f"reuses {interval_s:g}s apart outlive the longest TTL")
|
|
46
|
+
ttl = min(fits, key=TTL_SECONDS.__getitem__)
|
|
47
|
+
cost = t * m.cache_write[ttl] + n * t * m.cache_read
|
|
48
|
+
saving = (1 + n) * t * m.input - cost
|
|
49
|
+
if saving <= 0:
|
|
50
|
+
return Decision(False, None, saving, f"caching costs ${-saving:.6f} more than not caching")
|
|
51
|
+
return Decision(True, ttl, saving, f"saves ${saving:.6f} over {n} reuses")
|
|
@@ -0,0 +1,114 @@
|
|
|
1
|
+
"""Provider prompt-caching facts. Prices are USD per 1M tokens; every row links to its source.
|
|
2
|
+
|
|
3
|
+
Checked on VERIFIED. Add or correct models by editing MODELS (it is a plain dict)."""
|
|
4
|
+
|
|
5
|
+
from __future__ import annotations
|
|
6
|
+
|
|
7
|
+
from dataclasses import dataclass, field
|
|
8
|
+
|
|
9
|
+
VERIFIED = "2026-10-30"
|
|
10
|
+
|
|
11
|
+
|
|
12
|
+
@dataclass(frozen=True)
|
|
13
|
+
class Provider:
|
|
14
|
+
max_breakpoints: int | None # explicit markers per request; None = none (implicit caching)
|
|
15
|
+
ttls: tuple[str, ...] # shortest first
|
|
16
|
+
docs: str
|
|
17
|
+
|
|
18
|
+
|
|
19
|
+
@dataclass(frozen=True)
|
|
20
|
+
class Model:
|
|
21
|
+
provider: str
|
|
22
|
+
input: float
|
|
23
|
+
output: float
|
|
24
|
+
cache_read: float
|
|
25
|
+
cache_write: dict[str, float] = field(default_factory=dict) # TTL -> price, shortest first
|
|
26
|
+
min_tokens: int = 1024
|
|
27
|
+
storage_hour: float | None = None # Gemini explicit caches, per 1M tokens per hour
|
|
28
|
+
long_context: tuple[int, Model] | None = None # (prompt tokens above which, these prices)
|
|
29
|
+
source: str = ""
|
|
30
|
+
|
|
31
|
+
|
|
32
|
+
PROVIDERS = {
|
|
33
|
+
"anthropic": Provider(4, ("5m", "1h"), "https://platform.claude.com/docs/en/build-with-claude/prompt-caching"),
|
|
34
|
+
"openai": Provider(4, ("30m", "12h"), "https://developers.openai.com/api/docs/guides/prompt-caching"),
|
|
35
|
+
"gemini": Provider(None, (), "https://ai.google.dev/gemini-api/docs/caching"),
|
|
36
|
+
}
|
|
37
|
+
|
|
38
|
+
_A = "https://platform.claude.com/docs/en/about-claude/pricing"
|
|
39
|
+
_O = "https://developers.openai.com/api/docs/pricing"
|
|
40
|
+
_G = "https://ai.google.dev/gemini-api/docs/pricing"
|
|
41
|
+
|
|
42
|
+
MODELS: dict[str, Model] = {
|
|
43
|
+
"claude-haiku-5-5": Model(
|
|
44
|
+
"anthropic",
|
|
45
|
+
0.10,
|
|
46
|
+
0.50,
|
|
47
|
+
0.01,
|
|
48
|
+
{"5m": 0.125, "1h": 0.20},
|
|
49
|
+
512,
|
|
50
|
+
source=_A,
|
|
51
|
+
long_context=(100_000, Model("anthropic", 0.50, 2.50, 0.05, {"5m": 0.625, "1h": 1.00}, 512, source=_A)),
|
|
52
|
+
),
|
|
53
|
+
"claude-sonnet-5-5": Model("anthropic", 2.00, 10.00, 0.10, {"5m": 2.50, "1h": 4.00}, 512, source=_A),
|
|
54
|
+
"claude-opus-5-5": Model("anthropic", 4.00, 20.00, 0.20, {"5m": 5.00, "1h": 8.00}, 512, source=_A),
|
|
55
|
+
"claude-fable-5-1": Model("anthropic", 10.00, 50.00, 0.25, {"5m": 12.50, "1h": 20.00}, 512, source=_A),
|
|
56
|
+
"gpt-6-luna": Model("openai", 0.10, 0.50, 0.01, {"30m": 0.125, "12h": 0.25}, 1024, source=_O),
|
|
57
|
+
"gpt-6.1-sol": Model("openai", 2.00, 10.00, 0.10, {"30m": 2.50, "12h": 5.00}, 1024, source=_O),
|
|
58
|
+
"gpt-6-astra": Model("openai", 10.00, 50.00, 1.00, {"30m": 12.50, "12h": 25.00}, 1024, source=_O),
|
|
59
|
+
# Gemini caches implicitly; storage_hour marks explicit-cache support.
|
|
60
|
+
# gemini-3.8-flash prices double on 2027-01-01, gemini-4-argon's on 2026-12-01: patch releases then.
|
|
61
|
+
"gemini-3.8-flash": Model("gemini", 0.75, 3.75, 0.075, min_tokens=4096, storage_hour=0.50, source=_G),
|
|
62
|
+
"gemini-3.1-flash-lite": Model("gemini", 0.25, 1.50, 0.025, min_tokens=4096, storage_hour=1.00, source=_G),
|
|
63
|
+
"gemini-4-argon": Model("gemini", 2.00, 10.00, 0.10, min_tokens=4096, source=_G),
|
|
64
|
+
}
|
|
65
|
+
|
|
66
|
+
|
|
67
|
+
def find(model: str) -> Model | None:
|
|
68
|
+
"""Longest-prefix match on the id, ignoring 'provider/' and 'models/' prefixes and dated suffixes."""
|
|
69
|
+
name = model.rsplit("/", 1)[-1]
|
|
70
|
+
best = max((k for k in MODELS if name.startswith(k)), key=len, default=None)
|
|
71
|
+
return MODELS[best] if best else None
|
|
72
|
+
|
|
73
|
+
|
|
74
|
+
def provider_of(model: str) -> str:
|
|
75
|
+
"""'anthropic', 'openai', 'gemini' or 'other' for a model id, LiteLLM 'route/model' ids included."""
|
|
76
|
+
if (m := find(model)) is not None:
|
|
77
|
+
return m.provider
|
|
78
|
+
prefix, _, rest = model.partition("/")
|
|
79
|
+
if rest and prefix in PROVIDERS:
|
|
80
|
+
return prefix
|
|
81
|
+
name = rest or prefix
|
|
82
|
+
if "claude" in name:
|
|
83
|
+
return "anthropic"
|
|
84
|
+
if name.startswith("gemini"):
|
|
85
|
+
return "gemini"
|
|
86
|
+
if not rest and name.startswith(("gpt-", "o1", "o3", "o4")):
|
|
87
|
+
return "openai"
|
|
88
|
+
return "other"
|
|
89
|
+
|
|
90
|
+
|
|
91
|
+
def markdown() -> str:
|
|
92
|
+
"""The facts as Markdown; docs/_facts.md is this output."""
|
|
93
|
+
out = ["| Provider | Max breakpoints | TTLs | Docs |", "|---|---|---|---|"]
|
|
94
|
+
for name, p in PROVIDERS.items():
|
|
95
|
+
ttls = ", ".join(p.ttls) or "explicit caches take any TTL"
|
|
96
|
+
out.append(f"| {name} | {p.max_breakpoints or 'implicit only'} | {ttls} | <{p.docs}> |")
|
|
97
|
+
out += [
|
|
98
|
+
"",
|
|
99
|
+
"| Model | Input | Cache read | Cache write | Output | Min tokens | Storage/h | Source |",
|
|
100
|
+
"|---|--:|--:|---|--:|--:|--:|---|",
|
|
101
|
+
]
|
|
102
|
+
for name, m in MODELS.items():
|
|
103
|
+
write = ", ".join(f"{ttl}: {price:g}" for ttl, price in m.cache_write.items()) or "—"
|
|
104
|
+
storage = "—" if m.storage_hour is None else f"{m.storage_hour:g}"
|
|
105
|
+
out.append(
|
|
106
|
+
f"| `{name}` | {m.input:g} | {m.cache_read:g} | {write} | {m.output:g} "
|
|
107
|
+
f"| {m.min_tokens:,} | {storage} | [pricing]({m.source}) |"
|
|
108
|
+
)
|
|
109
|
+
out += ["", f"USD per 1M tokens. Verified {VERIFIED}."]
|
|
110
|
+
return "\n".join(out) + "\n"
|
|
111
|
+
|
|
112
|
+
|
|
113
|
+
if __name__ == "__main__":
|
|
114
|
+
print(markdown(), end="")
|
|
@@ -0,0 +1,84 @@
|
|
|
1
|
+
"""Gemini explicit caches through your own google-genai client: the library's only I/O."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import time
|
|
6
|
+
from typing import Any
|
|
7
|
+
|
|
8
|
+
from .economics import should_cache
|
|
9
|
+
from .prompt import Prompt
|
|
10
|
+
|
|
11
|
+
_LIVE: dict[str, tuple[str, float]] = {} # ponytail: per-process memo; other processes match on display_name
|
|
12
|
+
_MARGIN = 30.0 # seconds a cache must still live to be reused
|
|
13
|
+
|
|
14
|
+
|
|
15
|
+
def _plan(
|
|
16
|
+
p: Prompt, model: str, reuses: int, interval_s: float, tokens: int | None
|
|
17
|
+
) -> tuple[str, dict[str, Any]] | None:
|
|
18
|
+
if any(callable(t) for t in p._tools): # python-function tools can't live in an explicit cache
|
|
19
|
+
return None
|
|
20
|
+
d = should_cache(tokens or p.est_prefix_tokens(), reuses, "gemini", model, interval_s=interval_s)
|
|
21
|
+
if not d.cache or d.ttl is None:
|
|
22
|
+
return None
|
|
23
|
+
key = f"cmx-{p.call_site}-{model.rsplit('/', 1)[-1]}-{p.prefix_hash()}"
|
|
24
|
+
return key, {"display_name": key, "ttl": d.ttl, **p.gemini_prefix()}
|
|
25
|
+
|
|
26
|
+
|
|
27
|
+
def _alive(c: Any, key: str) -> bool:
|
|
28
|
+
exp = getattr(c, "expire_time", None)
|
|
29
|
+
return getattr(c, "display_name", None) == key and exp is not None and exp.timestamp() - time.time() > _MARGIN
|
|
30
|
+
|
|
31
|
+
|
|
32
|
+
def _remember(key: str, c: Any) -> str:
|
|
33
|
+
_LIVE[key] = (str(c.name), c.expire_time.timestamp())
|
|
34
|
+
return str(c.name)
|
|
35
|
+
|
|
36
|
+
|
|
37
|
+
def _memo(key: str) -> str | None:
|
|
38
|
+
hit = _LIVE.get(key)
|
|
39
|
+
return hit[0] if hit and hit[1] - time.time() > _MARGIN else None
|
|
40
|
+
|
|
41
|
+
|
|
42
|
+
def gemini_cache(
|
|
43
|
+
client: Any,
|
|
44
|
+
p: Prompt,
|
|
45
|
+
model: str,
|
|
46
|
+
*,
|
|
47
|
+
expected_reuses: int,
|
|
48
|
+
interval_s: float = 60.0,
|
|
49
|
+
prefix_tokens: int | None = None,
|
|
50
|
+
) -> str | None:
|
|
51
|
+
"""Name of a live explicit cache holding p's static prefix, created only if should_cache() says it pays.
|
|
52
|
+
Use it as p.gemini(model, cached_content=name). None means stay on implicit caching."""
|
|
53
|
+
plan = _plan(p, model, expected_reuses, interval_s, prefix_tokens)
|
|
54
|
+
if plan is None:
|
|
55
|
+
return None
|
|
56
|
+
key, config = plan
|
|
57
|
+
if name := _memo(key):
|
|
58
|
+
return name
|
|
59
|
+
for c in client.caches.list():
|
|
60
|
+
if _alive(c, key):
|
|
61
|
+
return _remember(key, c)
|
|
62
|
+
return _remember(key, client.caches.create(model=model, config=config))
|
|
63
|
+
|
|
64
|
+
|
|
65
|
+
async def gemini_cache_async(
|
|
66
|
+
client: Any,
|
|
67
|
+
p: Prompt,
|
|
68
|
+
model: str,
|
|
69
|
+
*,
|
|
70
|
+
expected_reuses: int,
|
|
71
|
+
interval_s: float = 60.0,
|
|
72
|
+
prefix_tokens: int | None = None,
|
|
73
|
+
) -> str | None:
|
|
74
|
+
"""Async twin of gemini_cache, using client.aio."""
|
|
75
|
+
plan = _plan(p, model, expected_reuses, interval_s, prefix_tokens)
|
|
76
|
+
if plan is None:
|
|
77
|
+
return None
|
|
78
|
+
key, config = plan
|
|
79
|
+
if name := _memo(key):
|
|
80
|
+
return name
|
|
81
|
+
async for c in await client.aio.caches.list():
|
|
82
|
+
if _alive(c, key):
|
|
83
|
+
return _remember(key, c)
|
|
84
|
+
return _remember(key, await client.aio.caches.create(model=model, config=config))
|
|
@@ -0,0 +1,295 @@
|
|
|
1
|
+
"""Prompt: segments ordered from most to least stable, rendered as request kwargs per provider."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
import hashlib
|
|
6
|
+
import re
|
|
7
|
+
from collections.abc import Mapping, Sequence
|
|
8
|
+
from typing import Any, Self
|
|
9
|
+
|
|
10
|
+
from . import facts
|
|
11
|
+
from .canon import canonical_json, normalize_ws, plain, tool_name
|
|
12
|
+
|
|
13
|
+
Json = dict[str, Any]
|
|
14
|
+
Parts = str | Mapping[str, Any] | Sequence[str | Mapping[str, Any]]
|
|
15
|
+
|
|
16
|
+
|
|
17
|
+
def _parts(x: Parts) -> list[str]:
|
|
18
|
+
"""Text parts: strings verbatim, anything else as canonical JSON."""
|
|
19
|
+
items: Sequence[Any] = [x] if isinstance(x, str | Mapping) else x
|
|
20
|
+
return [p if isinstance(p, str) else canonical_json(p) for p in items]
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
def _sort_tool(t: Any) -> Any:
|
|
24
|
+
t = plain(t)
|
|
25
|
+
if isinstance(t, dict):
|
|
26
|
+
for key in ("function_declarations", "functionDeclarations"):
|
|
27
|
+
if isinstance(t.get(key), list):
|
|
28
|
+
return {**t, key: sorted(t[key], key=tool_name)}
|
|
29
|
+
return t
|
|
30
|
+
|
|
31
|
+
|
|
32
|
+
_NOT_MARKABLE = {"thinking", "redacted_thinking"}
|
|
33
|
+
_LITELLM_ROUTES = { # LiteLLM route prefixes that honour each provider's cache fields
|
|
34
|
+
"anthropic": {"", "anthropic", "bedrock", "vertex_ai"},
|
|
35
|
+
"openai": {"", "openai"},
|
|
36
|
+
"gemini": {"", "gemini", "vertex_ai"},
|
|
37
|
+
}
|
|
38
|
+
|
|
39
|
+
|
|
40
|
+
def _cc(ttl: str) -> Json:
|
|
41
|
+
return {"type": "ephemeral"} if ttl == "5m" else {"type": "ephemeral", "ttl": ttl}
|
|
42
|
+
|
|
43
|
+
|
|
44
|
+
def _drop(t: Any, key: str) -> Any:
|
|
45
|
+
d = plain(t)
|
|
46
|
+
return {k: v for k, v in d.items() if k != key} if isinstance(d, dict) and key in d else t
|
|
47
|
+
|
|
48
|
+
|
|
49
|
+
def _drop_fn(t: Any) -> Any:
|
|
50
|
+
"""A LiteLLM tool without a stale cache_control inside its function object."""
|
|
51
|
+
d = plain(t)
|
|
52
|
+
if isinstance(d, dict) and isinstance(d.get("function"), dict) and "cache_control" in d["function"]:
|
|
53
|
+
return {**d, "function": _drop(d["function"], "cache_control")}
|
|
54
|
+
return t
|
|
55
|
+
|
|
56
|
+
|
|
57
|
+
def _check_ttl(provider: str, ttl: str) -> str:
|
|
58
|
+
if ttl not in facts.PROVIDERS[provider].ttls:
|
|
59
|
+
raise ValueError(f"{provider} cache TTL must be one of {facts.PROVIDERS[provider].ttls}, not {ttl!r}")
|
|
60
|
+
return ttl
|
|
61
|
+
|
|
62
|
+
|
|
63
|
+
def _unmark(msg: Any, key: str) -> Any:
|
|
64
|
+
"""Copy of msg without `key` markers on its blocks. Markers aren't content; stale ones would pile up."""
|
|
65
|
+
m = plain(msg)
|
|
66
|
+
if not (isinstance(m, dict) and isinstance(m.get("content"), list)):
|
|
67
|
+
return msg
|
|
68
|
+
blocks = [plain(b) for b in m["content"]]
|
|
69
|
+
if not any(isinstance(b, dict) and key in b for b in blocks):
|
|
70
|
+
return msg
|
|
71
|
+
return {**m, "content": [{k: v for k, v in b.items() if k != key} if isinstance(b, dict) else b for b in blocks]}
|
|
72
|
+
|
|
73
|
+
|
|
74
|
+
def openai_explicit(model: str) -> bool:
|
|
75
|
+
"""GPT-5.6 and later take explicit cache breakpoints; older models cache implicitly."""
|
|
76
|
+
m = re.search(r"gpt-(\d+)(?:\.(\d+))?", model)
|
|
77
|
+
return m is not None and (int(m[1]), int(m[2] or 0)) >= (5, 6)
|
|
78
|
+
|
|
79
|
+
|
|
80
|
+
def _mark(msg: Any, key: str, marker: Json, text_type: str, only_text: bool) -> Any:
|
|
81
|
+
"""Copy of msg with `marker` on its last markable block, or None if it has none. Text never changes."""
|
|
82
|
+
m = dict(plain(msg))
|
|
83
|
+
content = m.get("content")
|
|
84
|
+
if isinstance(content, str):
|
|
85
|
+
if not content.strip(): # providers reject markers on empty text
|
|
86
|
+
return None
|
|
87
|
+
m["content"] = [{"type": text_type, "text": content, key: marker}]
|
|
88
|
+
return m
|
|
89
|
+
if isinstance(content, list):
|
|
90
|
+
blocks = [plain(b) for b in content]
|
|
91
|
+
for i in range(len(blocks) - 1, -1, -1):
|
|
92
|
+
kind = blocks[i].get("type") if isinstance(blocks[i], dict) else None
|
|
93
|
+
ok = kind == text_type if only_text else kind is not None and kind not in _NOT_MARKABLE
|
|
94
|
+
if ok and not (kind in ("text", "input_text") and not str(blocks[i].get("text", "")).strip()):
|
|
95
|
+
blocks[i] = {**blocks[i], key: marker}
|
|
96
|
+
m["content"] = blocks
|
|
97
|
+
return m
|
|
98
|
+
return None
|
|
99
|
+
|
|
100
|
+
|
|
101
|
+
class Prompt:
|
|
102
|
+
"""Collect segments in any order; render with an adapter. Output order is fixed:
|
|
103
|
+
tools, system, context, examples, history, retrieved, user."""
|
|
104
|
+
|
|
105
|
+
def __init__(self, call_site: str = "default") -> None:
|
|
106
|
+
self.call_site = call_site
|
|
107
|
+
self._tools: list[Any] = []
|
|
108
|
+
self._system: list[str] = []
|
|
109
|
+
self._context: list[str] = []
|
|
110
|
+
self._examples: list[str] = []
|
|
111
|
+
self._history: list[Any] = []
|
|
112
|
+
self._retrieved: list[str] = []
|
|
113
|
+
self._user: list[str] = []
|
|
114
|
+
|
|
115
|
+
def tools(self, tools: Sequence[Any], *, sort: bool = True) -> Self:
|
|
116
|
+
"""Tool definitions in your provider's format; sorted by name unless sort=False."""
|
|
117
|
+
self._tools = sorted(map(_sort_tool, tools), key=tool_name) if sort else list(tools)
|
|
118
|
+
return self
|
|
119
|
+
|
|
120
|
+
def system(self, text: Parts) -> Self:
|
|
121
|
+
self._system = [t for t in map(normalize_ws, _parts(text)) if t]
|
|
122
|
+
return self
|
|
123
|
+
|
|
124
|
+
def context(self, docs: Parts, *, reorderable: bool = False) -> Self:
|
|
125
|
+
"""Static reference material. reorderable=True sorts the parts so their order can't drift."""
|
|
126
|
+
parts = [t for t in map(normalize_ws, _parts(docs)) if t]
|
|
127
|
+
self._context = sorted(parts) if reorderable else parts
|
|
128
|
+
return self
|
|
129
|
+
|
|
130
|
+
def examples(self, examples: Parts, *, reorderable: bool = False) -> Self:
|
|
131
|
+
parts = [t for t in map(normalize_ws, _parts(examples)) if t]
|
|
132
|
+
self._examples = sorted(parts) if reorderable else parts
|
|
133
|
+
return self
|
|
134
|
+
|
|
135
|
+
def history(self, messages: Sequence[Any]) -> Self:
|
|
136
|
+
"""Earlier turns in your provider's message format. Append-only; never modified."""
|
|
137
|
+
self._history = list(messages)
|
|
138
|
+
return self
|
|
139
|
+
|
|
140
|
+
def retrieved(self, chunks: Parts) -> Self:
|
|
141
|
+
"""Per-request context (RAG chunks, time, user profile). Placed after history, verbatim."""
|
|
142
|
+
self._retrieved = [t for t in _parts(chunks) if t.strip()]
|
|
143
|
+
return self
|
|
144
|
+
|
|
145
|
+
def user(self, text: str) -> Self:
|
|
146
|
+
self._user = [text] if text.strip() else []
|
|
147
|
+
return self
|
|
148
|
+
|
|
149
|
+
@property
|
|
150
|
+
def static(self) -> list[str]:
|
|
151
|
+
return self._system + self._context + self._examples
|
|
152
|
+
|
|
153
|
+
def _prefix_blob(self) -> str:
|
|
154
|
+
tools = [t.__qualname__ if callable(t) else plain(t) for t in self._tools] # python-function tools: by name
|
|
155
|
+
return canonical_json([tools, self.static])
|
|
156
|
+
|
|
157
|
+
def prefix_hash(self) -> str:
|
|
158
|
+
"""16 hex chars that change exactly when the tools or the static text change."""
|
|
159
|
+
return hashlib.sha256(self._prefix_blob().encode()).hexdigest()[:16]
|
|
160
|
+
|
|
161
|
+
def est_prefix_tokens(self) -> int:
|
|
162
|
+
# ponytail: ~4 chars/token estimate; pass exact counts to should_cache() when you have them
|
|
163
|
+
return len(self._prefix_blob()) // 4
|
|
164
|
+
|
|
165
|
+
def _tail(
|
|
166
|
+
self,
|
|
167
|
+
marker: Json | None,
|
|
168
|
+
key: str,
|
|
169
|
+
text_type: str,
|
|
170
|
+
roles: tuple[str, ...],
|
|
171
|
+
*,
|
|
172
|
+
only_text: bool,
|
|
173
|
+
count: int = 1,
|
|
174
|
+
) -> list[Any]:
|
|
175
|
+
"""History, then the final user turn, with `count` markers on the last markable positions: the final
|
|
176
|
+
user block (unless a per-request retrieved block follows it), then eligible history messages.
|
|
177
|
+
Stale markers in history are stripped first so they never pile up. Anthropic needs one tail marker
|
|
178
|
+
(its 20-block lookback finds earlier entries); OpenAI only looks up at breakpoints present in the
|
|
179
|
+
request, so count=2 also re-marks the position the previous request wrote."""
|
|
180
|
+
msgs = [_unmark(m, key) for m in self._history]
|
|
181
|
+
final: list[Json] = [{"type": text_type, "text": t} for t in self._retrieved + self._user]
|
|
182
|
+
left = count if marker is not None else 0
|
|
183
|
+
if left and final and not self._retrieved:
|
|
184
|
+
final[-1][key] = marker
|
|
185
|
+
left -= 1
|
|
186
|
+
for i in range(len(msgs) - 1, -1, -1):
|
|
187
|
+
if not left:
|
|
188
|
+
break
|
|
189
|
+
m = plain(msgs[i])
|
|
190
|
+
if isinstance(m, dict) and m.get("role") in roles and marker is not None:
|
|
191
|
+
marked = _mark(m, key, marker, text_type, only_text)
|
|
192
|
+
if marked is not None:
|
|
193
|
+
msgs[i] = marked
|
|
194
|
+
left -= 1
|
|
195
|
+
if final:
|
|
196
|
+
msgs.append({"role": "user", "content": final})
|
|
197
|
+
return msgs
|
|
198
|
+
|
|
199
|
+
def anthropic(self, model: str, *, ttl: str = "5m") -> Json:
|
|
200
|
+
"""kwargs for anthropic `client.messages.create(max_tokens=..., **kwargs)`."""
|
|
201
|
+
cc = _cc(_check_ttl("anthropic", ttl))
|
|
202
|
+
kw: Json = {"model": model}
|
|
203
|
+
if self._tools:
|
|
204
|
+
tools = [_drop(t, "cache_control") for t in self._tools]
|
|
205
|
+
kw["tools"] = [*tools[:-1], {**plain(tools[-1]), "cache_control": cc}]
|
|
206
|
+
if self.static:
|
|
207
|
+
kw["system"] = [{"type": "text", "text": t} for t in self.static]
|
|
208
|
+
kw["system"][-1]["cache_control"] = cc
|
|
209
|
+
kw["messages"] = self._tail(cc, "cache_control", "text", ("user", "assistant"), only_text=False)
|
|
210
|
+
return kw
|
|
211
|
+
|
|
212
|
+
def openai(self, model: str, *, ttl: str = "30m", cache_key: str | None = None) -> Json:
|
|
213
|
+
"""kwargs for openai `client.responses.create(**kwargs)`."""
|
|
214
|
+
return self._openai(model, ttl, cache_key, field="input", role="developer", text_type="input_text")
|
|
215
|
+
|
|
216
|
+
def openai_chat(self, model: str, *, ttl: str = "30m", cache_key: str | None = None) -> Json:
|
|
217
|
+
"""kwargs for openai `client.chat.completions.create(**kwargs)` and OpenAI-compatible servers."""
|
|
218
|
+
if ttl == "12h":
|
|
219
|
+
raise ValueError("the 12h cache TTL is Responses-only; use Prompt.openai()")
|
|
220
|
+
return self._openai(model, ttl, cache_key, field="messages", role="system", text_type="text")
|
|
221
|
+
|
|
222
|
+
def _openai(self, model: str, ttl: str, cache_key: str | None, *, field: str, role: str, text_type: str) -> Json:
|
|
223
|
+
explicit = openai_explicit(model)
|
|
224
|
+
if explicit:
|
|
225
|
+
_check_ttl("openai", ttl)
|
|
226
|
+
bp: Json | None = {"mode": "explicit"} if explicit else None
|
|
227
|
+
kw: Json = {"model": model}
|
|
228
|
+
if self._tools:
|
|
229
|
+
kw["tools"] = list(self._tools)
|
|
230
|
+
msgs: list[Any] = []
|
|
231
|
+
if self.static:
|
|
232
|
+
parts: list[Json] = [{"type": text_type, "text": t} for t in self.static]
|
|
233
|
+
if bp is not None:
|
|
234
|
+
parts[-1]["prompt_cache_breakpoint"] = bp
|
|
235
|
+
msgs.append({"role": role, "content": parts})
|
|
236
|
+
roles = ("user", "developer", "system")
|
|
237
|
+
msgs += self._tail(bp, "prompt_cache_breakpoint", text_type, roles, only_text=True, count=2)
|
|
238
|
+
kw[field] = msgs
|
|
239
|
+
if explicit:
|
|
240
|
+
kw["prompt_cache_options"] = {"mode": "explicit", "ttl": ttl}
|
|
241
|
+
if cache_key or not explicit:
|
|
242
|
+
kw["prompt_cache_key"] = cache_key or f"{self.call_site}:{self.prefix_hash()}"
|
|
243
|
+
return kw
|
|
244
|
+
|
|
245
|
+
def gemini(self, model: str, *, cached_content: str | None = None) -> Json:
|
|
246
|
+
"""kwargs for google-genai `client.models.generate_content(**kwargs)`. Implicit caching unless
|
|
247
|
+
cached_content (from gemini_cache) is given; then the cached fields are left out."""
|
|
248
|
+
config: Json = {"cached_content": cached_content} if cached_content else self.gemini_prefix()
|
|
249
|
+
contents = list(self._history)
|
|
250
|
+
final = [{"text": t} for t in self._retrieved + self._user]
|
|
251
|
+
if final:
|
|
252
|
+
contents.append({"role": "user", "parts": final})
|
|
253
|
+
return {"model": model, "contents": contents, "config": config}
|
|
254
|
+
|
|
255
|
+
def gemini_prefix(self) -> Json:
|
|
256
|
+
"""The cacheable part of a Gemini request: what an explicit cache holds."""
|
|
257
|
+
prefix: Json = {}
|
|
258
|
+
if self.static:
|
|
259
|
+
prefix["system_instruction"] = {"parts": [{"text": t} for t in self.static]}
|
|
260
|
+
if self._tools:
|
|
261
|
+
prefix["tools"] = list(self._tools)
|
|
262
|
+
return prefix
|
|
263
|
+
|
|
264
|
+
def litellm(self, model: str, *, ttl: str | None = None, explicit: bool = False) -> Json:
|
|
265
|
+
"""kwargs for `litellm.completion(**kwargs)` (or the LiteLLM Proxy via the OpenAI SDK), model included.
|
|
266
|
+
Cache fields follow the route: Claude gets cache_control, openai/ gets openai_chat(), gemini/ stays
|
|
267
|
+
implicit unless explicit=True (LiteLLM then creates an explicit cache for the static prefix)."""
|
|
268
|
+
route = model.split("/", 1)[0] if "/" in model else ""
|
|
269
|
+
provider = facts.provider_of(model)
|
|
270
|
+
if route not in _LITELLM_ROUTES.get(provider, set()):
|
|
271
|
+
provider = "other"
|
|
272
|
+
if provider == "openai":
|
|
273
|
+
return self.openai_chat(model, ttl=ttl or "30m")
|
|
274
|
+
if provider == "gemini" and explicit and (fm := facts.find(model)) is not None and fm.storage_hour is None:
|
|
275
|
+
raise ValueError(f"{model} has no explicit caching; drop explicit=True")
|
|
276
|
+
mark = provider == "anthropic" or (provider == "gemini" and explicit)
|
|
277
|
+
marker = _cc(_check_ttl("anthropic", ttl or "5m")) if mark else None
|
|
278
|
+
kw: Json = {"model": model}
|
|
279
|
+
if self._tools:
|
|
280
|
+
tools = [_drop_fn(t) for t in self._tools]
|
|
281
|
+
last = plain(tools[-1])
|
|
282
|
+
if provider == "anthropic" and isinstance(last, dict) and isinstance(last.get("function"), dict):
|
|
283
|
+
tools[-1] = {**last, "function": {**last["function"], "cache_control": marker}}
|
|
284
|
+
kw["tools"] = tools
|
|
285
|
+
msgs: list[Any] = []
|
|
286
|
+
if self.static:
|
|
287
|
+
parts: list[Json] = [{"type": "text", "text": t} for t in self.static]
|
|
288
|
+
if marker is not None:
|
|
289
|
+
parts[-1]["cache_control"] = marker
|
|
290
|
+
msgs.append({"role": "system", "content": parts})
|
|
291
|
+
# Gemini explicit caches cover the static prefix only; a history marker would create a cache per turn.
|
|
292
|
+
tail_marker = marker if provider == "anthropic" else None
|
|
293
|
+
msgs += self._tail(tail_marker, "cache_control", "text", ("user", "assistant"), only_text=True)
|
|
294
|
+
kw["messages"] = msgs
|
|
295
|
+
return kw
|
|
File without changes
|
|
@@ -0,0 +1,139 @@
|
|
|
1
|
+
"""Normalize provider usage into one shape, price it, aggregate it per call site."""
|
|
2
|
+
|
|
3
|
+
from __future__ import annotations
|
|
4
|
+
|
|
5
|
+
from dataclasses import dataclass, replace
|
|
6
|
+
from typing import Any
|
|
7
|
+
|
|
8
|
+
from . import facts
|
|
9
|
+
from .canon import jsonable, plain
|
|
10
|
+
|
|
11
|
+
|
|
12
|
+
@dataclass(frozen=True)
|
|
13
|
+
class Usage:
|
|
14
|
+
provider: str
|
|
15
|
+
model: str
|
|
16
|
+
input: int = 0 # every prompt token: uncached + cache read + cache write
|
|
17
|
+
cache_read: int = 0
|
|
18
|
+
cache_write: int = 0
|
|
19
|
+
output: int = 0 # includes thinking / reasoning tokens
|
|
20
|
+
est_cost: float | None = None # USD at list price as of facts.VERIFIED; None for unknown models
|
|
21
|
+
|
|
22
|
+
@property
|
|
23
|
+
def hit_rate(self) -> float:
|
|
24
|
+
return self.cache_read / self.input if self.input else 0.0
|
|
25
|
+
|
|
26
|
+
def __add__(self, other: Usage) -> Usage:
|
|
27
|
+
cost = None if self.est_cost is None or other.est_cost is None else self.est_cost + other.est_cost
|
|
28
|
+
return replace(
|
|
29
|
+
self,
|
|
30
|
+
input=self.input + other.input,
|
|
31
|
+
cache_read=self.cache_read + other.cache_read,
|
|
32
|
+
cache_write=self.cache_write + other.cache_write,
|
|
33
|
+
output=self.output + other.output,
|
|
34
|
+
est_cost=cost,
|
|
35
|
+
)
|
|
36
|
+
|
|
37
|
+
|
|
38
|
+
def _camel(key: str) -> str:
|
|
39
|
+
head, *rest = key.split("_")
|
|
40
|
+
return head + "".join(w.title() for w in rest)
|
|
41
|
+
|
|
42
|
+
|
|
43
|
+
def _n(d: Any, *keys: str) -> int:
|
|
44
|
+
"""First non-zero count among keys (snake_case or camelCase) of dict d; 0 if none."""
|
|
45
|
+
if isinstance(d, dict):
|
|
46
|
+
for k in keys:
|
|
47
|
+
for key in (k, _camel(k)):
|
|
48
|
+
if d.get(key):
|
|
49
|
+
return int(d[key])
|
|
50
|
+
return 0
|
|
51
|
+
|
|
52
|
+
|
|
53
|
+
def usage(response: Any, model: str | None = None) -> Usage:
|
|
54
|
+
"""Normalize an Anthropic, OpenAI (Responses or Chat), Gemini or LiteLLM response (object or dict)."""
|
|
55
|
+
d = plain(response)
|
|
56
|
+
if not isinstance(d, dict):
|
|
57
|
+
raise ValueError("unrecognised response: expected an SDK response object or dict")
|
|
58
|
+
name = str(model or d.get("model") or d.get("model_version") or d.get("modelVersion") or "")
|
|
59
|
+
meta = d.get("usage_metadata") or d.get("usageMetadata")
|
|
60
|
+
if meta is not None or "candidates" in d: # Gemini: prompt_token_count includes cached tokens
|
|
61
|
+
total = _n(meta, "prompt_token_count") + _n(meta, "tool_use_prompt_token_count")
|
|
62
|
+
out = _n(meta, "candidates_token_count") + _n(meta, "thoughts_token_count")
|
|
63
|
+
return _priced("gemini", name, total, _n(meta, "cached_content_token_count"), 0, out)
|
|
64
|
+
u = d.get("usage") or {}
|
|
65
|
+
if d.get("type") == "message": # Anthropic: input_tokens EXCLUDES cache tokens
|
|
66
|
+
read, write = _n(u, "cache_read_input_tokens"), _n(u, "cache_creation_input_tokens")
|
|
67
|
+
long_write = _n(u.get("cache_creation"), "ephemeral_1h_input_tokens")
|
|
68
|
+
total = _n(u, "input_tokens") + read + write
|
|
69
|
+
return _priced("anthropic", name, total, read, write, _n(u, "output_tokens"), long_write)
|
|
70
|
+
if "prompt_tokens" in u: # OpenAI Chat and LiteLLM: prompt_tokens includes cache tokens
|
|
71
|
+
det = u.get("prompt_tokens_details") or {}
|
|
72
|
+
write = _n(det, "cache_write_tokens", "cache_creation_tokens") or _n(u, "cache_creation_input_tokens")
|
|
73
|
+
long_write = _n(det.get("cache_write_tokens_details"), "ttl_12h_tokens")
|
|
74
|
+
read, out = _n(det, "cached_tokens"), _n(u, "completion_tokens")
|
|
75
|
+
return _priced(facts.provider_of(name), name, _n(u, "prompt_tokens"), read, write, out, long_write)
|
|
76
|
+
if "input_tokens" in u: # OpenAI Responses: input_tokens includes cache tokens
|
|
77
|
+
det = u.get("input_tokens_details") or {}
|
|
78
|
+
long_write = _n(det.get("cache_write_tokens_details"), "ttl_12h_tokens")
|
|
79
|
+
read, write = _n(det, "cached_tokens"), _n(det, "cache_write_tokens")
|
|
80
|
+
return _priced("openai", name, _n(u, "input_tokens"), read, write, _n(u, "output_tokens"), long_write)
|
|
81
|
+
raise ValueError("unrecognised response: expected Anthropic, OpenAI, Gemini or LiteLLM")
|
|
82
|
+
|
|
83
|
+
|
|
84
|
+
def _priced(provider: str, model: str, total: int, read: int, write: int, out: int, long_write: int = 0) -> Usage:
|
|
85
|
+
m = facts.find(model)
|
|
86
|
+
cost = None
|
|
87
|
+
if m is not None:
|
|
88
|
+
if m.long_context and total > m.long_context[0]:
|
|
89
|
+
m = m.long_context[1]
|
|
90
|
+
writes = list(m.cache_write.values()) or [m.input] # [short TTL, long TTL]
|
|
91
|
+
uncached = total - read - write
|
|
92
|
+
cost = (
|
|
93
|
+
uncached * m.input
|
|
94
|
+
+ read * m.cache_read
|
|
95
|
+
+ (write - long_write) * writes[0]
|
|
96
|
+
+ long_write * writes[-1]
|
|
97
|
+
+ out * m.output
|
|
98
|
+
) / 1e6
|
|
99
|
+
return Usage(provider, model, total, read, write, out, cost)
|
|
100
|
+
|
|
101
|
+
|
|
102
|
+
_HEADER = ("call site", "calls", "hit rate", "input", "cache read", "cache write", "output", "est $", "top drift")
|
|
103
|
+
|
|
104
|
+
|
|
105
|
+
class Stats:
|
|
106
|
+
"""Usage totals per call site, in memory."""
|
|
107
|
+
|
|
108
|
+
def __init__(self) -> None:
|
|
109
|
+
self.calls: dict[str, int] = {}
|
|
110
|
+
self.totals: dict[str, Usage] = {}
|
|
111
|
+
|
|
112
|
+
def add(self, call_site: str, u: Usage) -> None:
|
|
113
|
+
self.calls[call_site] = self.calls.get(call_site, 0) + 1
|
|
114
|
+
self.totals[call_site] = self.totals[call_site] + u if call_site in self.totals else u
|
|
115
|
+
|
|
116
|
+
def table(self, notes: dict[str, str] | None = None) -> str:
|
|
117
|
+
rows = [list(_HEADER)]
|
|
118
|
+
for site, u in sorted(self.totals.items()):
|
|
119
|
+
cost = "n/a" if u.est_cost is None else f"{u.est_cost:.4f}"
|
|
120
|
+
rows.append(
|
|
121
|
+
[
|
|
122
|
+
site,
|
|
123
|
+
str(self.calls[site]),
|
|
124
|
+
f"{u.hit_rate:.1%}",
|
|
125
|
+
f"{u.input:,}",
|
|
126
|
+
f"{u.cache_read:,}",
|
|
127
|
+
f"{u.cache_write:,}",
|
|
128
|
+
f"{u.output:,}",
|
|
129
|
+
cost,
|
|
130
|
+
(notes or {}).get(site, ""),
|
|
131
|
+
]
|
|
132
|
+
)
|
|
133
|
+
widths = [max(len(r[i]) for r in rows) for i in range(len(rows[0]))]
|
|
134
|
+
return "\n".join(" ".join(c.ljust(w) for c, w in zip(r, widths, strict=True)).rstrip() for r in rows)
|
|
135
|
+
|
|
136
|
+
|
|
137
|
+
def record(call_site: str, request: Any, response: Any) -> dict[str, Any]:
|
|
138
|
+
"""One JSONL line for `cachemaxxing report`. The library never writes files; you do."""
|
|
139
|
+
return {"call_site": call_site, "request": jsonable(request), "response": jsonable(response)}
|