bigquery-data-science 0.8.0__tar.gz → 0.8.2__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- bigquery_data_science-0.8.2/CHANGELOG.md +77 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/CITATION.cff +2 -2
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/CONTRIBUTING.md +22 -9
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/PKG-INFO +1 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/README.md +3 -4
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/plugin.json +1 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/pyproject.toml +2 -2
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/scripts/check_install.sh +7 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/PLANS.md +13 -5
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/SKILL.md +1 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/skill.manifest.json +3 -3
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-data-science/SKILL.md +1 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-data-science/reference/namespace-matrix.md +16 -15
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-data-science/skill.manifest.json +3 -3
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/SKILL.md +1 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/reference/preprocessing-functions.md +1 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/skill.manifest.json +3 -3
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/__init__.py +5 -5
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/cli.py +293 -2
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/installer.py +3 -1
- bigquery_data_science-0.8.2/src/bigquery_data_science/tooling/bump_version.py +324 -0
- bigquery_data_science-0.8.2/src/bigquery_data_science/tooling/crossrefs.py +135 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/manifest.py +10 -4
- bigquery_data_science-0.8.2/src/bigquery_data_science/tooling/markdown_check.py +213 -0
- bigquery_data_science-0.8.2/src/bigquery_data_science/tooling/notebook_claims.py +136 -0
- bigquery_data_science-0.8.2/src/bigquery_data_science/tooling/run_notebook.py +199 -0
- bigquery_data_science-0.8.2/src/bigquery_data_science/tooling/status_labels.py +181 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/tests/test_installer_and_catalog.py +1 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/tests/test_packaging.py +1 -1
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/tests/test_tooling.py +252 -0
- bigquery_data_science-0.8.0/CHANGELOG.md +0 -42
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/.gitignore +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/CODE_OF_CONDUCT.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/LICENSE +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/SECURITY.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_agg.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_classify.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_count_tokens.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_detect_anomalies.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_embed.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_evaluate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_forecast.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_generate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_generate_bool.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_generate_double.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_generate_embedding.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_generate_int.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_generate_table.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_generate_text.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_if.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_key_drivers.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_parse_document.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_predict.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_score.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_search.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ai_similarity.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/catalog_search.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/content_analysis.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/content_moderation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/data_enrichment.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/document_intelligence.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/document_rag.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/image_deduplication.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/log_analysis.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/metric_diagnostics.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ml_annotate_image.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ml_generate_embedding.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ml_generate_text.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ml_process_document.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ml_transcribe.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ml_translate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/ml_understand_text.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/multimodal_analysis.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/rag_pipeline.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/semantic_search.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/tabular_prediction.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/time_series_intelligence.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/narrative/vector_search.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/reference/augmented-analytics.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/reference/cloud-ai-service-models.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/reference/document-processing.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/reference/embeddings-and-search.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/reference/general-purpose-generation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/reference/managed-functions.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/reference/predictive-ai.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/reference/workflows.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/INDEX.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aiagg.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aicausal_effect-covered-in-bigquery-ml.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aiclassify.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aicount_tokens.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aidetect_anomalies.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aiembed.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aievaluate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aiforecast.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aigenerate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aigenerate_bool.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aigenerate_double.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aigenerate_embedding.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aigenerate_int.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aigenerate_table.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aigenerate_text.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aiif.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aikey_drivers.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aiparse_document.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aipredict.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aiscore.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aisearch.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/aisimilarity.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/choosing-between-these-and-the-ai-functions.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/hybrid-search-capability.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/mlannotate_image.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/mlgenerate_embedding.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/mlgenerate_text.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/mlprocess_document.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/mltranscribe.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/mltranslate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/mlunderstand_text.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/multimodal-input-patterns-by-function.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/object-tables.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/objectref-and-objectrefruntime-schema-reference.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/objfetch_metadata.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/objget_access_url.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/objget_read_url.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/objlist.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/objmake_ref.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/per-row-failures-and-the-retry-pattern.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/setup-apis-connection-roles.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/two-input-shapes.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/vector_search.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/syntax/what-the-five-have-in-common.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/airflow_with_kfp.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/anomaly_fraud_detection.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/arima_plus.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/arima_plus_xreg.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/autoencoder.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/automl_classifier.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/automl_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/boosted_tree_classifier.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/boosted_tree_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/bucketizing.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/causal_effect.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/churn_retention.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/cloud_workflows.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/composer_airflow.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/contribution_analysis.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/cross_validation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/customer_segmentation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/dataform.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/dbt.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/difference_in_differences.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/distance.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/dnn_classifier.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/dnn_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/embeddings_classification.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/encoding.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/ensembling.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/evaluation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/exploration.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/export.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/feature_engineering.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/feature_store.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/feature_store_workflow.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/ga4_churn_prediction.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/hierarchical_forecasting.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/image.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/imported.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/kmeans.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/linear_regression.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/logistic_regression.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/matrix_factorization.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/model_monitoring.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/pca.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/price_elasticity_dml.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/propensity_score_matching.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/random_forest_classifier.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/random_forest_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/recommendation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/regression_based_forecasting.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/remote.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/scalers.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/scheduled_queries.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/sql_scripting.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/survival_analysis.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/synthetic_control.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/text.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/time_series.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/transform_only.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/uplift_cate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/vertex_kfp.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/wide_and_deep_classifier.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/narrative/wide_and_deep_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/reference/classification.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/reference/model-management.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/reference/regression.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/reference/unsupervised-and-specialized.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/reference/workflows-and-pipelines.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/1-model_type-catalog.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/2-task-mlevaluate-metric-columns.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/3-capability-matrix-per-model-type.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/4-explainability-weights-functions.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/5-connection-matrix.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/6-which-model-free-function-no-create-model-no-connection.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/7-point-in-time-feature-retrieval-which-of-the-two.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/INDEX.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/aicausal_effect.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/arima_plus-forecasting-lifecycle-functions.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/arima_plus-univariate-time-series-forecasting.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/arima_plus_xreg-multivariate-time-series-with-external-regressors.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/autoencoder.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/automl_classifier-automl_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/boosted_tree_classifier-boosted_tree_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/contribution_analysis.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/dnn_classifier-dnn_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/dnn_linear_combined_classifier-dnn_linear_combined_regressor-wide-and-deep.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/explainability-functions-mlexplain_predict-mlglobal_explain-mlfeature_importance.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/exploratory-data-analysis-mldescribe_data-mlcorrelation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/export-model.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/feature-engineering-standalone-preprocessing-functions.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/image-preprocessing-functions-mldecode_image-mlresize_image-mlconvert_image_type-mlconvert_color_space.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/imported-models-tensorflow-tensorflow_lite-onnx-xgboost.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/kmeans.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/linear_reg-logistic_reg-generalized-linear-models.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/matrix_factorization.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mladvanced_weights.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlarima_coefficients.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlarima_evaluate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlbag_of_words.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlbucketize.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlcentroids.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlconfusion_matrix.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlconvert_color_space.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlconvert_image_type.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlcorrelation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mldecode_image.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mldescribe_data.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mldetect_anomalies.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mldistance.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlentity_features_at_time.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlevaluate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlexplain_forecast.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlexplain_predict.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlfeature_cross.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlfeature_importance.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlfeature_info.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlfeatures_at_time.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlforecast.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlgenerate_embedding-from-a-bqml-pca-autoencoder-matrix_factorization-model.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlglobal_explain.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlhash_bucketize.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlholiday_info.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlimputer.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mllp_norm.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlmetrics.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlngrams.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlone_hot_encoder-mlmulti_hot_encoder-mllabel_encoder.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlpolynomial_expand.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlpredict.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlprincipal_component_info.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlprincipal_components.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlquantile_bucketize.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlrecommend.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlreconstruction_loss.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlresize_image.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlroc_curve.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mltf_idf.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mltfdv_describe.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mltfdv_validate.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mltraining_info.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mltransform-applying-a-saved-transform.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mltranspose-not-a-function-pointer.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mltrial_info.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlvalidate_data_drift.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlvalidate_data_skew.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/mlweights.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/model-free-time-series-decomposition-mltrend-mlseasonality-mldetect_change_points.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/model-introspection-mlfeature_info-mltraining_info-mltrial_info.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/model-monitoring-data-validation.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/numerical-scalers-mlstandard_scaler-mlmin_max_scaler-mlmax_abs_scaler-mlrobust_scaler-mlnormalizer.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/onnx.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/pca.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/point-in-time-feature-retrieval-mlfeatures_at_time-mlentity_features_at_time.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/quick-comparison.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/random_forest_classifier-random_forest_regressor.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/remote-remote-model-over-a-vertex-ai-endpoint-the-mechanism.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/tensorflow.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/tensorflow_lite.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/text-preprocessing-functions-mlngrams-mltf_idf-mlbag_of_words.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/timesfm-built-in-foundation-forecaster-see-bigquery-ai.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/transform_only.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/syntax/xgboost.md +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/pinned-models.json +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/catalog.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/mcp_server.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/__init__.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/convert_notebook.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/link_policy.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/markdown_anchors.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/narrative_drift.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/pinned_models.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/reference_structure.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/sync_syntax.py +0 -0
- {bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/tooling/validate.py +0 -0
|
@@ -0,0 +1,77 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
All notable changes to `bigquery-data-science` are documented in this file.
|
|
4
|
+
|
|
5
|
+
The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.1.0/),
|
|
6
|
+
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).
|
|
7
|
+
|
|
8
|
+
## [0.8.2] - 2026-10-21
|
|
9
|
+
|
|
10
|
+
### Added
|
|
11
|
+
- **Maintainer Verification & Execution Gates (`P2.1`–`P2.5`):**
|
|
12
|
+
- `bigquery-data-science check-status-labels`: Verifies `Preview` vs `GA` status label consistency across `bigquery-ai/README.md`, `bigquery-ml/README.md`, `<domain>/reference/*.md`, and `skills/bigquery-data-science/reference/namespace-matrix.md`.
|
|
13
|
+
- `bigquery-data-science check-crossrefs`: Verifies bidirectional link symmetry between workflow notebooks (`**Functions/Models used:**`) and function/model notebooks (`**Featured in:**`).
|
|
14
|
+
- `bigquery-data-science run-notebook`: Headless Jupyter notebook runner wrapping `jupyter_client` and `nbformat` with automatic working-directory resolution, mTLS certificate configuration, `bigquery-data-science` kernelspec stamping, and optional `--sync-narratives`.
|
|
15
|
+
- `bigquery-data-science check-notebook-claims`: Audits high-precision decimal claims in notebook markdown prose against code cells and rendered cell outputs.
|
|
16
|
+
- `bigquery-data-science check-markdown`: Verifies balanced code fences, GFM table column consistency (including zero unescaped `|` pipes inside inline code in table cells), and vertical-first `flowchart TD` Mermaid diagram layout ($\le 3$ parallel horizontal nodes per rank).
|
|
17
|
+
- Integrated `check-status-labels`, `check-crossrefs`, `check-notebook-claims`, and `check-markdown` into `bigquery-data-science sweep` (Stage 7).
|
|
18
|
+
|
|
19
|
+
### Changed
|
|
20
|
+
- **Vertical-First Mermaid Diagram Refactor (`README.md` & `bigquery-ml/README.md`):**
|
|
21
|
+
- Refactored `README.md` architecture diagram from `flowchart LR` to vertical `flowchart TD` and updated `pyproject.toml` `hatch-fancy-pypi-readme` pattern.
|
|
22
|
+
- Refactored `bigquery-ml/README.md` lifecycle diagram to stack `SCORE` (`Evaluate & Score`) and `EXPLAIN` (`Explainability, Weights & Training Metadata`) vertically (`<= 3` nodes wide per rank) for maximum font legibility on GitHub.
|
|
23
|
+
- **Status Label & Table Alignment (`namespace-matrix.md`, `managed-functions.md`, `preprocessing-functions.md`):**
|
|
24
|
+
- Synchronized `AI.AGG`, `AI.IF`, `AI.SCORE`, `AI.CLASSIFY`, `AI.EMBED`, `AI.SIMILARITY`, `AI.SEARCH`, and `ML.DECODE_IMAGE` family status labels in `skills/bigquery-data-science/reference/namespace-matrix.md`.
|
|
25
|
+
- Replaced unescaped `||vector||_p` pipe syntax inside the `ML.NORMALIZER` GFM table row in `skills/bigquery-ml/reference/preprocessing-functions.md` with `ML.LP_NORM(vector, p)`.
|
|
26
|
+
|
|
27
|
+
## [0.8.1] - 2026-10-21
|
|
28
|
+
|
|
29
|
+
### Added
|
|
30
|
+
- **Lockstep Version Stamper (`bigquery-data-science bump-version`):**
|
|
31
|
+
- Added `src/bigquery_data_science/tooling/bump_version.py` and the `bigquery-data-science bump-version [<version>] [--check]` CLI command to stamp or verify Semantic Version parity across `pyproject.toml`, `src/bigquery_data_science/__init__.py`, `CITATION.cff`, `plugin.json`, `.claude-plugin/marketplace.json`, `skills/*/SKILL.md`, `skills/*/skill.manifest.json`, and `tests/test_packaging.py` in a single step.
|
|
32
|
+
- Integrated `check_version_lockstep` into `bigquery-data-science sweep`.
|
|
33
|
+
- **Authoring, Readability & Visual Standards (`CONTRIBUTING.md` & `skills/PLANS.md`):**
|
|
34
|
+
- Codified the 100% additive/backward-compatible contract, simple Python/SQL and plain-English guidelines, vertical-first `flowchart TD` Mermaid diagram layout rules ($\le 3$ columns wide), and clean Markdown/table compilation standards.
|
|
35
|
+
|
|
36
|
+
### Changed
|
|
37
|
+
- **GitHub Actions Runner & Node 24 Modernization (`.github/workflows/ci.yml` & `release.yml`):**
|
|
38
|
+
- Pinned `runs-on: ubuntu-24.04` and enabled `FORCE_JAVASCRIPT_ACTIONS_TO_NODE24: "true"` across CI and Release workflows.
|
|
39
|
+
- **Pre-Commit Hook & Version Fallback Hygiene:**
|
|
40
|
+
- Updated `.pre-commit-config.yaml` to use generic internal-domain regex detection.
|
|
41
|
+
- Replaced hardcoded `"0.7.0"` fallback strings in `src/bigquery_data_science/installer.py` and `src/bigquery_data_science/tooling/manifest.py` with `bigquery_data_science.__version__`.
|
|
42
|
+
|
|
43
|
+
## [0.8.0] - 2026-10-20
|
|
44
|
+
|
|
45
|
+
### Added
|
|
46
|
+
- **`AI.AGG` Structured Output & Error Tolerance Support:**
|
|
47
|
+
- Added coverage for GA `output_schema` parameter emitting typed `STRUCT` records directly from aggregation via SQL DDL schema strings.
|
|
48
|
+
- Added coverage for GA `max_error_ratio` parameter for fault-tolerant aggregation.
|
|
49
|
+
- Added Section 11 (`output_schema`) and Section 12 (`max_error_ratio`) to `bigquery-ai/functions/ai_agg/ai_agg.ipynb` and matching Examples 9 & 10 to `bigquery-ai/functions/ai_agg/ai_agg.sql`.
|
|
50
|
+
- **`gemini-4-argon` Foundation Model Support:**
|
|
51
|
+
- Added `gemini-4-argon` to `skills/pinned-models.json`, `bigquery-ai/RESOURCES.md`, and `bigquery-ai/reference/general-purpose-functions.md`. Verified live via BigQuery.
|
|
52
|
+
- **GoogleSQL Reusable Column Aliases GA:**
|
|
53
|
+
- Documented GoogleSQL GA support for referencing `SELECT` aliases inside expressions and `WHERE` clauses.
|
|
54
|
+
|
|
55
|
+
### Changed
|
|
56
|
+
- **`AI.AGG` Status Transition:**
|
|
57
|
+
- Graduated `AI.AGG` from Preview to GA in `bigquery-ai/README.md`, `bigquery-ai/reference/managed-functions.md`, and `skills/bigquery-ai/reference/managed-functions.md`.
|
|
58
|
+
- **Skill Progressive Lenses Re-synchronized:**
|
|
59
|
+
- Lens 3 (`skills/bigquery-ai/syntax/aiagg.md`): Regenerated surgical syntax card with `output_schema` and `max_error_ratio` signatures.
|
|
60
|
+
- Lens 4 (`skills/bigquery-ai/narrative/ai_agg.md`): Regenerated textbook narrative from the executed `ai_agg.ipynb`.
|
|
61
|
+
- Refreshed manifests across all 3 agent skills (`bigquery-data-science`, `bigquery-ml`, `bigquery-ai`).
|
|
62
|
+
|
|
63
|
+
## [0.7.0] - 2026-10-19
|
|
64
|
+
|
|
65
|
+
### Added
|
|
66
|
+
- **Standalone Repository & 1:1 Domain Normalization (`bigquery-ml/` and `bigquery-ai/`):**
|
|
67
|
+
- Extracted and normalized all 61 BigQuery ML notebooks (`bigquery-ml/`) and 43 BigQuery AI notebooks (`bigquery-ai/`) with companion `.sql` scripts, exhaustive `reference/*.md` documentation, and unified `bigquery-data-science` Jupyter kernel metadata.
|
|
68
|
+
- **Hybrid 3-Skill Hierarchy & 4-Lens Progressive Disclosure (`skills/`):**
|
|
69
|
+
- `skills/bigquery-data-science/`: Umbrella task router, 10 head-to-head empirical comparisons, cross-namespace composition guide, reviewer rubric, and `reference/namespace-matrix.md` prerequisite matrix.
|
|
70
|
+
- `skills/bigquery-ml/` and `skills/bigquery-ai/`: 4-Lens architecture — Lens 1 (`SKILL.md` routing & cross-cutting gotchas), Lens 2 (`reference/*.md` use-case decision guides), Lens 3 (`syntax/*.md` surgical H2-sliced per-model/per-function syntax cards + `syntax/INDEX.md`), and Lens 4 (`narrative/*.md` 104 boilerplate-stripped textbook walkthroughs with GitHub provenance banners).
|
|
71
|
+
- **Zero-Dependency Python Package, CLI & Stdio MCP Server (`src/bigquery_data_science/`):**
|
|
72
|
+
- Skill & kernel installer (`bigquery-data-science install`, `list`, `path`, `kernel`) and federated `statmike.agent_skills` entry point.
|
|
73
|
+
- Instant offline catalog engine (`bigquery-data-science lookup`, `search`, `triage`).
|
|
74
|
+
- Zero-dependency JSON-RPC stdio MCP server (`bigquery-data-science mcp`) exposing `triage_bigquery_task`, `lookup_bigquery_syntax`, `search_bigquery_gotchas`, and `get_bigquery_walkthrough`.
|
|
75
|
+
- Maintainer verification suite (`sweep`, `validate`, `check-links`, `check-reference`, `check-syntax-sync`, `check-pinned-models`, `check-narratives`, `sync-syntax`, `convert-notebook`, `manifest`).
|
|
76
|
+
- **Unified Packaging & Layered `uv` Extras (`pyproject.toml` & `uv.lock`):**
|
|
77
|
+
- Zero-dependency `< 1.5 MB` PyPI wheel bundling `skills/`, with optional extras `[notebooks]`, `[pipelines]`, `[workflows]`, and `[all]`.
|
|
@@ -9,8 +9,8 @@ authors:
|
|
|
9
9
|
repository-code: "https://github.com/statmike/bigquery-data-science"
|
|
10
10
|
url: "https://github.com/statmike/bigquery-data-science"
|
|
11
11
|
license: Apache-2.0
|
|
12
|
-
version: "0.8.
|
|
13
|
-
date-released: "2026-10-
|
|
12
|
+
version: "0.8.2"
|
|
13
|
+
date-released: "2026-10-21"
|
|
14
14
|
keywords:
|
|
15
15
|
- google-cloud
|
|
16
16
|
- bigquery
|
|
@@ -38,6 +38,22 @@ Every contribution must follow these security and privacy rules:
|
|
|
38
38
|
- **Zero proprietary or customer data:** Never include customer names, internal hostnames, credentials, or hardcoded live personal/internal GCP project IDs in tracked code or configs.
|
|
39
39
|
- **Self-contained, reproducible workflows:** Notebooks rely on public datasets (`bigquery-public-data.*`), synthetic data generated in-notebook, or resources created by the workflow's own setup steps.
|
|
40
40
|
|
|
41
|
+
## Authoring, Readability & Visual Standards
|
|
42
|
+
|
|
43
|
+
To keep `bigquery-data-science` easy for humans to read and deterministic for agents to consume, all contributions follow four authoring rules:
|
|
44
|
+
|
|
45
|
+
1. **100% Additive & Backward-Compatible Changes:**
|
|
46
|
+
- Do not remove or incompatibly alter existing CLI subcommands, positional arguments, flags, MCP tool names/schemas, Python exports (`bigquery_data_science.__all__`), or skill paths (`skills/<name>/{SKILL.md,reference,syntax,narrative}`).
|
|
47
|
+
- Add new CLI capabilities via opt-in flags, and add new BigQuery features to existing notebooks/SQL scripts as additional numbered steps or examples rather than deleting foundational examples.
|
|
48
|
+
2. **Simple Code & Simple English:**
|
|
49
|
+
- **Python & SQL:** Prefer flat control flow, descriptive identifiers, named module-level constants instead of magic literals, full type annotations (`mypy --strict`), and small single-purpose functions. SQL scripts should use clear CTE stages and brief inline comments explaining *why* options are set.
|
|
50
|
+
- **Prose:** Open every section with a plain-English summary (*what it does, when to use it, and what it requires*) before diving into syntax tables or edge cases. Prefer short sentences and comparison tables over dense paragraphs.
|
|
51
|
+
3. **Vertical-First Mermaid Diagrams (`flowchart TD`):**
|
|
52
|
+
- Wide horizontal diagrams (`flowchart LR` or rows with 4+ nodes side-by-side) force GitHub and Markdown viewers to shrink the entire SVG to fit the page width, making node text tiny and hard to read.
|
|
53
|
+
- Always orient the primary flow **vertically (`flowchart TD`)**, keep horizontal width to **at most 3 nodes per rank** (stacking larger sets into vertical `subgraph` blocks), wrap node labels at ~35–45 characters using `<br/>`, and quote labels containing parentheses or brackets (`id["Label (Detail)"]`).
|
|
54
|
+
4. **Clean Markdown, Mermaid & Table Compilation:**
|
|
55
|
+
- Every Markdown file and notebook Markdown cell must render cleanly on GitHub: balanced code fences, valid GFM table delimiter rows with matching column counts across every row, no unescaped `|` characters inside table cells, and 100% resolved relative links and `#anchors`.
|
|
56
|
+
|
|
41
57
|
## Releasing
|
|
42
58
|
|
|
43
59
|
Releases are published to TestPyPI and PyPI via GitHub Actions OIDC Trusted Publishing ([`.github/workflows/release.yml`](.github/workflows/release.yml)) whenever a `v*` tag is pushed.
|
|
@@ -53,16 +69,13 @@ Releases are published to TestPyPI and PyPI via GitHub Actions OIDC Trusted Publ
|
|
|
53
69
|
|
|
54
70
|
### 1. Version Bump & Changelog Lockstep
|
|
55
71
|
|
|
56
|
-
|
|
57
|
-
|
|
58
|
-
|
|
59
|
-
|
|
60
|
-
|
|
61
|
-
5. `CITATION.cff` (`version` and `date-released`)
|
|
62
|
-
6. `CHANGELOG.md` (`## [X.Y.Z] - YYYY-MM-DD` section)
|
|
63
|
-
7. `skills/{bigquery-data-science,bigquery-ml,bigquery-ai}/skill.manifest.json` (`"version"`, regenerated via `uv run bigquery-data-science manifest --version X.Y.Z`)
|
|
72
|
+
Stamp the new version across all lockstep locations (`pyproject.toml`, `src/bigquery_data_science/__init__.py`, `CITATION.cff`, `plugin.json`, `.claude-plugin/marketplace.json`, `skills/*/SKILL.md`, `skills/*/skill.manifest.json`, and `tests/test_packaging.py`) with a single command:
|
|
73
|
+
|
|
74
|
+
```bash
|
|
75
|
+
uv run bigquery-data-science bump-version X.Y.Z
|
|
76
|
+
```
|
|
64
77
|
|
|
65
|
-
Then re-lock with `UV_NO_CONFIG=1 uv lock
|
|
78
|
+
Then add the `## [X.Y.Z] - YYYY-MM-DD` section to `CHANGELOG.md`, re-lock with `UV_NO_CONFIG=1 uv lock`, and run the full verification gate above (or `uv run bigquery-data-science bump-version --check`).
|
|
66
79
|
|
|
67
80
|
### 2. Pre-Release Verification on TestPyPI (`vX.Y.Zrc1`)
|
|
68
81
|
|
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.5
|
|
2
2
|
Name: bigquery-data-science
|
|
3
|
-
Version: 0.8.
|
|
3
|
+
Version: 0.8.2
|
|
4
4
|
Summary: BigQuery ML, BigQuery AI, and 4-Lens Agent Skills: 104 live-verified SQL/Python workflows, zero-dependency CLI catalog & skill installer, and stdio MCP server.
|
|
5
5
|
Project-URL: Homepage, https://github.com/statmike/bigquery-data-science
|
|
6
6
|
Project-URL: Repository, https://github.com/statmike/bigquery-data-science
|
|
@@ -12,16 +12,15 @@
|
|
|
12
12
|
`104 live-verified notebooks` · `87 SQL scripts` · `3 Agent Skills` · `137 <25 KB syntax cards` · `zero-dependency CLI & stdio MCP`
|
|
13
13
|
|
|
14
14
|
```mermaid
|
|
15
|
-
flowchart
|
|
15
|
+
flowchart TD
|
|
16
16
|
subgraph GT["1. Ground-Truth Notebooks & SQL (GitHub)"]
|
|
17
|
-
direction
|
|
17
|
+
direction LR
|
|
18
18
|
BQML["bigquery-ml/ (61 Notebooks · 58 SQL)<br/>23 Models · 12 Functions<br/>18 Workflows · 8 Pipelines"]
|
|
19
19
|
BQAI["bigquery-ai/ (43 Notebooks · 29 SQL)<br/>29 AI.* & ML.* Functions<br/>14 Multi-Function Workflows"]
|
|
20
20
|
REFS["13 Deep Reference Guides<br/>bigquery-ml/reference/ (5) · bigquery-ai/reference/ (8)<br/>Options · Gotchas · Pinned Models"]
|
|
21
|
-
BQML --- BQAI --- REFS
|
|
22
21
|
end
|
|
23
22
|
subgraph SYNC["2. Distillation & Verification"]
|
|
24
|
-
direction
|
|
23
|
+
direction LR
|
|
25
24
|
SWEEP["bigquery-data-science sweep<br/>sync-syntax (H2 Slicer)<br/>convert-notebook (Clean MD)<br/>6-Gate CI & Link Audit"]
|
|
26
25
|
CLI["Zero-Dependency CLI & MCP<br/>uvx bigquery-data-science<br/>install · triage · lookup · search · mcp"]
|
|
27
26
|
SWEEP --> CLI
|
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
{
|
|
2
2
|
"$schema": "https://agent-plugins.org/schemas/1.0.0/plugin.schema.json",
|
|
3
3
|
"name": "bigquery-data-science",
|
|
4
|
-
"version": "0.8.
|
|
4
|
+
"version": "0.8.2",
|
|
5
5
|
"description": "BigQuery ML, BigQuery AI, and 4-Lens Agent Skills for SQL and Python data science on Google Cloud: task routing, prerequisite matrix, surgical syntax cards, and 104 live-verified walkthroughs.",
|
|
6
6
|
"author": {
|
|
7
7
|
"name": "Mike Henderson",
|
|
@@ -4,7 +4,7 @@ build-backend = "hatchling.build"
|
|
|
4
4
|
|
|
5
5
|
[project]
|
|
6
6
|
name = "bigquery-data-science"
|
|
7
|
-
version = "0.8.
|
|
7
|
+
version = "0.8.2"
|
|
8
8
|
description = "BigQuery ML, BigQuery AI, and 4-Lens Agent Skills: 104 live-verified SQL/Python workflows, zero-dependency CLI catalog & skill installer, and stdio MCP server."
|
|
9
9
|
dynamic = ["readme"]
|
|
10
10
|
requires-python = ">=3.11"
|
|
@@ -174,7 +174,7 @@ path = "README.md"
|
|
|
174
174
|
|
|
175
175
|
# 1. Swap the front-door Mermaid block with its pre-rendered PNG on PyPI
|
|
176
176
|
[[tool.hatch.metadata.hooks.fancy-pypi-readme.substitutions]]
|
|
177
|
-
pattern = '(?s)```mermaid\nflowchart LR\n.*?```'
|
|
177
|
+
pattern = '(?s)```mermaid\nflowchart (?:LR|TD)\n.*?```'
|
|
178
178
|
replacement = '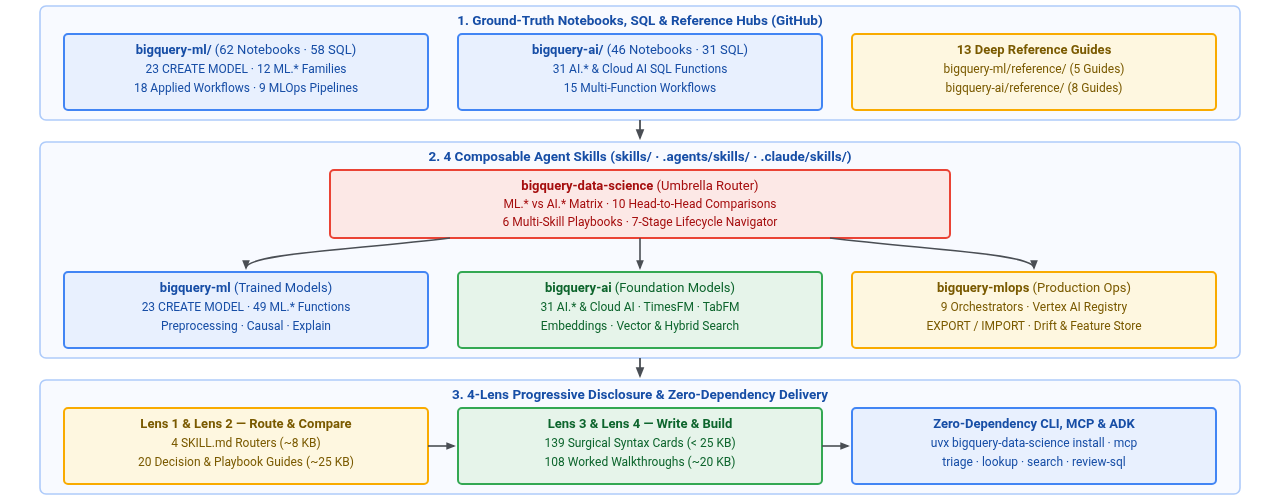'
|
|
179
179
|
|
|
180
180
|
# 2. Rewrite relative Markdown image paths to raw.githubusercontent.com
|
|
@@ -68,12 +68,18 @@ BIN="$WORK/venv/bin"
|
|
|
68
68
|
|
|
69
69
|
[[ -x "$BIN/bigquery-data-science" ]] || fail "bigquery-data-science console script missing in venv"
|
|
70
70
|
|
|
71
|
-
echo "4. Verifying CLI commands (list, install, lookup, triage)..."
|
|
71
|
+
echo "4. Verifying CLI commands (list, install, lookup, triage, bump-version --check)..."
|
|
72
72
|
LIST_OUT="$("$BIN/bigquery-data-science" list)" || fail "bigquery-data-science list failed"
|
|
73
73
|
grep -q "bigquery-data-science" <<<"$LIST_OUT" || fail "list missing bigquery-data-science"
|
|
74
74
|
grep -q "bigquery-ml" <<<"$LIST_OUT" || fail "list missing bigquery-ml"
|
|
75
75
|
grep -q "bigquery-ai" <<<"$LIST_OUT" || fail "list missing bigquery-ai"
|
|
76
76
|
|
|
77
|
+
"$BIN/bigquery-data-science" bump-version --check --repo-root "$REPO_ROOT" >/dev/null || fail "bump-version --check failed"
|
|
78
|
+
"$BIN/bigquery-data-science" check-status-labels "$REPO_ROOT/skills" --repo-root "$REPO_ROOT" >/dev/null || fail "check-status-labels failed"
|
|
79
|
+
"$BIN/bigquery-data-science" check-crossrefs --repo-root "$REPO_ROOT" >/dev/null || fail "check-crossrefs failed"
|
|
80
|
+
"$BIN/bigquery-data-science" check-notebook-claims "$REPO_ROOT" --repo-root "$REPO_ROOT" >/dev/null || fail "check-notebook-claims failed"
|
|
81
|
+
"$BIN/bigquery-data-science" check-markdown --repo-root "$REPO_ROOT" >/dev/null || fail "check-markdown failed"
|
|
82
|
+
|
|
77
83
|
TARGET_DIR="$WORK/installed-skills"
|
|
78
84
|
"$BIN/bigquery-data-science" install --target "$TARGET_DIR" >/dev/null || fail "install failed"
|
|
79
85
|
[[ -f "$TARGET_DIR/bigquery-data-science/SKILL.md" ]] || fail "installed bigquery-data-science/SKILL.md missing"
|
|
@@ -38,7 +38,16 @@ A skill is a directory under `skills/<name>/` (symlinked into `.agents/skills/<n
|
|
|
38
38
|
2. **`reference/<bucket>.md` (Lens 2)** — One file per use-case bucket, organized by what the practitioner is trying to accomplish. Each carries a single H1 heading, a `Contents:` TOC in the first 10 lines when > 100 lines, an options table, selection guidance, verified empirical gotchas, a canonical snippet, and relative links into `../syntax/<slug>.md` and `../narrative/<topic>.md`.
|
|
39
39
|
3. **`syntax/<slug>.md` + `syntax/INDEX.md` (Lens 3)** — Auto-generated from `<domain>/reference/*.md` via `uv run bigquery-data-science sync-syntax`. Never hand-edit `syntax/*.md`; edit the source `<domain>/reference/*.md` page and re-run `sync-syntax`. Every card is verified `< 25,000` bytes.
|
|
40
40
|
4. **`narrative/<topic>.md` (Lens 4)** — Auto-generated from `<domain>/{models,functions,workflows,pipelines}/**/*.ipynb` via `uv run bigquery-data-science sync-narratives` (or `convert-notebook`). Strips the HTML tracker header, `def install(*packages):` helper, Colab auth shim, and trailing `## Cleanup` section while prepending a clickable GitHub provenance banner to the source `.ipynb` and `.sql`.
|
|
41
|
-
5. **`skill.manifest.json`** — Generated via `uv run bigquery-data-science manifest --all --version <version
|
|
41
|
+
5. **`skill.manifest.json`** — Generated via `uv run bigquery-data-science manifest --all --version <version>` (or stamped alongside all lockstep files via `uv run bigquery-data-science bump-version <version>`).
|
|
42
|
+
|
|
43
|
+
### Readability, Visual & Compatibility Standards
|
|
44
|
+
|
|
45
|
+
All skill markdown, domain reference guides, notebooks, and maintainer Python code adhere to four repository-wide standards:
|
|
46
|
+
|
|
47
|
+
1. **100% Additive & Backward-Compatible**: Existing CLI commands, positional arguments, flags, MCP tool names/schemas, Python exports, and skill paths are never incompatibly altered in `0.x` minor or patch releases. New modes use opt-in flags, and new BigQuery features are appended as new numbered examples.
|
|
48
|
+
2. **Simple Code & Simple English**: Python modules use flat control flow, named constants instead of magic literals, and strict `mypy` typing. Prose opens with a plain-English summary (*what it does, when to use it, and what it requires*) and uses scannable tables over dense paragraphs.
|
|
49
|
+
3. **Vertical-First Mermaid Diagrams (`flowchart TD`)**: Orient the longest flow vertically (`flowchart TD`), cap horizontal width at $\le 3$ nodes per rank (stacking wider sets into vertical `subgraph` blocks) so GitHub never shrinks diagram fonts, wrap text at ~35–45 chars with `<br/>`, and quote labels containing special characters (`id["Label (Detail)"]`).
|
|
50
|
+
4. **Clean Markdown & Table Compilation**: Every `.md` file and `.ipynb` markdown cell must compile cleanly with balanced code fences, consistent GFM table column counts across every row, no unescaped `|` characters in cells, and 100% verified relative links and `#anchors`.
|
|
42
51
|
|
|
43
52
|
## Change Types and Checklists
|
|
44
53
|
|
|
@@ -54,10 +63,9 @@ This repository, the Python package, and all three agent skills follow a coordin
|
|
|
54
63
|
- Targeted single-area updates, isolated bug fixes, typo fixes, or individual notebook adjustments.
|
|
55
64
|
|
|
56
65
|
When bumping versions across the repository:
|
|
57
|
-
1.
|
|
58
|
-
2.
|
|
59
|
-
3.
|
|
60
|
-
4. Re-lock dependencies with `UV_NO_CONFIG=1 uv lock`.
|
|
66
|
+
1. Run `uv run bigquery-data-science bump-version X.Y.Z` to stamp `pyproject.toml`, `src/bigquery_data_science/__init__.py`, `CITATION.cff`, `plugin.json`, `.claude-plugin/marketplace.json`, `skills/*/SKILL.md`, `skills/*/skill.manifest.json`, and `tests/test_packaging.py` in lockstep.
|
|
67
|
+
2. Add the `## [X.Y.Z] - YYYY-MM-DD` release section to `CHANGELOG.md`.
|
|
68
|
+
3. Verify parity with `uv run bigquery-data-science bump-version --check` and re-lock dependencies with `UV_NO_CONFIG=1 uv lock`.
|
|
61
69
|
|
|
62
70
|
#### Adding or updating a model, function, or workflow
|
|
63
71
|
- [ ] Update the ground-truth notebook/SQL and `<domain>/reference/*.md` in `bigquery-ml/` or `bigquery-ai/`.
|
|
@@ -2,7 +2,7 @@
|
|
|
2
2
|
name: bigquery-ai
|
|
3
3
|
description: Use when calling Gemini, TimesFM, TabFM, or pre-trained Cloud AI services from BigQuery SQL or BigFrames — generation (AI.GENERATE*, AI.COUNT_TOKENS), managed scoring/classification (AI.IF, AI.SCORE, AI.CLASSIFY, AI.AGG), embeddings and vector/hybrid search (AI.EMBED, VECTOR_SEARCH, AI.SEARCH), forecasting/prediction (AI.FORECAST, AI.PREDICT, AI.KEY_DRIVERS), and Cloud AI service models (ML.PROCESS_DOCUMENT, ML.TRANSLATE, ML.TRANSCRIBE).
|
|
4
4
|
metadata:
|
|
5
|
-
version: "0.8.
|
|
5
|
+
version: "0.8.2"
|
|
6
6
|
---
|
|
7
7
|
|
|
8
8
|
# BigQuery AI (`bigquery-ai`)
|
{bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ai/skill.manifest.json
RENAMED
|
@@ -1,10 +1,10 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "bigquery-ai",
|
|
3
|
-
"version": "0.8.
|
|
3
|
+
"version": "0.8.2",
|
|
4
4
|
"source_project": "bigquery-ai",
|
|
5
5
|
"narrative_sources": {},
|
|
6
|
-
"generated_date": "2026-10-
|
|
7
|
-
"source_commit": "
|
|
6
|
+
"generated_date": "2026-10-21",
|
|
7
|
+
"source_commit": "dcd557e",
|
|
8
8
|
"reference_files": [
|
|
9
9
|
"augmented-analytics.md",
|
|
10
10
|
"cloud-ai-service-models.md",
|
{bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-data-science/SKILL.md
RENAMED
|
@@ -2,7 +2,7 @@
|
|
|
2
2
|
name: bigquery-data-science
|
|
3
3
|
description: "Use FIRST when someone wants to predict, classify, forecast, embed, search, extract, or explain data in BigQuery and needs to choose between a trained model (bigquery-ml — CREATE MODEL + ML.*), a zero-training generative or foundation model function (bigquery-ai — AI.* + TimesFM + TabFM), or a pre-trained Google Cloud AI service model (ML.PROCESS_DOCUMENT, ML.TRANSLATE, ML.UNDERSTAND_TEXT, ML.ANNOTATE_IMAGE, ML.TRANSCRIBE)."
|
|
4
4
|
metadata:
|
|
5
|
-
version: "0.8.
|
|
5
|
+
version: "0.8.2"
|
|
6
6
|
---
|
|
7
7
|
|
|
8
8
|
# BigQuery Data Science — Umbrella Router & Triage (`bigquery-data-science`)
|
|
@@ -35,8 +35,8 @@ Most BigQuery ML and BigQuery AI features run on standard on-demand pricing, **e
|
|
|
35
35
|
| `RANDOM_FOREST_REGRESSOR` | `bigquery-ml` | Regression | None | On-demand OK | GA | `bigquery-ml/narrative/random_forest_regressor.md` |
|
|
36
36
|
| `DNN_CLASSIFIER` | `bigquery-ml` | Deep Neural Network | None | On-demand OK | GA | `bigquery-ml/narrative/dnn_classifier.md` |
|
|
37
37
|
| `DNN_REGRESSOR` | `bigquery-ml` | Deep Neural Network | None | On-demand OK | GA | `bigquery-ml/narrative/dnn_regressor.md` |
|
|
38
|
-
| `WIDE_AND_DEEP_CLASSIFIER` | `bigquery-ml` | Wide & Deep Network | None | On-demand OK | GA | `bigquery-ml/narrative/wide_and_deep_classifier.md` |
|
|
39
|
-
| `WIDE_AND_DEEP_REGRESSOR` | `bigquery-ml` | Wide & Deep Network | None | On-demand OK | GA | `bigquery-ml/narrative/wide_and_deep_regressor.md` |
|
|
38
|
+
| `WIDE_AND_DEEP_CLASSIFIER` / `DNN_LINEAR_COMBINED_CLASSIFIER` | `bigquery-ml` | Wide & Deep Network | None | On-demand OK | GA | `bigquery-ml/narrative/wide_and_deep_classifier.md` |
|
|
39
|
+
| `WIDE_AND_DEEP_REGRESSOR` / `DNN_LINEAR_COMBINED_REGRESSOR` | `bigquery-ml` | Wide & Deep Network | None | On-demand OK | GA | `bigquery-ml/narrative/wide_and_deep_regressor.md` |
|
|
40
40
|
| `AUTOML_CLASSIFIER` | `bigquery-ml` | AutoML Tabular | None | On-demand OK | GA | `bigquery-ml/narrative/automl_classifier.md` |
|
|
41
41
|
| `AUTOML_REGRESSOR` | `bigquery-ml` | AutoML Tabular | None | On-demand OK | GA | `bigquery-ml/narrative/automl_regressor.md` |
|
|
42
42
|
| `ARIMA_PLUS` | `bigquery-ml` | Univariate Forecasting (`TIME_SERIES_TIMESTAMP_COL`, `TIME_SERIES_DATA_COL`) | None | On-demand OK | GA | `bigquery-ml/narrative/arima_plus.md` |
|
|
@@ -48,7 +48,7 @@ Most BigQuery ML and BigQuery AI features run on standard on-demand pricing, **e
|
|
|
48
48
|
| `CONTRIBUTION_ANALYSIS` | `bigquery-ml` | Driver Attribution | None | On-demand OK | GA | `bigquery-ml/narrative/contribution_analysis.md` |
|
|
49
49
|
| `TRANSFORM_ONLY` | `bigquery-ml` | Reusable Feature Pipeline | None | On-demand OK | GA | `bigquery-ml/narrative/transform_only.md` |
|
|
50
50
|
| `TENSORFLOW` / `ONNX` / `XGBOOST` / `TENSORFLOW_LITE` | `bigquery-ml` | Imported GCS Models | Optional (for Object Tables) | On-demand OK | GA | `bigquery-ml/narrative/imported.md` |
|
|
51
|
-
| `REMOTE WITH CONNECTION` (`endpoint`) | `bigquery-ml` | Vertex AI Endpoint | `CLOUD_RESOURCE` (`roles/aiplatform.user`) | On-demand OK | GA | `bigquery-ml/narrative/remote.md` |
|
|
51
|
+
| `REMOTE` / `REMOTE WITH CONNECTION` (`endpoint`) | `bigquery-ml` | Vertex AI Endpoint | `CLOUD_RESOURCE` (`roles/aiplatform.user`) | On-demand OK | GA | `bigquery-ml/narrative/remote.md` |
|
|
52
52
|
|
|
53
53
|
## Model Lifecycle & Model-Free Functions (`ML.*` in `bigquery-ml`)
|
|
54
54
|
|
|
@@ -67,12 +67,13 @@ Most BigQuery ML and BigQuery AI features run on standard on-demand pricing, **e
|
|
|
67
67
|
| `ML.GET_INSIGHTS` | `bigquery-ml` | Contribution Analysis Output | None | On-demand OK | GA | `bigquery-ml/narrative/contribution_analysis.md` |
|
|
68
68
|
| `ML.EXPLAIN_PREDICT` / `ML.GLOBAL_EXPLAIN` / `ML.FEATURE_IMPORTANCE` / `ML.WEIGHTS` / `ML.ADVANCED_WEIGHTS` | `bigquery-ml` | Explainability & Weights | None | On-demand OK | GA | `bigquery-ml/narrative/evaluation.md` |
|
|
69
69
|
| `ML.FEATURES_AT_TIME` / `ML.ENTITY_FEATURES_AT_TIME` | `bigquery-ml` | Point-in-Time Feature Store | None | On-demand OK | GA | `bigquery-ml/narrative/feature_store.md` |
|
|
70
|
-
| `ML.DESCRIBE_DATA` / `ML.CORRELATION`
|
|
70
|
+
| `ML.DESCRIBE_DATA` / `ML.CORRELATION` | `bigquery-ml` | Exploratory Data Analysis | None | On-demand OK | GA / Preview | `bigquery-ml/narrative/exploration.md` |
|
|
71
|
+
| `ML.TF_IDF` / `ML.NGRAMS` / `ML.BAG_OF_WORDS` | `bigquery-ml` | Text Feature Extraction | None | On-demand OK | GA | `bigquery-ml/narrative/text.md` |
|
|
71
72
|
| `ML.STANDARD_SCALER` / `ML.MIN_MAX_SCALER` / `ML.ROBUST_SCALER` / `ML.MAX_ABS_SCALER` / `ML.NORMALIZER` | `bigquery-ml` | Numerical Scaling | None | On-demand OK | GA | `bigquery-ml/narrative/scalers.md` |
|
|
72
|
-
| `ML.ONE_HOT_ENCODER` / `ML.LABEL_ENCODER` / `ML.
|
|
73
|
-
| `ML.BUCKETIZE` / `ML.QUANTILE_BUCKETIZE` / `ML.IMPUTER` / `ML.POLYNOMIAL_EXPAND` / `ML.FEATURE_CROSS` | `bigquery-ml` | Bucketizing & Feature Crosses | None | On-demand OK | GA | `bigquery-ml/narrative/bucketizing.md` |
|
|
74
|
-
| `ML.LP_NORM` / `ML.DISTANCE` / `ML.COSINE_DISTANCE` / `ML.EUCLIDEAN_DISTANCE` / `ML.MANHATTAN_DISTANCE` / `ML.EDIT_DISTANCE` | `bigquery-ml` | Vector & String Distances | None | On-demand OK | GA
|
|
75
|
-
| `ML.DECODE_IMAGE` / `ML.RESIZE_IMAGE` / `ML.CONVERT_COLOR_SPACE` / `ML.CONVERT_IMAGE_TYPE` | `bigquery-ml` | SQL Image Preprocessing | Optional (Object Table) | **Enterprise Reservation (`QUERY`)** |
|
|
73
|
+
| `ML.ONE_HOT_ENCODER` / `ML.LABEL_ENCODER` / `ML.MULTI_HOT_ENCODER` | `bigquery-ml` | Categorical Encoding | None | On-demand OK | GA | `bigquery-ml/narrative/encoding.md` |
|
|
74
|
+
| `ML.BUCKETIZE` / `ML.QUANTILE_BUCKETIZE` / `ML.HASH_BUCKETIZE` / `ML.IMPUTER` / `ML.POLYNOMIAL_EXPAND` / `ML.FEATURE_CROSS` | `bigquery-ml` | Bucketizing & Feature Crosses | None | On-demand OK | GA | `bigquery-ml/narrative/bucketizing.md` |
|
|
75
|
+
| `ML.LP_NORM` / `ML.DISTANCE` / `ML.COSINE_DISTANCE` / `ML.EUCLIDEAN_DISTANCE` / `ML.MANHATTAN_DISTANCE` / `ML.EDIT_DISTANCE` | `bigquery-ml` | Vector & String Distances | None | On-demand OK | GA | `bigquery-ml/narrative/distance.md` |
|
|
76
|
+
| `ML.DECODE_IMAGE` / `ML.RESIZE_IMAGE` / `ML.CONVERT_COLOR_SPACE` / `ML.CONVERT_IMAGE_TYPE` | `bigquery-ml` | SQL Image Preprocessing | Optional (Object Table) | **Enterprise Reservation (`QUERY`)** | GA | `bigquery-ml/narrative/image.md` |
|
|
76
77
|
| `ML.VALIDATE_DATA_DRIFT` / `ML.VALIDATE_DATA_SKEW` / `ML.TFDV_DESCRIBE` / `ML.TFDV_VALIDATE` | `bigquery-ml` | Data Drift & Skew Monitoring | None | On-demand OK | GA | `bigquery-ml/narrative/model_monitoring.md` |
|
|
77
78
|
|
|
78
79
|
## Generative, Foundation & Managed Functions (`AI.*` & `VECTOR_SEARCH` in `bigquery-ai`)
|
|
@@ -84,15 +85,15 @@ Most BigQuery ML and BigQuery AI features run on standard on-demand pricing, **e
|
|
|
84
85
|
| `AI.GENERATE_TABLE` | `bigquery-ai` | Structured TVF Generation | `CLOUD_RESOURCE` (`roles/aiplatform.user`) | On-demand OK | GA | `bigquery-ai/narrative/ai_generate_table.md` |
|
|
85
86
|
| `AI.GENERATE_TEXT` / `ML.GENERATE_TEXT` | `bigquery-ai` | Remote Model Text TVF | `CLOUD_RESOURCE` (`roles/aiplatform.user`) | On-demand OK | GA | `bigquery-ai/narrative/ai_generate_text.md` |
|
|
86
87
|
| `AI.COUNT_TOKENS` | `bigquery-ai` | Local Token Estimator | None | On-demand OK | Preview | `bigquery-ai/narrative/ai_count_tokens.md` |
|
|
87
|
-
| `AI.IF` | `bigquery-ai` | Managed Boolean Filter | End-user creds (Connection optional) | On-demand OK |
|
|
88
|
-
| `AI.SCORE` | `bigquery-ai` | Managed Numeric Rubric Scorer | End-user creds (Connection optional) | On-demand OK |
|
|
89
|
-
| `AI.CLASSIFY` | `bigquery-ai` | Managed Category Classifier | End-user creds (Connection optional) | On-demand OK |
|
|
90
|
-
| `AI.AGG` | `bigquery-ai` | Managed Aggregate Synthesis | End-user creds (Connection optional) | On-demand OK |
|
|
91
|
-
| `AI.EMBED` | `bigquery-ai` | Scalar Text / Multimodal Embedding | None for `embeddinggemma-300m`; Connection for multimodal | On-demand OK |
|
|
88
|
+
| `AI.IF` | `bigquery-ai` | Managed Boolean Filter | End-user creds (Connection optional) | On-demand OK | Preview | `bigquery-ai/narrative/ai_if.md` |
|
|
89
|
+
| `AI.SCORE` | `bigquery-ai` | Managed Numeric Rubric Scorer | End-user creds (Connection optional) | On-demand OK | Preview | `bigquery-ai/narrative/ai_score.md` |
|
|
90
|
+
| `AI.CLASSIFY` | `bigquery-ai` | Managed Category Classifier | End-user creds (Connection optional) | On-demand OK | Preview | `bigquery-ai/narrative/ai_classify.md` |
|
|
91
|
+
| `AI.AGG` | `bigquery-ai` | Managed Aggregate Synthesis | End-user creds (Connection optional) | On-demand OK | GA | `bigquery-ai/narrative/ai_agg.md` |
|
|
92
|
+
| `AI.EMBED` | `bigquery-ai` | Scalar Text / Multimodal Embedding | None for `embeddinggemma-300m`; Connection for multimodal | On-demand OK | Preview | `bigquery-ai/narrative/ai_embed.md` |
|
|
92
93
|
| `AI.GENERATE_EMBEDDING` / `ML.GENERATE_EMBEDDING` | `bigquery-ai` | Remote Model Embedding TVF | `CLOUD_RESOURCE` (`roles/aiplatform.user`) | On-demand OK | GA | `bigquery-ai/narrative/ai_generate_embedding.md` |
|
|
93
|
-
| `AI.SIMILARITY` | `bigquery-ai` | Scalar Pairwise Semantic Similarity | None for `embeddinggemma-300m`; Connection for multimodal | On-demand OK |
|
|
94
|
+
| `AI.SIMILARITY` | `bigquery-ai` | Scalar Pairwise Semantic Similarity | None for `embeddinggemma-300m`; Connection for multimodal | On-demand OK | Preview | `bigquery-ai/narrative/ai_similarity.md` |
|
|
94
95
|
| `VECTOR_SEARCH` | `bigquery-ai` | Vector & Hybrid RRF Search TVF | Only when query embedding uses remote model | On-demand OK (`ALTER VECTOR INDEX` needs Enterprise `BACKGROUND`) | GA / Preview (hybrid) | `bigquery-ai/narrative/vector_search.md` |
|
|
95
|
-
| `AI.SEARCH` | `bigquery-ai` | Simplified Autonomous Search TVF | None (autonomous embedding column) | On-demand OK | Preview | `bigquery-ai/narrative/ai_search.md` |
|
|
96
|
+
| `AI.SEARCH` | `bigquery-ai` | Simplified Autonomous Search TVF | None (autonomous embedding column) | On-demand OK | GA (`mode` Preview) | `bigquery-ai/narrative/ai_search.md` |
|
|
96
97
|
| `AI.FORECAST` | `bigquery-ai` | Zero-Training TimesFM Forecasting | None | On-demand OK | GA (2.5) / Preview (3.0) | `bigquery-ai/narrative/ai_forecast.md` |
|
|
97
98
|
| `AI.DETECT_ANOMALIES` | `bigquery-ai` | Zero-Training TimesFM Anomalies | None | On-demand OK | GA | `bigquery-ai/narrative/ai_detect_anomalies.md` |
|
|
98
99
|
| `AI.EVALUATE` | `bigquery-ai` | Zero-Training TimesFM / TabFM Eval | None | On-demand OK | GA (TS) / Preview (TabFM) | `bigquery-ai/narrative/ai_evaluate.md` |
|
|
@@ -1,10 +1,10 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "bigquery-data-science",
|
|
3
|
-
"version": "0.8.
|
|
3
|
+
"version": "0.8.2",
|
|
4
4
|
"source_project": null,
|
|
5
5
|
"narrative_sources": {},
|
|
6
|
-
"generated_date": "2026-10-
|
|
7
|
-
"source_commit": "
|
|
6
|
+
"generated_date": "2026-10-21",
|
|
7
|
+
"source_commit": "dcd557e",
|
|
8
8
|
"reference_files": [
|
|
9
9
|
"namespace-matrix.md"
|
|
10
10
|
],
|
|
@@ -2,7 +2,7 @@
|
|
|
2
2
|
name: bigquery-ml
|
|
3
3
|
description: Use when training, evaluating, deploying, or monitoring a machine learning model in BigQuery with SQL (CREATE MODEL and ML.* functions) — picking a model type, choosing a preprocessing function, point-in-time feature retrieval, causal inference (including AI.CAUSAL_EFFECT), or production retraining pipelines across 23 model types, 49 functions, 18 workflows, and 8 pipelines.
|
|
4
4
|
metadata:
|
|
5
|
-
version: "0.8.
|
|
5
|
+
version: "0.8.2"
|
|
6
6
|
---
|
|
7
7
|
|
|
8
8
|
# BigQuery ML (`bigquery-ml`)
|
|
@@ -43,7 +43,7 @@ Both require the feature table to have a `STRING` column named `entity_id` and a
|
|
|
43
43
|
| `ML.MIN_MAX_SCALER` | `(x - MIN) / (MAX - MIN)` → `[0,1]` | Need a bounded range; sensitive to outliers (a single extreme value compresses everything else). |
|
|
44
44
|
| `ML.MAX_ABS_SCALER` | `x / MAX(ABS(x))` → `[-1,1]` | Sparse/sign-bearing data where you must not shift/center (no subtraction of a mean/median). |
|
|
45
45
|
| `ML.ROBUST_SCALER` | `(x - median) / (q_hi - q_lo)`, default IQR `[25,75]` | Data with outliers — median/IQR aren't dragged around by extreme values the way mean/stddev or min/max are. |
|
|
46
|
-
| `ML.NORMALIZER` | Row-wise: `x_i /
|
|
46
|
+
| `ML.NORMALIZER` | Row-wise: `x_i / ML.LP_NORM(vector, p)` | Not a column scaler at all — normalizes each row's `ARRAY` to unit p-norm (e.g., embedding-like vectors). Scalar, no `OVER()`. |
|
|
47
47
|
|
|
48
48
|
The first four are **analytic** (mandatory empty `OVER()`); `ML.NORMALIZER` is **scalar** (no `OVER()`, operates within one row's array).
|
|
49
49
|
|
{bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/skills/bigquery-ml/skill.manifest.json
RENAMED
|
@@ -1,13 +1,13 @@
|
|
|
1
1
|
{
|
|
2
2
|
"name": "bigquery-ml",
|
|
3
|
-
"version": "0.8.
|
|
3
|
+
"version": "0.8.2",
|
|
4
4
|
"source_project": "bigquery-ml",
|
|
5
5
|
"narrative_sources": {
|
|
6
6
|
"feature_store.md": "functions/feature_store/feature_store.ipynb",
|
|
7
7
|
"feature_store_workflow.md": "workflows/feature_store/feature_store.ipynb"
|
|
8
8
|
},
|
|
9
|
-
"generated_date": "2026-10-
|
|
10
|
-
"source_commit": "
|
|
9
|
+
"generated_date": "2026-10-21",
|
|
10
|
+
"source_commit": "dcd557e",
|
|
11
11
|
"reference_files": [
|
|
12
12
|
"classification.md",
|
|
13
13
|
"model-management.md",
|
{bigquery_data_science-0.8.0 → bigquery_data_science-0.8.2}/src/bigquery_data_science/__init__.py
RENAMED
|
@@ -4,6 +4,11 @@ from __future__ import annotations
|
|
|
4
4
|
|
|
5
5
|
from importlib.metadata import PackageNotFoundError, version
|
|
6
6
|
|
|
7
|
+
try:
|
|
8
|
+
__version__ = version("bigquery-data-science")
|
|
9
|
+
except PackageNotFoundError:
|
|
10
|
+
__version__ = "0.8.2"
|
|
11
|
+
|
|
7
12
|
from bigquery_data_science.catalog import (
|
|
8
13
|
LookupResult,
|
|
9
14
|
SearchHit,
|
|
@@ -27,11 +32,6 @@ from bigquery_data_science.installer import (
|
|
|
27
32
|
list_bundled_skills,
|
|
28
33
|
)
|
|
29
34
|
|
|
30
|
-
try:
|
|
31
|
-
__version__ = version("bigquery-data-science")
|
|
32
|
-
except PackageNotFoundError:
|
|
33
|
-
__version__ = "0.8.0"
|
|
34
|
-
|
|
35
35
|
list_skills = list_bundled_skills
|
|
36
36
|
|
|
37
37
|
__all__ = [
|