bettertrees 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- bettertrees-0.1.0/CHANGELOG.md +36 -0
- bettertrees-0.1.0/CITATION.cff +16 -0
- bettertrees-0.1.0/LICENSE +29 -0
- bettertrees-0.1.0/MANIFEST.in +12 -0
- bettertrees-0.1.0/PKG-INFO +368 -0
- bettertrees-0.1.0/README.md +311 -0
- bettertrees-0.1.0/docs/ITM_INTERACTIONS.md +35 -0
- bettertrees-0.1.0/docs/export.md +42 -0
- bettertrees-0.1.0/docs/images/frontier.png +0 -0
- bettertrees-0.1.0/docs/images/scoreboard.png +0 -0
- bettertrees-0.1.0/docs/images/scorecard.png +0 -0
- bettertrees-0.1.0/docs/typing.md +28 -0
- bettertrees-0.1.0/examples/01_quickstart.ipynb +403 -0
- bettertrees-0.1.0/examples/02_interpretation.ipynb +650 -0
- bettertrees-0.1.0/examples/03_editing.ipynb +530 -0
- bettertrees-0.1.0/examples/credit_data.py +44 -0
- bettertrees-0.1.0/pyproject.toml +101 -0
- bettertrees-0.1.0/setup.cfg +4 -0
- bettertrees-0.1.0/src/bettertrees/__init__.py +57 -0
- bettertrees-0.1.0/src/bettertrees/_data.py +115 -0
- bettertrees-0.1.0/src/bettertrees/_typing.py +20 -0
- bettertrees-0.1.0/src/bettertrees/autotune.py +193 -0
- bettertrees-0.1.0/src/bettertrees/bins.py +247 -0
- bettertrees-0.1.0/src/bettertrees/builder.py +309 -0
- bettertrees-0.1.0/src/bettertrees/estimator.py +607 -0
- bettertrees-0.1.0/src/bettertrees/experimental/__init__.py +36 -0
- bettertrees-0.1.0/src/bettertrees/experimental/_itm_kernels.py +7 -0
- bettertrees-0.1.0/src/bettertrees/experimental/_oblique_kernels.py +29 -0
- bettertrees-0.1.0/src/bettertrees/experimental/distill.py +7 -0
- bettertrees-0.1.0/src/bettertrees/experimental/interactions.py +7 -0
- bettertrees-0.1.0/src/bettertrees/experimental/itm.py +7 -0
- bettertrees-0.1.0/src/bettertrees/experimental/oblique.py +612 -0
- bettertrees-0.1.0/src/bettertrees/experimental/precision.py +60 -0
- bettertrees-0.1.0/src/bettertrees/experimental/ratios.py +7 -0
- bettertrees-0.1.0/src/bettertrees/experimental/rulefit.py +7 -0
- bettertrees-0.1.0/src/bettertrees/kernels.py +1277 -0
- bettertrees-0.1.0/src/bettertrees/lab/__init__.py +50 -0
- bettertrees-0.1.0/src/bettertrees/lab/_itm_kernels.py +199 -0
- bettertrees-0.1.0/src/bettertrees/lab/distill.py +232 -0
- bettertrees-0.1.0/src/bettertrees/lab/interactions.py +68 -0
- bettertrees-0.1.0/src/bettertrees/lab/itm.py +726 -0
- bettertrees-0.1.0/src/bettertrees/lab/multilevel.py +400 -0
- bettertrees-0.1.0/src/bettertrees/lab/ratios.py +119 -0
- bettertrees-0.1.0/src/bettertrees/lab/robust.py +402 -0
- bettertrees-0.1.0/src/bettertrees/lab/rulefit.py +245 -0
- bettertrees-0.1.0/src/bettertrees/multilevel.py +7 -0
- bettertrees-0.1.0/src/bettertrees/postprocess.py +300 -0
- bettertrees-0.1.0/src/bettertrees/py.typed +0 -0
- bettertrees-0.1.0/src/bettertrees/search.py +388 -0
- bettertrees-0.1.0/src/bettertrees/splitters.py +191 -0
- bettertrees-0.1.0/src/bettertrees/sums/__init__.py +49 -0
- bettertrees-0.1.0/src/bettertrees/sums/_common.py +195 -0
- bettertrees-0.1.0/src/bettertrees/sums/_kernels.py +847 -0
- bettertrees-0.1.0/src/bettertrees/sums/additive.py +270 -0
- bettertrees-0.1.0/src/bettertrees/sums/budget.py +111 -0
- bettertrees-0.1.0/src/bettertrees/sums/budget.pyi +49 -0
- bettertrees-0.1.0/src/bettertrees/sums/compact.py +429 -0
- bettertrees-0.1.0/src/bettertrees/sums/edit.py +432 -0
- bettertrees-0.1.0/src/bettertrees/sums/explain.py +500 -0
- bettertrees-0.1.0/src/bettertrees/sums/imported.py +249 -0
- bettertrees-0.1.0/src/bettertrees/sums/prune.py +91 -0
- bettertrees-0.1.0/src/bettertrees/sums/robust.py +7 -0
- bettertrees-0.1.0/src/bettertrees/sums/screen.py +102 -0
- bettertrees-0.1.0/src/bettertrees/sums/smalltrees.py +668 -0
- bettertrees-0.1.0/src/bettertrees.egg-info/PKG-INFO +368 -0
- bettertrees-0.1.0/src/bettertrees.egg-info/SOURCES.txt +101 -0
- bettertrees-0.1.0/src/bettertrees.egg-info/dependency_links.txt +1 -0
- bettertrees-0.1.0/src/bettertrees.egg-info/requires.txt +36 -0
- bettertrees-0.1.0/src/bettertrees.egg-info/top_level.txt +1 -0
- bettertrees-0.1.0/tests/_core.py +111 -0
- bettertrees-0.1.0/tests/_reference.py +405 -0
- bettertrees-0.1.0/tests/_sklearn_checks.py +26 -0
- bettertrees-0.1.0/tests/test_autotune.py +203 -0
- bettertrees-0.1.0/tests/test_binary_edges.py +20 -0
- bettertrees-0.1.0/tests/test_compat_imports.py +81 -0
- bettertrees-0.1.0/tests/test_degenerate.py +110 -0
- bettertrees-0.1.0/tests/test_edit.py +192 -0
- bettertrees-0.1.0/tests/test_edit_more.py +124 -0
- bettertrees-0.1.0/tests/test_export.py +106 -0
- bettertrees-0.1.0/tests/test_figs_fast_path.py +156 -0
- bettertrees-0.1.0/tests/test_imported.py +148 -0
- bettertrees-0.1.0/tests/test_interleaved_name.py +31 -0
- bettertrees-0.1.0/tests/test_invariants.py +197 -0
- bettertrees-0.1.0/tests/test_itm.py +388 -0
- bettertrees-0.1.0/tests/test_multilevel.py +291 -0
- bettertrees-0.1.0/tests/test_oblique.py +336 -0
- bettertrees-0.1.0/tests/test_package_smoke.py +58 -0
- bettertrees-0.1.0/tests/test_prune.py +45 -0
- bettertrees-0.1.0/tests/test_robust.py +144 -0
- bettertrees-0.1.0/tests/test_row_hist.py +55 -0
- bettertrees-0.1.0/tests/test_sums.py +525 -0
- bettertrees-0.1.0/tests/test_sums_api.py +212 -0
- bettertrees-0.1.0/tests/test_to_sql.py +35 -0
- bettertrees-0.1.0/tests/test_tree.py +1083 -0
- bettertrees-0.1.0/tests/test_weight_contract.py +40 -0
- bettertrees-0.1.0/tests/tree_invariants.py +591 -0
- bettertrees-0.1.0/tools/build_examples.py +284 -0
- bettertrees-0.1.0/tools/check_distribution.py +110 -0
- bettertrees-0.1.0/tools/check_readme.py +35 -0
- bettertrees-0.1.0/tools/equivalence.py +63 -0
- bettertrees-0.1.0/tools/predict_export.py +79 -0
- bettertrees-0.1.0/tools/reference.npz +0 -0
- bettertrees-0.1.0/tools/typing_smoke.py +52 -0
|
@@ -0,0 +1,36 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
## 0.1.0 (unreleased)
|
|
4
|
+
|
|
5
|
+
First public release. Tested on Python 3.10 and 3.14 (numpy 2.2 to 2.5, scikit-learn 1.7 to 1.9,
|
|
6
|
+
numba 0.68); declared for Python 3.10 to 3.14.
|
|
7
|
+
|
|
8
|
+
- `BudgetClassifier(max_splits=b)`: the Interleaved Tree Model with a fixed rule per cut
|
|
9
|
+
budget, no tuning (evaluated from 4 to 64 cuts; applied unvalidated above).
|
|
10
|
+
- `InterleavedTreeClassifier`, the Interleaved Tree Model (ITM): a logit sum of small trees
|
|
11
|
+
grown together under a budget of cuts (internal nodes), with Newton leaves and a refit of every
|
|
12
|
+
leaf after each cut. `FIGSClassifier` is an alias.
|
|
13
|
+
- Other sums: `SumOfOptimalTrees` (optimal depth-1 to depth-3 trees), `CompactTreeBooster`,
|
|
14
|
+
`AdditiveTreeBooster`, and `LightGBMRefitClassifier` / `from_lightgbm` (a LightGBM model
|
|
15
|
+
as an editable sum).
|
|
16
|
+
- Single trees: `FastDecisionTreeClassifier` and `FastDecisionTreeClassifierCV` (leaf count
|
|
17
|
+
and hierarchical shrinkage chosen by cross-validation).
|
|
18
|
+
- Reading a sum: `explain`, `rules`, `to_dict`, `to_sql`, `get_trees`, `export_text`,
|
|
19
|
+
`predict_contributions`, `plot_contributions`, `plot_shapes`, `to_shap_model`.
|
|
20
|
+
- Editing a sum: `prune`, `set_cut`, `split_leaf`, `add_stump`, `drop_tree`,
|
|
21
|
+
`merge_duplicates`, `set_leaf_value`, `refit_leaves` (partial refit, monotone
|
|
22
|
+
constraints), `monotone_violations`, `cut_alternatives`.
|
|
23
|
+
- `bettertrees.experimental` (no API guarantee): `ObliqueFIGSClassifier`,
|
|
24
|
+
`PrecisionTreeClassifier`.
|
|
25
|
+
- `bettertrees.lab`: research code with negative or inconclusive results, kept so the
|
|
26
|
+
benchmark can be reproduced; not part of the public API.
|
|
27
|
+
- Duplicate-tree merging preserves leaf paths after manual edits. LightGBM imports
|
|
28
|
+
retain float64 input precision and reject unsupported missing-value semantics
|
|
29
|
+
and models exceeding the internal bin capacity.
|
|
30
|
+
- JSON exports include exact numeric bins and trees with a standalone evaluator;
|
|
31
|
+
rounded rules remain available for reading.
|
|
32
|
+
- Zero-weight rows are excluded before binning and cross-validation; conversion
|
|
33
|
+
overflow and invalid cut budgets are rejected explicitly.
|
|
34
|
+
- Public type hints for the high-level API, the `py.typed` marker, a `budget.pyi` stub for
|
|
35
|
+
the delegating `BudgetClassifier`, and a downstream `mypy` check in CI; no new runtime
|
|
36
|
+
dependencies.
|
|
@@ -0,0 +1,16 @@
|
|
|
1
|
+
cff-version: 1.2.0
|
|
2
|
+
message: "If you use bettertrees, please cite it as below. A paper is in preparation; this entry will point to it once it is out."
|
|
3
|
+
title: "bettertrees: Interleaved Tree Models for binary classification under a budget of cuts"
|
|
4
|
+
type: software
|
|
5
|
+
authors:
|
|
6
|
+
- given-names: "Rafael"
|
|
7
|
+
family-names: "do Prado Silva"
|
|
8
|
+
version: 0.1.0
|
|
9
|
+
license: BSD-3-Clause
|
|
10
|
+
repository-code: "https://github.com/rafapras/bettertrees"
|
|
11
|
+
keywords:
|
|
12
|
+
- decision trees
|
|
13
|
+
- interpretable machine learning
|
|
14
|
+
- sums of trees
|
|
15
|
+
- credit scoring
|
|
16
|
+
- scikit-learn
|
|
@@ -0,0 +1,29 @@
|
|
|
1
|
+
BSD 3-Clause License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026, The bettertrees developers
|
|
4
|
+
All rights reserved.
|
|
5
|
+
|
|
6
|
+
Redistribution and use in source and binary forms, with or without
|
|
7
|
+
modification, are permitted provided that the following conditions are met:
|
|
8
|
+
|
|
9
|
+
1. Redistributions of source code must retain the above copyright notice, this
|
|
10
|
+
list of conditions and the following disclaimer.
|
|
11
|
+
|
|
12
|
+
2. Redistributions in binary form must reproduce the above copyright notice,
|
|
13
|
+
this list of conditions and the following disclaimer in the documentation
|
|
14
|
+
and/or other materials provided with the distribution.
|
|
15
|
+
|
|
16
|
+
3. Neither the name of the copyright holder nor the names of its
|
|
17
|
+
contributors may be used to endorse or promote products derived from
|
|
18
|
+
this software without specific prior written permission.
|
|
19
|
+
|
|
20
|
+
THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS "AS IS"
|
|
21
|
+
AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE
|
|
22
|
+
IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE
|
|
23
|
+
DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT HOLDER OR CONTRIBUTORS BE LIABLE
|
|
24
|
+
FOR ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL
|
|
25
|
+
DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR
|
|
26
|
+
SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER
|
|
27
|
+
CAUSED AND ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY,
|
|
28
|
+
OR TORT (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
|
|
29
|
+
OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
|
@@ -0,0 +1,12 @@
|
|
|
1
|
+
# source distribution: the package plus what is needed to test and read it
|
|
2
|
+
include CHANGELOG.md CITATION.cff
|
|
3
|
+
recursive-include src *.pyi py.typed
|
|
4
|
+
recursive-include tests *.py
|
|
5
|
+
recursive-include examples *.py *.ipynb
|
|
6
|
+
recursive-include tools *.py *.npz
|
|
7
|
+
include docs/*.md
|
|
8
|
+
recursive-include docs/images *.png
|
|
9
|
+
# reference material kept on disk, never shipped
|
|
10
|
+
prune docs/paper
|
|
11
|
+
prune docs/reference
|
|
12
|
+
global-exclude *.py[cod] __pycache__ *.nbc *.nbi
|
|
@@ -0,0 +1,368 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: bettertrees
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Interleaved Tree Models: small, readable sums of trees for binary classification under a budget of cuts
|
|
5
|
+
Author: Rafael do Prado Silva
|
|
6
|
+
License-Expression: BSD-3-Clause
|
|
7
|
+
Project-URL: Homepage, https://github.com/rafapras/bettertrees
|
|
8
|
+
Project-URL: Repository, https://github.com/rafapras/bettertrees
|
|
9
|
+
Project-URL: Issues, https://github.com/rafapras/bettertrees/issues
|
|
10
|
+
Project-URL: Changelog, https://github.com/rafapras/bettertrees/blob/main/CHANGELOG.md
|
|
11
|
+
Keywords: decision trees,interpretable machine learning,FIGS,sum of trees,credit scoring,scikit-learn
|
|
12
|
+
Classifier: Development Status :: 4 - Beta
|
|
13
|
+
Classifier: Intended Audience :: Science/Research
|
|
14
|
+
Classifier: Intended Audience :: Financial and Insurance Industry
|
|
15
|
+
Classifier: Operating System :: OS Independent
|
|
16
|
+
Classifier: Programming Language :: Python :: 3
|
|
17
|
+
Classifier: Programming Language :: Python :: 3 :: Only
|
|
18
|
+
Classifier: Programming Language :: Python :: 3.10
|
|
19
|
+
Classifier: Programming Language :: Python :: 3.11
|
|
20
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
21
|
+
Classifier: Programming Language :: Python :: 3.13
|
|
22
|
+
Classifier: Programming Language :: Python :: 3.14
|
|
23
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
24
|
+
Requires-Python: >=3.10
|
|
25
|
+
Description-Content-Type: text/markdown
|
|
26
|
+
License-File: LICENSE
|
|
27
|
+
Requires-Dist: numpy<3,>=1.26
|
|
28
|
+
Requires-Dist: numba>=0.60
|
|
29
|
+
Requires-Dist: scikit-learn<2,>=1.6
|
|
30
|
+
Provides-Extra: lightgbm
|
|
31
|
+
Requires-Dist: lightgbm>=4.0; extra == "lightgbm"
|
|
32
|
+
Provides-Extra: plot
|
|
33
|
+
Requires-Dist: matplotlib>=3.8; extra == "plot"
|
|
34
|
+
Provides-Extra: shap
|
|
35
|
+
Requires-Dist: shap>=0.45; extra == "shap"
|
|
36
|
+
Provides-Extra: all
|
|
37
|
+
Requires-Dist: lightgbm>=4.0; extra == "all"
|
|
38
|
+
Requires-Dist: matplotlib>=3.8; extra == "all"
|
|
39
|
+
Requires-Dist: shap>=0.45; extra == "all"
|
|
40
|
+
Requires-Dist: pandas>=2.0; extra == "all"
|
|
41
|
+
Provides-Extra: test
|
|
42
|
+
Requires-Dist: pytest>=8; extra == "test"
|
|
43
|
+
Requires-Dist: scipy; extra == "test"
|
|
44
|
+
Requires-Dist: pandas; extra == "test"
|
|
45
|
+
Requires-Dist: matplotlib; extra == "test"
|
|
46
|
+
Requires-Dist: shap; extra == "test"
|
|
47
|
+
Requires-Dist: lightgbm>=4.0; extra == "test"
|
|
48
|
+
Provides-Extra: examples
|
|
49
|
+
Requires-Dist: pandas; extra == "examples"
|
|
50
|
+
Requires-Dist: matplotlib; extra == "examples"
|
|
51
|
+
Requires-Dist: nbformat; extra == "examples"
|
|
52
|
+
Requires-Dist: nbclient; extra == "examples"
|
|
53
|
+
Requires-Dist: ipykernel; extra == "examples"
|
|
54
|
+
Provides-Extra: typing
|
|
55
|
+
Requires-Dist: mypy>=1.15; extra == "typing"
|
|
56
|
+
Dynamic: license-file
|
|
57
|
+
|
|
58
|
+
# bettertrees
|
|
59
|
+
|
|
60
|
+
**Interleaved Tree Models: small, readable sums of trees for binary classification, under a
|
|
61
|
+
budget of cuts.**
|
|
62
|
+
|
|
63
|
+
[](LICENSE)
|
|
64
|
+

|
|
65
|
+
[](https://github.com/rafapras/bettertrees/actions/workflows/ci.yml)
|
|
66
|
+
|
|
67
|
+
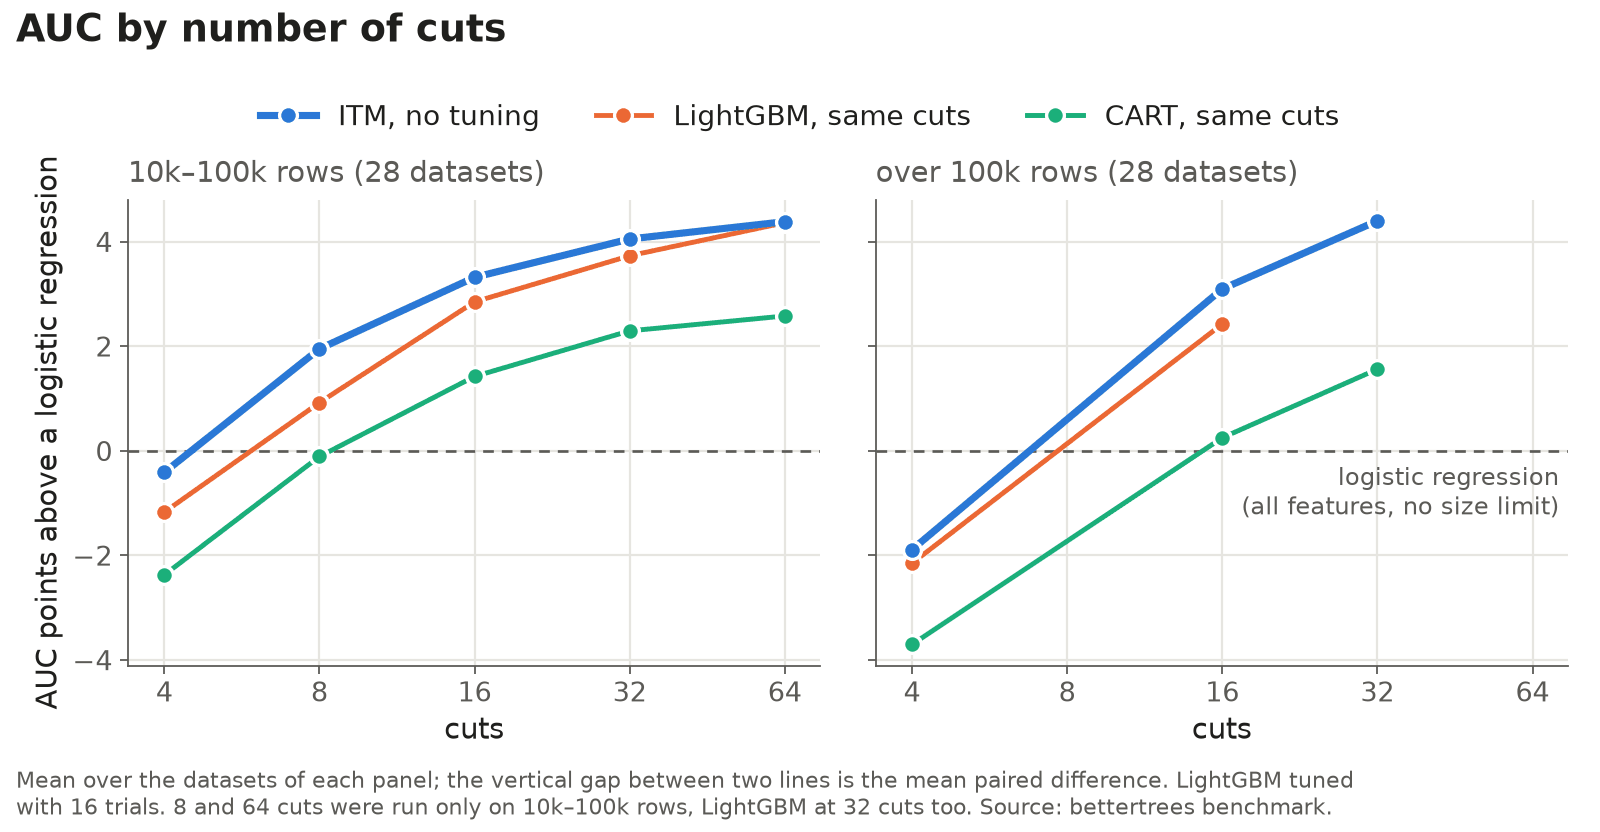
|
|
68
|
+
|
|
69
|
+
## Why
|
|
70
|
+
|
|
71
|
+
Where a decision must be explained line by line, as in credit scoring and in the biological
|
|
72
|
+
sciences, the binding constraint is the size of the model: a scorecard with a few dozen bins, a
|
|
73
|
+
tree with a few dozen nodes. bettertrees asks how much predictive power fits in each cut. Its main
|
|
74
|
+
model, the Interleaved Tree Model (ITM), is a logit sum of a few small trees that share one budget
|
|
75
|
+
of cuts. You set the budget; a fixed rule sets everything else, so there is nothing to
|
|
76
|
+
tune per dataset.
|
|
77
|
+
|
|
78
|
+
## Install
|
|
79
|
+
|
|
80
|
+
```bash
|
|
81
|
+
pip install bettertrees # numpy, numba, scikit-learn
|
|
82
|
+
pip install "bettertrees[all]" # + LightGBM screening, matplotlib plots, SHAP, pandas
|
|
83
|
+
```
|
|
84
|
+
|
|
85
|
+
From source: `pip install "git+https://github.com/rafapras/bettertrees"`. Python 3.10 or newer (tested on 3.10 and 3.14).
|
|
86
|
+
The Numba kernels compile on first use (about 5 to 10 seconds, once per environment) and are
|
|
87
|
+
cached afterwards. The public API has [type hints](https://github.com/rafapras/bettertrees/blob/main/docs/typing.md)
|
|
88
|
+
(`py.typed`); pandas inputs stay at the array-like level.
|
|
89
|
+
|
|
90
|
+
## Quickstart
|
|
91
|
+
|
|
92
|
+
This example uses a pandas DataFrame; install the `all` extra above. For NumPy-only
|
|
93
|
+
use, omit `as_frame=True` when loading the data.
|
|
94
|
+
|
|
95
|
+
```python
|
|
96
|
+
from sklearn.datasets import load_breast_cancer
|
|
97
|
+
from sklearn.metrics import roc_auc_score
|
|
98
|
+
from sklearn.model_selection import train_test_split
|
|
99
|
+
from bettertrees import BudgetClassifier
|
|
100
|
+
|
|
101
|
+
X, y = load_breast_cancer(return_X_y=True, as_frame=True) # a DataFrame keeps the column names
|
|
102
|
+
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.3, random_state=0, stratify=y)
|
|
103
|
+
|
|
104
|
+
model = BudgetClassifier(max_splits=8).fit(X_train, y_train)
|
|
105
|
+
auc = roc_auc_score(y_test, model.predict_proba(X_test)[:, 1])
|
|
106
|
+
print(f"{model.n_splits_} cuts in {len(model.trees_)} trees, test AUC {auc:.3f}")
|
|
107
|
+
```
|
|
108
|
+
|
|
109
|
+
```
|
|
110
|
+
8 cuts in 7 trees, test AUC 0.975
|
|
111
|
+
```
|
|
112
|
+
|
|
113
|
+
`BudgetClassifier(max_splits=b)` is the ITM with the rule of the benchmark: `lam = 2b`; up to 8
|
|
114
|
+
cuts a full Newton step capped at 4 logits, above 8 cuts a step of 0.3. The rule was evaluated
|
|
115
|
+
from 4 to 64 cuts. `InterleavedTreeClassifier` is the same model with every setting exposed.
|
|
116
|
+
|
|
117
|
+
## Reading the model
|
|
118
|
+
|
|
119
|
+
The whole model is the printout. To score a row, add the base and one value per tree, then apply
|
|
120
|
+
the logistic function.
|
|
121
|
+
|
|
122
|
+
```python
|
|
123
|
+
print(model.explain())
|
|
124
|
+
```
|
|
125
|
+
|
|
126
|
+
```
|
|
127
|
+
logit P(y = 1) = base +0.5242 + sum of 7 trees (8 cuts)
|
|
128
|
+
tree 1:
|
|
129
|
+
+1.7784 if worst perimeter <= 108.5
|
|
130
|
+
-2.3190 if worst perimeter > 108.5
|
|
131
|
+
tree 2:
|
|
132
|
+
+1.5100 if worst concave points <= 0.1415
|
|
133
|
+
-1.8678 if worst concave points > 0.1415
|
|
134
|
+
tree 3:
|
|
135
|
+
+1.3691 if worst texture <= 23.07
|
|
136
|
+
-1.2124 if worst texture > 23.07
|
|
137
|
+
tree 4:
|
|
138
|
+
+0.8157 if mean concavity <= 0.09267
|
|
139
|
+
-0.8322 if mean concavity > 0.09267
|
|
140
|
+
tree 5:
|
|
141
|
+
+0.5433 if mean texture <= 20.15
|
|
142
|
+
-0.6155 if mean texture > 20.15
|
|
143
|
+
tree 6:
|
|
144
|
+
+0.7050 if worst radius <= 15.87
|
|
145
|
+
-0.2938 if worst radius > 15.87 and worst texture <= 19.78
|
|
146
|
+
-0.9831 if worst radius > 15.87 and worst texture > 19.78
|
|
147
|
+
tree 7:
|
|
148
|
+
+0.4234 if worst symmetry <= 0.2852
|
|
149
|
+
-0.4383 if worst symmetry > 0.2852
|
|
150
|
+
```
|
|
151
|
+
|
|
152
|
+
Six trees are single cuts, one additive effect each; tree 6 is an interaction, the effect of
|
|
153
|
+
texture among large radii. The same model as data, per row, and as SQL:
|
|
154
|
+
|
|
155
|
+
```python
|
|
156
|
+
model.rules()[:2] # [(tree, conditions, logit value)] per leaf
|
|
157
|
+
# [(0, ['worst perimeter <= 108.5'], 1.7783520345848123),
|
|
158
|
+
# (0, ['worst perimeter > 108.5'], -2.3190229737929564)]
|
|
159
|
+
|
|
160
|
+
model.predict_contributions(X_test[:1]) # one column per tree; base + row sum = logit
|
|
161
|
+
# [[-2.31902297 -1.86779044 -1.21240149 -0.8322431 -0.61554356 -0.98310833 -0.43829661]]
|
|
162
|
+
|
|
163
|
+
print(model.to_sql(table="patients")) # the model as one query, no Python needed to score
|
|
164
|
+
```
|
|
165
|
+
|
|
166
|
+
```sql
|
|
167
|
+
-- logit P(y = 1) = base + sum of 7 tree columns (8 cuts); p = 1 / (1 + EXP(-score))
|
|
168
|
+
WITH contributions AS (
|
|
169
|
+
SELECT *,
|
|
170
|
+
CASE -- tree 1
|
|
171
|
+
WHEN "worst perimeter" <= 108.5 THEN 1.77835
|
|
172
|
+
ELSE -2.31902
|
|
173
|
+
END AS "t1_worst perimeter",
|
|
174
|
+
...
|
|
175
|
+
CASE -- tree 6
|
|
176
|
+
WHEN "worst radius" <= 15.870001 THEN 0.704956
|
|
177
|
+
WHEN "worst radius" > 15.870001 AND "worst texture" <= 19.779999 THEN -0.293802
|
|
178
|
+
ELSE -0.983108
|
|
179
|
+
END AS "t6_worst radius_worst texture",
|
|
180
|
+
...
|
|
181
|
+
FROM patients
|
|
182
|
+
), scored AS (
|
|
183
|
+
SELECT *, 0.524249 -- base
|
|
184
|
+
+ "t1_worst perimeter"
|
|
185
|
+
...
|
|
186
|
+
AS score
|
|
187
|
+
FROM contributions
|
|
188
|
+
)
|
|
189
|
+
SELECT *, 1.0 / (1.0 + EXP(-score)) AS p
|
|
190
|
+
FROM scored;
|
|
191
|
+
```
|
|
192
|
+
|
|
193
|
+
Also on every sum: `to_dict()` (JSON), `get_trees()` (arrays, as scikit-learn's `tree_`),
|
|
194
|
+
`export_text()`, `plot_contributions(x)` (waterfall of one prediction), `plot_shapes()` (shape
|
|
195
|
+
functions of the single-feature trees) and `to_shap_model()` (exact TreeSHAP with
|
|
196
|
+
`shap.TreeExplainer`).
|
|
197
|
+
|
|
198
|
+
For deployment, `to_dict()` stores exact bins and tree arrays alongside the rounded
|
|
199
|
+
rules. The [export guide](https://github.com/rafapras/bettertrees/blob/main/docs/export.md) includes an independent evaluator and the
|
|
200
|
+
input precision and missing-value conventions. SQL printouts round leaf values to
|
|
201
|
+
`precision` significant digits (6 by default); validate the generated query against
|
|
202
|
+
the fitted model on deployment inputs.
|
|
203
|
+
|
|
204
|
+
## Results
|
|
205
|
+
|
|
206
|
+
From the benchmark of the paper (in preparation): 56 binary classification datasets from
|
|
207
|
+
TabArena, the AutoML Benchmark, the suite of Grinsztajn et al. and Kaggle, with 10 thousand to
|
|
208
|
+
2.2 million rows. Three evaluation partitions per dataset up to 100 thousand rows, one 80/20
|
|
209
|
+
holdout above; the partition used to choose the rule is excluded. Every rival is held to the same
|
|
210
|
+
budget in its own unit: CART is grown to b + 1 leaves, LightGBM gets K trees of l leaves with
|
|
211
|
+
K(l − 1) ≤ b, RGF is refitted to exactly b cuts.
|
|
212
|
+
|
|
213
|
+
Mean AUC difference in points (ITM minus rival; one point = 0.01 AUC), with the number of datasets
|
|
214
|
+
on which the ITM has the higher AUC. Positive = ITM better.
|
|
215
|
+
|
|
216
|
+
| rival (same budget unless noted) | 4 cuts | 16 cuts | 32 cuts | 64 cuts |
|
|
217
|
+
|---|---|---|---|---|
|
|
218
|
+
| CART (scikit-learn, tuned) | +1.89 (50/56) | +2.37 (52/56) | +2.30 (53/56) | +1.80 (25/28) |
|
|
219
|
+
| LightGBM, tuned with 16 trials | +0.51 (44/56) | +0.57 (51/56) | +0.32 (20/28) | +0.02 (16/28) |
|
|
220
|
+
| LightGBM, tuned with 100 trials | +0.64 (38/49) | +0.45 (43/49) | +0.59 (26/28) | — |
|
|
221
|
+
| RGF, tuned | −0.18 (28/56) | −0.03 (23/56) | +0.15 (31/56) | — |
|
|
222
|
+
| WoE scorecard (no size limit) | −3.95 (4/56) | +0.41 (37/56) | +1.43 (50/56) | +1.98 (24/28) |
|
|
223
|
+
|
|
224
|
+
Cells with 28 datasets cover only 10–100 thousand rows (64 cuts, and LightGBM with 16 trials at
|
|
225
|
+
32 cuts) or only above 100 thousand rows (LightGBM with 100 trials at 32 cuts); LightGBM with 100
|
|
226
|
+
trials was not run on the 7 datasets of 50–100 thousand rows. "—": not run.
|
|
227
|
+
|
|
228
|
+
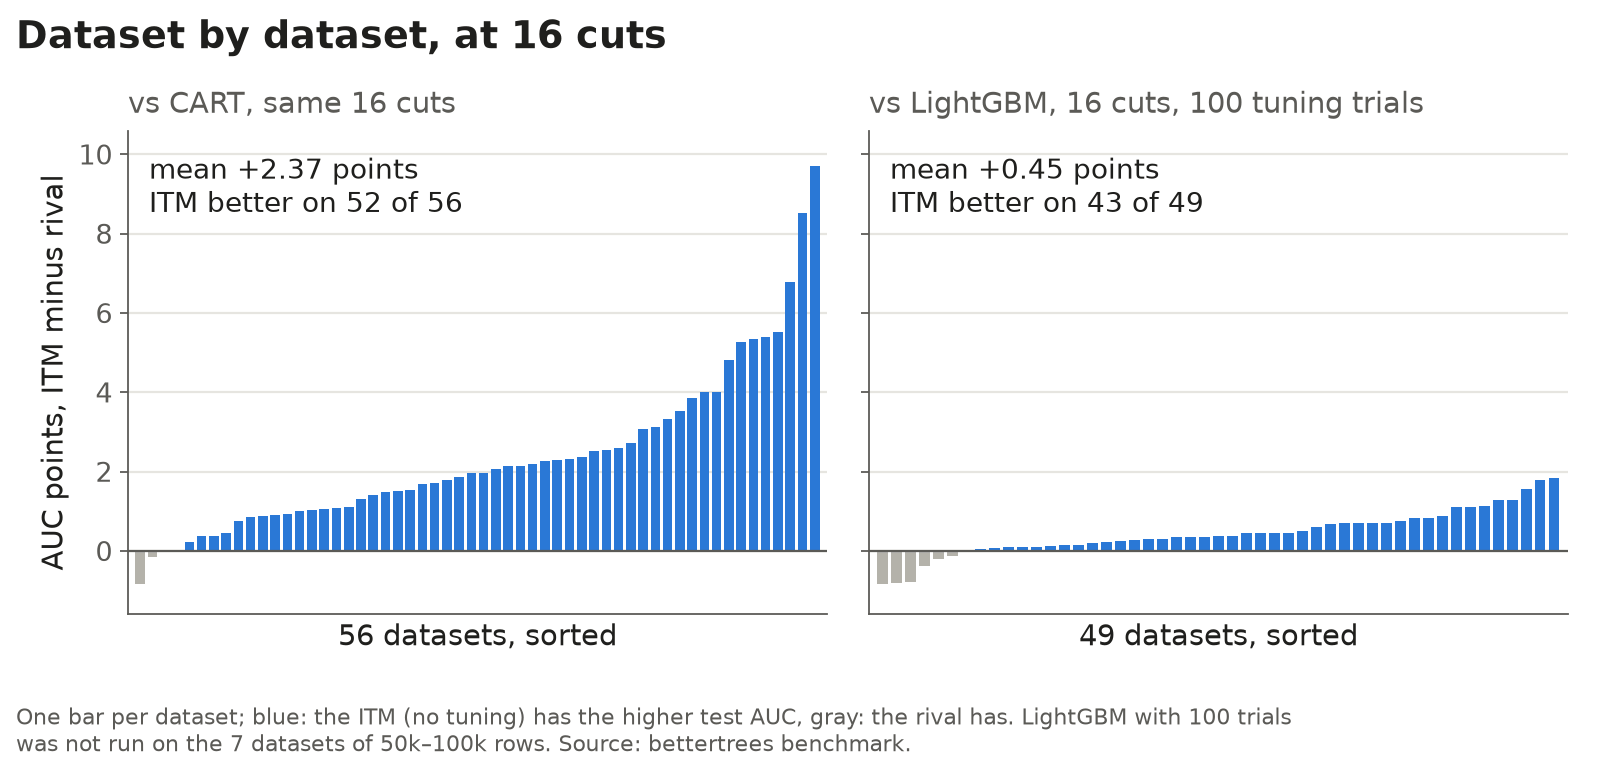
In short: the ITM beats CART of the same size by about 2 AUC points at every budget, beats
|
|
229
|
+
LightGBM of the same size from 4 to 32 cuts and ties it at 64, and ties a tuned RGF, its closest
|
|
230
|
+
ancestor (with its library defaults, RGF is 2.5 to 3.6 points behind). Dataset by dataset at 16
|
|
231
|
+
cuts:
|
|
232
|
+
|
|
233
|
+
|
|
234
|
+
|
|
235
|
+
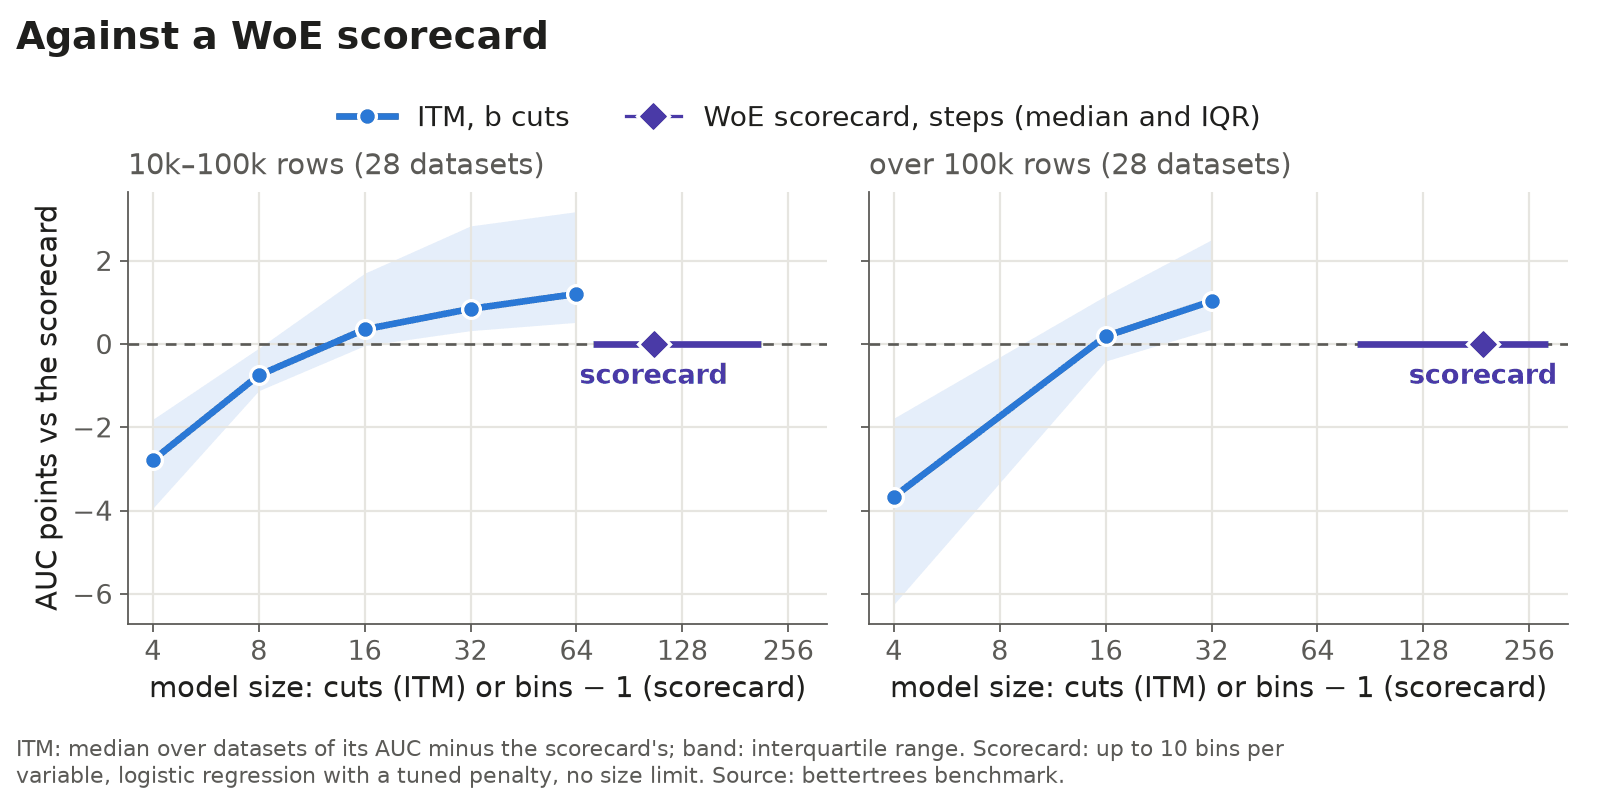
Against a weight-of-evidence scorecard (up to 10 bins per variable, no size limit; a median of
|
|
236
|
+
157 steps, one step per bin boundary), the ITM loses with 4 and 8 cuts and passes the scorecard
|
|
237
|
+
at 16:
|
|
238
|
+
|
|
239
|
+
|
|
240
|
+
|
|
241
|
+
**Cost.** The ITM is cheaper to obtain because it is not tuned. At 16 cuts on 10–50 thousand
|
|
242
|
+
rows it takes a median of 0.11 seconds against 5.26 seconds for LightGBM tuned with 100 trials
|
|
243
|
+
(median per-dataset ratio 47); above 100 thousand rows the ratio is 2.9 (7.7 against 22.3
|
|
244
|
+
seconds), because the tuned control searches on a 100 thousand-row sample.
|
|
245
|
+
|
|
246
|
+
## How it works
|
|
247
|
+
|
|
248
|
+
The ITM scores a row as `logit P(y = 1) = base + T_1(x) + ... + T_K(x)`, where each `T_k` is a
|
|
249
|
+
small tree with values in log-odds. Growth starts with no trees. At each step every leaf of every
|
|
250
|
+
tree, and the root of a new tree, is a candidate; the cut with the largest Newton gain
|
|
251
|
+
`G_l²/(H_l + λ) + G_r²/(H_r + λ) − G²/(H + λ)`, at the margin of the other trees, is added; its
|
|
252
|
+
two leaves take a Newton step `−G/(H + λ)`, and one sweep then refits every leaf of every tree.
|
|
253
|
+
Growth stops after b cuts (internal nodes, one per split operation); a (feature, threshold)
|
|
254
|
+
pair may repeat, so the model has at most b distinct pairs. The growth across trees comes from FIGS
|
|
255
|
+
(Tan et al.), the refit of all leaves from RGF (Johnson and Zhang); the ITM replaces FIGS's
|
|
256
|
+
mean-residual leaves with Newton steps in log-odds, refits after every cut, and replaces tuning with a
|
|
257
|
+
fixed rule. Features are binned into 32 quantile bins;
|
|
258
|
+
missing values get a bin of their own and always go left.
|
|
259
|
+
|
|
260
|
+
## Limitations
|
|
261
|
+
|
|
262
|
+
- **Binary classification only** for the sums (they raise on a multiclass target; wrap them in
|
|
263
|
+
`OneVsRestClassifier`). The single trees are multiclass.
|
|
264
|
+
- **Evaluated from 4 to 64 cuts.** Above 64 the rule is applied without validation; at 64 the ITM
|
|
265
|
+
only ties LightGBM.
|
|
266
|
+
- **Not faster per fit.** One ITM fit is slower than one LightGBM fit of the same size (16 cuts,
|
|
267
|
+
50 features, one thread: 0.15, 1.38 and 15 seconds at 10 thousand, 100 thousand and one
|
|
268
|
+
million rows, against 0.05, 0.60 and 2.62 for LightGBM). The time saved comes from not tuning.
|
|
269
|
+
- **Small budgets and many weak effects.** With 4 and 8 cuts a WoE scorecard of about 150 steps
|
|
270
|
+
has the higher AUC; where many variables each carry a weak monotone effect, many cheap bins beat
|
|
271
|
+
a few cuts.
|
|
272
|
+
- **Deep interactions.** Where the target is itself a deep interaction (in the benchmark,
|
|
273
|
+
`electricity` and the hierarchical `pol`), a single tree or boosting is the right shape and the
|
|
274
|
+
sum gains little over CART.
|
|
275
|
+
- **The rule** was chosen among about fifty variants on development partitions of the same pool
|
|
276
|
+
of datasets, and the step cap at 4 and 8 cuts was added after the first evaluation results. It
|
|
277
|
+
has not been validated on datasets outside the project.
|
|
278
|
+
- **Ordered numeric inputs.** Thresholds assume that the order of a feature's values means
|
|
279
|
+
something; integer-coded categories with thousands of levels are better served by native
|
|
280
|
+
categorical splits.
|
|
281
|
+
|
|
282
|
+
## What else is in the package
|
|
283
|
+
|
|
284
|
+
| estimator | what it is |
|
|
285
|
+
|---|---|
|
|
286
|
+
| `BudgetClassifier` | the ITM with the fixed rule per budget; start here |
|
|
287
|
+
| `InterleavedTreeClassifier` | the ITM with every setting exposed; `FIGSClassifier` is an alias |
|
|
288
|
+
| `SumOfOptimalTrees` | a logit sum of a few optimal (exhaustive search) trees of depth 1–3, with backfitting |
|
|
289
|
+
| `CompactTreeBooster` | shrunken boosting of optimal trees, identical trees merged, budget in distinct cuts |
|
|
290
|
+
| `AdditiveTreeBooster` | a long sum of optimal depth-1/2 trees with early stopping (no budget) |
|
|
291
|
+
| `LightGBMRefitClassifier`, `from_lightgbm` | a LightGBM model imported as an editable sum (exact predictions), with its leaves refitted jointly |
|
|
292
|
+
| `FastDecisionTreeClassifier`, `FastDecisionTreeClassifierCV` | a single CART-style tree (Gini), multiclass; the CV version chooses the leaf count and hierarchical shrinkage |
|
|
293
|
+
|
|
294
|
+
`bettertrees.sums` also exposes `TreeSum` (the editable sum returned by `from_lightgbm`),
|
|
295
|
+
`SmallTree` (one tree of a sum, in `trees_`) and `screen_features` (bootstrap screening of
|
|
296
|
+
single cuts on a residual).
|
|
297
|
+
|
|
298
|
+
All estimators follow the scikit-learn API (pipelines, `GridSearchCV`, `CalibratedClassifierCV`,
|
|
299
|
+
`permutation_importance`, `partial_dependence`, pickle), accept NaN and `sample_weight`, and keep
|
|
300
|
+
DataFrame column names.
|
|
301
|
+
|
|
302
|
+
`from_lightgbm` supports binary models with numerical splits, at most 254 distinct
|
|
303
|
+
thresholds per feature, and missing values routed left. It rejects categorical splits,
|
|
304
|
+
`zero_as_missing` and NaN routed right, whose semantics cannot be preserved.
|
|
305
|
+
Rows with zero sample weight are excluded from training and binning; positive weights
|
|
306
|
+
change the objective mass and do not generally mean repeating rows, especially with
|
|
307
|
+
row-based validation or LightGBM binning.
|
|
308
|
+
|
|
309
|
+
**Editing.** Every sum can be edited and re-estimated, and all outputs follow the edit:
|
|
310
|
+
|
|
311
|
+
```python
|
|
312
|
+
model.set_cut(tree, node, "income", 50_000) # move or replace a cut (snaps to a bin edge)
|
|
313
|
+
model.split_leaf(tree, leaf, "debt", 2.5) # add a cut by hand
|
|
314
|
+
model.add_stump("age", 65) # add a rule as a new tree
|
|
315
|
+
model.prune(tree, node) # collapse a cut into a leaf
|
|
316
|
+
model.refit_leaves(X, y, monotone={"income": -1}) # refit, with monotone constraints
|
|
317
|
+
model.cut_alternatives(X_val, y_val, tree, node, epsilon=0.01) # near-equivalent cuts
|
|
318
|
+
```
|
|
319
|
+
|
|
320
|
+
**Experimental and lab.**
|
|
321
|
+
|
|
322
|
+
- `bettertrees.experimental` (no API stability guarantee): `ObliqueFIGSClassifier`, the ITM with
|
|
323
|
+
cuts on linear combinations of two features, which helped at 4 and 8 cuts and added little at
|
|
324
|
+
16 and 32; `PrecisionTreeClassifier`, a tree whose cuts maximize one class's precision.
|
|
325
|
+
- `bettertrees.lab` is research code from the benchmark with negative or inconclusive results:
|
|
326
|
+
product terms between trees, bagged and Rashomon structure selection, distillation from a
|
|
327
|
+
teacher, pair and ratio features, RuleFit, and a multilevel tree of optimal depth-2 blocks.
|
|
328
|
+
**It is not part of the public API and carries no stability guarantee**; it is kept so that the
|
|
329
|
+
results can be reproduced.
|
|
330
|
+
|
|
331
|
+
**Examples.** Three notebooks in [`examples/`](https://github.com/rafapras/bettertrees/tree/main/examples), run by CI on simulated credit data
|
|
332
|
+
with known effects: [`01_quickstart`](https://github.com/rafapras/bettertrees/blob/main/examples/01_quickstart.ipynb),
|
|
333
|
+
[`02_interpretation`](https://github.com/rafapras/bettertrees/blob/main/examples/02_interpretation.ipynb) and
|
|
334
|
+
[`03_editing`](https://github.com/rafapras/bettertrees/blob/main/examples/03_editing.ipynb).
|
|
335
|
+
|
|
336
|
+
## Credits
|
|
337
|
+
|
|
338
|
+
| work | what bettertrees borrows |
|
|
339
|
+
|---|---|
|
|
340
|
+
| **FIGS**: Tan, Singh, Nasseri, Agarwal, et al. "Fast Interpretable Greedy-Tree Sums." arXiv:2201.11931 (2022); [imodels](https://github.com/csinva/imodels) | Growth across trees: the next cut may deepen any leaf of any tree or start a new one. |
|
|
341
|
+
| **RGF**: Johnson, Zhang. "Learning Nonlinear Functions Using Regularized Greedy Forest." *IEEE TPAMI* (2014) | The refit of all leaf values as the forest grows. |
|
|
342
|
+
| **XGBoost**: Chen, Guestrin. *KDD* (2016) | The second-order gain `G²/(H+λ)` and leaf value `−G/(H+λ)`. |
|
|
343
|
+
| **LightGBM**: Ke et al. *NeurIPS* (2017); scikit-learn's HistGradientBoosting | Quantile histograms with a bin for missing values; best-first growth. |
|
|
344
|
+
| **Hierarchical Shrinkage**: Agarwal, Tan, Ronen, Singh, Yu. *ICML* (2022) | Leaf values shrunk toward their ancestors in the single tree. |
|
|
345
|
+
| **MurTree**: Demirović et al. *JMLR* (2022); **ConTree**: Briţa, van der Linden, Demirović. *AAAI* (2025) | The depth-two solver behind `SumOfOptimalTrees`, here on bins with the Newton gain. |
|
|
346
|
+
| **GA2M / EBM**: Lou, Caruana, Gehrke, Hooker. *KDD* (2013); Nori et al. InterpretML (2019) | Additive models with pairwise interactions and shape plots. |
|
|
347
|
+
| **CART**: Breiman, Friedman, Olshen, Stone (1984); Pagallo and Haussler, *Machine Learning* (1990) | The tree engine, cost-complexity pruning and the replication problem that motivates sums. |
|
|
348
|
+
| **SHAP / TreeSHAP**: Lundberg et al. *Nature Machine Intelligence* (2020) | `to_shap_model()` for exact TreeSHAP. |
|
|
349
|
+
| **scikit-learn** (Pedregosa et al., *JMLR* 2011) and **Numba** (Lam, Pitrou, Seibert, 2015) | The estimator API; all kernels. |
|
|
350
|
+
|
|
351
|
+
## Citation
|
|
352
|
+
|
|
353
|
+
A paper on the ITM and the benchmark is in preparation. Until it is out, please cite the software
|
|
354
|
+
([`CITATION.cff`](https://github.com/rafapras/bettertrees/blob/main/CITATION.cff)):
|
|
355
|
+
|
|
356
|
+
```bibtex
|
|
357
|
+
@software{bettertrees,
|
|
358
|
+
title = {bettertrees: Interleaved Tree Models for binary classification under a budget of cuts},
|
|
359
|
+
author = {rafapras},
|
|
360
|
+
year = {2026},
|
|
361
|
+
version = {0.1.0},
|
|
362
|
+
url = {https://github.com/rafapras/bettertrees}
|
|
363
|
+
}
|
|
364
|
+
```
|
|
365
|
+
|
|
366
|
+
## License
|
|
367
|
+
|
|
368
|
+
BSD-3-Clause; see [`LICENSE`](https://github.com/rafapras/bettertrees/blob/main/LICENSE).
|