beseda 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- beseda-0.1.0/LICENSE +21 -0
- beseda-0.1.0/PKG-INFO +213 -0
- beseda-0.1.0/README.md +181 -0
- beseda-0.1.0/beseda/__init__.py +0 -0
- beseda-0.1.0/beseda/__main__.py +514 -0
- beseda-0.1.0/beseda/brains.py +199 -0
- beseda-0.1.0/beseda/language.py +74 -0
- beseda-0.1.0/beseda/languages/en.toml +61 -0
- beseda-0.1.0/beseda/languages/ru.toml +64 -0
- beseda-0.1.0/beseda/models.py +33 -0
- beseda-0.1.0/beseda/recording.py +98 -0
- beseda-0.1.0/beseda/samples.py +58 -0
- beseda-0.1.0/beseda/stt.py +64 -0
- beseda-0.1.0/beseda/tts.py +160 -0
- beseda-0.1.0/beseda/wake.py +30 -0
- beseda-0.1.0/pyproject.toml +60 -0
- beseda-0.1.0/pyproject.toml.orig +52 -0
beseda-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Mikhail Angelov
|
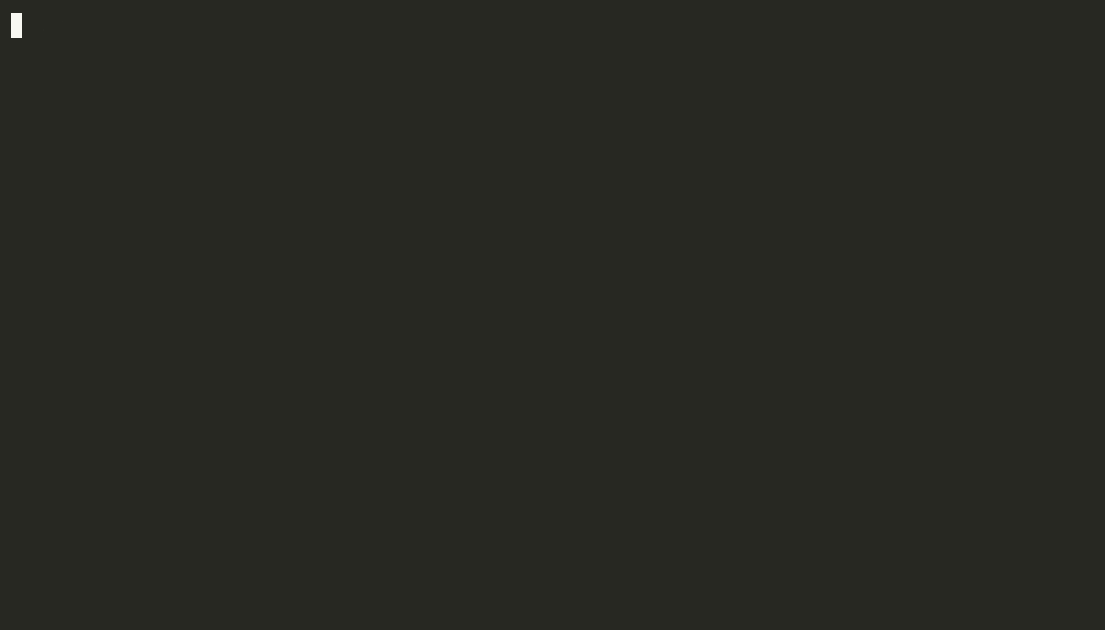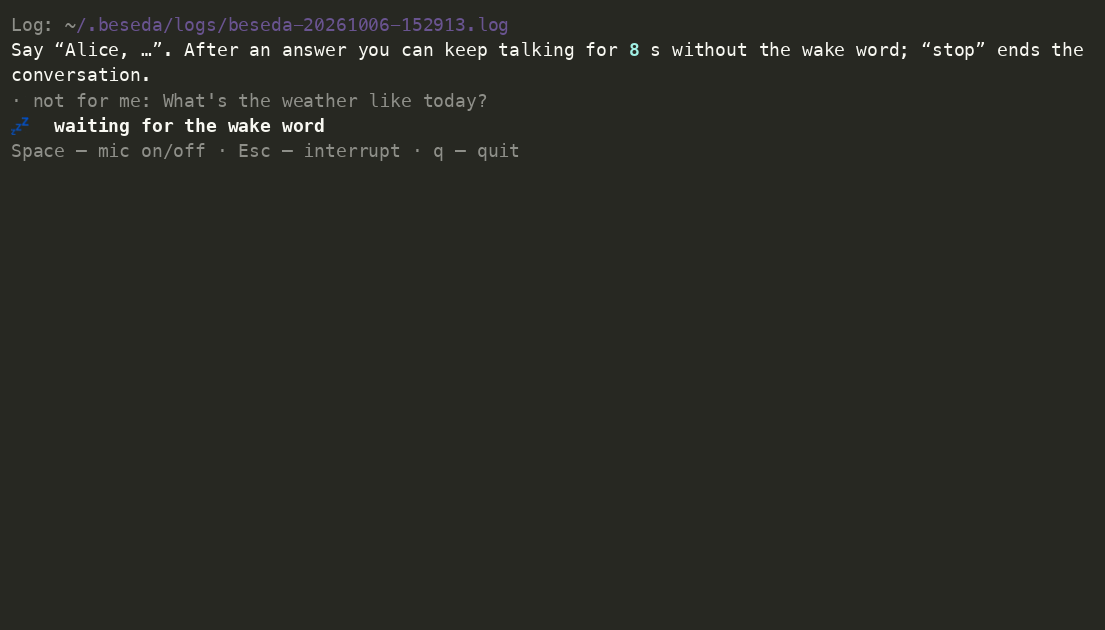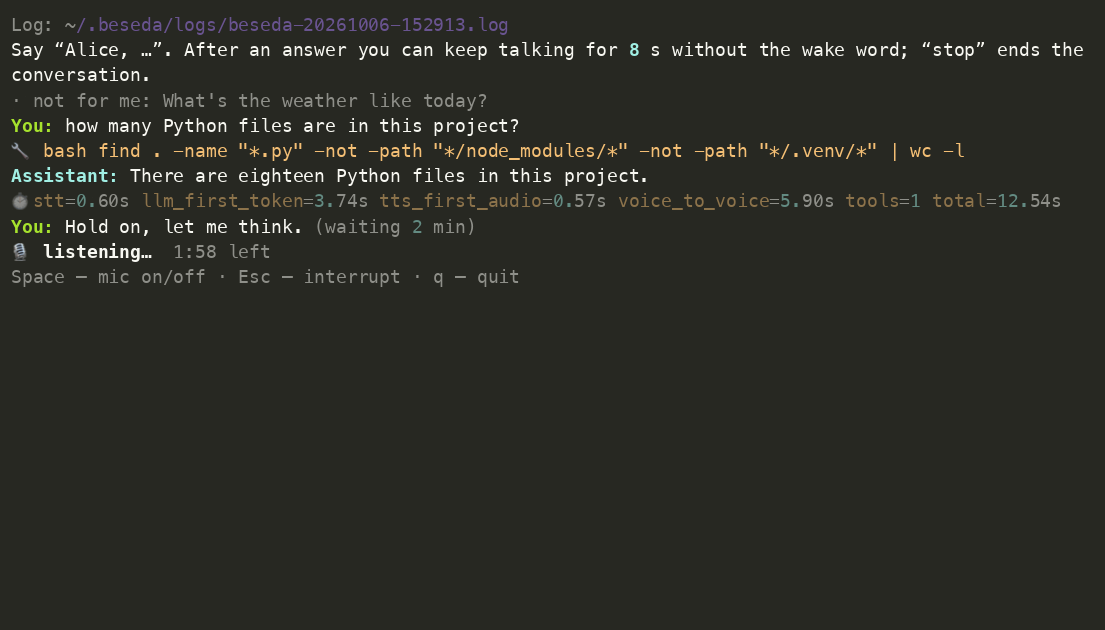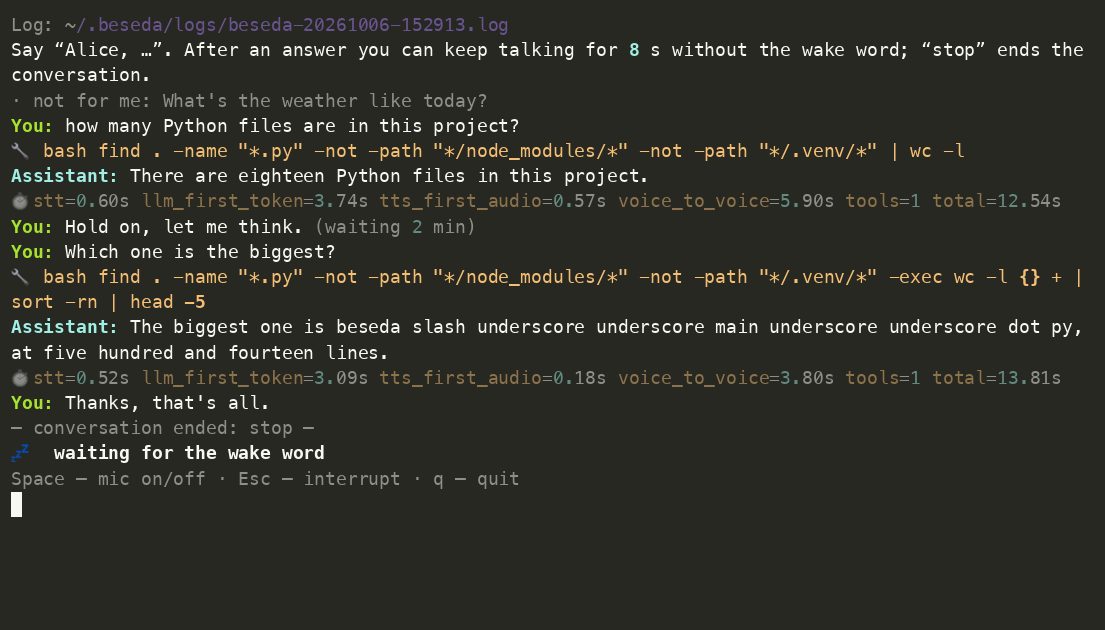
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
beseda-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,213 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: beseda
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Voice conversations with your coding agent: a Russian-speaking terminal assistant with local speech recognition and synthesis
|
|
5
|
+
Keywords: voice-assistant,speech-recognition,text-to-speech,whisper,coding-agent,russian
|
|
6
|
+
Author: Mikhail Angelov
|
|
7
|
+
Author-email: Mikhail Angelov <mikhail.angelov@gmail.com>
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Classifier: Development Status :: 3 - Alpha
|
|
11
|
+
Classifier: Environment :: Console
|
|
12
|
+
Classifier: Environment :: MacOS X
|
|
13
|
+
Classifier: Intended Audience :: Developers
|
|
14
|
+
Classifier: Natural Language :: Russian
|
|
15
|
+
Classifier: Operating System :: MacOS
|
|
16
|
+
Classifier: Programming Language :: Python :: 3.12
|
|
17
|
+
Classifier: Topic :: Multimedia :: Sound/Audio :: Speech
|
|
18
|
+
Requires-Dist: edge-tts>=7.2.8
|
|
19
|
+
Requires-Dist: numpy>=2.5.3
|
|
20
|
+
Requires-Dist: openai>=3.24.0
|
|
21
|
+
Requires-Dist: pyaudio>=0.2.14
|
|
22
|
+
Requires-Dist: pydub>=0.25.1
|
|
23
|
+
Requires-Dist: realtimestt[silero-onnx-cpu,whisper-cpp]>=1.1.2
|
|
24
|
+
Requires-Dist: realtimetts>=0.8.10
|
|
25
|
+
Requires-Dist: resampy>=0.4.3
|
|
26
|
+
Requires-Dist: rich>=15.0.0
|
|
27
|
+
Requires-Dist: torch>=2.14.1
|
|
28
|
+
Requires-Python: >=3.12
|
|
29
|
+
Project-URL: Homepage, https://github.com/mikhail-angelov/beseda
|
|
30
|
+
Project-URL: Issues, https://github.com/mikhail-angelov/beseda/issues
|
|
31
|
+
Description-Content-Type: text/markdown
|
|
32
|
+
|
|
33
|
+
# Beseda
|
|
34
|
+
|
|
35
|
+
**Voice conversations with your coding agent.** Say “Alice, …” (in Russian, “Вика, …”) and talk to an AI agent in English or Russian, right
|
|
36
|
+
from the terminal: speech recognition and synthesis run locally on your Mac, the agent works in the current folder.
|
|
37
|
+
|
|
38
|
+
[Русская версия](https://github.com/mikhail-angelov/beseda/blob/main/README.ru.md)
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
|
|
42
|
+
▶ [The same conversation with sound (MP4)](https://github.com/mikhail-angelov/beseda/blob/main/docs/demo-en.mp4) ([Russian](https://github.com/mikhail-angelov/beseda/blob/main/docs/demo-ru.mp4)). The user's phrases are spoken by a second Silero voice
|
|
43
|
+
instead of a microphone; recognition, the pi agent and the answers are the real app. Long waits in the GIF are shortened.
|
|
44
|
+
|
|
45
|
+
```
|
|
46
|
+
microphone → Silero VAD + whisper.cpp (local) → brain: pi agent or DeepSeek → TTS: Silero (local) → speakers
|
|
47
|
+
```
|
|
48
|
+
|
|
49
|
+
> **Status:** alpha. macOS on Apple Silicon only. Russian (default) and English; more languages are a TOML file away.
|
|
50
|
+
|
|
51
|
+
## Features
|
|
52
|
+
|
|
53
|
+
- **Wake word, like a smart speaker.** Only phrases addressed to «Вика» reach the model; after an answer you can
|
|
54
|
+
keep talking without the wake word, «стоп» ends the conversation, «подожди» gives you time to think.
|
|
55
|
+
- **Local speech.** whisper.cpp on the Mac GPU (Metal) for recognition, Silero for synthesis: from the
|
|
56
|
+
first word of the answer to sound in 0.1–0.25 s.
|
|
57
|
+
- **Pluggable brains.** The [pi](https://www.npmjs.com/package/@earendil-works/pi-coding-agent) coding agent
|
|
58
|
+
(reads and edits files, runs commands) or a plain DeepSeek chat; adding Claude or Codex is one class.
|
|
59
|
+
- **Observability.** Every session writes a log with a per-turn latency timeline: recognition, first token,
|
|
60
|
+
first audio, tool calls.
|
|
61
|
+
- **Dialog recording.** The whole conversation as one WAV, with the real pauses.
|
|
62
|
+
|
|
63
|
+
## Requirements
|
|
64
|
+
|
|
65
|
+
- macOS on Apple Silicon, Python 3.12+, [uv](https://docs.astral.sh/uv/), `brew install portaudio`
|
|
66
|
+
- For `--tts edge`: `brew install ffmpeg`
|
|
67
|
+
- For the default brain: `npm install -g @earendil-works/pi-coding-agent` with a DeepSeek key configured in pi.
|
|
68
|
+
For `--brain deepseek`: the `DEEPSEEK_API_KEY` environment variable.
|
|
69
|
+
|
|
70
|
+
## Install
|
|
71
|
+
|
|
72
|
+
```bash
|
|
73
|
+
brew install portaudio
|
|
74
|
+
uv tool install beseda
|
|
75
|
+
```
|
|
76
|
+
|
|
77
|
+
Models download on first launch into `~/.beseda/models/` (Whisper small ~490 MB, Silero ~145 MB, VAD ~1 MB).
|
|
78
|
+
|
|
79
|
+
## Use
|
|
80
|
+
|
|
81
|
+
```bash
|
|
82
|
+
cd ~/some/project # the agent works in the current folder
|
|
83
|
+
beseda # Russian
|
|
84
|
+
beseda --language en # English
|
|
85
|
+
```
|
|
86
|
+
|
|
87
|
+
The table shows the Russian phrases; the English pack has its own (“Alice, …”, “hold on”, “that's all”).
|
|
88
|
+
|
|
89
|
+
| You say | What happens |
|
|
90
|
+
|---|---|
|
|
91
|
+
| «Вика, какая погода?» | Conversation starts (Tink sound); «какая погода?» goes to the model |
|
|
92
|
+
| «Вика» | A beep, then it waits for the request |
|
|
93
|
+
| anything, within `--follow-up` s after an answer (8 s) | Goes to the model without the wake word; the status line counts down |
|
|
94
|
+
| «Подожди», «дай подумать», «секунду» | Not sent to the model; the wait extends to `--hold` s (2 min) |
|
|
95
|
+
| «Стоп», «хватит», «спасибо, всё», or silence | Conversation ends (Bottle sound); the wake word is needed again |
|
|
96
|
+
| anything else without the wake word | Ignored, shown dimmed |
|
|
97
|
+
|
|
98
|
+
Keys: **Space** turns the microphone on/off, **Esc** interrupts the answer, **q** quits.
|
|
99
|
+
|
|
100
|
+
The microphone is off while the assistant speaks, so it never hears itself; interrupting by voice isn't
|
|
101
|
+
supported yet. The macOS microphone indicator stays on while Beseda runs: the stream must stay open to hear
|
|
102
|
+
the wake word.
|
|
103
|
+
|
|
104
|
+
## Configuration
|
|
105
|
+
|
|
106
|
+
Any option can be set in `~/.beseda/config.toml`; command-line flags win.
|
|
107
|
+
|
|
108
|
+
```toml
|
|
109
|
+
language = "ru" # ru | en | your own pack
|
|
110
|
+
brain = "pi" # pi | deepseek
|
|
111
|
+
model = "deepseek/deepseek-v4-flash"
|
|
112
|
+
whisper = "small" # small | turbo
|
|
113
|
+
vocabulary = ["JavaScript", "DeepSeek"]
|
|
114
|
+
tts = "silero" # silero | edge | say
|
|
115
|
+
voice = "baya"
|
|
116
|
+
wake-word = "вика" # default comes from the language pack; "" answers everything
|
|
117
|
+
follow-up = 8
|
|
118
|
+
hold = 120
|
|
119
|
+
record = true # or a file path
|
|
120
|
+
log-days = 14
|
|
121
|
+
```
|
|
122
|
+
|
|
123
|
+
See `beseda --help` for the full list.
|
|
124
|
+
|
|
125
|
+
## Languages
|
|
126
|
+
|
|
127
|
+
Everything that depends on the spoken language lives in a language pack, a TOML file: Whisper's language and
|
|
128
|
+
style prompt, the voice prompt for the model, the wake word and its grammatical endings, stop and hold phrases,
|
|
129
|
+
default TTS voices and the Silero model, and the terminal UI strings.
|
|
130
|
+
|
|
131
|
+
Built-in packs: [`ru`](https://github.com/mikhail-angelov/beseda/blob/main/beseda/languages/ru.toml) (default) and [`en`](https://github.com/mikhail-angelov/beseda/blob/main/beseda/languages/en.toml). To change a pack
|
|
132
|
+
or add a language, put a file into `~/.beseda/languages/`: `ru.toml` there overrides the built-in one, `de.toml`
|
|
133
|
+
adds German (`beseda --language de`). Copy a built-in pack as a starting point; every key is required.
|
|
134
|
+
|
|
135
|
+
## Speech recognition
|
|
136
|
+
|
|
137
|
+
Techniques carried over from [Vadic](https://github.com/mikhail-angelov/vadic) and checked on real dialogs:
|
|
138
|
+
loudness normalization before recognition, Whisper's own VAD (without it a cough becomes «Спасибо.», which is a
|
|
139
|
+
stop phrase), a style prompt for punctuation plus your `vocabulary` for terms, greedy decoding at temperature 0.
|
|
140
|
+
|
|
141
|
+
| `whisper` | Time per phrase (M1) | Notes |
|
|
142
|
+
|---|---|---|
|
|
143
|
+
| `small` (default) | ~0.5 s | Occasional wrong words |
|
|
144
|
+
| `turbo` (large-v3-turbo-q5_0) | ~2.1 s | Far more accurate; 574 MB |
|
|
145
|
+
|
|
146
|
+
Models other apps already downloaded (VoiceInk, Vadic) are reused.
|
|
147
|
+
|
|
148
|
+
## Speech synthesis
|
|
149
|
+
|
|
150
|
+
| `tts` | Russian voices | English voices | Runs | Per sentence (ru) | CPU per second of speech | RAM |
|
|
151
|
+
|---|---|---|---|---|---|---|
|
|
152
|
+
| `silero` (default) | xenia, baya, kseniya, aidar, eugene | en_0 … en_4 | locally | 0.04 s (en: ~0.35 s) | 16 ms | ~760 MB |
|
|
153
|
+
| `say` | Milena | Daniel | locally (macOS) | 0.6 s | 140 ms | ~40 MB |
|
|
154
|
+
| `edge` (experimental) | ru-RU-SvetlanaNeural, ru-RU-DmitryNeural | en-US-AriaNeural, en-US-GuyNeural | Microsoft cloud | 1–2 s | 60 ms | ~55 MB |
|
|
155
|
+
|
|
156
|
+
Silero's Russian model skips digits and Latin letters, so the Russian voice prompt asks the model to write numbers
|
|
157
|
+
and names in Russian words. Compare the voices by ear: `beseda-samples [--language en]` writes the same phrase in
|
|
158
|
+
every voice to `~/Downloads/beseda-tts-samples/`.
|
|
159
|
+
|
|
160
|
+
## Logs and recordings
|
|
161
|
+
|
|
162
|
+
Each session logs to `~/.beseda/logs/beseda-<time>.log`; logs older than `log-days` are deleted on start.
|
|
163
|
+
|
|
164
|
+
```bash
|
|
165
|
+
grep summary ~/.beseda/logs/*.log | tail # latency per turn: stt, llm_first_token, tts_first_audio, voice_to_voice
|
|
166
|
+
grep -E 'ERROR|WARNING' ~/.beseda/logs/*.log # incidents
|
|
167
|
+
```
|
|
168
|
+
|
|
169
|
+
`--debug` adds every pi event. `--record` saves the dialog to `~/Downloads/beseda-<time>.wav` on exit.
|
|
170
|
+
|
|
171
|
+
## Security
|
|
172
|
+
|
|
173
|
+
With the default `pi` brain the agent has **full access**: it reads and writes files and runs shell commands in
|
|
174
|
+
the current folder, by voice. Recognition makes mistakes. Run Beseda only in folders where that is acceptable,
|
|
175
|
+
and keep them under version control.
|
|
176
|
+
|
|
177
|
+
## Privacy
|
|
178
|
+
|
|
179
|
+
- Recognition, synthesis with `silero` or `say`, logs and recordings stay on your Mac.
|
|
180
|
+
- What you say to the assistant (after the wake word) is sent to the LLM provider: DeepSeek by default.
|
|
181
|
+
- With `tts = "edge"` the answers are sent to Microsoft.
|
|
182
|
+
- Logs contain the full text of your dialogs, including phrases that weren't addressed to the assistant;
|
|
183
|
+
they are kept for `log-days` days.
|
|
184
|
+
|
|
185
|
+
## Model licenses
|
|
186
|
+
|
|
187
|
+
Beseda's code is MIT, and no models are bundled: they download to your machine on first use.
|
|
188
|
+
- **Silero TTS** (default voice): [CC BY-NC-SA 4.0](https://github.com/snakers4/silero-models/blob/master/LICENSE),
|
|
189
|
+
**non-commercial use only**. For commercial use pick `say` or `edge`, or obtain a license from Silero.
|
|
190
|
+
- **Whisper** models and the Silero VAD used by whisper.cpp: MIT.
|
|
191
|
+
- **Edge TTS** uses an unofficial endpoint of the Microsoft Edge read-aloud service and may stop working.
|
|
192
|
+
|
|
193
|
+
## Extending
|
|
194
|
+
|
|
195
|
+
- A brain (`beseda/brains.py`) yields `("text", …)`, `("tool", …)`, `("error", …)` events and supports `abort()`;
|
|
196
|
+
register it in `BRAINS`.
|
|
197
|
+
- A TTS engine (`beseda/tts.py`) subclasses `PcmEngine` with `render(text) -> PCM`; register it in `TTS_ENGINES`
|
|
198
|
+
and list its voices under `[voices]` in each language pack.
|
|
199
|
+
- A language is a TOML file, see [Languages](#languages).
|
|
200
|
+
|
|
201
|
+
## Development
|
|
202
|
+
|
|
203
|
+
```bash
|
|
204
|
+
uv sync
|
|
205
|
+
uv run pytest
|
|
206
|
+
uv tool install --editable . # the beseda command picks up code changes
|
|
207
|
+
uv run python scripts/demo.py # re-record docs/demo-ru.gif and .mp4; --language en for the English one (needs brew install agg ffmpeg)
|
|
208
|
+
git tag v0.1.0 && git push origin v0.1.0 # release: CI tests and publishes to PyPI (the tag must match the version in pyproject.toml)
|
|
209
|
+
```
|
|
210
|
+
|
|
211
|
+
## License
|
|
212
|
+
|
|
213
|
+
[MIT](https://github.com/mikhail-angelov/beseda/blob/main/LICENSE)
|
beseda-0.1.0/README.md
ADDED
|
@@ -0,0 +1,181 @@
|
|
|
1
|
+
# Beseda
|
|
2
|
+
|
|
3
|
+
**Voice conversations with your coding agent.** Say “Alice, …” (in Russian, “Вика, …”) and talk to an AI agent in English or Russian, right
|
|
4
|
+
from the terminal: speech recognition and synthesis run locally on your Mac, the agent works in the current folder.
|
|
5
|
+
|
|
6
|
+
[Русская версия](https://github.com/mikhail-angelov/beseda/blob/main/README.ru.md)
|
|
7
|
+
|
|
8
|
+

|
|
9
|
+
|
|
10
|
+
▶ [The same conversation with sound (MP4)](https://github.com/mikhail-angelov/beseda/blob/main/docs/demo-en.mp4) ([Russian](https://github.com/mikhail-angelov/beseda/blob/main/docs/demo-ru.mp4)). The user's phrases are spoken by a second Silero voice
|
|
11
|
+
instead of a microphone; recognition, the pi agent and the answers are the real app. Long waits in the GIF are shortened.
|
|
12
|
+
|
|
13
|
+
```
|
|
14
|
+
microphone → Silero VAD + whisper.cpp (local) → brain: pi agent or DeepSeek → TTS: Silero (local) → speakers
|
|
15
|
+
```
|
|
16
|
+
|
|
17
|
+
> **Status:** alpha. macOS on Apple Silicon only. Russian (default) and English; more languages are a TOML file away.
|
|
18
|
+
|
|
19
|
+
## Features
|
|
20
|
+
|
|
21
|
+
- **Wake word, like a smart speaker.** Only phrases addressed to «Вика» reach the model; after an answer you can
|
|
22
|
+
keep talking without the wake word, «стоп» ends the conversation, «подожди» gives you time to think.
|
|
23
|
+
- **Local speech.** whisper.cpp on the Mac GPU (Metal) for recognition, Silero for synthesis: from the
|
|
24
|
+
first word of the answer to sound in 0.1–0.25 s.
|
|
25
|
+
- **Pluggable brains.** The [pi](https://www.npmjs.com/package/@earendil-works/pi-coding-agent) coding agent
|
|
26
|
+
(reads and edits files, runs commands) or a plain DeepSeek chat; adding Claude or Codex is one class.
|
|
27
|
+
- **Observability.** Every session writes a log with a per-turn latency timeline: recognition, first token,
|
|
28
|
+
first audio, tool calls.
|
|
29
|
+
- **Dialog recording.** The whole conversation as one WAV, with the real pauses.
|
|
30
|
+
|
|
31
|
+
## Requirements
|
|
32
|
+
|
|
33
|
+
- macOS on Apple Silicon, Python 3.12+, [uv](https://docs.astral.sh/uv/), `brew install portaudio`
|
|
34
|
+
- For `--tts edge`: `brew install ffmpeg`
|
|
35
|
+
- For the default brain: `npm install -g @earendil-works/pi-coding-agent` with a DeepSeek key configured in pi.
|
|
36
|
+
For `--brain deepseek`: the `DEEPSEEK_API_KEY` environment variable.
|
|
37
|
+
|
|
38
|
+
## Install
|
|
39
|
+
|
|
40
|
+
```bash
|
|
41
|
+
brew install portaudio
|
|
42
|
+
uv tool install beseda
|
|
43
|
+
```
|
|
44
|
+
|
|
45
|
+
Models download on first launch into `~/.beseda/models/` (Whisper small ~490 MB, Silero ~145 MB, VAD ~1 MB).
|
|
46
|
+
|
|
47
|
+
## Use
|
|
48
|
+
|
|
49
|
+
```bash
|
|
50
|
+
cd ~/some/project # the agent works in the current folder
|
|
51
|
+
beseda # Russian
|
|
52
|
+
beseda --language en # English
|
|
53
|
+
```
|
|
54
|
+
|
|
55
|
+
The table shows the Russian phrases; the English pack has its own (“Alice, …”, “hold on”, “that's all”).
|
|
56
|
+
|
|
57
|
+
| You say | What happens |
|
|
58
|
+
|---|---|
|
|
59
|
+
| «Вика, какая погода?» | Conversation starts (Tink sound); «какая погода?» goes to the model |
|
|
60
|
+
| «Вика» | A beep, then it waits for the request |
|
|
61
|
+
| anything, within `--follow-up` s after an answer (8 s) | Goes to the model without the wake word; the status line counts down |
|
|
62
|
+
| «Подожди», «дай подумать», «секунду» | Not sent to the model; the wait extends to `--hold` s (2 min) |
|
|
63
|
+
| «Стоп», «хватит», «спасибо, всё», or silence | Conversation ends (Bottle sound); the wake word is needed again |
|
|
64
|
+
| anything else without the wake word | Ignored, shown dimmed |
|
|
65
|
+
|
|
66
|
+
Keys: **Space** turns the microphone on/off, **Esc** interrupts the answer, **q** quits.
|
|
67
|
+
|
|
68
|
+
The microphone is off while the assistant speaks, so it never hears itself; interrupting by voice isn't
|
|
69
|
+
supported yet. The macOS microphone indicator stays on while Beseda runs: the stream must stay open to hear
|
|
70
|
+
the wake word.
|
|
71
|
+
|
|
72
|
+
## Configuration
|
|
73
|
+
|
|
74
|
+
Any option can be set in `~/.beseda/config.toml`; command-line flags win.
|
|
75
|
+
|
|
76
|
+
```toml
|
|
77
|
+
language = "ru" # ru | en | your own pack
|
|
78
|
+
brain = "pi" # pi | deepseek
|
|
79
|
+
model = "deepseek/deepseek-v4-flash"
|
|
80
|
+
whisper = "small" # small | turbo
|
|
81
|
+
vocabulary = ["JavaScript", "DeepSeek"]
|
|
82
|
+
tts = "silero" # silero | edge | say
|
|
83
|
+
voice = "baya"
|
|
84
|
+
wake-word = "вика" # default comes from the language pack; "" answers everything
|
|
85
|
+
follow-up = 8
|
|
86
|
+
hold = 120
|
|
87
|
+
record = true # or a file path
|
|
88
|
+
log-days = 14
|
|
89
|
+
```
|
|
90
|
+
|
|
91
|
+
See `beseda --help` for the full list.
|
|
92
|
+
|
|
93
|
+
## Languages
|
|
94
|
+
|
|
95
|
+
Everything that depends on the spoken language lives in a language pack, a TOML file: Whisper's language and
|
|
96
|
+
style prompt, the voice prompt for the model, the wake word and its grammatical endings, stop and hold phrases,
|
|
97
|
+
default TTS voices and the Silero model, and the terminal UI strings.
|
|
98
|
+
|
|
99
|
+
Built-in packs: [`ru`](https://github.com/mikhail-angelov/beseda/blob/main/beseda/languages/ru.toml) (default) and [`en`](https://github.com/mikhail-angelov/beseda/blob/main/beseda/languages/en.toml). To change a pack
|
|
100
|
+
or add a language, put a file into `~/.beseda/languages/`: `ru.toml` there overrides the built-in one, `de.toml`
|
|
101
|
+
adds German (`beseda --language de`). Copy a built-in pack as a starting point; every key is required.
|
|
102
|
+
|
|
103
|
+
## Speech recognition
|
|
104
|
+
|
|
105
|
+
Techniques carried over from [Vadic](https://github.com/mikhail-angelov/vadic) and checked on real dialogs:
|
|
106
|
+
loudness normalization before recognition, Whisper's own VAD (without it a cough becomes «Спасибо.», which is a
|
|
107
|
+
stop phrase), a style prompt for punctuation plus your `vocabulary` for terms, greedy decoding at temperature 0.
|
|
108
|
+
|
|
109
|
+
| `whisper` | Time per phrase (M1) | Notes |
|
|
110
|
+
|---|---|---|
|
|
111
|
+
| `small` (default) | ~0.5 s | Occasional wrong words |
|
|
112
|
+
| `turbo` (large-v3-turbo-q5_0) | ~2.1 s | Far more accurate; 574 MB |
|
|
113
|
+
|
|
114
|
+
Models other apps already downloaded (VoiceInk, Vadic) are reused.
|
|
115
|
+
|
|
116
|
+
## Speech synthesis
|
|
117
|
+
|
|
118
|
+
| `tts` | Russian voices | English voices | Runs | Per sentence (ru) | CPU per second of speech | RAM |
|
|
119
|
+
|---|---|---|---|---|---|---|
|
|
120
|
+
| `silero` (default) | xenia, baya, kseniya, aidar, eugene | en_0 … en_4 | locally | 0.04 s (en: ~0.35 s) | 16 ms | ~760 MB |
|
|
121
|
+
| `say` | Milena | Daniel | locally (macOS) | 0.6 s | 140 ms | ~40 MB |
|
|
122
|
+
| `edge` (experimental) | ru-RU-SvetlanaNeural, ru-RU-DmitryNeural | en-US-AriaNeural, en-US-GuyNeural | Microsoft cloud | 1–2 s | 60 ms | ~55 MB |
|
|
123
|
+
|
|
124
|
+
Silero's Russian model skips digits and Latin letters, so the Russian voice prompt asks the model to write numbers
|
|
125
|
+
and names in Russian words. Compare the voices by ear: `beseda-samples [--language en]` writes the same phrase in
|
|
126
|
+
every voice to `~/Downloads/beseda-tts-samples/`.
|
|
127
|
+
|
|
128
|
+
## Logs and recordings
|
|
129
|
+
|
|
130
|
+
Each session logs to `~/.beseda/logs/beseda-<time>.log`; logs older than `log-days` are deleted on start.
|
|
131
|
+
|
|
132
|
+
```bash
|
|
133
|
+
grep summary ~/.beseda/logs/*.log | tail # latency per turn: stt, llm_first_token, tts_first_audio, voice_to_voice
|
|
134
|
+
grep -E 'ERROR|WARNING' ~/.beseda/logs/*.log # incidents
|
|
135
|
+
```
|
|
136
|
+
|
|
137
|
+
`--debug` adds every pi event. `--record` saves the dialog to `~/Downloads/beseda-<time>.wav` on exit.
|
|
138
|
+
|
|
139
|
+
## Security
|
|
140
|
+
|
|
141
|
+
With the default `pi` brain the agent has **full access**: it reads and writes files and runs shell commands in
|
|
142
|
+
the current folder, by voice. Recognition makes mistakes. Run Beseda only in folders where that is acceptable,
|
|
143
|
+
and keep them under version control.
|
|
144
|
+
|
|
145
|
+
## Privacy
|
|
146
|
+
|
|
147
|
+
- Recognition, synthesis with `silero` or `say`, logs and recordings stay on your Mac.
|
|
148
|
+
- What you say to the assistant (after the wake word) is sent to the LLM provider: DeepSeek by default.
|
|
149
|
+
- With `tts = "edge"` the answers are sent to Microsoft.
|
|
150
|
+
- Logs contain the full text of your dialogs, including phrases that weren't addressed to the assistant;
|
|
151
|
+
they are kept for `log-days` days.
|
|
152
|
+
|
|
153
|
+
## Model licenses
|
|
154
|
+
|
|
155
|
+
Beseda's code is MIT, and no models are bundled: they download to your machine on first use.
|
|
156
|
+
- **Silero TTS** (default voice): [CC BY-NC-SA 4.0](https://github.com/snakers4/silero-models/blob/master/LICENSE),
|
|
157
|
+
**non-commercial use only**. For commercial use pick `say` or `edge`, or obtain a license from Silero.
|
|
158
|
+
- **Whisper** models and the Silero VAD used by whisper.cpp: MIT.
|
|
159
|
+
- **Edge TTS** uses an unofficial endpoint of the Microsoft Edge read-aloud service and may stop working.
|
|
160
|
+
|
|
161
|
+
## Extending
|
|
162
|
+
|
|
163
|
+
- A brain (`beseda/brains.py`) yields `("text", …)`, `("tool", …)`, `("error", …)` events and supports `abort()`;
|
|
164
|
+
register it in `BRAINS`.
|
|
165
|
+
- A TTS engine (`beseda/tts.py`) subclasses `PcmEngine` with `render(text) -> PCM`; register it in `TTS_ENGINES`
|
|
166
|
+
and list its voices under `[voices]` in each language pack.
|
|
167
|
+
- A language is a TOML file, see [Languages](#languages).
|
|
168
|
+
|
|
169
|
+
## Development
|
|
170
|
+
|
|
171
|
+
```bash
|
|
172
|
+
uv sync
|
|
173
|
+
uv run pytest
|
|
174
|
+
uv tool install --editable . # the beseda command picks up code changes
|
|
175
|
+
uv run python scripts/demo.py # re-record docs/demo-ru.gif and .mp4; --language en for the English one (needs brew install agg ffmpeg)
|
|
176
|
+
git tag v0.1.0 && git push origin v0.1.0 # release: CI tests and publishes to PyPI (the tag must match the version in pyproject.toml)
|
|
177
|
+
```
|
|
178
|
+
|
|
179
|
+
## License
|
|
180
|
+
|
|
181
|
+
[MIT](https://github.com/mikhail-angelov/beseda/blob/main/LICENSE)
|
|
File without changes
|