agentvow 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- agentvow-0.1.0/CHANGELOG.md +14 -0
- agentvow-0.1.0/LICENSE +21 -0
- agentvow-0.1.0/MANIFEST.in +2 -0
- agentvow-0.1.0/PKG-INFO +101 -0
- agentvow-0.1.0/README.md +81 -0
- agentvow-0.1.0/agentvow/__init__.py +2 -0
- agentvow-0.1.0/agentvow/__main__.py +3 -0
- agentvow-0.1.0/agentvow/adapters.py +184 -0
- agentvow-0.1.0/agentvow/api_diff.py +85 -0
- agentvow-0.1.0/agentvow/ci.py +59 -0
- agentvow-0.1.0/agentvow/claims.py +64 -0
- agentvow-0.1.0/agentvow/cli.py +429 -0
- agentvow-0.1.0/agentvow/decision.py +289 -0
- agentvow-0.1.0/agentvow/demo.py +64 -0
- agentvow-0.1.0/agentvow/doctor.py +188 -0
- agentvow-0.1.0/agentvow/envsetup.py +157 -0
- agentvow-0.1.0/agentvow/reality.py +339 -0
- agentvow-0.1.0/agentvow/report.py +198 -0
- agentvow-0.1.0/agentvow/runner.py +376 -0
- agentvow-0.1.0/agentvow.egg-info/PKG-INFO +101 -0
- agentvow-0.1.0/agentvow.egg-info/SOURCES.txt +42 -0
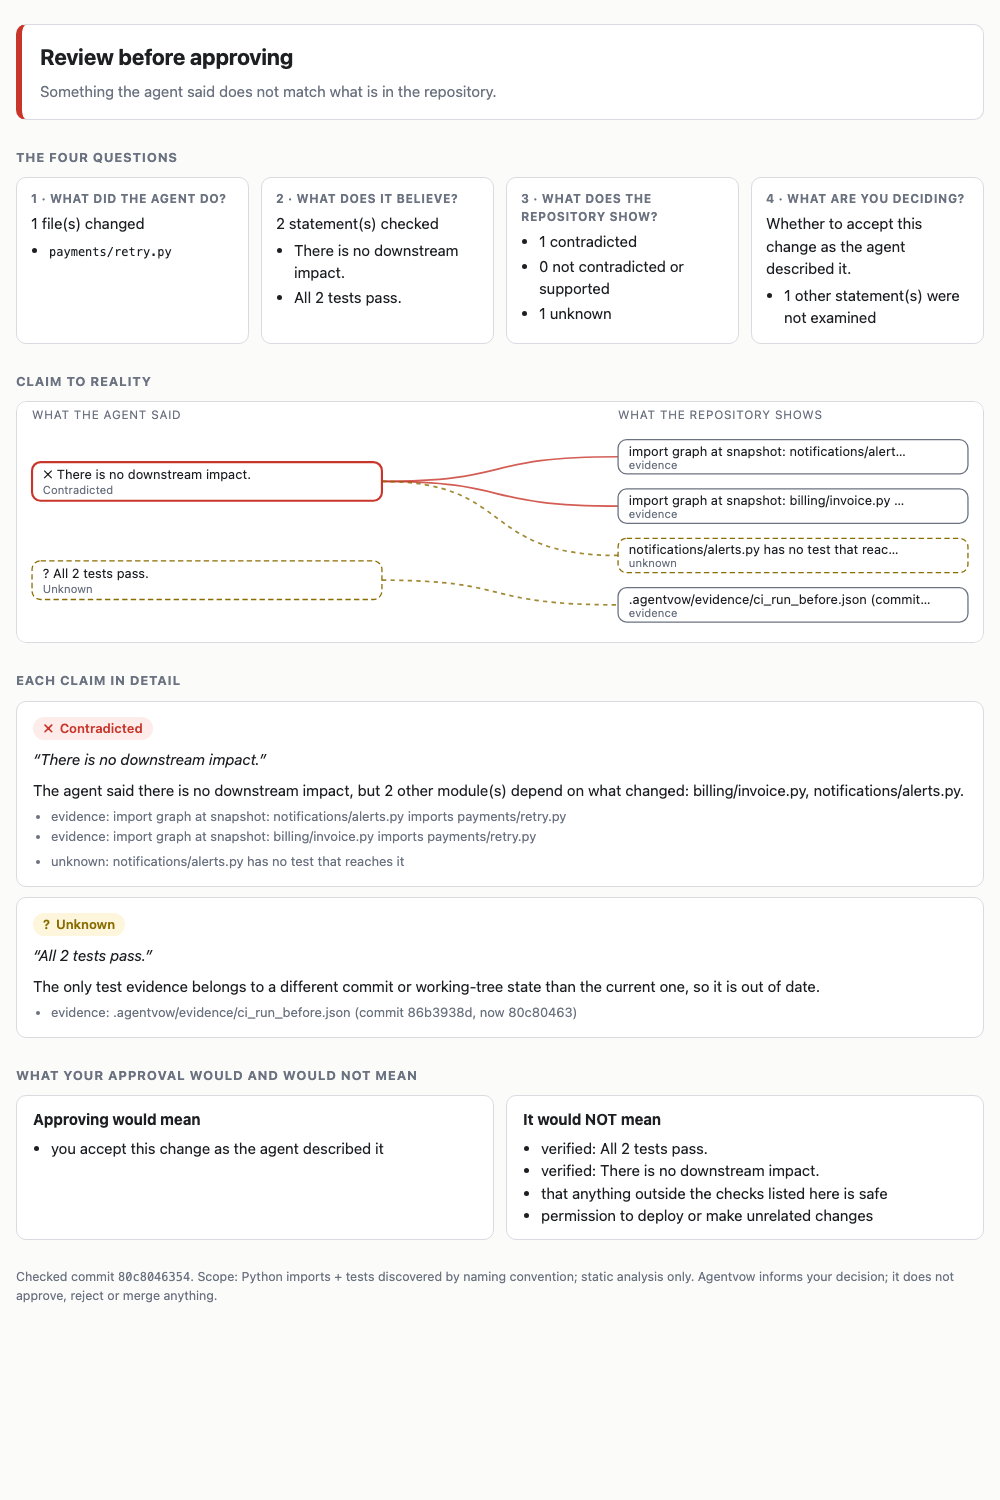
- agentvow-0.1.0/agentvow.egg-info/dependency_links.txt +1 -0
- agentvow-0.1.0/agentvow.egg-info/entry_points.txt +2 -0
- agentvow-0.1.0/agentvow.egg-info/top_level.txt +1 -0
- agentvow-0.1.0/docs/images/report.png +0 -0
- agentvow-0.1.0/pyproject.toml +32 -0
- agentvow-0.1.0/setup.cfg +4 -0
- agentvow-0.1.0/tests/test_adapters.py +116 -0
- agentvow-0.1.0/tests/test_bounds.py +32 -0
- agentvow-0.1.0/tests/test_check.py +214 -0
- agentvow-0.1.0/tests/test_copilot_format.py +207 -0
- agentvow-0.1.0/tests/test_demo.py +20 -0
- agentvow-0.1.0/tests/test_doctor.py +109 -0
- agentvow-0.1.0/tests/test_home.py +41 -0
- agentvow-0.1.0/tests/test_instructions.py +71 -0
- agentvow-0.1.0/tests/test_policy.py +79 -0
- agentvow-0.1.0/tests/test_prompt_hook.py +101 -0
- agentvow-0.1.0/tests/test_report.py +66 -0
- agentvow-0.1.0/tests/test_review2.py +64 -0
- agentvow-0.1.0/tests/test_review_fixes.py +271 -0
- agentvow-0.1.0/tests/test_runner.py +232 -0
- agentvow-0.1.0/tests/test_sandbox.py +85 -0
- agentvow-0.1.0/tests/test_security_fixes.py +224 -0
- agentvow-0.1.0/tests/test_turns.py +175 -0
|
@@ -0,0 +1,14 @@
|
|
|
1
|
+
# Changelog
|
|
2
|
+
|
|
3
|
+
## 0.1.0 (release candidate, 2026-10-08)
|
|
4
|
+
First feature-complete prototype. Not a safety verdict; see `docs/SECURITY_MODEL.md` and the limits in README.
|
|
5
|
+
- Claim checking (tests pass with counts, backward compatible, no downstream impact) against the repository, sandboxed test runs (macOS), CI reading, differential regression rule, fail-closed statuses and exit codes.
|
|
6
|
+
- Visual HTML report, markdown summary, JSON; hook for Claude Code and GitHub Copilot (Stop/agentStop) with sealed results; VS Code extension (status bar, notifications, `@agentvow`); GitHub Action; `doctor`; `agent-instructions`.
|
|
7
|
+
- Security hardening after three adversarial reviews (sandboxed installs/tests, signed evidence and seals, symlink-safe writes, hardened git).
|
|
8
|
+
- Studies and honest limits in `docs/research/`.
|
|
9
|
+
|
|
10
|
+
### Unreleased
|
|
11
|
+
- `agentvow demo` and VS Code command "Try the demo"; second adversarial review fixes (see docs/SECURITY_MODEL.md).
|
|
12
|
+
- Per-turn change tracking (changes counted since the previous check, signed state file); `--background-tests` for the hook.
|
|
13
|
+
- Linux test sandbox (bubblewrap), validated in CI on ubuntu and macos; sandbox guarantees tested directly (tests/test_sandbox.py).
|
|
14
|
+
- Renamed from the working name AgentMirror to Agentvow: package/module/command `agentvow`, folder `.agentvow/`, env `AGENTVOW_*`, VS Code ids `agentvow.*`. Results saved under the old `.agentmirror/` folder are not read.
|
agentvow-0.1.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Agentvow contributors
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
agentvow-0.1.0/PKG-INFO
ADDED
|
@@ -0,0 +1,101 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: agentvow
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Check a coding agent's claims against the repository before you approve.
|
|
5
|
+
License: MIT
|
|
6
|
+
Project-URL: Homepage, https://github.com/NavikkumarModi/Agentvow
|
|
7
|
+
Project-URL: Issues, https://github.com/NavikkumarModi/Agentvow/issues
|
|
8
|
+
Keywords: ai-agents,verification,code-review,copilot,claude-code,hooks
|
|
9
|
+
Classifier: Development Status :: 3 - Alpha
|
|
10
|
+
Classifier: Intended Audience :: Developers
|
|
11
|
+
Classifier: License :: OSI Approved :: MIT License
|
|
12
|
+
Classifier: Operating System :: MacOS
|
|
13
|
+
Classifier: Operating System :: POSIX :: Linux
|
|
14
|
+
Classifier: Programming Language :: Python :: 3
|
|
15
|
+
Classifier: Topic :: Software Development :: Quality Assurance
|
|
16
|
+
Requires-Python: >=3.10
|
|
17
|
+
Description-Content-Type: text/markdown
|
|
18
|
+
License-File: LICENSE
|
|
19
|
+
Dynamic: license-file
|
|
20
|
+
|
|
21
|
+
# Agentvow
|
|
22
|
+
|
|
23
|
+
When a coding agent says "all tests pass" or "nothing else depends on this", Agentvow checks that against the repository and tells you what it could confirm, what it contradicted, and what it could not check. It runs **outside** the agent (an agent must not grade itself), uses no LLM, and never approves, rejects or merges anything.
|
|
24
|
+
|
|
25
|
+
**Status: 0.1.0 release candidate (prototype).** Not a safety verdict. Python repositories; running tests needs macOS or Linux (bubblewrap). See [Known limits](#known-limits) and `docs/SECURITY_MODEL.md`.
|
|
26
|
+
|
|
27
|
+
> **Name:** Agentvow (an agent's claims are vows; this checks them). It was developed under the working name AgentMirror; the name was changed because that name, and its Python module, belong to an unrelated PyPI project.
|
|
28
|
+
|
|
29
|
+
## Quick start
|
|
30
|
+
```bash
|
|
31
|
+
pip install agentvow # once published; from a checkout: pip install . or: pip install dist/agentvow-0.1.0-py3-none-any.whl (no dependencies; Python 3.10+)
|
|
32
|
+
agentvow doctor --repo /path/to/project # checks your setup and runs the whole hook path end to end
|
|
33
|
+
echo "I changed X. All 12 tests pass. Nothing else depends on it." | agentvow check --repo /path/to/project
|
|
34
|
+
agentvow check --repo . --transcript msg.txt --run-tests --python venv/bin/python # also run the tests (sandboxed, macOS/Linux)
|
|
35
|
+
agentvow check --repo . --transcript msg.txt --ci --html report.html # also read CI results; write a visual report
|
|
36
|
+
```
|
|
37
|
+
Exit codes: `0` no contradiction found (scoped), `1` review required, `2` insufficient evidence, `3` tool error. Other options: `--markdown`, `--json`, `--session <Claude Code session.jsonl>`, `--base <ref>`, `--test-cmd`, `--test-timeout`, `--setup auto`, `--new-test-failures review`.
|
|
38
|
+
|
|
39
|
+
|
|
40
|
+
|
|
41
|
+
## See it in 10 seconds
|
|
42
|
+
```bash
|
|
43
|
+
agentvow demo # builds a small demo repo, checks "no downstream impact" against it and writes a sealed result
|
|
44
|
+
```
|
|
45
|
+
In VS Code run **Agentvow: Try the demo**: it shows the red verdict panel and copies a prompt you can paste into Copilot (in the demo folder, with the hook added) to see the same on a real agent turn.
|
|
46
|
+
|
|
47
|
+
## What it checks
|
|
48
|
+
| Claim in the agent's message | How it is checked |
|
|
49
|
+
|---|---|
|
|
50
|
+
| "tests pass" (with an optional count) | tests run at the base and head states in a sandbox; a regression is a test that passed before and fails now; the claimed count is compared; failures that also occur at base are treated as environmental; deleted/skipped tests and modified existing tests prevent a plain "supported"; CI test jobs for the commit are read with `--ci` |
|
|
51
|
+
| "backward compatible" | static public-API diff of changed Python files (removed or renamed names and parameters, new required parameters, `__init__` re-exports) |
|
|
52
|
+
| "no downstream impact" | static import graph (src layout aware); deleted modules, dynamic imports and non-Python code make the result UNKNOWN |
|
|
53
|
+
|
|
54
|
+
Anything else the agent says is listed as **unchecked**, and the report says how many statements were not examined. **UNKNOWN is a real result**: missing evidence, a failed collector, an unreadable message or an unfamiliar format never become "OK". The best possible status is `NO CONTRADICTION FOUND (scoped, not a safety verdict)`.
|
|
55
|
+
|
|
56
|
+
## Where it plugs in (and how well each is verified)
|
|
57
|
+
| Where | How | Status |
|
|
58
|
+
|---|---|---|
|
|
59
|
+
| **GitHub Copilot in VS Code** (agent chat, Copilot CLI engine) | `.github/hooks/agentvow.json` (extension command *Agentvow: Add the agent hook*) | **Verified on a real run:** Copilot ran the hook, its payload and session file (`events.jsonl`) are parsed, the result is sealed and detected by the extension. Hooks are a Preview feature |
|
|
60
|
+
| **Claude Code** | Stop hook `agentvow check --hook` | Session format and payload verified |
|
|
61
|
+
| Copilot CLI (terminal), Copilot cloud agent | same hook file | From documentation only |
|
|
62
|
+
| Codex, Cursor, Gemini CLI | their stop hooks → `agentvow check --hook` | Not tested; `AGENTVOW_DEBUG=1` records only the *structure* of what an agent sends so an adapter can be built |
|
|
63
|
+
| Any agent's pull request | GitHub Action `action.yml`: PR description as the claim, CI results, comment + report | Shell step tested locally; not run on GitHub |
|
|
64
|
+
| Anything else | paste or pipe the message; VS Code commands for clipboard/selection | Tested |
|
|
65
|
+
|
|
66
|
+
## Seeing the verdict
|
|
67
|
+
Copilot keeps only `decision`/`reason` from a hook's output, so **a hook cannot add text to Copilot's own reply.** The verdict is shown in:
|
|
68
|
+
- the VS Code **status bar**, a **notification** (`agentvow.notify`: `review` default, `always`, `never`) and the **report panel**; the extension logs to the *Agentvow* output channel;
|
|
69
|
+
- `@agentvow` in the chat: prints the last sealed verdict as its own message (not part of Copilot's reply);
|
|
70
|
+
- `agentvow agent-instructions --write .github/copilot-instructions.md`: tells the chat agent to run the check itself and show its output (works through the model; the agent chooses the draft it checks, so the independent hook remains the check that does not depend on the agent);
|
|
71
|
+
- `agentvow check --hook --feedback-to-agent` (opt-in): asks the agent, once, to revise an answer with a contradicted claim (the only mode in which the hook can block);
|
|
72
|
+
- `agentvow check --hook --background-tests` (opt-in): the hook answers at once with what it can see, then runs your tests in the background (sandboxed, macOS/Linux) and updates the verdict when they finish, so slow suites do not hit the agent's hook timeout. Changes are counted since the previous check in the repository (not since your last commit), so earlier uncommitted work is not blamed on the agent.
|
|
73
|
+
- **experimental, off by default:** a `UserPromptSubmit` hook (`agentvow prompt-hook`) that tells the agent the last verdict on your next prompt. In one live session the first delivery coincided with a Copilot chat that stalled (cause unproven).
|
|
74
|
+
Details and a step-by-step live test: `docs/LIVE_TESTING.md`.
|
|
75
|
+
|
|
76
|
+
## Install the VS Code extension
|
|
77
|
+
```bash
|
|
78
|
+
"/Applications/Visual Studio Code.app/Contents/Resources/app/bin/code" --install-extension dist/agentvow-0.1.0.vsix --force
|
|
79
|
+
```
|
|
80
|
+
Then **Developer: Reload Window**. The extension is plain JavaScript with no dependencies; it calls the `agentvow` command, which must be reachable by path (use the full path in `agentvow.command` if VS Code does not see your shell's PATH).
|
|
81
|
+
|
|
82
|
+
## Safety in one paragraph
|
|
83
|
+
Running tests executes the project's code. It runs in a sandbox: macOS `sandbox-exec` or Linux `bubblewrap` (`apt install bubblewrap`; on Ubuntu 24.04+ unprivileged user namespaces must be allowed, e.g. `sysctl kernel.apparmor_restrict_unprivileged_userns=0`; `agentvow doctor` tells you). Network denied, file writes only inside a throwaway worktree plus a private scratch directory, signing key and credential folders unreadable, whole process group killed on timeout; on Windows, or where no working sandbox exists, Agentvow refuses to run tests (static checks and CI reading still work; `agentvow doctor` says which). The Linux sandbox makes the whole filesystem read-only; the macOS one allows OS services by default (a review showed a Mach service could still write outside it; common helpers like `open`/`defaults`/`osascript` are blocked, which is not complete containment). Results are HMAC-sealed with a key outside the repository, which stops casual forgery and files copied from elsewhere, **but test results are only as trustworthy as the repository's own test code**: a hostile `conftest.py` can print fake pass counts. Treat a "no contradiction" on an untrusted repository accordingly. Text from agents and repositories is length-bounded, stripped of control characters and escaped in reports and in plain-text output. Full model, reviews and open weaknesses: `docs/SECURITY_MODEL.md`, `docs/research/RISKS.md`.
|
|
84
|
+
|
|
85
|
+
## Evidence so far (and what it does not show)
|
|
86
|
+
- Agent PR claims in the wild (688 public Python PRs from five agents that claim tests pass): CI test jobs could judge 33%; of those about 27% had a failing test job (clustered in a few repositories; not an agent ranking). `docs/research/CI_CLAIM_STUDY.md`
|
|
87
|
+
- Local runs on unfamiliar repos with automatic setup reached a verdict for 29% of PRs; half stopped on a missing dependency. `docs/research/LOCAL_COVERAGE.md`
|
|
88
|
+
- Planted faults (authored by us, 15 real PRs): 26 of 30 test-detectable breaks attributed, no false alarms. **Detection on real bad PRs is not demonstrated** (the zero-config setup could not run most of them). `docs/research/PLANTED_FAULTS.md`, `docs/research/DETECTION_STUDY.md`
|
|
89
|
+
- Novelty is **not** claimed: the closest prior work (Assay, EA-Graph, backcheck and others) and what remains open are in `docs/research/NOVELTY_BOUNDARY.md`.
|
|
90
|
+
|
|
91
|
+
## Known limits
|
|
92
|
+
Python only for impact and API checks; claim extraction is rule-based (three claim types); CI job classification is by name; trivialised tests are not detected; tests that start daemons can hang under the sandbox (ends at `--test-timeout`); hooks and Copilot integration are Preview features and only the Copilot CLI engine inside VS Code has been observed live; Windows has no test sandbox (tests are refused there); the chat-injection routes go through the model; one annotator behind every hand-validated number.
|
|
93
|
+
|
|
94
|
+
## Develop and validate
|
|
95
|
+
```bash
|
|
96
|
+
scripts/validate_all.sh # tests, consistency, secret scan, wheel + clean-room install, extension package, leaks (builds dist/)
|
|
97
|
+
python3 -m unittest discover -s tests && node --test vscode/test/extension.test.js vscode/test/helpers.test.js
|
|
98
|
+
```
|
|
99
|
+
Design and research: `docs/research/` (start with `NOVELTY_BOUNDARY.md`, `RISKS.md`, `PILOT_P0.md`), product notes `docs/product/`, rules for contributors `CLAUDE.md`. License: MIT (`LICENSE`).
|
|
100
|
+
|
|
101
|
+
<!-- test counts, checked by scripts/validate_all.sh: 208 Python tests, 32 node tests -->
|
agentvow-0.1.0/README.md
ADDED
|
@@ -0,0 +1,81 @@
|
|
|
1
|
+
# Agentvow
|
|
2
|
+
|
|
3
|
+
When a coding agent says "all tests pass" or "nothing else depends on this", Agentvow checks that against the repository and tells you what it could confirm, what it contradicted, and what it could not check. It runs **outside** the agent (an agent must not grade itself), uses no LLM, and never approves, rejects or merges anything.
|
|
4
|
+
|
|
5
|
+
**Status: 0.1.0 release candidate (prototype).** Not a safety verdict. Python repositories; running tests needs macOS or Linux (bubblewrap). See [Known limits](#known-limits) and `docs/SECURITY_MODEL.md`.
|
|
6
|
+
|
|
7
|
+
> **Name:** Agentvow (an agent's claims are vows; this checks them). It was developed under the working name AgentMirror; the name was changed because that name, and its Python module, belong to an unrelated PyPI project.
|
|
8
|
+
|
|
9
|
+
## Quick start
|
|
10
|
+
```bash
|
|
11
|
+
pip install agentvow # once published; from a checkout: pip install . or: pip install dist/agentvow-0.1.0-py3-none-any.whl (no dependencies; Python 3.10+)
|
|
12
|
+
agentvow doctor --repo /path/to/project # checks your setup and runs the whole hook path end to end
|
|
13
|
+
echo "I changed X. All 12 tests pass. Nothing else depends on it." | agentvow check --repo /path/to/project
|
|
14
|
+
agentvow check --repo . --transcript msg.txt --run-tests --python venv/bin/python # also run the tests (sandboxed, macOS/Linux)
|
|
15
|
+
agentvow check --repo . --transcript msg.txt --ci --html report.html # also read CI results; write a visual report
|
|
16
|
+
```
|
|
17
|
+
Exit codes: `0` no contradiction found (scoped), `1` review required, `2` insufficient evidence, `3` tool error. Other options: `--markdown`, `--json`, `--session <Claude Code session.jsonl>`, `--base <ref>`, `--test-cmd`, `--test-timeout`, `--setup auto`, `--new-test-failures review`.
|
|
18
|
+
|
|
19
|
+

|
|
20
|
+
|
|
21
|
+
## See it in 10 seconds
|
|
22
|
+
```bash
|
|
23
|
+
agentvow demo # builds a small demo repo, checks "no downstream impact" against it and writes a sealed result
|
|
24
|
+
```
|
|
25
|
+
In VS Code run **Agentvow: Try the demo**: it shows the red verdict panel and copies a prompt you can paste into Copilot (in the demo folder, with the hook added) to see the same on a real agent turn.
|
|
26
|
+
|
|
27
|
+
## What it checks
|
|
28
|
+
| Claim in the agent's message | How it is checked |
|
|
29
|
+
|---|---|
|
|
30
|
+
| "tests pass" (with an optional count) | tests run at the base and head states in a sandbox; a regression is a test that passed before and fails now; the claimed count is compared; failures that also occur at base are treated as environmental; deleted/skipped tests and modified existing tests prevent a plain "supported"; CI test jobs for the commit are read with `--ci` |
|
|
31
|
+
| "backward compatible" | static public-API diff of changed Python files (removed or renamed names and parameters, new required parameters, `__init__` re-exports) |
|
|
32
|
+
| "no downstream impact" | static import graph (src layout aware); deleted modules, dynamic imports and non-Python code make the result UNKNOWN |
|
|
33
|
+
|
|
34
|
+
Anything else the agent says is listed as **unchecked**, and the report says how many statements were not examined. **UNKNOWN is a real result**: missing evidence, a failed collector, an unreadable message or an unfamiliar format never become "OK". The best possible status is `NO CONTRADICTION FOUND (scoped, not a safety verdict)`.
|
|
35
|
+
|
|
36
|
+
## Where it plugs in (and how well each is verified)
|
|
37
|
+
| Where | How | Status |
|
|
38
|
+
|---|---|---|
|
|
39
|
+
| **GitHub Copilot in VS Code** (agent chat, Copilot CLI engine) | `.github/hooks/agentvow.json` (extension command *Agentvow: Add the agent hook*) | **Verified on a real run:** Copilot ran the hook, its payload and session file (`events.jsonl`) are parsed, the result is sealed and detected by the extension. Hooks are a Preview feature |
|
|
40
|
+
| **Claude Code** | Stop hook `agentvow check --hook` | Session format and payload verified |
|
|
41
|
+
| Copilot CLI (terminal), Copilot cloud agent | same hook file | From documentation only |
|
|
42
|
+
| Codex, Cursor, Gemini CLI | their stop hooks → `agentvow check --hook` | Not tested; `AGENTVOW_DEBUG=1` records only the *structure* of what an agent sends so an adapter can be built |
|
|
43
|
+
| Any agent's pull request | GitHub Action `action.yml`: PR description as the claim, CI results, comment + report | Shell step tested locally; not run on GitHub |
|
|
44
|
+
| Anything else | paste or pipe the message; VS Code commands for clipboard/selection | Tested |
|
|
45
|
+
|
|
46
|
+
## Seeing the verdict
|
|
47
|
+
Copilot keeps only `decision`/`reason` from a hook's output, so **a hook cannot add text to Copilot's own reply.** The verdict is shown in:
|
|
48
|
+
- the VS Code **status bar**, a **notification** (`agentvow.notify`: `review` default, `always`, `never`) and the **report panel**; the extension logs to the *Agentvow* output channel;
|
|
49
|
+
- `@agentvow` in the chat: prints the last sealed verdict as its own message (not part of Copilot's reply);
|
|
50
|
+
- `agentvow agent-instructions --write .github/copilot-instructions.md`: tells the chat agent to run the check itself and show its output (works through the model; the agent chooses the draft it checks, so the independent hook remains the check that does not depend on the agent);
|
|
51
|
+
- `agentvow check --hook --feedback-to-agent` (opt-in): asks the agent, once, to revise an answer with a contradicted claim (the only mode in which the hook can block);
|
|
52
|
+
- `agentvow check --hook --background-tests` (opt-in): the hook answers at once with what it can see, then runs your tests in the background (sandboxed, macOS/Linux) and updates the verdict when they finish, so slow suites do not hit the agent's hook timeout. Changes are counted since the previous check in the repository (not since your last commit), so earlier uncommitted work is not blamed on the agent.
|
|
53
|
+
- **experimental, off by default:** a `UserPromptSubmit` hook (`agentvow prompt-hook`) that tells the agent the last verdict on your next prompt. In one live session the first delivery coincided with a Copilot chat that stalled (cause unproven).
|
|
54
|
+
Details and a step-by-step live test: `docs/LIVE_TESTING.md`.
|
|
55
|
+
|
|
56
|
+
## Install the VS Code extension
|
|
57
|
+
```bash
|
|
58
|
+
"/Applications/Visual Studio Code.app/Contents/Resources/app/bin/code" --install-extension dist/agentvow-0.1.0.vsix --force
|
|
59
|
+
```
|
|
60
|
+
Then **Developer: Reload Window**. The extension is plain JavaScript with no dependencies; it calls the `agentvow` command, which must be reachable by path (use the full path in `agentvow.command` if VS Code does not see your shell's PATH).
|
|
61
|
+
|
|
62
|
+
## Safety in one paragraph
|
|
63
|
+
Running tests executes the project's code. It runs in a sandbox: macOS `sandbox-exec` or Linux `bubblewrap` (`apt install bubblewrap`; on Ubuntu 24.04+ unprivileged user namespaces must be allowed, e.g. `sysctl kernel.apparmor_restrict_unprivileged_userns=0`; `agentvow doctor` tells you). Network denied, file writes only inside a throwaway worktree plus a private scratch directory, signing key and credential folders unreadable, whole process group killed on timeout; on Windows, or where no working sandbox exists, Agentvow refuses to run tests (static checks and CI reading still work; `agentvow doctor` says which). The Linux sandbox makes the whole filesystem read-only; the macOS one allows OS services by default (a review showed a Mach service could still write outside it; common helpers like `open`/`defaults`/`osascript` are blocked, which is not complete containment). Results are HMAC-sealed with a key outside the repository, which stops casual forgery and files copied from elsewhere, **but test results are only as trustworthy as the repository's own test code**: a hostile `conftest.py` can print fake pass counts. Treat a "no contradiction" on an untrusted repository accordingly. Text from agents and repositories is length-bounded, stripped of control characters and escaped in reports and in plain-text output. Full model, reviews and open weaknesses: `docs/SECURITY_MODEL.md`, `docs/research/RISKS.md`.
|
|
64
|
+
|
|
65
|
+
## Evidence so far (and what it does not show)
|
|
66
|
+
- Agent PR claims in the wild (688 public Python PRs from five agents that claim tests pass): CI test jobs could judge 33%; of those about 27% had a failing test job (clustered in a few repositories; not an agent ranking). `docs/research/CI_CLAIM_STUDY.md`
|
|
67
|
+
- Local runs on unfamiliar repos with automatic setup reached a verdict for 29% of PRs; half stopped on a missing dependency. `docs/research/LOCAL_COVERAGE.md`
|
|
68
|
+
- Planted faults (authored by us, 15 real PRs): 26 of 30 test-detectable breaks attributed, no false alarms. **Detection on real bad PRs is not demonstrated** (the zero-config setup could not run most of them). `docs/research/PLANTED_FAULTS.md`, `docs/research/DETECTION_STUDY.md`
|
|
69
|
+
- Novelty is **not** claimed: the closest prior work (Assay, EA-Graph, backcheck and others) and what remains open are in `docs/research/NOVELTY_BOUNDARY.md`.
|
|
70
|
+
|
|
71
|
+
## Known limits
|
|
72
|
+
Python only for impact and API checks; claim extraction is rule-based (three claim types); CI job classification is by name; trivialised tests are not detected; tests that start daemons can hang under the sandbox (ends at `--test-timeout`); hooks and Copilot integration are Preview features and only the Copilot CLI engine inside VS Code has been observed live; Windows has no test sandbox (tests are refused there); the chat-injection routes go through the model; one annotator behind every hand-validated number.
|
|
73
|
+
|
|
74
|
+
## Develop and validate
|
|
75
|
+
```bash
|
|
76
|
+
scripts/validate_all.sh # tests, consistency, secret scan, wheel + clean-room install, extension package, leaks (builds dist/)
|
|
77
|
+
python3 -m unittest discover -s tests && node --test vscode/test/extension.test.js vscode/test/helpers.test.js
|
|
78
|
+
```
|
|
79
|
+
Design and research: `docs/research/` (start with `NOVELTY_BOUNDARY.md`, `RISKS.md`, `PILOT_P0.md`), product notes `docs/product/`, rules for contributors `CLAUDE.md`. License: MIT (`LICENSE`).
|
|
80
|
+
|
|
81
|
+
<!-- test counts, checked by scripts/validate_all.sh: 208 Python tests, 32 node tests -->
|
|
@@ -0,0 +1,184 @@
|
|
|
1
|
+
"""Agent-agnostic input: hook payloads and transcripts from different agents.
|
|
2
|
+
|
|
3
|
+
Verified against: Claude Code session files (used in this project). Everything else is built from vendor documentation or
|
|
4
|
+
tolerant format sniffing and is NOT yet verified against real Copilot/Codex/Cursor/Gemini transcripts: when a transcript
|
|
5
|
+
cannot be understood the caller gets None and reports "nothing was verified" (never a guess).
|
|
6
|
+
"""
|
|
7
|
+
import json
|
|
8
|
+
from pathlib import Path
|
|
9
|
+
|
|
10
|
+
_TEXT_KEYS = ("text", "output_text", "content", "message", "last_assistant_message", "response")
|
|
11
|
+
_ASSIST = {"assistant", "model", "agent", "ai", "bot", "copilot"}
|
|
12
|
+
_ASSIST_TYPES = {"assistant", "assistant_message", "agent_message", "model", "model_response", "response", "agent_response"}
|
|
13
|
+
|
|
14
|
+
|
|
15
|
+
def parse_hook_payload(payload: dict) -> dict:
|
|
16
|
+
"""Normalise camelCase (Copilot CLI/cloud agent), snake_case (VS Code, Claude Code, Codex) and Cursor-style hook inputs."""
|
|
17
|
+
g = lambda *ks: next((payload[k] for k in ks if payload.get(k)), None)
|
|
18
|
+
return {
|
|
19
|
+
"cwd": g("cwd", "workingDirectory", "workspace_root", "workspaceRoot") or (g("workspace_roots") or [None])[0]
|
|
20
|
+
if isinstance(g("workspace_roots"), list) or g("cwd", "workingDirectory", "workspace_root", "workspaceRoot") else None,
|
|
21
|
+
"transcript": g("transcript_path", "transcriptPath"),
|
|
22
|
+
"message": g("last_assistant_message", "lastAssistantMessage", "final_message", "text"),
|
|
23
|
+
"session": g("session_id", "sessionId", "conversation_id"),
|
|
24
|
+
"loop": bool(g("stop_hook_active", "stopHookActive")),
|
|
25
|
+
}
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
def _is_assistant(node: dict) -> bool:
|
|
29
|
+
role = str(node.get("role", "")).lower()
|
|
30
|
+
typ = str(node.get("type", "")).lower()
|
|
31
|
+
return role in _ASSIST or typ in _ASSIST_TYPES
|
|
32
|
+
|
|
33
|
+
|
|
34
|
+
MAX_DEPTH = 40
|
|
35
|
+
|
|
36
|
+
|
|
37
|
+
def _texts(node, assistant: bool, out: list, depth: int = 0):
|
|
38
|
+
"""Collect text strings under assistant nodes (recursive; tolerant of unknown nesting; depth-bounded)."""
|
|
39
|
+
if depth > MAX_DEPTH:
|
|
40
|
+
return
|
|
41
|
+
if isinstance(node, dict):
|
|
42
|
+
a = assistant or _is_assistant(node)
|
|
43
|
+
for k, v in node.items():
|
|
44
|
+
if isinstance(v, str) and a and k in _TEXT_KEYS and v.strip() and not v.lstrip().startswith(("{", "[")):
|
|
45
|
+
if str(node.get("type", "")).lower() not in ("tool_use", "tool_result", "function_call", "tool_call", "thinking", "reasoning"):
|
|
46
|
+
out.append(v.strip())
|
|
47
|
+
elif isinstance(v, (dict, list)):
|
|
48
|
+
_texts(v, a, out, depth + 1)
|
|
49
|
+
elif isinstance(node, list):
|
|
50
|
+
for v in node:
|
|
51
|
+
_texts(v, assistant, out, depth + 1)
|
|
52
|
+
|
|
53
|
+
|
|
54
|
+
def _copilot_event_text(obj):
|
|
55
|
+
"""GitHub Copilot CLI session events (~/.copilot/session-state/<id>/events.jsonl): {"type": "assistant.message", "data": {"content": "...",
|
|
56
|
+
"phase": "final_answer"|"commentary"|None, "toolRequests": [...]}}. Only data.content is the message; tool arguments (which can hold whole
|
|
57
|
+
files under a `content` key) must never be mistaken for it. -> (text, is_final) or None when this record is not an assistant message."""
|
|
58
|
+
if isinstance(obj, dict) and obj.get("type") == "assistant.message" and isinstance(obj.get("data"), dict):
|
|
59
|
+
d = obj["data"]
|
|
60
|
+
text = d.get("content")
|
|
61
|
+
return (text.strip() if isinstance(text, str) else ""), d.get("phase") == "final_answer"
|
|
62
|
+
return None
|
|
63
|
+
|
|
64
|
+
|
|
65
|
+
def final_message_info(raw: str):
|
|
66
|
+
"""-> (text or None, is_final, is_copilot). Copilot CLI transcripts are scoped to the CURRENT turn (everything after the latest
|
|
67
|
+
user.message): when the final answer has not been flushed to the file yet this returns no text, never the previous turn's answer."""
|
|
68
|
+
last, last_final, parsed_any, copilot = None, None, False, False
|
|
69
|
+
for line in raw.splitlines():
|
|
70
|
+
line = line.strip()
|
|
71
|
+
if not line or line[0] not in "{[" or len(line) > 2_000_000:
|
|
72
|
+
continue
|
|
73
|
+
try:
|
|
74
|
+
obj = json.loads(line)
|
|
75
|
+
except (ValueError, RecursionError):
|
|
76
|
+
continue
|
|
77
|
+
parsed_any = True
|
|
78
|
+
if isinstance(obj, dict) and obj.get("type") == "user.message":
|
|
79
|
+
last = last_final = None # a new turn starts: nothing before this belongs to the answer we are looking for
|
|
80
|
+
copilot = True
|
|
81
|
+
continue
|
|
82
|
+
cop = _copilot_event_text(obj)
|
|
83
|
+
if cop is not None:
|
|
84
|
+
copilot = True
|
|
85
|
+
if cop[0]:
|
|
86
|
+
last = cop[0]
|
|
87
|
+
if cop[1]:
|
|
88
|
+
last_final = cop[0]
|
|
89
|
+
continue
|
|
90
|
+
found: list = []
|
|
91
|
+
_texts(obj, False, found)
|
|
92
|
+
if found:
|
|
93
|
+
last = "\n".join(found).strip() or last
|
|
94
|
+
if last_final:
|
|
95
|
+
return last_final, True, copilot
|
|
96
|
+
if not parsed_any:
|
|
97
|
+
try: # a single pretty-printed JSON document
|
|
98
|
+
obj = json.loads(raw[:5_000_000])
|
|
99
|
+
found = []
|
|
100
|
+
_texts(obj, False, found)
|
|
101
|
+
return (found[-1] if found else None), False, False
|
|
102
|
+
except (ValueError, RecursionError):
|
|
103
|
+
return (raw.strip()[-6000:] or None), False, False # plain text transcript (bounded)
|
|
104
|
+
return last, False, copilot
|
|
105
|
+
|
|
106
|
+
|
|
107
|
+
def final_message_from_text(raw: str):
|
|
108
|
+
return final_message_info(raw)[0]
|
|
109
|
+
|
|
110
|
+
|
|
111
|
+
MAX_TRANSCRIPT_BYTES = 8_000_000 # transcripts can be hundreds of MB; the final answer is at the end, so only the tail is read
|
|
112
|
+
|
|
113
|
+
|
|
114
|
+
def read_tail(path: Path, limit: int = MAX_TRANSCRIPT_BYTES) -> str:
|
|
115
|
+
"""The last `limit` bytes of a regular file as text (first partial line dropped). Non-regular files (fifos, devices) are refused."""
|
|
116
|
+
import os, stat
|
|
117
|
+
fd = os.open(path, os.O_RDONLY | getattr(os, "O_NONBLOCK", 0))
|
|
118
|
+
try:
|
|
119
|
+
st = os.fstat(fd)
|
|
120
|
+
if not stat.S_ISREG(st.st_mode):
|
|
121
|
+
raise OSError("not a regular file")
|
|
122
|
+
cut = st.st_size > limit
|
|
123
|
+
if cut:
|
|
124
|
+
os.lseek(fd, st.st_size - limit, os.SEEK_SET)
|
|
125
|
+
data = b""
|
|
126
|
+
while len(data) < limit:
|
|
127
|
+
chunk = os.read(fd, min(1_000_000, limit - len(data)))
|
|
128
|
+
if not chunk:
|
|
129
|
+
break
|
|
130
|
+
data += chunk
|
|
131
|
+
finally:
|
|
132
|
+
os.close(fd)
|
|
133
|
+
text = data.decode("utf-8", errors="replace")
|
|
134
|
+
return text.split("\n", 1)[1] if cut and "\n" in text else text
|
|
135
|
+
|
|
136
|
+
|
|
137
|
+
def final_message_info_file(path: Path):
|
|
138
|
+
try:
|
|
139
|
+
return final_message_info(read_tail(path))
|
|
140
|
+
except OSError:
|
|
141
|
+
return None, False, False
|
|
142
|
+
|
|
143
|
+
|
|
144
|
+
def final_message(path: Path):
|
|
145
|
+
try:
|
|
146
|
+
return final_message_from_text(read_tail(path))
|
|
147
|
+
except OSError:
|
|
148
|
+
return None
|
|
149
|
+
|
|
150
|
+
|
|
151
|
+
def shape_of(node, depth: int = 0):
|
|
152
|
+
"""The STRUCTURE of a JSON value (key names, types, string lengths), never its content: safe to share when debugging an unknown format."""
|
|
153
|
+
if depth > 6:
|
|
154
|
+
return "..."
|
|
155
|
+
if isinstance(node, dict):
|
|
156
|
+
return {str(k): shape_of(v, depth + 1) for k, v in list(node.items())[:40]}
|
|
157
|
+
if isinstance(node, list):
|
|
158
|
+
return [shape_of(node[0], depth + 1), f"... {len(node)} items"] if node else []
|
|
159
|
+
if isinstance(node, str):
|
|
160
|
+
return f"str[{len(node)}]"
|
|
161
|
+
return type(node).__name__
|
|
162
|
+
|
|
163
|
+
|
|
164
|
+
def transcript_shapes(path: Path, n: int = 4) -> dict:
|
|
165
|
+
"""Structure of the first and last few records of a JSONL transcript (no content)."""
|
|
166
|
+
from collections import deque
|
|
167
|
+
head, tail = [], deque(maxlen=n)
|
|
168
|
+
try:
|
|
169
|
+
with path.open(encoding="utf-8", errors="replace") as fh:
|
|
170
|
+
for i, line in enumerate(fh):
|
|
171
|
+
line = line[:200_000]
|
|
172
|
+
if i < n:
|
|
173
|
+
head.append(line)
|
|
174
|
+
else:
|
|
175
|
+
tail.append(line)
|
|
176
|
+
except OSError as e:
|
|
177
|
+
return {"error": type(e).__name__}
|
|
178
|
+
shapes = []
|
|
179
|
+
for line in [*head, *tail]:
|
|
180
|
+
try:
|
|
181
|
+
shapes.append(shape_of(json.loads(line)))
|
|
182
|
+
except (ValueError, RecursionError):
|
|
183
|
+
shapes.append(f"non-json line, {len(line)} chars")
|
|
184
|
+
return {"records_sampled": len(shapes), "shapes": shapes}
|
|
@@ -0,0 +1,85 @@
|
|
|
1
|
+
"""Public-API diff between two commits (Python, static): removed names and incompatible signature changes."""
|
|
2
|
+
import ast
|
|
3
|
+
import subprocess
|
|
4
|
+
|
|
5
|
+
from .reality import safe_prefix
|
|
6
|
+
from pathlib import Path
|
|
7
|
+
|
|
8
|
+
|
|
9
|
+
def _show(repo: Path, ref: str, path: str):
|
|
10
|
+
r = subprocess.run(["git", *safe_prefix(repo), "-C", str(repo), "show", f"{ref}:{path}"], capture_output=True, text=True)
|
|
11
|
+
return r.stdout if r.returncode == 0 else None
|
|
12
|
+
|
|
13
|
+
|
|
14
|
+
def _sig(fn):
|
|
15
|
+
a = fn.args
|
|
16
|
+
pos = [x.arg for x in a.posonlyargs + a.args]
|
|
17
|
+
req = pos[: len(pos) - len(a.defaults)]
|
|
18
|
+
kw = [x.arg for x in a.kwonlyargs]
|
|
19
|
+
kwreq = [x.arg for x, d in zip(a.kwonlyargs, a.kw_defaults) if d is None]
|
|
20
|
+
return {"pos": pos, "req": req, "kw": kw, "kwreq": kwreq, "var": a.vararg is not None, "varkw": a.kwarg is not None}
|
|
21
|
+
|
|
22
|
+
|
|
23
|
+
def public_api(source: str, is_init: bool = False) -> dict:
|
|
24
|
+
api = {}
|
|
25
|
+
for n in ast.parse(source).body:
|
|
26
|
+
if isinstance(n, (ast.FunctionDef, ast.AsyncFunctionDef)) and not n.name.startswith("_"):
|
|
27
|
+
api[n.name] = _sig(n)
|
|
28
|
+
elif isinstance(n, ast.ClassDef) and not n.name.startswith("_"):
|
|
29
|
+
api[n.name] = {"class": True}
|
|
30
|
+
for m in n.body:
|
|
31
|
+
if isinstance(m, (ast.FunctionDef, ast.AsyncFunctionDef)) and (not m.name.startswith("_") or m.name == "__init__"):
|
|
32
|
+
api[f"{n.name}.{m.name}"] = _sig(m)
|
|
33
|
+
elif isinstance(n, ast.AnnAssign) and isinstance(n.target, ast.Name) and not n.target.id.startswith("_"):
|
|
34
|
+
api[n.target.id] = {"const": True}
|
|
35
|
+
elif is_init and isinstance(n, ast.ImportFrom):
|
|
36
|
+
for a in n.names: # names re-exported from a package __init__ are part of its public API
|
|
37
|
+
nm = a.asname or a.name
|
|
38
|
+
if not nm.startswith("_") and nm != "*":
|
|
39
|
+
api.setdefault(nm, {"const": True})
|
|
40
|
+
elif isinstance(n, ast.Assign):
|
|
41
|
+
for t in n.targets:
|
|
42
|
+
if isinstance(t, ast.Name) and not t.id.startswith("_"):
|
|
43
|
+
api[t.id] = {"const": True}
|
|
44
|
+
return api
|
|
45
|
+
|
|
46
|
+
|
|
47
|
+
def breaking(old: dict, new: dict) -> list:
|
|
48
|
+
out = []
|
|
49
|
+
for name, o in old.items():
|
|
50
|
+
n = new.get(name)
|
|
51
|
+
if n is None:
|
|
52
|
+
out.append(f"removed: {name}")
|
|
53
|
+
elif "pos" in o and "pos" in n:
|
|
54
|
+
gone = [p for p in o["pos"] + o["kw"] if p not in n["pos"] + n["kw"] and not n["varkw"]]
|
|
55
|
+
added = [p for p in n["req"] if p not in o["req"]] + [p for p in n["kwreq"] if p not in o["kwreq"]]
|
|
56
|
+
order = o["pos"] != n["pos"][: len(o["pos"])] and not gone
|
|
57
|
+
if gone:
|
|
58
|
+
out.append(f"{name}: parameter(s) removed or renamed: {', '.join(gone)}")
|
|
59
|
+
if added:
|
|
60
|
+
out.append(f"{name}: new required parameter(s): {', '.join(added)}")
|
|
61
|
+
if order:
|
|
62
|
+
out.append(f"{name}: positional parameter order changed")
|
|
63
|
+
elif ("pos" in o) != ("pos" in n):
|
|
64
|
+
out.append(f"{name}: changed kind (function/class/constant)")
|
|
65
|
+
return out
|
|
66
|
+
|
|
67
|
+
|
|
68
|
+
def diff(repo: Path, base: str, files: list):
|
|
69
|
+
"""Return (breaking_changes, gaps). Files that fail to parse are gaps, never silently OK."""
|
|
70
|
+
found, gaps = [], []
|
|
71
|
+
for f in files:
|
|
72
|
+
if not f.endswith(".py"):
|
|
73
|
+
continue
|
|
74
|
+
old = _show(repo, base, f)
|
|
75
|
+
if old is None:
|
|
76
|
+
continue # new file: nothing to break
|
|
77
|
+
try:
|
|
78
|
+
new_src = (repo / f).read_text(encoding="utf-8") if (repo / f).exists() else None
|
|
79
|
+
if new_src is None:
|
|
80
|
+
found.append(f"removed file: {f}")
|
|
81
|
+
continue
|
|
82
|
+
found += [f"{f}: {x}" for x in breaking(public_api(old, f.endswith('__init__.py')), public_api(new_src, f.endswith('__init__.py')))]
|
|
83
|
+
except (SyntaxError, UnicodeDecodeError, RecursionError, MemoryError, ValueError):
|
|
84
|
+
gaps.append(f"could not parse {f} for API comparison")
|
|
85
|
+
return found, gaps
|
|
@@ -0,0 +1,59 @@
|
|
|
1
|
+
"""CI evidence: read the project's own check results for the exact commit through the GitHub CLI (read-only GETs).
|
|
2
|
+
|
|
3
|
+
Only jobs whose names look like test jobs count towards a "tests pass" claim; lint, security scans, title checks, release
|
|
4
|
+
automation and similar are reported but ignored. A commit with no CI yields no evidence (never a pass).
|
|
5
|
+
"""
|
|
6
|
+
import json
|
|
7
|
+
import re
|
|
8
|
+
import time
|
|
9
|
+
import subprocess
|
|
10
|
+
from pathlib import Path
|
|
11
|
+
|
|
12
|
+
from .reality import safe_prefix, Evidence, Snapshot
|
|
13
|
+
|
|
14
|
+
# v2 (2026-10-07, post-hoc after the RQ4 audit: v1 had 91% precision, 59% recall on 60 blind-judged job names).
|
|
15
|
+
# Token-aware (underscores and digits do not hide a word), recognises python-version matrix names, excludes test.pypi.
|
|
16
|
+
TEST_JOB = re.compile(r"(?<![a-z])(?:tests?(?!\.pypi)|pytest|pytester|unit|unittests?|integration|tox|nox|specs?)(?![a-z])|^(?:python|py)[ -]?3\.\d+|^\U0001F40D", re.I)
|
|
17
|
+
TEST_JOB_V1 = re.compile(r"\b(?:tests?|pytest|unit|unittests?|integration|tox|nox|specs?)\b", re.I)
|
|
18
|
+
_IND = {"framing": "separate", "evidence": "separate", "mechanism": "separate", "authority": "unknown"} # the PR can change the CI configuration
|
|
19
|
+
|
|
20
|
+
|
|
21
|
+
def _gh(path: str):
|
|
22
|
+
r = subprocess.run(["gh", "api", path], capture_output=True, text=True)
|
|
23
|
+
return json.loads(r.stdout) if r.returncode == 0 and r.stdout.strip() else None
|
|
24
|
+
|
|
25
|
+
|
|
26
|
+
def _slug(repo: Path):
|
|
27
|
+
r = subprocess.run(["git", *safe_prefix(repo), "-C", str(repo), "remote", "get-url", "origin"], capture_output=True, text=True)
|
|
28
|
+
m = re.search(r"github\.com[:/]([\w.-]+/[\w.-]+?)(?:\.git)?$", r.stdout.strip())
|
|
29
|
+
return m.group(1) if m else None
|
|
30
|
+
|
|
31
|
+
|
|
32
|
+
def ci_evidence(repo: Path, snap: Snapshot, fetch=_gh, slug=None, sha=None, wait: int = 0, sleep=time.sleep) -> list:
|
|
33
|
+
"""Evidence from CI for HEAD. Not available for uncommitted work (CI never saw it)."""
|
|
34
|
+
if snap.dirty and not sha:
|
|
35
|
+
return []
|
|
36
|
+
sha = sha or snap.commit
|
|
37
|
+
slug = slug or _slug(repo)
|
|
38
|
+
if not slug:
|
|
39
|
+
return []
|
|
40
|
+
deadline = time.time() + wait
|
|
41
|
+
while True:
|
|
42
|
+
data = fetch(f"repos/{slug}/commits/{sha}/check-runs?per_page=100") or {}
|
|
43
|
+
pending = [r for r in data.get("check_runs", []) if TEST_JOB.search(r.get("name", "")) and r.get("status") != "completed"]
|
|
44
|
+
if not pending or time.time() >= deadline: # test jobs still running right after a push: wait (bounded) instead of reporting "no result"
|
|
45
|
+
break
|
|
46
|
+
sleep(15)
|
|
47
|
+
if data.get("total_count", 0) > len(data.get("check_runs", [])):
|
|
48
|
+
return [] # truncated listing: refuse to draw conclusions from a partial view
|
|
49
|
+
out = []
|
|
50
|
+
for run in data.get("check_runs", []):
|
|
51
|
+
name, status, concl = run.get("name", ""), run.get("status"), run.get("conclusion")
|
|
52
|
+
if not TEST_JOB.search(name) or status != "completed":
|
|
53
|
+
continue
|
|
54
|
+
if concl in ("neutral", "skipped"):
|
|
55
|
+
continue # a skipped job proves nothing
|
|
56
|
+
ok = concl == "success"
|
|
57
|
+
out.append(Evidence(f"ci_{len(out)}", "ci_check", "github-checks", snap.commit, "", "VALID", _IND,
|
|
58
|
+
f"ci:{name} ({concl})", f"{'pass' if ok else 'fail'}: {name} {concl}"))
|
|
59
|
+
return out
|
|
@@ -0,0 +1,64 @@
|
|
|
1
|
+
"""Rule-based claim extraction. No LLM: anything not matched is reported as unchecked."""
|
|
2
|
+
import re
|
|
3
|
+
from dataclasses import dataclass
|
|
4
|
+
|
|
5
|
+
NO_IMPACT = "no_downstream_impact"
|
|
6
|
+
TESTS_PASS = "tests_pass"
|
|
7
|
+
BACKCOMPAT = "backward_compatible"
|
|
8
|
+
|
|
9
|
+
_PATTERNS = [
|
|
10
|
+
(BACKCOMPAT, re.compile(r"\b(?:no|without|non)[- ]breaking (?:changes?|api)\b|\bbackward[s]?[- ]compatib|\bno api changes?\b|\bpublic api (?:is )?unchanged\b", re.I)),
|
|
11
|
+
(NO_IMPACT, re.compile(r"\bno (?:other |further )?(?:downstream |side )?(?:impact|effects?|consumers?|dependents?)\b|\bnothing else (?:depends|is affected)\b|\bdoes(?:n't| not) affect (?:any )?(?:other|downstream)", re.I)),
|
|
12
|
+
(TESTS_PASS, re.compile(r"\b(?:all )?tests? (?:are )?(?:pass(?:ed|ing)?|green)\b|\b\d+ passed\b|\b(\d[\d,]*)\s*/\s*\1\s+(?:tests?\s+)?(?:pass\w*|green)\b|\b\d[\d,]*\s+(?:[\w-]+\s+){0,2}tests?\b[^.\n]{0,80}\b(?:all )?(?:green|pass\w*|succe\w+)\b|\b(?:ran|run|running)\b[^.\n]{0,40}\b(?:tests?|pytest|test suite|suite)\b[^.\n]{0,60}\b(?:pass\w*|green|succe\w+)\b|\b(?:tests?|pytest|test suite|suite)\b[^.\n]{0,25}[:—-]\s*(?:all )?(?:pass\w*|green|ok|succe\w+)\b|\b(?:verified|confirmed)\b[^.\n]{0,60}\b(?:tests?|pytest|suite)\b[^.\n]{0,40}\b(?:pass\w*|green|succe\w+)\b", re.I)),
|
|
13
|
+
]
|
|
14
|
+
_GENERIC = re.compile(r"\b(?:safe to merge|looks good|fully (?:tested|verified)|ready to ship|backward[- ]compatible)\b", re.I)
|
|
15
|
+
|
|
16
|
+
|
|
17
|
+
@dataclass
|
|
18
|
+
class Claim:
|
|
19
|
+
kind: str # NO_IMPACT, TESTS_PASS, or "unchecked"
|
|
20
|
+
text: str
|
|
21
|
+
count: int | None = None # number of tests the agent says passed, if stated
|
|
22
|
+
|
|
23
|
+
|
|
24
|
+
_RATIO = re.compile(r"\b(\d[\d,]*)\s*/\s*(\d[\d,]*)\s+(?:tests?\s+)?(?:pass\w*|green)\b", re.I)
|
|
25
|
+
_COUNT = re.compile(r"\b(\d[\d,]*)\s+(?:[\w-]+\s+){0,3}?tests?\s+(?:are\s+|were\s+|all\s+)?(?:pass(?:ed|ing)?|green)\b|\b(\d[\d,]*)\s+passed\b|\b(\d[\d,]*)\s+(?:[\w-]+\s+){0,2}tests?\b[^.\n]{0,80}\b(?:all )?(?:green|passing)\b", re.I)
|
|
26
|
+
|
|
27
|
+
|
|
28
|
+
_NEGATED = re.compile(r"\b(?:not|never|no longer|n't|unable to|failed to|couldn't|cannot|can't)\b[^.\n]{0,40}\b(?:confirm|verify|verified|run|ran|pass\w*|green)\b|\b(?:could|can) ?not\b", re.I)
|
|
29
|
+
|
|
30
|
+
|
|
31
|
+
def extract(transcript: str) -> list[Claim]:
|
|
32
|
+
claims: list[Claim] = []
|
|
33
|
+
transcript = transcript[-20000:] # bound the work done on agent-controlled text (the regexes are not linear-time on adversarial input)
|
|
34
|
+
for sentence in re.split(r"(?<=[.!?])\s+|\n+", transcript):
|
|
35
|
+
s = sentence.strip()[:600]
|
|
36
|
+
if not s:
|
|
37
|
+
continue
|
|
38
|
+
if _NEGATED.search(s):
|
|
39
|
+
claims.append(Claim("unchecked", s)) # a negated statement is not a claim of success; surface it as unchecked
|
|
40
|
+
continue
|
|
41
|
+
if re.search(r"\b[1-9]\d*\s+(?:failed|failing|failures?|errors?)\b", s, re.I):
|
|
42
|
+
claims.append(Claim("unchecked", s)) # an honest failure report is not a claim that tests pass
|
|
43
|
+
continue
|
|
44
|
+
matched = False
|
|
45
|
+
for kind, pat in _PATTERNS:
|
|
46
|
+
if pat.search(s):
|
|
47
|
+
r = _RATIO.search(s) if kind == TESTS_PASS else None
|
|
48
|
+
m = _COUNT.search(s) if kind == TESTS_PASS and not r else None
|
|
49
|
+
n = int(r.group(2).replace(",", "")) if r else (int(next(g for g in m.groups() if g).replace(",", "")) if m else None)
|
|
50
|
+
claims.append(Claim(kind, s, n))
|
|
51
|
+
matched = True
|
|
52
|
+
if not matched and _GENERIC.search(s):
|
|
53
|
+
claims.append(Claim("unchecked", s))
|
|
54
|
+
return claims
|
|
55
|
+
|
|
56
|
+
|
|
57
|
+
def sentences(text: str) -> list[str]:
|
|
58
|
+
return [x.strip() for x in re.split(r"(?<=[.!?])\s+|\n+", text) if x.strip()]
|
|
59
|
+
|
|
60
|
+
|
|
61
|
+
def count_unexamined(text: str, found: list) -> int:
|
|
62
|
+
"""Substantive sentences (5+ words) that no extractor pattern looked at."""
|
|
63
|
+
seen = {c.text for c in found}
|
|
64
|
+
return sum(1 for x in sentences(text) if len(x.split()) >= 5 and x not in seen)
|