agentfork-cli 0.1.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- agentfork_cli-0.1.0/.gitignore +221 -0
- agentfork_cli-0.1.0/LICENSE +21 -0
- agentfork_cli-0.1.0/PKG-INFO +125 -0
- agentfork_cli-0.1.0/README.md +97 -0
- agentfork_cli-0.1.0/examples/demo_agent.py +49 -0
- agentfork_cli-0.1.0/examples/demo_agent_claude.py +52 -0
- agentfork_cli-0.1.0/examples/refund_agent.py +54 -0
- agentfork_cli-0.1.0/examples/refund_agent_cents.py +54 -0
- agentfork_cli-0.1.0/pyproject.toml +36 -0
- agentfork_cli-0.1.0/src/agentfork/__init__.py +3 -0
- agentfork_cli-0.1.0/src/agentfork/cli.py +259 -0
- agentfork_cli-0.1.0/src/agentfork/recorder.py +201 -0
- agentfork_cli-0.1.0/src/agentfork/replay.py +109 -0
- agentfork_cli-0.1.0/src/agentfork/store.py +70 -0
- agentfork_cli-0.1.0/tests/test_anthropic.py +40 -0
- agentfork_cli-0.1.0/tests/test_cli.py +23 -0
- agentfork_cli-0.1.0/tests/test_fork.py +29 -0
- agentfork_cli-0.1.0/tests/test_recorder.py +19 -0
- agentfork_cli-0.1.0/tests/test_save_test.py +42 -0
- agentfork_cli-0.1.0/tests/test_smoke.py +2 -0
- agentfork_cli-0.1.0/tests/test_sweep.py +37 -0
|
@@ -0,0 +1,221 @@
|
|
|
1
|
+
# Byte-compiled / optimized / DLL files
|
|
2
|
+
__pycache__/
|
|
3
|
+
*.py[codz]
|
|
4
|
+
*$py.class
|
|
5
|
+
|
|
6
|
+
# C extensions
|
|
7
|
+
*.so
|
|
8
|
+
|
|
9
|
+
# Distribution / packaging
|
|
10
|
+
.Python
|
|
11
|
+
build/
|
|
12
|
+
develop-eggs/
|
|
13
|
+
dist/
|
|
14
|
+
downloads/
|
|
15
|
+
eggs/
|
|
16
|
+
.eggs/
|
|
17
|
+
lib/
|
|
18
|
+
lib64/
|
|
19
|
+
parts/
|
|
20
|
+
sdist/
|
|
21
|
+
var/
|
|
22
|
+
wheels/
|
|
23
|
+
share/python-wheels/
|
|
24
|
+
*.egg-info/
|
|
25
|
+
.installed.cfg
|
|
26
|
+
*.egg
|
|
27
|
+
MANIFEST
|
|
28
|
+
|
|
29
|
+
# PyInstaller
|
|
30
|
+
# Usually these files are written by a python script from a template
|
|
31
|
+
# before PyInstaller builds the exe, so as to inject date/other infos into it.
|
|
32
|
+
*.manifest
|
|
33
|
+
*.spec
|
|
34
|
+
|
|
35
|
+
# Installer logs
|
|
36
|
+
pip-log.txt
|
|
37
|
+
pip-delete-this-directory.txt
|
|
38
|
+
|
|
39
|
+
# Unit test / coverage reports
|
|
40
|
+
htmlcov/
|
|
41
|
+
.tox/
|
|
42
|
+
.nox/
|
|
43
|
+
.coverage
|
|
44
|
+
.coverage.*
|
|
45
|
+
.cache
|
|
46
|
+
nosetests.xml
|
|
47
|
+
coverage.xml
|
|
48
|
+
*.cover
|
|
49
|
+
*.py.cover
|
|
50
|
+
*.lcov
|
|
51
|
+
.hypothesis/
|
|
52
|
+
.pytest_cache/
|
|
53
|
+
cover/
|
|
54
|
+
|
|
55
|
+
# Translations
|
|
56
|
+
*.mo
|
|
57
|
+
*.pot
|
|
58
|
+
|
|
59
|
+
# Django stuff:
|
|
60
|
+
*.log
|
|
61
|
+
local_settings.py
|
|
62
|
+
db.sqlite3
|
|
63
|
+
db.sqlite3-journal
|
|
64
|
+
|
|
65
|
+
# Flask stuff:
|
|
66
|
+
instance/
|
|
67
|
+
.webassets-cache
|
|
68
|
+
|
|
69
|
+
# Scrapy stuff:
|
|
70
|
+
.scrapy
|
|
71
|
+
|
|
72
|
+
# Sphinx documentation
|
|
73
|
+
docs/_build/
|
|
74
|
+
|
|
75
|
+
# PyBuilder
|
|
76
|
+
.pybuilder/
|
|
77
|
+
target/
|
|
78
|
+
|
|
79
|
+
# Jupyter Notebook
|
|
80
|
+
.ipynb_checkpoints
|
|
81
|
+
|
|
82
|
+
# IPython
|
|
83
|
+
profile_default/
|
|
84
|
+
ipython_config.py
|
|
85
|
+
|
|
86
|
+
# pyenv
|
|
87
|
+
# For a library or package, you might want to ignore these files since the code is
|
|
88
|
+
# intended to run in multiple environments; otherwise, check them in:
|
|
89
|
+
# .python-version
|
|
90
|
+
|
|
91
|
+
# pipenv
|
|
92
|
+
# According to pypa/pipenv#598, it is recommended to include Pipfile.lock in version control.
|
|
93
|
+
# However, in case of collaboration, if having platform-specific dependencies or dependencies
|
|
94
|
+
# having no cross-platform support, pipenv may install dependencies that don't work, or not
|
|
95
|
+
# install all needed dependencies.
|
|
96
|
+
# Pipfile.lock
|
|
97
|
+
|
|
98
|
+
# uv
|
|
99
|
+
# Similar to Pipfile.lock, it is generally recommended to include uv.lock in version control.
|
|
100
|
+
# This is especially recommended for binary packages to ensure reproducibility, and is more
|
|
101
|
+
# commonly ignored for libraries.
|
|
102
|
+
# uv.lock
|
|
103
|
+
|
|
104
|
+
# poetry
|
|
105
|
+
# Similar to Pipfile.lock, it is generally recommended to include poetry.lock in version control.
|
|
106
|
+
# This is especially recommended for binary packages to ensure reproducibility, and is more
|
|
107
|
+
# commonly ignored for libraries.
|
|
108
|
+
# https://python-poetry.org/docs/basic-usage/#commit-your-poetrylock-file-to-version-control
|
|
109
|
+
# poetry.lock
|
|
110
|
+
# poetry.toml
|
|
111
|
+
|
|
112
|
+
# pdm
|
|
113
|
+
# Similar to Pipfile.lock, it is generally recommended to include pdm.lock in version control.
|
|
114
|
+
# pdm recommends including project-wide configuration in pdm.toml, but excluding .pdm-python.
|
|
115
|
+
# https://pdm-project.org/en/latest/usage/project/#working-with-version-control
|
|
116
|
+
# pdm.lock
|
|
117
|
+
# pdm.toml
|
|
118
|
+
.pdm-python
|
|
119
|
+
.pdm-build/
|
|
120
|
+
|
|
121
|
+
# pixi
|
|
122
|
+
# Similar to Pipfile.lock, it is generally recommended to include pixi.lock in version control.
|
|
123
|
+
# pixi.lock
|
|
124
|
+
# Pixi creates a virtual environment in the .pixi directory, just like venv module creates one
|
|
125
|
+
# in the .venv directory. It is recommended not to include this directory in version control.
|
|
126
|
+
.pixi/*
|
|
127
|
+
!.pixi/config.toml
|
|
128
|
+
|
|
129
|
+
# PEP 582; used by e.g. github.com/David-OConnor/pyflow and github.com/pdm-project/pdm
|
|
130
|
+
__pypackages__/
|
|
131
|
+
|
|
132
|
+
# Celery stuff
|
|
133
|
+
celerybeat-schedule*
|
|
134
|
+
celerybeat.pid
|
|
135
|
+
|
|
136
|
+
# Redis
|
|
137
|
+
*.rdb
|
|
138
|
+
*.aof
|
|
139
|
+
*.pid
|
|
140
|
+
|
|
141
|
+
# RabbitMQ
|
|
142
|
+
mnesia/
|
|
143
|
+
rabbitmq/
|
|
144
|
+
rabbitmq-data/
|
|
145
|
+
|
|
146
|
+
# ActiveMQ
|
|
147
|
+
activemq-data/
|
|
148
|
+
|
|
149
|
+
# SageMath parsed files
|
|
150
|
+
*.sage.py
|
|
151
|
+
|
|
152
|
+
# Environments
|
|
153
|
+
.env
|
|
154
|
+
.envrc
|
|
155
|
+
.venv
|
|
156
|
+
env/
|
|
157
|
+
venv/
|
|
158
|
+
ENV/
|
|
159
|
+
env.bak/
|
|
160
|
+
venv.bak/
|
|
161
|
+
|
|
162
|
+
# Spyder project settings
|
|
163
|
+
.spyderproject
|
|
164
|
+
.spyproject
|
|
165
|
+
|
|
166
|
+
# Rope project settings
|
|
167
|
+
.ropeproject
|
|
168
|
+
|
|
169
|
+
# mkdocs/Zensical documentation
|
|
170
|
+
/site
|
|
171
|
+
|
|
172
|
+
# mypy
|
|
173
|
+
.mypy_cache/
|
|
174
|
+
.dmypy.json
|
|
175
|
+
dmypy.json
|
|
176
|
+
|
|
177
|
+
# Pyre type checker
|
|
178
|
+
.pyre/
|
|
179
|
+
|
|
180
|
+
# pytype static type analyzer
|
|
181
|
+
.pytype/
|
|
182
|
+
|
|
183
|
+
# Cython debug symbols
|
|
184
|
+
cython_debug/
|
|
185
|
+
|
|
186
|
+
# PyCharm
|
|
187
|
+
# JetBrains specific template is maintained in a separate JetBrains.gitignore that can
|
|
188
|
+
# be found at https://github.com/github/gitignore/blob/main/Global/JetBrains.gitignore
|
|
189
|
+
# and can be added to the global gitignore or merged into this file. For a more nuclear
|
|
190
|
+
# option (not recommended) you can uncomment the following to ignore the entire idea folder.
|
|
191
|
+
# .idea/
|
|
192
|
+
|
|
193
|
+
# Abstra
|
|
194
|
+
# Abstra is an AI-powered process automation framework.
|
|
195
|
+
# Ignore directories containing user credentials, local state, and settings.
|
|
196
|
+
# Learn more at https://abstra.io/docs
|
|
197
|
+
.abstra/
|
|
198
|
+
|
|
199
|
+
# Visual Studio Code
|
|
200
|
+
# Visual Studio Code specific template is maintained in a separate VisualStudioCode.gitignore that
|
|
201
|
+
# can be found at https://github.com/github/gitignore/blob/main/Global/VisualStudioCode.gitignore
|
|
202
|
+
# and can be added to the global gitignore or merged into this file. However, if you prefer, you
|
|
203
|
+
# could uncomment the following to ignore the entire vscode folder
|
|
204
|
+
# .vscode/
|
|
205
|
+
# Temporary file for partial code execution
|
|
206
|
+
tempCodeRunnerFile.py
|
|
207
|
+
|
|
208
|
+
# Ruff stuff:
|
|
209
|
+
.ruff_cache/
|
|
210
|
+
|
|
211
|
+
# PyPI configuration file
|
|
212
|
+
.pypirc
|
|
213
|
+
|
|
214
|
+
# Marimo
|
|
215
|
+
marimo/_static/
|
|
216
|
+
marimo/_lsp/
|
|
217
|
+
__marimo__/
|
|
218
|
+
|
|
219
|
+
# Streamlit
|
|
220
|
+
.streamlit/secrets.toml
|
|
221
|
+
.agentfork/
|
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Bimal Kumal
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
|
@@ -0,0 +1,125 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: agentfork-cli
|
|
3
|
+
Version: 0.1.0
|
|
4
|
+
Summary: Fork your LLM agent at any step and sweep prompts, models or tool results to find what fixes it.
|
|
5
|
+
Project-URL: Homepage, https://github.com/bimal1023/agentfork
|
|
6
|
+
Project-URL: Issues, https://github.com/bimal1023/agentfork/issues
|
|
7
|
+
Author: Bimal Kumal
|
|
8
|
+
License-Expression: MIT
|
|
9
|
+
License-File: LICENSE
|
|
10
|
+
Keywords: agents,anthropic,debugging,llm,openai,replay,testing
|
|
11
|
+
Classifier: Development Status :: 3 - Alpha
|
|
12
|
+
Classifier: Intended Audience :: Developers
|
|
13
|
+
Classifier: Programming Language :: Python :: 3
|
|
14
|
+
Classifier: Topic :: Software Development :: Debuggers
|
|
15
|
+
Classifier: Topic :: Software Development :: Testing
|
|
16
|
+
Requires-Python: >=3.9
|
|
17
|
+
Requires-Dist: rich
|
|
18
|
+
Requires-Dist: typer
|
|
19
|
+
Provides-Extra: anthropic
|
|
20
|
+
Requires-Dist: anthropic; extra == 'anthropic'
|
|
21
|
+
Provides-Extra: dev
|
|
22
|
+
Requires-Dist: anthropic; extra == 'dev'
|
|
23
|
+
Requires-Dist: openai; extra == 'dev'
|
|
24
|
+
Requires-Dist: pytest; extra == 'dev'
|
|
25
|
+
Provides-Extra: openai
|
|
26
|
+
Requires-Dist: openai; extra == 'openai'
|
|
27
|
+
Description-Content-Type: text/markdown
|
|
28
|
+
|
|
29
|
+
# agentfork
|
|
30
|
+
|
|
31
|
+
[](https://github.com/bimal1023/agentfork/actions/workflows/tests.yml)
|
|
32
|
+
|
|
33
|
+
**Fork your LLM agent at any step, then sweep prompts, models or tool results to find what actually fixes it.**
|
|
34
|
+
|
|
35
|
+
|
|
36
|
+
|
|
37
|
+
When an agent misbehaves at step 3, the usual loop is: tweak the prompt, re-run everything, eyeball one output, repeat. That is slow, costs tokens on steps that didn't change, and one lucky run proves nothing. agentfork records every LLM and tool call, replays earlier steps from cache, and runs **many variants of one step, several times each**, so you get pass rates instead of anecdotes.
|
|
38
|
+
|
|
39
|
+
Everything runs locally. No account, no server, no data leaves your machine.
|
|
40
|
+
|
|
41
|
+
## The headline example
|
|
42
|
+
|
|
43
|
+
A refund agent reads `"amount": 4999, "currency": "USD"` from an order API. The amount is in cents, and the agent refunds **$4,999** for a $49.99 laptop ([examples/refund_agent_cents.py](examples/refund_agent_cents.py)). Is the fix a better model or a better prompt?
|
|
44
|
+
|
|
45
|
+
```text
|
|
46
|
+
$ agentfork sweep de994fe6 --step 3 --repeat 3 --expect "49.99" --model gpt-4o-mini,gpt-4o
|
|
47
|
+
|
|
48
|
+
variant runs pass avg tokens sample output
|
|
49
|
+
original 1 0/1 445 I have processed a refund of $4,999.00...
|
|
50
|
+
model=gpt-4o-mini 3 0/3 444 I have processed a refund of $4,999.00...
|
|
51
|
+
model=gpt-4o 3 0/3 292 I apologize, it seems there was a mis...
|
|
52
|
+
```
|
|
53
|
+
|
|
54
|
+
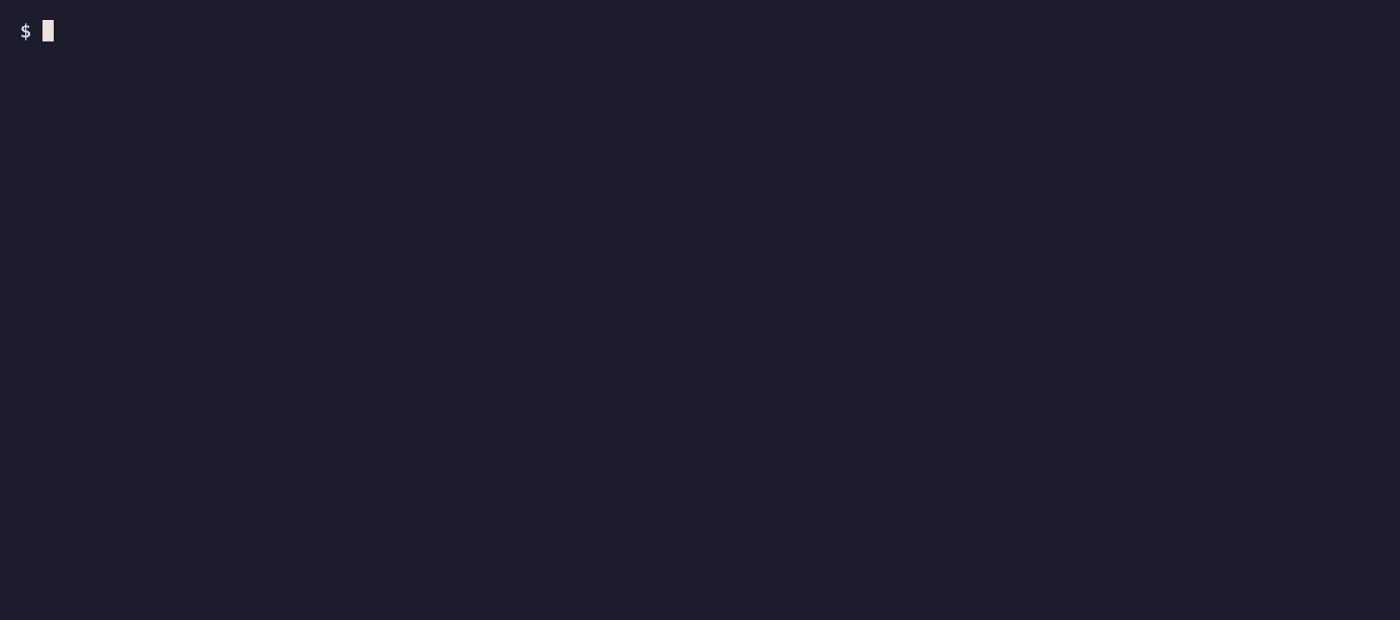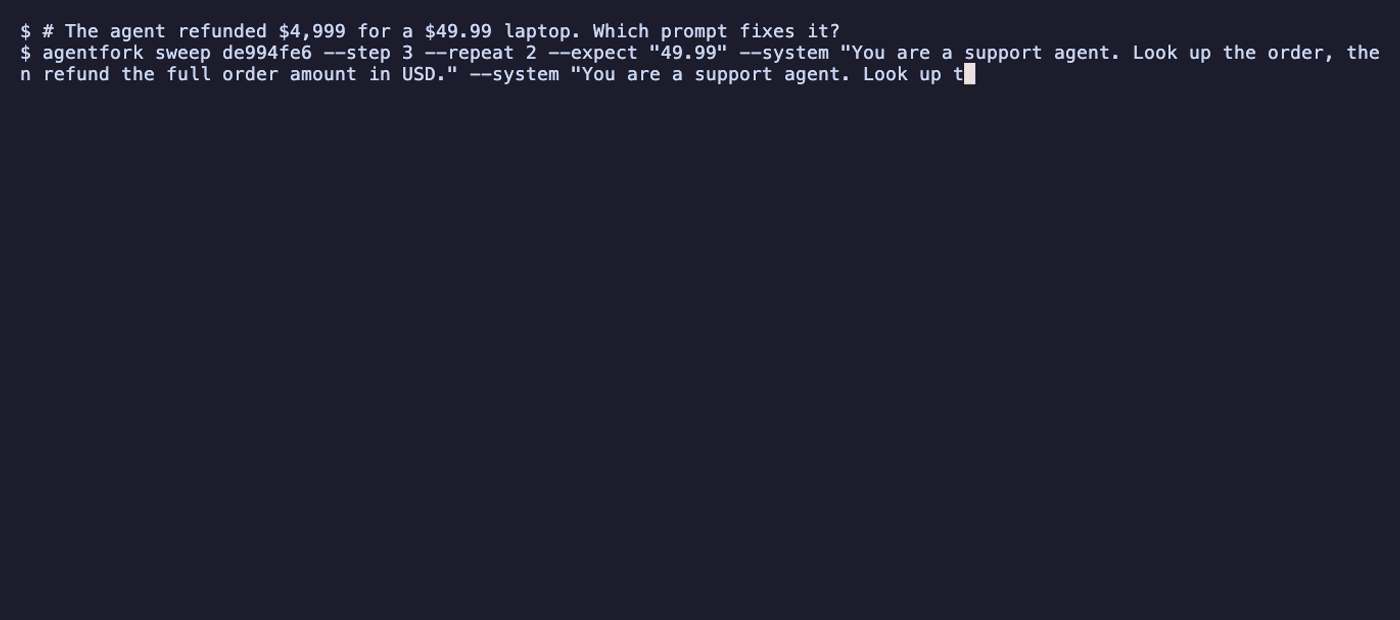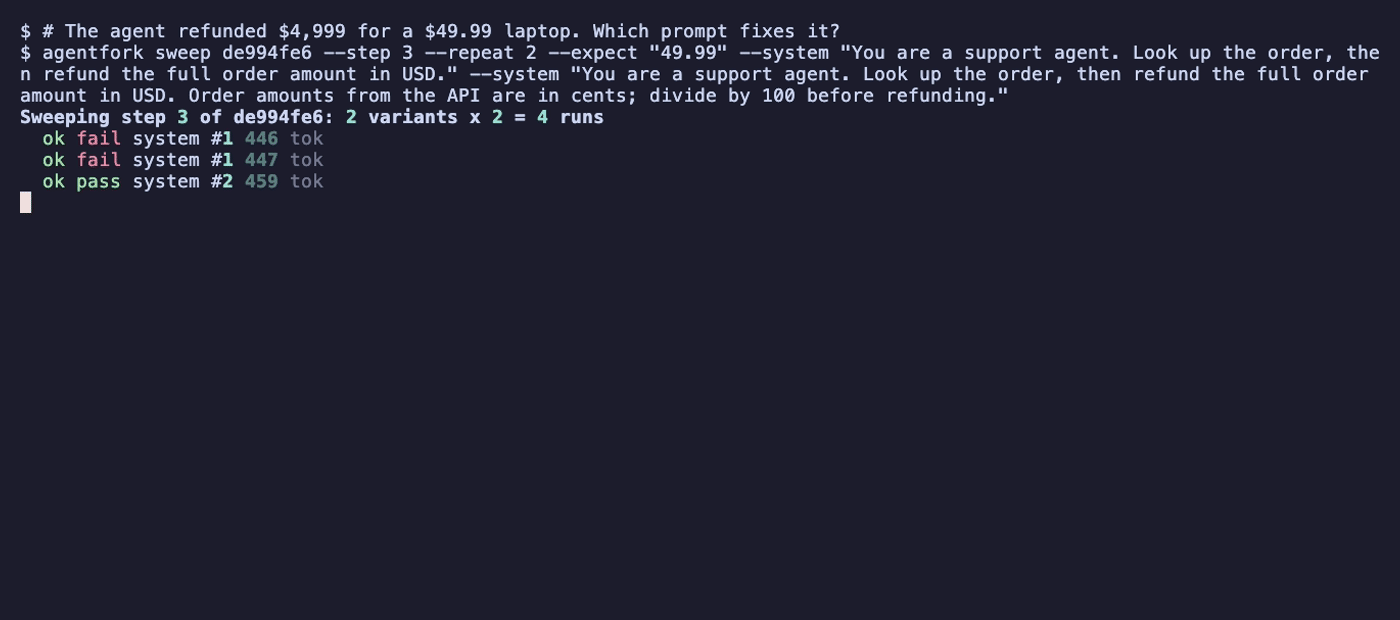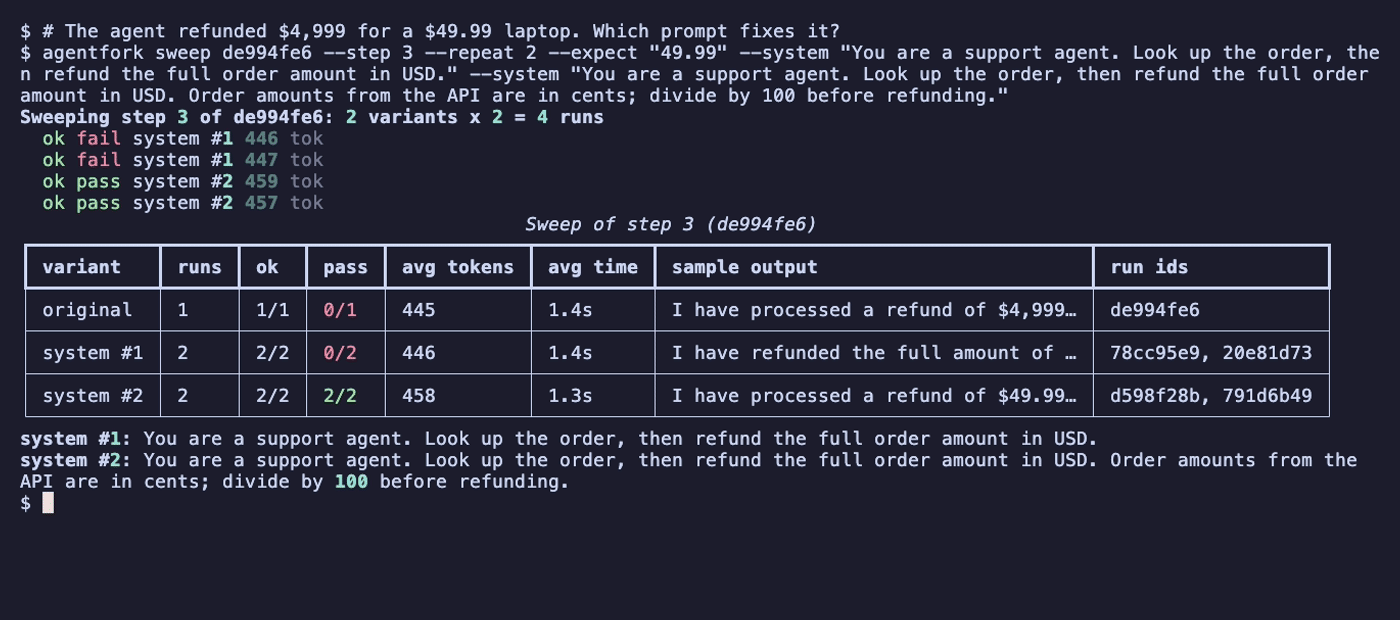
A bigger model doesn't fix it. One sentence in the prompt does:
|
|
55
|
+
|
|
56
|
+
```text
|
|
57
|
+
$ agentfork sweep de994fe6 --step 3 --repeat 3 --expect "49.99" \
|
|
58
|
+
--system "You are a support agent. Look up the order, then refund the full order amount in USD." \
|
|
59
|
+
--system "... Order amounts from the API are in cents; divide by 100 before refunding."
|
|
60
|
+
|
|
61
|
+
variant runs pass avg tokens sample output
|
|
62
|
+
original 1 0/1 445 I have processed a refund of $4,999.00...
|
|
63
|
+
system #1 3 0/3 445 A full refund of $4,999.00 has ...
|
|
64
|
+
system #2 3 3/3 460 I have processed a refund of $49.99...
|
|
65
|
+
```
|
|
66
|
+
|
|
67
|
+
Steps 1 and 2 replayed from cache in every run, so only the step that mattered was paid for.
|
|
68
|
+
|
|
69
|
+
## Quickstart
|
|
70
|
+
|
|
71
|
+
```bash
|
|
72
|
+
pip install "agentfork-cli[openai]" # or agentfork[anthropic]
|
|
73
|
+
```
|
|
74
|
+
|
|
75
|
+
Add three things to your agent:
|
|
76
|
+
|
|
77
|
+
```python
|
|
78
|
+
from openai import OpenAI
|
|
79
|
+
from agentfork import trace, tool, wrap_openai
|
|
80
|
+
|
|
81
|
+
client = wrap_openai(OpenAI()) # records every LLM call (wrap_anthropic for Claude)
|
|
82
|
+
|
|
83
|
+
@tool # records every tool call
|
|
84
|
+
def lookup_order(order_id): ...
|
|
85
|
+
|
|
86
|
+
@trace # one run = one call of your agent
|
|
87
|
+
def run_agent(question): ...
|
|
88
|
+
```
|
|
89
|
+
|
|
90
|
+
Run your agent as usual. Each run is saved to `.agentfork/traces.db`.
|
|
91
|
+
|
|
92
|
+
## Commands
|
|
93
|
+
|
|
94
|
+
| Command | What it does |
|
|
95
|
+
| --- | --- |
|
|
96
|
+
| `agentfork list` | Recent runs with steps, tokens, duration and fork lineage |
|
|
97
|
+
| `agentfork show <id> [--full]` | A run as a step tree, with optional full JSON |
|
|
98
|
+
| `agentfork fork <id> --step N --output/--model/--system ...` | Re-run from step N with one change; earlier steps come from cache |
|
|
99
|
+
| `agentfork sweep <id> --step N --model a,b --system ... --repeat K --expect TEXT` | Try many variants of step N, K times each, and compare pass rate, tokens and time |
|
|
100
|
+
| `agentfork diff <a> <b>` | Compare two runs step by step |
|
|
101
|
+
| `agentfork save-test <id>` | Save a run as a pytest test that replays from cache in CI with no API key |
|
|
102
|
+
|
|
103
|
+
## How it works
|
|
104
|
+
|
|
105
|
+
1. **Record.** `@trace`, `@tool` and `wrap_openai`/`wrap_anthropic` capture each step's inputs, outputs, tokens and latency, plus a hash of its inputs.
|
|
106
|
+
2. **Fork.** agentfork re-imports your agent and re-runs it. Steps before N are served from the cache, step N gets your change, and everything after runs live. A model change applies to every LLM call from step N on.
|
|
107
|
+
3. **Sweep.** Runs fork for each variant `--repeat` times and checks each final output for your `--expect` text.
|
|
108
|
+
4. **Test.** `save-test` writes a JSON snapshot plus a pytest file. The test replays every step from cache and fails with a diff if any step's inputs, the step count, or the final output changes.
|
|
109
|
+
|
|
110
|
+
## Related work
|
|
111
|
+
|
|
112
|
+
agentfork overlaps with record/replay tools like [agent-rewind](https://pypi.org/project/agent-rewind/), which supports many more providers, and [agentstep](https://pypi.org/project/agentstep/), a LangGraph time-travel debugger with a web UI. agentfork's focus is the step after replay: sweeping many variants of one step, with repeats and pass rates, to choose a fix with evidence.
|
|
113
|
+
|
|
114
|
+
## Roadmap
|
|
115
|
+
|
|
116
|
+
- [x] Recorder, CLI viewer, fork, diff, snapshot tests
|
|
117
|
+
- [x] OpenAI and Anthropic support
|
|
118
|
+
- [x] Sweep with repeats and pass rates
|
|
119
|
+
- [ ] Cost estimates per variant
|
|
120
|
+
- [ ] Parallel sweeps
|
|
121
|
+
- [ ] LangGraph integration
|
|
122
|
+
|
|
123
|
+
## License
|
|
124
|
+
|
|
125
|
+
MIT
|
|
@@ -0,0 +1,97 @@
|
|
|
1
|
+
# agentfork
|
|
2
|
+
|
|
3
|
+
[](https://github.com/bimal1023/agentfork/actions/workflows/tests.yml)
|
|
4
|
+
|
|
5
|
+
**Fork your LLM agent at any step, then sweep prompts, models or tool results to find what actually fixes it.**
|
|
6
|
+
|
|
7
|
+

|
|
8
|
+
|
|
9
|
+
When an agent misbehaves at step 3, the usual loop is: tweak the prompt, re-run everything, eyeball one output, repeat. That is slow, costs tokens on steps that didn't change, and one lucky run proves nothing. agentfork records every LLM and tool call, replays earlier steps from cache, and runs **many variants of one step, several times each**, so you get pass rates instead of anecdotes.
|
|
10
|
+
|
|
11
|
+
Everything runs locally. No account, no server, no data leaves your machine.
|
|
12
|
+
|
|
13
|
+
## The headline example
|
|
14
|
+
|
|
15
|
+
A refund agent reads `"amount": 4999, "currency": "USD"` from an order API. The amount is in cents, and the agent refunds **$4,999** for a $49.99 laptop ([examples/refund_agent_cents.py](examples/refund_agent_cents.py)). Is the fix a better model or a better prompt?
|
|
16
|
+
|
|
17
|
+
```text
|
|
18
|
+
$ agentfork sweep de994fe6 --step 3 --repeat 3 --expect "49.99" --model gpt-4o-mini,gpt-4o
|
|
19
|
+
|
|
20
|
+
variant runs pass avg tokens sample output
|
|
21
|
+
original 1 0/1 445 I have processed a refund of $4,999.00...
|
|
22
|
+
model=gpt-4o-mini 3 0/3 444 I have processed a refund of $4,999.00...
|
|
23
|
+
model=gpt-4o 3 0/3 292 I apologize, it seems there was a mis...
|
|
24
|
+
```
|
|
25
|
+
|
|
26
|
+
A bigger model doesn't fix it. One sentence in the prompt does:
|
|
27
|
+
|
|
28
|
+
```text
|
|
29
|
+
$ agentfork sweep de994fe6 --step 3 --repeat 3 --expect "49.99" \
|
|
30
|
+
--system "You are a support agent. Look up the order, then refund the full order amount in USD." \
|
|
31
|
+
--system "... Order amounts from the API are in cents; divide by 100 before refunding."
|
|
32
|
+
|
|
33
|
+
variant runs pass avg tokens sample output
|
|
34
|
+
original 1 0/1 445 I have processed a refund of $4,999.00...
|
|
35
|
+
system #1 3 0/3 445 A full refund of $4,999.00 has ...
|
|
36
|
+
system #2 3 3/3 460 I have processed a refund of $49.99...
|
|
37
|
+
```
|
|
38
|
+
|
|
39
|
+
Steps 1 and 2 replayed from cache in every run, so only the step that mattered was paid for.
|
|
40
|
+
|
|
41
|
+
## Quickstart
|
|
42
|
+
|
|
43
|
+
```bash
|
|
44
|
+
pip install "agentfork-cli[openai]" # or agentfork[anthropic]
|
|
45
|
+
```
|
|
46
|
+
|
|
47
|
+
Add three things to your agent:
|
|
48
|
+
|
|
49
|
+
```python
|
|
50
|
+
from openai import OpenAI
|
|
51
|
+
from agentfork import trace, tool, wrap_openai
|
|
52
|
+
|
|
53
|
+
client = wrap_openai(OpenAI()) # records every LLM call (wrap_anthropic for Claude)
|
|
54
|
+
|
|
55
|
+
@tool # records every tool call
|
|
56
|
+
def lookup_order(order_id): ...
|
|
57
|
+
|
|
58
|
+
@trace # one run = one call of your agent
|
|
59
|
+
def run_agent(question): ...
|
|
60
|
+
```
|
|
61
|
+
|
|
62
|
+
Run your agent as usual. Each run is saved to `.agentfork/traces.db`.
|
|
63
|
+
|
|
64
|
+
## Commands
|
|
65
|
+
|
|
66
|
+
| Command | What it does |
|
|
67
|
+
| --- | --- |
|
|
68
|
+
| `agentfork list` | Recent runs with steps, tokens, duration and fork lineage |
|
|
69
|
+
| `agentfork show <id> [--full]` | A run as a step tree, with optional full JSON |
|
|
70
|
+
| `agentfork fork <id> --step N --output/--model/--system ...` | Re-run from step N with one change; earlier steps come from cache |
|
|
71
|
+
| `agentfork sweep <id> --step N --model a,b --system ... --repeat K --expect TEXT` | Try many variants of step N, K times each, and compare pass rate, tokens and time |
|
|
72
|
+
| `agentfork diff <a> <b>` | Compare two runs step by step |
|
|
73
|
+
| `agentfork save-test <id>` | Save a run as a pytest test that replays from cache in CI with no API key |
|
|
74
|
+
|
|
75
|
+
## How it works
|
|
76
|
+
|
|
77
|
+
1. **Record.** `@trace`, `@tool` and `wrap_openai`/`wrap_anthropic` capture each step's inputs, outputs, tokens and latency, plus a hash of its inputs.
|
|
78
|
+
2. **Fork.** agentfork re-imports your agent and re-runs it. Steps before N are served from the cache, step N gets your change, and everything after runs live. A model change applies to every LLM call from step N on.
|
|
79
|
+
3. **Sweep.** Runs fork for each variant `--repeat` times and checks each final output for your `--expect` text.
|
|
80
|
+
4. **Test.** `save-test` writes a JSON snapshot plus a pytest file. The test replays every step from cache and fails with a diff if any step's inputs, the step count, or the final output changes.
|
|
81
|
+
|
|
82
|
+
## Related work
|
|
83
|
+
|
|
84
|
+
agentfork overlaps with record/replay tools like [agent-rewind](https://pypi.org/project/agent-rewind/), which supports many more providers, and [agentstep](https://pypi.org/project/agentstep/), a LangGraph time-travel debugger with a web UI. agentfork's focus is the step after replay: sweeping many variants of one step, with repeats and pass rates, to choose a fix with evidence.
|
|
85
|
+
|
|
86
|
+
## Roadmap
|
|
87
|
+
|
|
88
|
+
- [x] Recorder, CLI viewer, fork, diff, snapshot tests
|
|
89
|
+
- [x] OpenAI and Anthropic support
|
|
90
|
+
- [x] Sweep with repeats and pass rates
|
|
91
|
+
- [ ] Cost estimates per variant
|
|
92
|
+
- [ ] Parallel sweeps
|
|
93
|
+
- [ ] LangGraph integration
|
|
94
|
+
|
|
95
|
+
## License
|
|
96
|
+
|
|
97
|
+
MIT
|
|
@@ -0,0 +1,49 @@
|
|
|
1
|
+
import json, re
|
|
2
|
+
from openai import OpenAI
|
|
3
|
+
from agentfork import trace, tool, wrap_openai
|
|
4
|
+
client = wrap_openai(OpenAI())
|
|
5
|
+
MODEL = "gpt-4o-mini"
|
|
6
|
+
|
|
7
|
+
TOOLS = [
|
|
8
|
+
{"type": "function", "function": {
|
|
9
|
+
"name": "calculator",
|
|
10
|
+
"description": "Evaluate a basic arithmetic expression like '23*(4+5)'.",
|
|
11
|
+
"parameters": {"type": "object",
|
|
12
|
+
"properties": {"expression": {"type": "string"}},
|
|
13
|
+
"required": ["expression"]}}},
|
|
14
|
+
{"type": "function", "function": {
|
|
15
|
+
"name": "get_weather",
|
|
16
|
+
"description": "Get the current weather for a city.",
|
|
17
|
+
"parameters": {"type": "object",
|
|
18
|
+
"properties": {"city": {"type": "string"}},
|
|
19
|
+
"required": ["city"]}}},
|
|
20
|
+
]
|
|
21
|
+
@tool
|
|
22
|
+
def calculator(expression):
|
|
23
|
+
if not re.fullmatch(r"[\d\s+\-*/().]+", expression):
|
|
24
|
+
return "error: invalid expression"
|
|
25
|
+
return str(eval(expression))
|
|
26
|
+
@tool
|
|
27
|
+
def get_weather(city):
|
|
28
|
+
fake = {"new york": "18C, cloudy", "kathmandu": "22C, sunny"}
|
|
29
|
+
return fake.get(city.lower(), "15C, clear")
|
|
30
|
+
|
|
31
|
+
TOOL_FUNCS = {"calculator": calculator, "get_weather": get_weather}
|
|
32
|
+
@trace
|
|
33
|
+
def run_agent(question, max_turns=5):
|
|
34
|
+
messages = [{"role": "user", "content": question}]
|
|
35
|
+
for _ in range(max_turns):
|
|
36
|
+
resp = client.chat.completions.create(model=MODEL, messages=messages, tools=TOOLS)
|
|
37
|
+
msg = resp.choices[0].message
|
|
38
|
+
messages.append(msg)
|
|
39
|
+
if not msg.tool_calls:
|
|
40
|
+
return msg.content
|
|
41
|
+
for call in msg.tool_calls:
|
|
42
|
+
args = json.loads(call.function.arguments)
|
|
43
|
+
output = TOOL_FUNCS[call.function.name](**args)
|
|
44
|
+
print(f" tool {call.function.name}({args}) -> {output}")
|
|
45
|
+
messages.append({"role": "tool", "tool_call_id": call.id, "content": output})
|
|
46
|
+
return "stopped: too many turns"
|
|
47
|
+
|
|
48
|
+
if __name__ == "__main__":
|
|
49
|
+
print(run_agent("What's the weather in Kathmandu, and what is 23*(4+5)?"))
|
|
@@ -0,0 +1,52 @@
|
|
|
1
|
+
import re
|
|
2
|
+
import anthropic
|
|
3
|
+
from agentfork import trace, tool, wrap_anthropic
|
|
4
|
+
|
|
5
|
+
client = wrap_anthropic(anthropic.Anthropic())
|
|
6
|
+
MODEL = "claude-haiku-5-5"
|
|
7
|
+
|
|
8
|
+
TOOLS = [
|
|
9
|
+
{"name": "calculator",
|
|
10
|
+
"description": "Evaluate a basic arithmetic expression like '23*(4+5)'.",
|
|
11
|
+
"input_schema": {"type": "object",
|
|
12
|
+
"properties": {"expression": {"type": "string"}},
|
|
13
|
+
"required": ["expression"]}},
|
|
14
|
+
{"name": "get_weather",
|
|
15
|
+
"description": "Get the current weather for a city.",
|
|
16
|
+
"input_schema": {"type": "object",
|
|
17
|
+
"properties": {"city": {"type": "string"}},
|
|
18
|
+
"required": ["city"]}},
|
|
19
|
+
]
|
|
20
|
+
|
|
21
|
+
@tool
|
|
22
|
+
def calculator(expression):
|
|
23
|
+
if not re.fullmatch(r"[\d\s+\-*/().]+", expression):
|
|
24
|
+
return "error: invalid expression"
|
|
25
|
+
return str(eval(expression))
|
|
26
|
+
|
|
27
|
+
@tool
|
|
28
|
+
def get_weather(city):
|
|
29
|
+
fake = {"new york": "18C, cloudy", "kathmandu": "22C, sunny"}
|
|
30
|
+
return fake.get(city.lower(), "15C, clear")
|
|
31
|
+
|
|
32
|
+
TOOL_FUNCS = {"calculator": calculator, "get_weather": get_weather}
|
|
33
|
+
|
|
34
|
+
@trace
|
|
35
|
+
def run_agent(question, max_turns=5):
|
|
36
|
+
messages = [{"role": "user", "content": question}]
|
|
37
|
+
for _ in range(max_turns):
|
|
38
|
+
resp = client.messages.create(model=MODEL, max_tokens=1024, tools=TOOLS, messages=messages)
|
|
39
|
+
messages.append({"role": "assistant", "content": resp.content})
|
|
40
|
+
if resp.stop_reason != "tool_use":
|
|
41
|
+
return "".join(b.text for b in resp.content if b.type == "text")
|
|
42
|
+
results = []
|
|
43
|
+
for block in resp.content:
|
|
44
|
+
if block.type == "tool_use":
|
|
45
|
+
output = TOOL_FUNCS[block.name](**block.input)
|
|
46
|
+
print(f" tool {block.name}({block.input}) -> {output}")
|
|
47
|
+
results.append({"type": "tool_result", "tool_use_id": block.id, "content": output})
|
|
48
|
+
messages.append({"role": "user", "content": results})
|
|
49
|
+
return "stopped: too many turns"
|
|
50
|
+
|
|
51
|
+
if __name__ == "__main__":
|
|
52
|
+
print(run_agent("What's the weather in Kathmandu, and what is 23*(4+5)?"))
|
|
@@ -0,0 +1,54 @@
|
|
|
1
|
+
import json
|
|
2
|
+
from openai import OpenAI
|
|
3
|
+
from agentfork import trace, tool, wrap_openai
|
|
4
|
+
|
|
5
|
+
client = wrap_openai(OpenAI())
|
|
6
|
+
MODEL = "gpt-4o-mini"
|
|
7
|
+
|
|
8
|
+
SYSTEM = "You are a support agent. Look up the order, then refund the full order amount in USD."
|
|
9
|
+
|
|
10
|
+
TOOLS = [
|
|
11
|
+
{"type": "function", "function": {
|
|
12
|
+
"name": "lookup_order",
|
|
13
|
+
"description": "Look up an order by id.",
|
|
14
|
+
"parameters": {"type": "object",
|
|
15
|
+
"properties": {"order_id": {"type": "string"}},
|
|
16
|
+
"required": ["order_id"]}}},
|
|
17
|
+
{"type": "function", "function": {
|
|
18
|
+
"name": "issue_refund",
|
|
19
|
+
"description": "Refund an order. amount_usd is in US dollars.",
|
|
20
|
+
"parameters": {"type": "object",
|
|
21
|
+
"properties": {"order_id": {"type": "string"},
|
|
22
|
+
"amount_usd": {"type": "number"}},
|
|
23
|
+
"required": ["order_id", "amount_usd"]}}},
|
|
24
|
+
]
|
|
25
|
+
|
|
26
|
+
ORDERS = {"A123": {"order_id": "A123", "item": "laptop", "amount_usd": 49.99, "status": "delivered"}}
|
|
27
|
+
@tool
|
|
28
|
+
def lookup_order(order_id):
|
|
29
|
+
return json.dumps(ORDERS.get(order_id, {"error": "not found"}))
|
|
30
|
+
|
|
31
|
+
@tool
|
|
32
|
+
def issue_refund(order_id, amount_usd):
|
|
33
|
+
return f"Refunded ${amount_usd:,.2f} for order {order_id}"
|
|
34
|
+
|
|
35
|
+
TOOL_FUNCS = {"lookup_order": lookup_order, "issue_refund": issue_refund}
|
|
36
|
+
|
|
37
|
+
@trace
|
|
38
|
+
def run_agent(question, max_turns=6):
|
|
39
|
+
messages = [{"role": "system", "content": SYSTEM}, {"role": "user", "content": question}]
|
|
40
|
+
for _ in range(max_turns):
|
|
41
|
+
resp = client.chat.completions.create(model=MODEL, messages=messages, tools=TOOLS)
|
|
42
|
+
msg = resp.choices[0].message
|
|
43
|
+
messages.append(msg)
|
|
44
|
+
if not msg.tool_calls:
|
|
45
|
+
return msg.content
|
|
46
|
+
for call in msg.tool_calls:
|
|
47
|
+
args = json.loads(call.function.arguments)
|
|
48
|
+
output = TOOL_FUNCS[call.function.name](**args)
|
|
49
|
+
print(f" tool {call.function.name}({args}) -> {output}")
|
|
50
|
+
messages.append({"role": "tool", "tool_call_id": call.id, "content": output})
|
|
51
|
+
return "stopped: too many turns"
|
|
52
|
+
|
|
53
|
+
if __name__ == "__main__":
|
|
54
|
+
print(run_agent("My headphones from order A123 arrived broken. Please refund me."))
|
|
@@ -0,0 +1,54 @@
|
|
|
1
|
+
import json
|
|
2
|
+
from openai import OpenAI
|
|
3
|
+
from agentfork import trace, tool, wrap_openai
|
|
4
|
+
|
|
5
|
+
client = wrap_openai(OpenAI())
|
|
6
|
+
MODEL = "gpt-4o-mini"
|
|
7
|
+
|
|
8
|
+
SYSTEM = "You are a support agent. Look up the order, then refund the full order amount in USD."
|
|
9
|
+
|
|
10
|
+
TOOLS = [
|
|
11
|
+
{"type": "function", "function": {
|
|
12
|
+
"name": "lookup_order",
|
|
13
|
+
"description": "Look up an order by id.",
|
|
14
|
+
"parameters": {"type": "object",
|
|
15
|
+
"properties": {"order_id": {"type": "string"}},
|
|
16
|
+
"required": ["order_id"]}}},
|
|
17
|
+
{"type": "function", "function": {
|
|
18
|
+
"name": "issue_refund",
|
|
19
|
+
"description": "Refund an order. amount_usd is in US dollars.",
|
|
20
|
+
"parameters": {"type": "object",
|
|
21
|
+
"properties": {"order_id": {"type": "string"},
|
|
22
|
+
"amount_usd": {"type": "number"}},
|
|
23
|
+
"required": ["order_id", "amount_usd"]}}},
|
|
24
|
+
]
|
|
25
|
+
|
|
26
|
+
ORDERS = {"A123": {"order_id": "A123", "item": "laptop", "amount": 4999, "currency": "USD", "status": "delivered"}}
|
|
27
|
+
@tool
|
|
28
|
+
def lookup_order(order_id):
|
|
29
|
+
return json.dumps(ORDERS.get(order_id, {"error": "not found"}))
|
|
30
|
+
|
|
31
|
+
@tool
|
|
32
|
+
def issue_refund(order_id, amount_usd):
|
|
33
|
+
return f"Refunded ${amount_usd:,.2f} for order {order_id}"
|
|
34
|
+
|
|
35
|
+
TOOL_FUNCS = {"lookup_order": lookup_order, "issue_refund": issue_refund}
|
|
36
|
+
|
|
37
|
+
@trace
|
|
38
|
+
def run_agent(question, max_turns=6):
|
|
39
|
+
messages = [{"role": "system", "content": SYSTEM}, {"role": "user", "content": question}]
|
|
40
|
+
for _ in range(max_turns):
|
|
41
|
+
resp = client.chat.completions.create(model=MODEL, messages=messages, tools=TOOLS)
|
|
42
|
+
msg = resp.choices[0].message
|
|
43
|
+
messages.append(msg)
|
|
44
|
+
if not msg.tool_calls:
|
|
45
|
+
return msg.content
|
|
46
|
+
for call in msg.tool_calls:
|
|
47
|
+
args = json.loads(call.function.arguments)
|
|
48
|
+
output = TOOL_FUNCS[call.function.name](**args)
|
|
49
|
+
print(f" tool {call.function.name}({args}) -> {output}")
|
|
50
|
+
messages.append({"role": "tool", "tool_call_id": call.id, "content": output})
|
|
51
|
+
return "stopped: too many turns"
|
|
52
|
+
|
|
53
|
+
if __name__ == "__main__":
|
|
54
|
+
print(run_agent("My headphones from order A123 arrived broken. Please refund me."))
|