agent-memory-git 0.1.1__tar.gz → 0.1.3__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/PKG-INFO +10 -5
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/README.md +9 -4
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/pyproject.toml +1 -1
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/pyproject.toml.orig +1 -1
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/capture.py +4 -4
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/cli.py +17 -10
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/context.py +1 -2
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/frontmatter.py +2 -3
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/gitsync.py +11 -5
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/hooks.py +23 -14
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/importers.py +76 -30
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/install.py +62 -30
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/lint.py +9 -3
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/select.py +1 -2
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/sessions.py +1 -2
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/ui.py +109 -53
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/ui_server.py +70 -23
- agent_memory_git-0.1.3/src/agent_memory/webui/app.css +263 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/webui/app.js +180 -76
- agent_memory_git-0.1.3/src/agent_memory/webui/index.html +47 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/workdir.py +10 -7
- agent_memory_git-0.1.1/src/agent_memory/webui/app.css +0 -192
- agent_memory_git-0.1.1/src/agent_memory/webui/index.html +0 -31
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/LICENSE +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/PROTOCOL.md +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/__init__.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/__main__.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/config.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/embed_worker.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/store.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.3}/src/agent_memory/util.py +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: agent-memory-git
|
|
3
|
-
Version: 0.1.
|
|
3
|
+
Version: 0.1.3
|
|
4
4
|
Summary: Shared, git-backed memory for Claude Code and Codex.
|
|
5
5
|
Keywords: claude-code,codex,memory,agents,git
|
|
6
6
|
Author: Shichao Song
|
|
@@ -47,6 +47,8 @@ embedding model; leave it out after `mem ui --fetch-model` to also search by mea
|
|
|
47
47
|
|
|
48
48
|
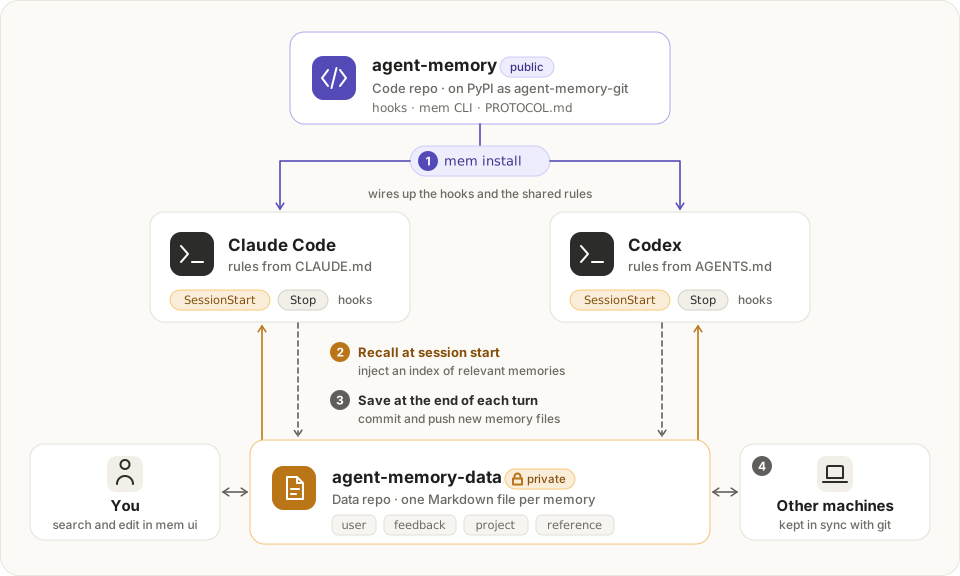
## How it works
|
|
49
49
|
|
|
50
|
+
|
|
51
|
+
|
|
50
52
|
- **One file per memory.** Frontmatter carries `type` (user / feedback / project / reference),
|
|
51
53
|
`scope` (global / here), a one-line `description`, and provenance under `source`: tool, session
|
|
52
54
|
id and name, model, host, folder, git root, remote, branch and commit. Files live in
|
|
@@ -129,11 +131,13 @@ terminal open while you use it. It needs `numpy`; the hooks do not.
|
|
|
129
131
|
- **Find.** One search box (press `/`). Word matches appear as you type, with the matching words
|
|
130
132
|
marked; a moment later the local model adds memories close in meaning, across Chinese and
|
|
131
133
|
English. Filters narrow the list by type, where a memory loads (everywhere, or one project or
|
|
132
|
-
folder), which tool wrote it, keyword,
|
|
133
|
-
|
|
134
|
+
folder), which tool wrote it, keyword, when it was added (a recent period or a date range), and
|
|
135
|
+
status (needs tidying, as `mem lint` reports and the open memory lists, or unchanged for 60
|
|
136
|
+
days). Tick several values in one filter to see memories that match any of them. The date
|
|
137
|
+
column's header sets the order: newest, oldest, recently changed or A to Z.
|
|
134
138
|
- **Read.** Click a row, or move with `j`/`k` and press Enter. The memory opens on the right with
|
|
135
|
-
|
|
136
|
-
`
|
|
139
|
+
the body rendered as Markdown with `[[links]]` that open other memories, every frontmatter field
|
|
140
|
+
(including each `source` entry), the most similar memories, and the file exactly as stored.
|
|
137
141
|
- **Change.** Edit (`e`) or delete from the open memory, add one with New (`n`), or tick several
|
|
138
142
|
rows (`x`) and delete them together. Every change is one git commit, pushed in the background,
|
|
139
143
|
with Undo. If an agent edits the same file meanwhile, saving is refused rather than overwriting.
|
|
@@ -157,6 +161,7 @@ prints, so other web pages cannot read or change memories.
|
|
|
157
161
|
uv sync --all-extras # dev tools and numpy
|
|
158
162
|
uv run pytest
|
|
159
163
|
uv run ruff check .
|
|
164
|
+
uv run ruff format .
|
|
160
165
|
```
|
|
161
166
|
|
|
162
167
|
`uv run mem ...` runs the working copy without touching the installed one. To have every
|
|
@@ -27,6 +27,8 @@ embedding model; leave it out after `mem ui --fetch-model` to also search by mea
|
|
|
27
27
|
|
|
28
28
|
## How it works
|
|
29
29
|
|
|
30
|
+

|
|
31
|
+
|
|
30
32
|
- **One file per memory.** Frontmatter carries `type` (user / feedback / project / reference),
|
|
31
33
|
`scope` (global / here), a one-line `description`, and provenance under `source`: tool, session
|
|
32
34
|
id and name, model, host, folder, git root, remote, branch and commit. Files live in
|
|
@@ -109,11 +111,13 @@ terminal open while you use it. It needs `numpy`; the hooks do not.
|
|
|
109
111
|
- **Find.** One search box (press `/`). Word matches appear as you type, with the matching words
|
|
110
112
|
marked; a moment later the local model adds memories close in meaning, across Chinese and
|
|
111
113
|
English. Filters narrow the list by type, where a memory loads (everywhere, or one project or
|
|
112
|
-
folder), which tool wrote it, keyword,
|
|
113
|
-
|
|
114
|
+
folder), which tool wrote it, keyword, when it was added (a recent period or a date range), and
|
|
115
|
+
status (needs tidying, as `mem lint` reports and the open memory lists, or unchanged for 60
|
|
116
|
+
days). Tick several values in one filter to see memories that match any of them. The date
|
|
117
|
+
column's header sets the order: newest, oldest, recently changed or A to Z.
|
|
114
118
|
- **Read.** Click a row, or move with `j`/`k` and press Enter. The memory opens on the right with
|
|
115
|
-
|
|
116
|
-
`
|
|
119
|
+
the body rendered as Markdown with `[[links]]` that open other memories, every frontmatter field
|
|
120
|
+
(including each `source` entry), the most similar memories, and the file exactly as stored.
|
|
117
121
|
- **Change.** Edit (`e`) or delete from the open memory, add one with New (`n`), or tick several
|
|
118
122
|
rows (`x`) and delete them together. Every change is one git commit, pushed in the background,
|
|
119
123
|
with Undo. If an agent edits the same file meanwhile, saving is refused rather than overwriting.
|
|
@@ -137,6 +141,7 @@ prints, so other web pages cannot read or change memories.
|
|
|
137
141
|
uv sync --all-extras # dev tools and numpy
|
|
138
142
|
uv run pytest
|
|
139
143
|
uv run ruff check .
|
|
144
|
+
uv run ruff format .
|
|
140
145
|
```
|
|
141
146
|
|
|
142
147
|
`uv run mem ...` runs the working copy without touching the installed one. To have every
|
|
@@ -148,10 +148,10 @@ def stamp_updates(data_dir):
|
|
|
148
148
|
|
|
149
149
|
def commit(data_dir, session, label=""):
|
|
150
150
|
stamp_updates(data_dir)
|
|
151
|
-
title = sessions.title(
|
|
152
|
-
|
|
153
|
-
|
|
154
|
-
|
|
151
|
+
title = sessions.title(
|
|
152
|
+
session.get("tool"), session.get("session_id"), session.get("transcript_path")
|
|
153
|
+
) or session.get("session_title", "")
|
|
154
|
+
stat = gitsync.git(data_dir, "status", "--porcelain", "-uall", "--", "memories").stdout.splitlines()
|
|
155
155
|
added = sum(1 for s in stat if s.startswith("??") or s.startswith("A"))
|
|
156
156
|
deleted = sum(1 for s in stat if s[:2].strip() == "D")
|
|
157
157
|
changed = len(stat) - added - deleted
|
|
@@ -74,8 +74,7 @@ def cmd_show(args):
|
|
|
74
74
|
def cmd_index(args):
|
|
75
75
|
data = _data()
|
|
76
76
|
ctx = detect(args.cwd)
|
|
77
|
-
paths = {"memories": str(store.memories_dir(data)), "staging": "(per session)",
|
|
78
|
-
"mem": str(config.BIN)}
|
|
77
|
+
paths = {"memories": str(store.memories_dir(data)), "staging": "(per session)", "mem": str(config.BIN)}
|
|
79
78
|
text = select.render(store.load_all(data), ctx, paths)
|
|
80
79
|
print(text, end="")
|
|
81
80
|
print(f"\n[{len(text)} characters]", file=sys.stderr)
|
|
@@ -88,8 +87,7 @@ def cmd_add(args):
|
|
|
88
87
|
sdir = store.staging_dir(data) / f"cli-{slugify(args.name)}"
|
|
89
88
|
sdir.mkdir(parents=True, exist_ok=True)
|
|
90
89
|
capture.write_session(sdir, session)
|
|
91
|
-
meta = {"name": args.name, "type": args.type, "scope": args.scope,
|
|
92
|
-
"description": args.description}
|
|
90
|
+
meta = {"name": args.name, "type": args.type, "scope": args.scope, "description": args.description}
|
|
93
91
|
atomic_write(sdir / f"{slugify(args.name)}.md", frontmatter.join(meta, body))
|
|
94
92
|
capture.flush(data, sdir, final=True)
|
|
95
93
|
print("saved")
|
|
@@ -107,6 +105,7 @@ def cmd_flush(args):
|
|
|
107
105
|
def cmd_relocate(args):
|
|
108
106
|
"""Re-attribute existing memories recorded in throwaway folders."""
|
|
109
107
|
from . import sessions, workdir
|
|
108
|
+
|
|
110
109
|
data = _data()
|
|
111
110
|
mdir = store.memories_dir(data)
|
|
112
111
|
moved = 0
|
|
@@ -116,8 +115,7 @@ def cmd_relocate(args):
|
|
|
116
115
|
continue
|
|
117
116
|
if args.only and not any(o in m["rel"] for o in args.only):
|
|
118
117
|
continue
|
|
119
|
-
transcript = src.get("transcript") or sessions.transcript_path(src.get("tool"),
|
|
120
|
-
src.get("session_id"))
|
|
118
|
+
transcript = src.get("transcript") or sessions.transcript_path(src.get("tool"), src.get("session_id"))
|
|
121
119
|
ctx = capture.relocate({"cwd": src["cwd"], "host": src.get("host")}, transcript)
|
|
122
120
|
if not ctx.get("original_cwd"):
|
|
123
121
|
print(f"keep {m['rel']} (no project found)")
|
|
@@ -146,12 +144,14 @@ def cmd_relocate(args):
|
|
|
146
144
|
|
|
147
145
|
def cmd_lint(args):
|
|
148
146
|
from . import lint
|
|
147
|
+
|
|
149
148
|
data = _data()
|
|
150
149
|
mdir = store.memories_dir(data)
|
|
151
150
|
memories = store.load_all(data)
|
|
152
151
|
names = {m["name"] for m in memories if m["name"]}
|
|
153
|
-
picked = [
|
|
154
|
-
|
|
152
|
+
picked = [
|
|
153
|
+
m for m in memories if not args.only or any(k in (m["id"], m["name"]) or k in m["rel"] for k in args.only)
|
|
154
|
+
]
|
|
155
155
|
flagged, kinds = 0, {}
|
|
156
156
|
for m in picked:
|
|
157
157
|
try:
|
|
@@ -180,6 +180,7 @@ def cmd_lint(args):
|
|
|
180
180
|
|
|
181
181
|
def cmd_ui(args):
|
|
182
182
|
from . import ui, ui_server
|
|
183
|
+
|
|
183
184
|
if args.fetch_model:
|
|
184
185
|
return ui.fetch_model()
|
|
185
186
|
ui_server.run(_data(), port=args.port, open_browser=not args.no_open, semantic=not args.keywords_only)
|
|
@@ -194,26 +195,31 @@ def cmd_sync(args):
|
|
|
194
195
|
|
|
195
196
|
def cmd_init(args):
|
|
196
197
|
from .install import init_data
|
|
198
|
+
|
|
197
199
|
init_data(Path(args.data_dir).expanduser())
|
|
198
200
|
|
|
199
201
|
|
|
200
202
|
def cmd_install(args):
|
|
201
203
|
from .install import install
|
|
204
|
+
|
|
202
205
|
install(dry_run=args.dry_run, claude=not args.no_claude, codex=not args.no_codex)
|
|
203
206
|
|
|
204
207
|
|
|
205
208
|
def cmd_uninstall(args):
|
|
206
209
|
from .install import uninstall
|
|
210
|
+
|
|
207
211
|
uninstall(dry_run=args.dry_run)
|
|
208
212
|
|
|
209
213
|
|
|
210
214
|
def cmd_import(args):
|
|
211
215
|
from . import importers
|
|
216
|
+
|
|
212
217
|
importers.run(args.source, _data(), dry_run=args.dry_run)
|
|
213
218
|
|
|
214
219
|
|
|
215
220
|
def cmd_doctor(args):
|
|
216
221
|
from .install import doctor
|
|
222
|
+
|
|
217
223
|
doctor()
|
|
218
224
|
|
|
219
225
|
|
|
@@ -277,8 +283,9 @@ def main(argv=None):
|
|
|
277
283
|
sp.add_argument("--port", type=int, default=8790)
|
|
278
284
|
sp.add_argument("--no-open", action="store_true", help="print the link without opening a browser")
|
|
279
285
|
sp.add_argument("--keywords-only", action="store_true", help="skip the embedding model")
|
|
280
|
-
sp.add_argument(
|
|
281
|
-
|
|
286
|
+
sp.add_argument(
|
|
287
|
+
"--fetch-model", action="store_true", help="download the local embedding model (about 625 MB) and exit"
|
|
288
|
+
)
|
|
282
289
|
sp.set_defaults(fn=cmd_ui)
|
|
283
290
|
|
|
284
291
|
sp = sub.add_parser("sync", help="pull and push the data repository")
|
|
@@ -10,8 +10,7 @@ _GIT_ENV = {**os.environ, "GIT_OPTIONAL_LOCKS": "0", "GIT_TERMINAL_PROMPT": "0"}
|
|
|
10
10
|
|
|
11
11
|
def _git(cwd, *args):
|
|
12
12
|
try:
|
|
13
|
-
r = subprocess.run(["git", "-C", cwd, *args], capture_output=True, text=True,
|
|
14
|
-
timeout=3, env=_GIT_ENV)
|
|
13
|
+
r = subprocess.run(["git", "-C", cwd, *args], capture_output=True, text=True, timeout=3, env=_GIT_ENV)
|
|
15
14
|
except (OSError, subprocess.SubprocessError):
|
|
16
15
|
return ""
|
|
17
16
|
return r.stdout.strip() if r.returncode == 0 else ""
|
|
@@ -18,7 +18,7 @@ def split(text):
|
|
|
18
18
|
for i in range(1, len(lines)):
|
|
19
19
|
if lines[i].strip() == FENCE:
|
|
20
20
|
meta = parse("\n".join(lines[1:i]))
|
|
21
|
-
body = "\n".join(lines[i + 1:]).lstrip("\n")
|
|
21
|
+
body = "\n".join(lines[i + 1 :]).lstrip("\n")
|
|
22
22
|
return meta, body
|
|
23
23
|
return {}, text
|
|
24
24
|
|
|
@@ -28,8 +28,7 @@ def join(meta, body):
|
|
|
28
28
|
|
|
29
29
|
|
|
30
30
|
def parse(block):
|
|
31
|
-
lines = [line.rstrip() for line in block.split("\n")
|
|
32
|
-
if line.strip() and not line.lstrip().startswith("#")]
|
|
31
|
+
lines = [line.rstrip() for line in block.split("\n") if line.strip() and not line.lstrip().startswith("#")]
|
|
33
32
|
if not lines:
|
|
34
33
|
return {}
|
|
35
34
|
value, _ = _parse_map(lines, 0, _indent(lines[0]))
|
|
@@ -43,8 +43,9 @@ class Lock:
|
|
|
43
43
|
|
|
44
44
|
|
|
45
45
|
def git(data_dir, *args, timeout=30):
|
|
46
|
-
return subprocess.run(
|
|
47
|
-
|
|
46
|
+
return subprocess.run(
|
|
47
|
+
["git", "-C", str(data_dir), *args], capture_output=True, text=True, timeout=timeout, env=_ENV
|
|
48
|
+
)
|
|
48
49
|
|
|
49
50
|
|
|
50
51
|
def has_remote(data_dir):
|
|
@@ -112,8 +113,13 @@ def spawn_sync(data_dir, push):
|
|
|
112
113
|
log_path = Path(data_dir) / ".cache" / "sync.out"
|
|
113
114
|
try:
|
|
114
115
|
with open(log_path, "a") as out:
|
|
115
|
-
subprocess.Popen(
|
|
116
|
-
|
|
117
|
-
|
|
116
|
+
subprocess.Popen(
|
|
117
|
+
args,
|
|
118
|
+
stdin=subprocess.DEVNULL,
|
|
119
|
+
stdout=out,
|
|
120
|
+
stderr=out,
|
|
121
|
+
start_new_session=True,
|
|
122
|
+
env={**os.environ, "AGENT_MEMORY_DATA": str(data_dir)},
|
|
123
|
+
)
|
|
118
124
|
except OSError as e:
|
|
119
125
|
log(data_dir, f"spawn sync failed: {e}")
|
|
@@ -36,14 +36,17 @@ def session_start(payload, tool, data_dir):
|
|
|
36
36
|
ctx = detect(payload.get("cwd"))
|
|
37
37
|
sdir = capture.session_dir(data_dir, tool, sid)
|
|
38
38
|
sdir.mkdir(parents=True, exist_ok=True)
|
|
39
|
-
capture.write_session(
|
|
40
|
-
|
|
41
|
-
|
|
42
|
-
|
|
43
|
-
|
|
44
|
-
|
|
45
|
-
|
|
46
|
-
|
|
39
|
+
capture.write_session(
|
|
40
|
+
sdir,
|
|
41
|
+
{
|
|
42
|
+
"tool": tool,
|
|
43
|
+
"session_id": sid,
|
|
44
|
+
"session_title": payload.get("session_title"),
|
|
45
|
+
"model": payload.get("model"),
|
|
46
|
+
"transcript_path": payload.get("transcript_path"),
|
|
47
|
+
"ctx": ctx,
|
|
48
|
+
},
|
|
49
|
+
)
|
|
47
50
|
|
|
48
51
|
recovered = capture.recover_orphans(data_dir, keep=sdir)
|
|
49
52
|
stamp = Path(data_dir) / ".cache" / "last-pull"
|
|
@@ -59,8 +62,7 @@ def session_start(payload, tool, data_dir):
|
|
|
59
62
|
"staging": str(sdir),
|
|
60
63
|
"mem": str(config.BIN),
|
|
61
64
|
}
|
|
62
|
-
return select.render(store.load_all(data_dir), ctx, paths,
|
|
63
|
-
throwaway=workdir.is_throwaway(ctx.get("cwd")))
|
|
65
|
+
return select.render(store.load_all(data_dir), ctx, paths, throwaway=workdir.is_throwaway(ctx.get("cwd")))
|
|
64
66
|
|
|
65
67
|
|
|
66
68
|
def flush(payload, tool, data_dir, final):
|
|
@@ -82,10 +84,17 @@ def main(event, tool):
|
|
|
82
84
|
try:
|
|
83
85
|
if event == "session-start":
|
|
84
86
|
text = session_start(payload, tool, data_dir)
|
|
85
|
-
print(
|
|
86
|
-
|
|
87
|
-
|
|
88
|
-
|
|
87
|
+
print(
|
|
88
|
+
json.dumps(
|
|
89
|
+
{
|
|
90
|
+
"hookSpecificOutput": {
|
|
91
|
+
"hookEventName": "SessionStart",
|
|
92
|
+
"additionalContext": text,
|
|
93
|
+
}
|
|
94
|
+
},
|
|
95
|
+
ensure_ascii=False,
|
|
96
|
+
)
|
|
97
|
+
)
|
|
89
98
|
elif event in ("stop", "session-end"):
|
|
90
99
|
flush(payload, tool, data_dir, final=event == "session-end")
|
|
91
100
|
else:
|
|
@@ -32,14 +32,21 @@ def _git_source(cwd):
|
|
|
32
32
|
def _record(*, name, typ, scope, description, body, created, source):
|
|
33
33
|
when = parse_time(created) or now()
|
|
34
34
|
memory_id = new_id(name, when)
|
|
35
|
-
meta = {
|
|
36
|
-
|
|
37
|
-
|
|
35
|
+
meta = {
|
|
36
|
+
"id": memory_id,
|
|
37
|
+
"name": slugify(name),
|
|
38
|
+
"type": typ,
|
|
39
|
+
"scope": scope,
|
|
40
|
+
"description": " ".join(description.split())[:300],
|
|
41
|
+
"created": when.isoformat(),
|
|
42
|
+
"source": {k: v for k, v in source.items() if v},
|
|
43
|
+
}
|
|
38
44
|
return memory_id, meta, body
|
|
39
45
|
|
|
40
46
|
|
|
41
47
|
# ---------------------------------------------------------------- Claude Code
|
|
42
48
|
|
|
49
|
+
|
|
43
50
|
def _decode_project_dir(name):
|
|
44
51
|
"""Recover a folder from Claude's dash-encoded project dir name, if it still exists."""
|
|
45
52
|
tokens = name.lstrip("-").split("-")
|
|
@@ -109,15 +116,24 @@ def claude_items():
|
|
|
109
116
|
original_cwd, cwd = cwd, inferred
|
|
110
117
|
created = legacy.get("modified") or meta.get("modified") or _mtime(path)
|
|
111
118
|
title = sessions.title("claude-code", origin, transcript) if transcript else ""
|
|
112
|
-
source = {
|
|
113
|
-
|
|
114
|
-
|
|
115
|
-
|
|
116
|
-
|
|
117
|
-
|
|
118
|
-
|
|
119
|
-
|
|
120
|
-
|
|
119
|
+
source = {
|
|
120
|
+
"tool": "claude-code",
|
|
121
|
+
"session_id": origin,
|
|
122
|
+
"session_name": title,
|
|
123
|
+
**_git_source(cwd),
|
|
124
|
+
"original_cwd": original_cwd,
|
|
125
|
+
"imported_from": "claude-code auto memory",
|
|
126
|
+
"original": "~/" + path.relative_to(HOME).as_posix(),
|
|
127
|
+
}
|
|
128
|
+
yield _record(
|
|
129
|
+
name=m["name"] or path.stem,
|
|
130
|
+
typ=m["type"],
|
|
131
|
+
scope="global" if m["type"] in ("user", "feedback") else "here",
|
|
132
|
+
description=m["description"],
|
|
133
|
+
body=body,
|
|
134
|
+
created=created,
|
|
135
|
+
source=source,
|
|
136
|
+
)
|
|
121
137
|
|
|
122
138
|
|
|
123
139
|
def _mtime(path):
|
|
@@ -126,6 +142,7 @@ def _mtime(path):
|
|
|
126
142
|
|
|
127
143
|
# ---------------------------------------------------------------- Codex
|
|
128
144
|
|
|
145
|
+
|
|
129
146
|
def _sections(text):
|
|
130
147
|
out, current = {}, None
|
|
131
148
|
for line in text.splitlines():
|
|
@@ -158,9 +175,15 @@ def _codex_source(original, cwd=None, thread=None):
|
|
|
158
175
|
inferred = workdir.infer(rollout, cwd, workdir.default_exclude())
|
|
159
176
|
if inferred:
|
|
160
177
|
original_cwd, cwd = cwd, inferred
|
|
161
|
-
return {
|
|
162
|
-
|
|
163
|
-
|
|
178
|
+
return {
|
|
179
|
+
"tool": "codex",
|
|
180
|
+
"session_id": thread,
|
|
181
|
+
"session_name": title,
|
|
182
|
+
**_git_source(cwd),
|
|
183
|
+
"original_cwd": original_cwd,
|
|
184
|
+
"imported_from": "codex memories",
|
|
185
|
+
"original": "~/" + (CODEX_MEMORIES / original).relative_to(HOME).as_posix(),
|
|
186
|
+
}
|
|
164
187
|
|
|
165
188
|
|
|
166
189
|
def codex_items():
|
|
@@ -171,17 +194,28 @@ def codex_items():
|
|
|
171
194
|
profile = " ".join(line.strip() for line in sec.get("User Profile", []) if line.strip())
|
|
172
195
|
if profile:
|
|
173
196
|
profile = profile.replace(ADHOC_TAG, "").strip()
|
|
174
|
-
yield _record(
|
|
175
|
-
|
|
176
|
-
|
|
177
|
-
|
|
197
|
+
yield _record(
|
|
198
|
+
name="user-profile-from-codex",
|
|
199
|
+
typ="user",
|
|
200
|
+
scope="global",
|
|
201
|
+
description="User profile as summarised by Codex: " + profile[:200],
|
|
202
|
+
body=profile + "\n",
|
|
203
|
+
created=created,
|
|
204
|
+
source=_codex_source("memory_summary.md#user-profile"),
|
|
205
|
+
)
|
|
178
206
|
for heading in ("User preferences", "General Tips"):
|
|
179
207
|
for n, text in enumerate(_bullets(sec.get(heading, []))):
|
|
180
208
|
if ADHOC_TAG in text or text.startswith("Skills:"):
|
|
181
209
|
continue # ad-hoc notes are imported from their own files
|
|
182
|
-
yield _record(
|
|
183
|
-
|
|
184
|
-
|
|
210
|
+
yield _record(
|
|
211
|
+
name=" ".join(text.split()[:6]),
|
|
212
|
+
typ="feedback",
|
|
213
|
+
scope="global",
|
|
214
|
+
description=text,
|
|
215
|
+
body=text + "\n",
|
|
216
|
+
created=created,
|
|
217
|
+
source=_codex_source(f"memory_summary.md#{slugify(heading)}-{n}"),
|
|
218
|
+
)
|
|
185
219
|
|
|
186
220
|
handbook = CODEX_MEMORIES / "MEMORY.md"
|
|
187
221
|
if handbook.exists():
|
|
@@ -189,27 +223,39 @@ def codex_items():
|
|
|
189
223
|
for block in blocks:
|
|
190
224
|
if not block.startswith("# Task Group: "):
|
|
191
225
|
continue
|
|
192
|
-
title = block.splitlines()[0][len("# Task Group: "):].strip()
|
|
226
|
+
title = block.splitlines()[0][len("# Task Group: ") :].strip()
|
|
193
227
|
cwd = next(iter(re.findall(r"cwd=([^\s;,)]+)", block)), None)
|
|
194
228
|
thread = next(iter(re.findall(r"thread_id=([0-9a-f-]{36})", block)), None)
|
|
195
229
|
stamps = sorted(re.findall(r"updated_at=([0-9T:.+-]+Z?)", block))
|
|
196
|
-
yield _record(
|
|
197
|
-
|
|
198
|
-
|
|
199
|
-
|
|
230
|
+
yield _record(
|
|
231
|
+
name=title,
|
|
232
|
+
typ="project",
|
|
233
|
+
scope="here",
|
|
234
|
+
description=f"Codex task history: {title}",
|
|
235
|
+
body=block.rstrip() + "\n",
|
|
236
|
+
created=stamps[-1] if stamps else _mtime(handbook),
|
|
237
|
+
source=_codex_source(f"MEMORY.md#{slugify(title)}", cwd, thread),
|
|
238
|
+
)
|
|
200
239
|
|
|
201
240
|
for path in sorted((CODEX_MEMORIES / "extensions" / "ad_hoc" / "notes").glob("*.md")):
|
|
202
241
|
body = path.read_text("utf-8")
|
|
203
242
|
_, raw = frontmatter.split(body)
|
|
204
243
|
desc = normalize({}, raw, path.stem)["description"]
|
|
205
244
|
name = re.sub(r"^[0-9T_-]+", "", path.stem) or path.stem
|
|
206
|
-
yield _record(
|
|
207
|
-
|
|
208
|
-
|
|
245
|
+
yield _record(
|
|
246
|
+
name=name,
|
|
247
|
+
typ="reference",
|
|
248
|
+
scope="global",
|
|
249
|
+
description=desc,
|
|
250
|
+
body=raw,
|
|
251
|
+
created=_mtime(path),
|
|
252
|
+
source=_codex_source(path.relative_to(CODEX_MEMORIES).as_posix()),
|
|
253
|
+
)
|
|
209
254
|
|
|
210
255
|
|
|
211
256
|
# ---------------------------------------------------------------- driver
|
|
212
257
|
|
|
258
|
+
|
|
213
259
|
def run(which, data_dir, dry_run=False):
|
|
214
260
|
items = list(claude_items() if which == "claude" else codex_items())
|
|
215
261
|
seen = {m["source"].get("original") for m in load_all(data_dir)}
|