agent-memory-git 0.1.1__tar.gz → 0.1.2__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/PKG-INFO +4 -1
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/README.md +3 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/pyproject.toml +1 -1
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/pyproject.toml.orig +1 -1
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/capture.py +4 -4
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/cli.py +17 -10
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/context.py +1 -2
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/frontmatter.py +2 -3
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/gitsync.py +11 -5
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/hooks.py +23 -14
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/importers.py +76 -30
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/install.py +62 -30
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/lint.py +9 -3
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/select.py +1 -2
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/sessions.py +1 -2
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/ui.py +109 -53
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/ui_server.py +70 -23
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/workdir.py +10 -7
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/LICENSE +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/PROTOCOL.md +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/__init__.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/__main__.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/config.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/embed_worker.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/store.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/util.py +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/webui/app.css +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/webui/app.js +0 -0
- {agent_memory_git-0.1.1 → agent_memory_git-0.1.2}/src/agent_memory/webui/index.html +0 -0
|
@@ -1,6 +1,6 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: agent-memory-git
|
|
3
|
-
Version: 0.1.
|
|
3
|
+
Version: 0.1.2
|
|
4
4
|
Summary: Shared, git-backed memory for Claude Code and Codex.
|
|
5
5
|
Keywords: claude-code,codex,memory,agents,git
|
|
6
6
|
Author: Shichao Song
|
|
@@ -47,6 +47,8 @@ embedding model; leave it out after `mem ui --fetch-model` to also search by mea
|
|
|
47
47
|
|
|
48
48
|
## How it works
|
|
49
49
|
|
|
50
|
+
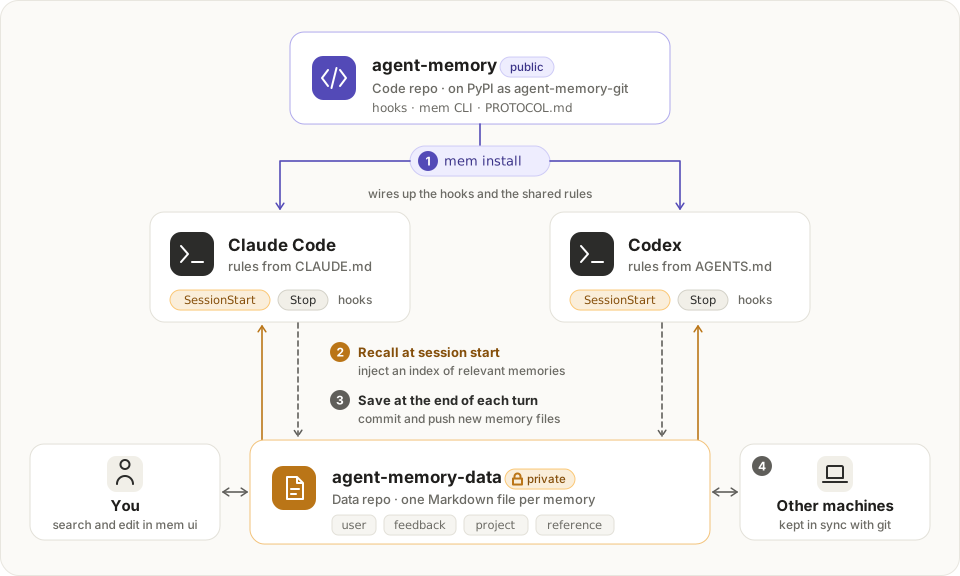
|
|
51
|
+
|
|
50
52
|
- **One file per memory.** Frontmatter carries `type` (user / feedback / project / reference),
|
|
51
53
|
`scope` (global / here), a one-line `description`, and provenance under `source`: tool, session
|
|
52
54
|
id and name, model, host, folder, git root, remote, branch and commit. Files live in
|
|
@@ -157,6 +159,7 @@ prints, so other web pages cannot read or change memories.
|
|
|
157
159
|
uv sync --all-extras # dev tools and numpy
|
|
158
160
|
uv run pytest
|
|
159
161
|
uv run ruff check .
|
|
162
|
+
uv run ruff format .
|
|
160
163
|
```
|
|
161
164
|
|
|
162
165
|
`uv run mem ...` runs the working copy without touching the installed one. To have every
|
|
@@ -27,6 +27,8 @@ embedding model; leave it out after `mem ui --fetch-model` to also search by mea
|
|
|
27
27
|
|
|
28
28
|
## How it works
|
|
29
29
|
|
|
30
|
+

|
|
31
|
+
|
|
30
32
|
- **One file per memory.** Frontmatter carries `type` (user / feedback / project / reference),
|
|
31
33
|
`scope` (global / here), a one-line `description`, and provenance under `source`: tool, session
|
|
32
34
|
id and name, model, host, folder, git root, remote, branch and commit. Files live in
|
|
@@ -137,6 +139,7 @@ prints, so other web pages cannot read or change memories.
|
|
|
137
139
|
uv sync --all-extras # dev tools and numpy
|
|
138
140
|
uv run pytest
|
|
139
141
|
uv run ruff check .
|
|
142
|
+
uv run ruff format .
|
|
140
143
|
```
|
|
141
144
|
|
|
142
145
|
`uv run mem ...` runs the working copy without touching the installed one. To have every
|
|
@@ -148,10 +148,10 @@ def stamp_updates(data_dir):
|
|
|
148
148
|
|
|
149
149
|
def commit(data_dir, session, label=""):
|
|
150
150
|
stamp_updates(data_dir)
|
|
151
|
-
title = sessions.title(
|
|
152
|
-
|
|
153
|
-
|
|
154
|
-
|
|
151
|
+
title = sessions.title(
|
|
152
|
+
session.get("tool"), session.get("session_id"), session.get("transcript_path")
|
|
153
|
+
) or session.get("session_title", "")
|
|
154
|
+
stat = gitsync.git(data_dir, "status", "--porcelain", "-uall", "--", "memories").stdout.splitlines()
|
|
155
155
|
added = sum(1 for s in stat if s.startswith("??") or s.startswith("A"))
|
|
156
156
|
deleted = sum(1 for s in stat if s[:2].strip() == "D")
|
|
157
157
|
changed = len(stat) - added - deleted
|
|
@@ -74,8 +74,7 @@ def cmd_show(args):
|
|
|
74
74
|
def cmd_index(args):
|
|
75
75
|
data = _data()
|
|
76
76
|
ctx = detect(args.cwd)
|
|
77
|
-
paths = {"memories": str(store.memories_dir(data)), "staging": "(per session)",
|
|
78
|
-
"mem": str(config.BIN)}
|
|
77
|
+
paths = {"memories": str(store.memories_dir(data)), "staging": "(per session)", "mem": str(config.BIN)}
|
|
79
78
|
text = select.render(store.load_all(data), ctx, paths)
|
|
80
79
|
print(text, end="")
|
|
81
80
|
print(f"\n[{len(text)} characters]", file=sys.stderr)
|
|
@@ -88,8 +87,7 @@ def cmd_add(args):
|
|
|
88
87
|
sdir = store.staging_dir(data) / f"cli-{slugify(args.name)}"
|
|
89
88
|
sdir.mkdir(parents=True, exist_ok=True)
|
|
90
89
|
capture.write_session(sdir, session)
|
|
91
|
-
meta = {"name": args.name, "type": args.type, "scope": args.scope,
|
|
92
|
-
"description": args.description}
|
|
90
|
+
meta = {"name": args.name, "type": args.type, "scope": args.scope, "description": args.description}
|
|
93
91
|
atomic_write(sdir / f"{slugify(args.name)}.md", frontmatter.join(meta, body))
|
|
94
92
|
capture.flush(data, sdir, final=True)
|
|
95
93
|
print("saved")
|
|
@@ -107,6 +105,7 @@ def cmd_flush(args):
|
|
|
107
105
|
def cmd_relocate(args):
|
|
108
106
|
"""Re-attribute existing memories recorded in throwaway folders."""
|
|
109
107
|
from . import sessions, workdir
|
|
108
|
+
|
|
110
109
|
data = _data()
|
|
111
110
|
mdir = store.memories_dir(data)
|
|
112
111
|
moved = 0
|
|
@@ -116,8 +115,7 @@ def cmd_relocate(args):
|
|
|
116
115
|
continue
|
|
117
116
|
if args.only and not any(o in m["rel"] for o in args.only):
|
|
118
117
|
continue
|
|
119
|
-
transcript = src.get("transcript") or sessions.transcript_path(src.get("tool"),
|
|
120
|
-
src.get("session_id"))
|
|
118
|
+
transcript = src.get("transcript") or sessions.transcript_path(src.get("tool"), src.get("session_id"))
|
|
121
119
|
ctx = capture.relocate({"cwd": src["cwd"], "host": src.get("host")}, transcript)
|
|
122
120
|
if not ctx.get("original_cwd"):
|
|
123
121
|
print(f"keep {m['rel']} (no project found)")
|
|
@@ -146,12 +144,14 @@ def cmd_relocate(args):
|
|
|
146
144
|
|
|
147
145
|
def cmd_lint(args):
|
|
148
146
|
from . import lint
|
|
147
|
+
|
|
149
148
|
data = _data()
|
|
150
149
|
mdir = store.memories_dir(data)
|
|
151
150
|
memories = store.load_all(data)
|
|
152
151
|
names = {m["name"] for m in memories if m["name"]}
|
|
153
|
-
picked = [
|
|
154
|
-
|
|
152
|
+
picked = [
|
|
153
|
+
m for m in memories if not args.only or any(k in (m["id"], m["name"]) or k in m["rel"] for k in args.only)
|
|
154
|
+
]
|
|
155
155
|
flagged, kinds = 0, {}
|
|
156
156
|
for m in picked:
|
|
157
157
|
try:
|
|
@@ -180,6 +180,7 @@ def cmd_lint(args):
|
|
|
180
180
|
|
|
181
181
|
def cmd_ui(args):
|
|
182
182
|
from . import ui, ui_server
|
|
183
|
+
|
|
183
184
|
if args.fetch_model:
|
|
184
185
|
return ui.fetch_model()
|
|
185
186
|
ui_server.run(_data(), port=args.port, open_browser=not args.no_open, semantic=not args.keywords_only)
|
|
@@ -194,26 +195,31 @@ def cmd_sync(args):
|
|
|
194
195
|
|
|
195
196
|
def cmd_init(args):
|
|
196
197
|
from .install import init_data
|
|
198
|
+
|
|
197
199
|
init_data(Path(args.data_dir).expanduser())
|
|
198
200
|
|
|
199
201
|
|
|
200
202
|
def cmd_install(args):
|
|
201
203
|
from .install import install
|
|
204
|
+
|
|
202
205
|
install(dry_run=args.dry_run, claude=not args.no_claude, codex=not args.no_codex)
|
|
203
206
|
|
|
204
207
|
|
|
205
208
|
def cmd_uninstall(args):
|
|
206
209
|
from .install import uninstall
|
|
210
|
+
|
|
207
211
|
uninstall(dry_run=args.dry_run)
|
|
208
212
|
|
|
209
213
|
|
|
210
214
|
def cmd_import(args):
|
|
211
215
|
from . import importers
|
|
216
|
+
|
|
212
217
|
importers.run(args.source, _data(), dry_run=args.dry_run)
|
|
213
218
|
|
|
214
219
|
|
|
215
220
|
def cmd_doctor(args):
|
|
216
221
|
from .install import doctor
|
|
222
|
+
|
|
217
223
|
doctor()
|
|
218
224
|
|
|
219
225
|
|
|
@@ -277,8 +283,9 @@ def main(argv=None):
|
|
|
277
283
|
sp.add_argument("--port", type=int, default=8790)
|
|
278
284
|
sp.add_argument("--no-open", action="store_true", help="print the link without opening a browser")
|
|
279
285
|
sp.add_argument("--keywords-only", action="store_true", help="skip the embedding model")
|
|
280
|
-
sp.add_argument(
|
|
281
|
-
|
|
286
|
+
sp.add_argument(
|
|
287
|
+
"--fetch-model", action="store_true", help="download the local embedding model (about 625 MB) and exit"
|
|
288
|
+
)
|
|
282
289
|
sp.set_defaults(fn=cmd_ui)
|
|
283
290
|
|
|
284
291
|
sp = sub.add_parser("sync", help="pull and push the data repository")
|
|
@@ -10,8 +10,7 @@ _GIT_ENV = {**os.environ, "GIT_OPTIONAL_LOCKS": "0", "GIT_TERMINAL_PROMPT": "0"}
|
|
|
10
10
|
|
|
11
11
|
def _git(cwd, *args):
|
|
12
12
|
try:
|
|
13
|
-
r = subprocess.run(["git", "-C", cwd, *args], capture_output=True, text=True,
|
|
14
|
-
timeout=3, env=_GIT_ENV)
|
|
13
|
+
r = subprocess.run(["git", "-C", cwd, *args], capture_output=True, text=True, timeout=3, env=_GIT_ENV)
|
|
15
14
|
except (OSError, subprocess.SubprocessError):
|
|
16
15
|
return ""
|
|
17
16
|
return r.stdout.strip() if r.returncode == 0 else ""
|
|
@@ -18,7 +18,7 @@ def split(text):
|
|
|
18
18
|
for i in range(1, len(lines)):
|
|
19
19
|
if lines[i].strip() == FENCE:
|
|
20
20
|
meta = parse("\n".join(lines[1:i]))
|
|
21
|
-
body = "\n".join(lines[i + 1:]).lstrip("\n")
|
|
21
|
+
body = "\n".join(lines[i + 1 :]).lstrip("\n")
|
|
22
22
|
return meta, body
|
|
23
23
|
return {}, text
|
|
24
24
|
|
|
@@ -28,8 +28,7 @@ def join(meta, body):
|
|
|
28
28
|
|
|
29
29
|
|
|
30
30
|
def parse(block):
|
|
31
|
-
lines = [line.rstrip() for line in block.split("\n")
|
|
32
|
-
if line.strip() and not line.lstrip().startswith("#")]
|
|
31
|
+
lines = [line.rstrip() for line in block.split("\n") if line.strip() and not line.lstrip().startswith("#")]
|
|
33
32
|
if not lines:
|
|
34
33
|
return {}
|
|
35
34
|
value, _ = _parse_map(lines, 0, _indent(lines[0]))
|
|
@@ -43,8 +43,9 @@ class Lock:
|
|
|
43
43
|
|
|
44
44
|
|
|
45
45
|
def git(data_dir, *args, timeout=30):
|
|
46
|
-
return subprocess.run(
|
|
47
|
-
|
|
46
|
+
return subprocess.run(
|
|
47
|
+
["git", "-C", str(data_dir), *args], capture_output=True, text=True, timeout=timeout, env=_ENV
|
|
48
|
+
)
|
|
48
49
|
|
|
49
50
|
|
|
50
51
|
def has_remote(data_dir):
|
|
@@ -112,8 +113,13 @@ def spawn_sync(data_dir, push):
|
|
|
112
113
|
log_path = Path(data_dir) / ".cache" / "sync.out"
|
|
113
114
|
try:
|
|
114
115
|
with open(log_path, "a") as out:
|
|
115
|
-
subprocess.Popen(
|
|
116
|
-
|
|
117
|
-
|
|
116
|
+
subprocess.Popen(
|
|
117
|
+
args,
|
|
118
|
+
stdin=subprocess.DEVNULL,
|
|
119
|
+
stdout=out,
|
|
120
|
+
stderr=out,
|
|
121
|
+
start_new_session=True,
|
|
122
|
+
env={**os.environ, "AGENT_MEMORY_DATA": str(data_dir)},
|
|
123
|
+
)
|
|
118
124
|
except OSError as e:
|
|
119
125
|
log(data_dir, f"spawn sync failed: {e}")
|
|
@@ -36,14 +36,17 @@ def session_start(payload, tool, data_dir):
|
|
|
36
36
|
ctx = detect(payload.get("cwd"))
|
|
37
37
|
sdir = capture.session_dir(data_dir, tool, sid)
|
|
38
38
|
sdir.mkdir(parents=True, exist_ok=True)
|
|
39
|
-
capture.write_session(
|
|
40
|
-
|
|
41
|
-
|
|
42
|
-
|
|
43
|
-
|
|
44
|
-
|
|
45
|
-
|
|
46
|
-
|
|
39
|
+
capture.write_session(
|
|
40
|
+
sdir,
|
|
41
|
+
{
|
|
42
|
+
"tool": tool,
|
|
43
|
+
"session_id": sid,
|
|
44
|
+
"session_title": payload.get("session_title"),
|
|
45
|
+
"model": payload.get("model"),
|
|
46
|
+
"transcript_path": payload.get("transcript_path"),
|
|
47
|
+
"ctx": ctx,
|
|
48
|
+
},
|
|
49
|
+
)
|
|
47
50
|
|
|
48
51
|
recovered = capture.recover_orphans(data_dir, keep=sdir)
|
|
49
52
|
stamp = Path(data_dir) / ".cache" / "last-pull"
|
|
@@ -59,8 +62,7 @@ def session_start(payload, tool, data_dir):
|
|
|
59
62
|
"staging": str(sdir),
|
|
60
63
|
"mem": str(config.BIN),
|
|
61
64
|
}
|
|
62
|
-
return select.render(store.load_all(data_dir), ctx, paths,
|
|
63
|
-
throwaway=workdir.is_throwaway(ctx.get("cwd")))
|
|
65
|
+
return select.render(store.load_all(data_dir), ctx, paths, throwaway=workdir.is_throwaway(ctx.get("cwd")))
|
|
64
66
|
|
|
65
67
|
|
|
66
68
|
def flush(payload, tool, data_dir, final):
|
|
@@ -82,10 +84,17 @@ def main(event, tool):
|
|
|
82
84
|
try:
|
|
83
85
|
if event == "session-start":
|
|
84
86
|
text = session_start(payload, tool, data_dir)
|
|
85
|
-
print(
|
|
86
|
-
|
|
87
|
-
|
|
88
|
-
|
|
87
|
+
print(
|
|
88
|
+
json.dumps(
|
|
89
|
+
{
|
|
90
|
+
"hookSpecificOutput": {
|
|
91
|
+
"hookEventName": "SessionStart",
|
|
92
|
+
"additionalContext": text,
|
|
93
|
+
}
|
|
94
|
+
},
|
|
95
|
+
ensure_ascii=False,
|
|
96
|
+
)
|
|
97
|
+
)
|
|
89
98
|
elif event in ("stop", "session-end"):
|
|
90
99
|
flush(payload, tool, data_dir, final=event == "session-end")
|
|
91
100
|
else:
|
|
@@ -32,14 +32,21 @@ def _git_source(cwd):
|
|
|
32
32
|
def _record(*, name, typ, scope, description, body, created, source):
|
|
33
33
|
when = parse_time(created) or now()
|
|
34
34
|
memory_id = new_id(name, when)
|
|
35
|
-
meta = {
|
|
36
|
-
|
|
37
|
-
|
|
35
|
+
meta = {
|
|
36
|
+
"id": memory_id,
|
|
37
|
+
"name": slugify(name),
|
|
38
|
+
"type": typ,
|
|
39
|
+
"scope": scope,
|
|
40
|
+
"description": " ".join(description.split())[:300],
|
|
41
|
+
"created": when.isoformat(),
|
|
42
|
+
"source": {k: v for k, v in source.items() if v},
|
|
43
|
+
}
|
|
38
44
|
return memory_id, meta, body
|
|
39
45
|
|
|
40
46
|
|
|
41
47
|
# ---------------------------------------------------------------- Claude Code
|
|
42
48
|
|
|
49
|
+
|
|
43
50
|
def _decode_project_dir(name):
|
|
44
51
|
"""Recover a folder from Claude's dash-encoded project dir name, if it still exists."""
|
|
45
52
|
tokens = name.lstrip("-").split("-")
|
|
@@ -109,15 +116,24 @@ def claude_items():
|
|
|
109
116
|
original_cwd, cwd = cwd, inferred
|
|
110
117
|
created = legacy.get("modified") or meta.get("modified") or _mtime(path)
|
|
111
118
|
title = sessions.title("claude-code", origin, transcript) if transcript else ""
|
|
112
|
-
source = {
|
|
113
|
-
|
|
114
|
-
|
|
115
|
-
|
|
116
|
-
|
|
117
|
-
|
|
118
|
-
|
|
119
|
-
|
|
120
|
-
|
|
119
|
+
source = {
|
|
120
|
+
"tool": "claude-code",
|
|
121
|
+
"session_id": origin,
|
|
122
|
+
"session_name": title,
|
|
123
|
+
**_git_source(cwd),
|
|
124
|
+
"original_cwd": original_cwd,
|
|
125
|
+
"imported_from": "claude-code auto memory",
|
|
126
|
+
"original": "~/" + path.relative_to(HOME).as_posix(),
|
|
127
|
+
}
|
|
128
|
+
yield _record(
|
|
129
|
+
name=m["name"] or path.stem,
|
|
130
|
+
typ=m["type"],
|
|
131
|
+
scope="global" if m["type"] in ("user", "feedback") else "here",
|
|
132
|
+
description=m["description"],
|
|
133
|
+
body=body,
|
|
134
|
+
created=created,
|
|
135
|
+
source=source,
|
|
136
|
+
)
|
|
121
137
|
|
|
122
138
|
|
|
123
139
|
def _mtime(path):
|
|
@@ -126,6 +142,7 @@ def _mtime(path):
|
|
|
126
142
|
|
|
127
143
|
# ---------------------------------------------------------------- Codex
|
|
128
144
|
|
|
145
|
+
|
|
129
146
|
def _sections(text):
|
|
130
147
|
out, current = {}, None
|
|
131
148
|
for line in text.splitlines():
|
|
@@ -158,9 +175,15 @@ def _codex_source(original, cwd=None, thread=None):
|
|
|
158
175
|
inferred = workdir.infer(rollout, cwd, workdir.default_exclude())
|
|
159
176
|
if inferred:
|
|
160
177
|
original_cwd, cwd = cwd, inferred
|
|
161
|
-
return {
|
|
162
|
-
|
|
163
|
-
|
|
178
|
+
return {
|
|
179
|
+
"tool": "codex",
|
|
180
|
+
"session_id": thread,
|
|
181
|
+
"session_name": title,
|
|
182
|
+
**_git_source(cwd),
|
|
183
|
+
"original_cwd": original_cwd,
|
|
184
|
+
"imported_from": "codex memories",
|
|
185
|
+
"original": "~/" + (CODEX_MEMORIES / original).relative_to(HOME).as_posix(),
|
|
186
|
+
}
|
|
164
187
|
|
|
165
188
|
|
|
166
189
|
def codex_items():
|
|
@@ -171,17 +194,28 @@ def codex_items():
|
|
|
171
194
|
profile = " ".join(line.strip() for line in sec.get("User Profile", []) if line.strip())
|
|
172
195
|
if profile:
|
|
173
196
|
profile = profile.replace(ADHOC_TAG, "").strip()
|
|
174
|
-
yield _record(
|
|
175
|
-
|
|
176
|
-
|
|
177
|
-
|
|
197
|
+
yield _record(
|
|
198
|
+
name="user-profile-from-codex",
|
|
199
|
+
typ="user",
|
|
200
|
+
scope="global",
|
|
201
|
+
description="User profile as summarised by Codex: " + profile[:200],
|
|
202
|
+
body=profile + "\n",
|
|
203
|
+
created=created,
|
|
204
|
+
source=_codex_source("memory_summary.md#user-profile"),
|
|
205
|
+
)
|
|
178
206
|
for heading in ("User preferences", "General Tips"):
|
|
179
207
|
for n, text in enumerate(_bullets(sec.get(heading, []))):
|
|
180
208
|
if ADHOC_TAG in text or text.startswith("Skills:"):
|
|
181
209
|
continue # ad-hoc notes are imported from their own files
|
|
182
|
-
yield _record(
|
|
183
|
-
|
|
184
|
-
|
|
210
|
+
yield _record(
|
|
211
|
+
name=" ".join(text.split()[:6]),
|
|
212
|
+
typ="feedback",
|
|
213
|
+
scope="global",
|
|
214
|
+
description=text,
|
|
215
|
+
body=text + "\n",
|
|
216
|
+
created=created,
|
|
217
|
+
source=_codex_source(f"memory_summary.md#{slugify(heading)}-{n}"),
|
|
218
|
+
)
|
|
185
219
|
|
|
186
220
|
handbook = CODEX_MEMORIES / "MEMORY.md"
|
|
187
221
|
if handbook.exists():
|
|
@@ -189,27 +223,39 @@ def codex_items():
|
|
|
189
223
|
for block in blocks:
|
|
190
224
|
if not block.startswith("# Task Group: "):
|
|
191
225
|
continue
|
|
192
|
-
title = block.splitlines()[0][len("# Task Group: "):].strip()
|
|
226
|
+
title = block.splitlines()[0][len("# Task Group: ") :].strip()
|
|
193
227
|
cwd = next(iter(re.findall(r"cwd=([^\s;,)]+)", block)), None)
|
|
194
228
|
thread = next(iter(re.findall(r"thread_id=([0-9a-f-]{36})", block)), None)
|
|
195
229
|
stamps = sorted(re.findall(r"updated_at=([0-9T:.+-]+Z?)", block))
|
|
196
|
-
yield _record(
|
|
197
|
-
|
|
198
|
-
|
|
199
|
-
|
|
230
|
+
yield _record(
|
|
231
|
+
name=title,
|
|
232
|
+
typ="project",
|
|
233
|
+
scope="here",
|
|
234
|
+
description=f"Codex task history: {title}",
|
|
235
|
+
body=block.rstrip() + "\n",
|
|
236
|
+
created=stamps[-1] if stamps else _mtime(handbook),
|
|
237
|
+
source=_codex_source(f"MEMORY.md#{slugify(title)}", cwd, thread),
|
|
238
|
+
)
|
|
200
239
|
|
|
201
240
|
for path in sorted((CODEX_MEMORIES / "extensions" / "ad_hoc" / "notes").glob("*.md")):
|
|
202
241
|
body = path.read_text("utf-8")
|
|
203
242
|
_, raw = frontmatter.split(body)
|
|
204
243
|
desc = normalize({}, raw, path.stem)["description"]
|
|
205
244
|
name = re.sub(r"^[0-9T_-]+", "", path.stem) or path.stem
|
|
206
|
-
yield _record(
|
|
207
|
-
|
|
208
|
-
|
|
245
|
+
yield _record(
|
|
246
|
+
name=name,
|
|
247
|
+
typ="reference",
|
|
248
|
+
scope="global",
|
|
249
|
+
description=desc,
|
|
250
|
+
body=raw,
|
|
251
|
+
created=_mtime(path),
|
|
252
|
+
source=_codex_source(path.relative_to(CODEX_MEMORIES).as_posix()),
|
|
253
|
+
)
|
|
209
254
|
|
|
210
255
|
|
|
211
256
|
# ---------------------------------------------------------------- driver
|
|
212
257
|
|
|
258
|
+
|
|
213
259
|
def run(which, data_dir, dry_run=False):
|
|
214
260
|
items = list(claude_items() if which == "claude" else codex_items())
|
|
215
261
|
seen = {m["source"].get("original") for m in load_all(data_dir)}
|
|
@@ -33,21 +33,26 @@ SH_BEGIN = "# >>> agent-memory >>>"
|
|
|
33
33
|
SH_END = "# <<< agent-memory <<<"
|
|
34
34
|
PATH_LINE = 'export PATH="$HOME/.local/bin:$PATH"'
|
|
35
35
|
|
|
36
|
-
HOOK_EVENTS = [
|
|
37
|
-
|
|
38
|
-
|
|
36
|
+
HOOK_EVENTS = [
|
|
37
|
+
("SessionStart", "session-start", 15),
|
|
38
|
+
("Stop", "stop", 15),
|
|
39
|
+
("SessionEnd", "session-end", 3),
|
|
40
|
+
] # Codex clamps SessionEnd to 3s
|
|
39
41
|
|
|
40
42
|
|
|
41
43
|
# ---------------------------------------------------------------- helpers
|
|
42
44
|
|
|
45
|
+
|
|
43
46
|
def hook_command(event, tool):
|
|
44
47
|
return " ".join(shlex.quote(a) for a in config.mem_command()) + f" hook {event} --tool {tool}"
|
|
45
48
|
|
|
46
49
|
|
|
47
50
|
def _is_ours(group):
|
|
48
|
-
return any(
|
|
49
|
-
|
|
50
|
-
|
|
51
|
+
return any(
|
|
52
|
+
("agent-memory" in h.get("command", "") or "agent_memory" in h.get("command", ""))
|
|
53
|
+
and " hook " in h.get("command", "")
|
|
54
|
+
for h in group.get("hooks", [])
|
|
55
|
+
)
|
|
51
56
|
|
|
52
57
|
|
|
53
58
|
def _home_rel(path):
|
|
@@ -135,7 +140,7 @@ def toml_unset(text, section, key):
|
|
|
135
140
|
span = _toml_section("\n".join(lines), section)
|
|
136
141
|
if span: # drop the section if we emptied it
|
|
137
142
|
i, j = span
|
|
138
|
-
if all(not line.strip() for line in lines[i + 1:j]):
|
|
143
|
+
if all(not line.strip() for line in lines[i + 1 : j]):
|
|
139
144
|
del lines[i:j]
|
|
140
145
|
return "\n".join(lines)
|
|
141
146
|
|
|
@@ -149,8 +154,9 @@ def _login_path():
|
|
|
149
154
|
shell = os.environ.get("SHELL", "/bin/zsh")
|
|
150
155
|
env = {"HOME": str(HOME), "USER": os.environ.get("USER", ""), "SHELL": shell, "TERM": "dumb"}
|
|
151
156
|
try:
|
|
152
|
-
r = subprocess.run(
|
|
153
|
-
|
|
157
|
+
r = subprocess.run(
|
|
158
|
+
[shell, "-lic", 'printf "__P__%s__P__" "$PATH"'], env=env, capture_output=True, text=True, timeout=15
|
|
159
|
+
)
|
|
154
160
|
except (OSError, subprocess.SubprocessError):
|
|
155
161
|
return None
|
|
156
162
|
m = re.search(r"__P__(.*?)__P__", r.stdout, re.S)
|
|
@@ -174,9 +180,10 @@ def _path_plan(plan, state):
|
|
|
174
180
|
|
|
175
181
|
# ---------------------------------------------------------------- planning
|
|
176
182
|
|
|
183
|
+
|
|
177
184
|
class Plan:
|
|
178
185
|
def __init__(self):
|
|
179
|
-
self.files = {}
|
|
186
|
+
self.files = {} # path -> (old_text or None, new_text or None)
|
|
180
187
|
self.state = {}
|
|
181
188
|
|
|
182
189
|
def edit(self, path, new_text):
|
|
@@ -222,15 +229,22 @@ def _claude_plan(plan, data_dir, state):
|
|
|
222
229
|
hooks = new.setdefault("hooks", {})
|
|
223
230
|
for event, name, timeout in HOOK_EVENTS:
|
|
224
231
|
groups = [g for g in hooks.get(event, []) if not _is_ours(g)]
|
|
225
|
-
groups.append(
|
|
226
|
-
|
|
232
|
+
groups.append(
|
|
233
|
+
{"hooks": [{"type": "command", "command": hook_command(name, "claude-code"), "timeout": timeout}]}
|
|
234
|
+
)
|
|
227
235
|
hooks[event] = groups
|
|
228
236
|
|
|
229
237
|
data = _home_rel(data_dir)
|
|
230
|
-
rules = [
|
|
231
|
-
|
|
232
|
-
|
|
233
|
-
|
|
238
|
+
rules = [
|
|
239
|
+
f"Read({data}/**)",
|
|
240
|
+
f"Edit({data}/**)",
|
|
241
|
+
f"Bash({config.BIN} search:*)",
|
|
242
|
+
f"Bash({config.BIN} list:*)",
|
|
243
|
+
f"Bash({config.BIN} show:*)",
|
|
244
|
+
"Bash(mem search:*)",
|
|
245
|
+
"Bash(mem list:*)",
|
|
246
|
+
"Bash(mem show:*)",
|
|
247
|
+
]
|
|
234
248
|
allow = new.setdefault("permissions", {}).setdefault("allow", [])
|
|
235
249
|
added = [r for r in rules if r not in allow]
|
|
236
250
|
allow.extend(added)
|
|
@@ -267,8 +281,10 @@ def _codex_plan(plan, data_dir, state):
|
|
|
267
281
|
toml = toml_set(toml, "memories", key, "false")
|
|
268
282
|
roots = toml_get(toml, "sandbox_workspace_write", "writable_roots")
|
|
269
283
|
roots = [] if roots == MISSING else list(roots)
|
|
270
|
-
state.setdefault(
|
|
271
|
-
|
|
284
|
+
state.setdefault(
|
|
285
|
+
"codex.writable_roots.had_key",
|
|
286
|
+
toml_get(_read(toml_path) or "", "sandbox_workspace_write", "writable_roots") != MISSING,
|
|
287
|
+
)
|
|
272
288
|
if str(data_dir) not in roots:
|
|
273
289
|
roots.append(str(data_dir))
|
|
274
290
|
state["codex.writable_root"] = str(data_dir)
|
|
@@ -283,6 +299,7 @@ def _codex_plan(plan, data_dir, state):
|
|
|
283
299
|
|
|
284
300
|
# ---------------------------------------------------------------- commands
|
|
285
301
|
|
|
302
|
+
|
|
286
303
|
def _load_state():
|
|
287
304
|
try:
|
|
288
305
|
return json.loads(STATE_FILE.read_text("utf-8"))
|
|
@@ -302,12 +319,15 @@ def init_data(data_dir):
|
|
|
302
319
|
"# agent-memory data\n\n"
|
|
303
320
|
"One Markdown file per memory under `memories/YYYY/MM/`, written by Claude Code and\n"
|
|
304
321
|
"Codex through the agent-memory hooks. Edit or delete files freely; every change is\n"
|
|
305
|
-
"a git commit.\n",
|
|
322
|
+
"a git commit.\n",
|
|
323
|
+
"utf-8",
|
|
324
|
+
)
|
|
306
325
|
if not (data_dir / ".git").exists():
|
|
307
326
|
gitsync.git(data_dir, "init", "-q", "-b", "main")
|
|
308
327
|
gitsync.git(data_dir, "add", "-A")
|
|
309
|
-
gitsync.git(
|
|
310
|
-
|
|
328
|
+
gitsync.git(
|
|
329
|
+
data_dir, "-c", "commit.gpgsign=false", "commit", "-q", "--no-verify", "-m", "Initialize memory repository"
|
|
330
|
+
)
|
|
311
331
|
cfg = config.load()
|
|
312
332
|
cfg["data_dir"] = str(data_dir)
|
|
313
333
|
config.save(cfg)
|
|
@@ -397,8 +417,11 @@ def uninstall(dry_run=False):
|
|
|
397
417
|
toml = _read(path) or ""
|
|
398
418
|
for key in ("generate_memories", "use_memories"):
|
|
399
419
|
prev = state.get(f"codex.memories.{key}", MISSING)
|
|
400
|
-
toml =
|
|
401
|
-
|
|
420
|
+
toml = (
|
|
421
|
+
toml_unset(toml, "memories", key)
|
|
422
|
+
if prev == MISSING
|
|
423
|
+
else toml_set(toml, "memories", key, _toml_literal(prev))
|
|
424
|
+
)
|
|
402
425
|
root = state.get("codex.writable_root")
|
|
403
426
|
roots = toml_get(toml, "sandbox_workspace_write", "writable_roots")
|
|
404
427
|
if root and roots != MISSING:
|
|
@@ -473,21 +496,30 @@ def doctor():
|
|
|
473
496
|
check(s.get("autoMemoryEnabled") is False, "Claude auto memory disabled")
|
|
474
497
|
for event, _, _ in HOOK_EVENTS:
|
|
475
498
|
check(any(_is_ours(g) for g in s.get("hooks", {}).get(event, [])), f"Claude {event} hook")
|
|
476
|
-
check(
|
|
477
|
-
|
|
478
|
-
|
|
499
|
+
check(
|
|
500
|
+
f"@{config.PROTOCOL_COPY}" in (_read(CLAUDE_DIR / "CLAUDE.md") or ""),
|
|
501
|
+
"Claude CLAUDE.md imports PROTOCOL.md",
|
|
502
|
+
)
|
|
503
|
+
check(
|
|
504
|
+
_read(config.PROTOCOL_COPY) == config.PROTOCOL.read_text("utf-8"),
|
|
505
|
+
"Claude's PROTOCOL.md copy is current (else run `mem install`)",
|
|
506
|
+
)
|
|
479
507
|
if state.get("codex"):
|
|
480
508
|
doc = json.loads(_read(CODEX_DIR / "hooks.json") or "{}")
|
|
481
509
|
for event, _, _ in HOOK_EVENTS:
|
|
482
510
|
check(any(_is_ours(g) for g in doc.get("hooks", {}).get(event, [])), f"Codex {event} hook")
|
|
483
511
|
toml = _read(CODEX_DIR / "config.toml") or ""
|
|
484
512
|
check(toml_get(toml, "memories", "use_memories") is False, "Codex native memories disabled")
|
|
485
|
-
check(
|
|
486
|
-
|
|
513
|
+
check(
|
|
514
|
+
config.PROTOCOL.read_text("utf-8").rstrip() in (_read(CODEX_DIR / "AGENTS.md") or ""),
|
|
515
|
+
"Codex AGENTS.md has the current protocol (else run `mem install`)",
|
|
516
|
+
)
|
|
487
517
|
path = _login_path()
|
|
488
518
|
if path is not None:
|
|
489
|
-
check(
|
|
490
|
-
|
|
519
|
+
check(
|
|
520
|
+
str(LOCAL_BIN.parent) in path or SH_BEGIN in (_read(_rc_file()) or ""),
|
|
521
|
+
f"`mem` on a new terminal's PATH ({LOCAL_BIN.parent})",
|
|
522
|
+
)
|
|
491
523
|
if data:
|
|
492
524
|
check(gitsync.has_remote(data), "data repository has a remote (optional)")
|
|
493
525
|
staged = list((data / "staging").glob("*/*.md")) if (data / "staging").exists() else []
|
|
@@ -6,15 +6,21 @@ someone tidies it, so nothing is rejected.
|
|
|
6
6
|
|
|
7
7
|
import re
|
|
8
8
|
|
|
9
|
-
DESCRIPTION_MAX = 150
|
|
9
|
+
DESCRIPTION_MAX = 150 # the index cuts longer descriptions (select.line)
|
|
10
10
|
BODY_MAX = 1500
|
|
11
11
|
NEEDS_REASON = ("feedback", "project")
|
|
12
12
|
|
|
13
13
|
_WHY = re.compile(r"\*\*\s*why\s*:?\s*\*\*", re.I)
|
|
14
14
|
_HOW = re.compile(r"\*\*\s*how to apply\s*:?\s*\*\*", re.I)
|
|
15
15
|
_WIKI = re.compile(r"\[\[([^\]]+)\]\]")
|
|
16
|
-
KINDS = {
|
|
17
|
-
|
|
16
|
+
KINDS = {
|
|
17
|
+
"long": "too long",
|
|
18
|
+
"reason": "without Why or How to apply",
|
|
19
|
+
"heading": "opening with a heading",
|
|
20
|
+
"description": "with a description the index cuts",
|
|
21
|
+
"links": "with broken links",
|
|
22
|
+
"empty": "empty",
|
|
23
|
+
}
|
|
18
24
|
|
|
19
25
|
|
|
20
26
|
def check(m, body, names):
|
|
@@ -72,8 +72,7 @@ def _take(items, budget):
|
|
|
72
72
|
return out, used
|
|
73
73
|
|
|
74
74
|
|
|
75
|
-
THROWAWAY_NOTE =
|
|
76
|
-
"this session works in")
|
|
75
|
+
THROWAWAY_NOTE = "throwaway folder: `here` memories will be filed under the project this session works in"
|
|
77
76
|
|
|
78
77
|
|
|
79
78
|
def render(memories, ctx, paths, budget=DEFAULT_BUDGET, throwaway=False):
|
|
@@ -30,8 +30,7 @@ def _codex_thread(session_id, column):
|
|
|
30
30
|
try:
|
|
31
31
|
con = sqlite3.connect(f"file:{dbs[-1]}?mode=ro", uri=True, timeout=1)
|
|
32
32
|
try:
|
|
33
|
-
row = con.execute(f"select {column} from threads where id = ?",
|
|
34
|
-
(session_id,)).fetchone()
|
|
33
|
+
row = con.execute(f"select {column} from threads where id = ?", (session_id,)).fetchone()
|
|
35
34
|
finally:
|
|
36
35
|
con.close()
|
|
37
36
|
except sqlite3.Error:
|
|
@@ -33,23 +33,28 @@ MODEL = {
|
|
|
33
33
|
"dir": "qwen3-embedding-0.6b-int8",
|
|
34
34
|
"repo": "onnx-community/Qwen3-Embedding-0.6B-ONNX",
|
|
35
35
|
"revision": "c25a394dd583836952667c12f008335071b3f43d",
|
|
36
|
-
"files": {
|
|
37
|
-
|
|
38
|
-
|
|
36
|
+
"files": {
|
|
37
|
+
"onnx/model_quantized.onnx": "87cd124e0ef1fd1f223ebc283efccbaeac386d0b08344701c46975d0657b591f",
|
|
38
|
+
"config.json": None,
|
|
39
|
+
"tokenizer.json": None,
|
|
40
|
+
"tokenizer_config.json": None,
|
|
41
|
+
"special_tokens_map.json": None,
|
|
42
|
+
},
|
|
39
43
|
# Plain text, no instruction prefix: on known same-topic pairs (including Chinese/English
|
|
40
44
|
# ones) this ranked partners closer than the topic or similarity instructions did.
|
|
41
45
|
"instruction": "",
|
|
42
46
|
}
|
|
43
47
|
WORKER_DEPS = ["onnxruntime==1.31.0", "tokenizers==0.23.3", "numpy"]
|
|
44
|
-
EMBED_CHARS = 2000
|
|
45
|
-
TITLE_WEIGHT = 3
|
|
46
|
-
NEIGHBORS = 6
|
|
47
|
-
KEYWORDS = 4
|
|
48
|
+
EMBED_CHARS = 2000 # characters of each memory given to the model
|
|
49
|
+
TITLE_WEIGHT = 3 # description and name count this many times in keyword vectors
|
|
50
|
+
NEIGHBORS = 6 # similar memories listed for each memory
|
|
51
|
+
KEYWORDS = 4 # keywords shown for each memory
|
|
48
52
|
SEARCH_INSTRUCTION = "Instruct: Given a search query, retrieve memory notes about it\nQuery: "
|
|
49
53
|
|
|
50
54
|
_ASCII = re.compile(r"[A-Za-z][A-Za-z0-9_+#-]*[A-Za-z0-9+#]|[A-Za-z]")
|
|
51
55
|
_CJK = re.compile(r"[㐀-鿿]+")
|
|
52
|
-
_STOP = set(
|
|
56
|
+
_STOP = set(
|
|
57
|
+
"""
|
|
53
58
|
a about above after again against all also am an and any are as at be because been before being
|
|
54
59
|
below between both but by can could did do does doing done down during each either else etc even
|
|
55
60
|
ever every few for from further get gets got had has have having he her here hers him his how i if
|
|
@@ -67,21 +72,28 @@ rollout_summary_files rollout_summaries applies_to reuse_rule keywords reusable
|
|
|
67
72
|
differently preferences apply how why outcome success partial history summary
|
|
68
73
|
asked plus real never check checks verify verified evidence explicit said complete final current
|
|
69
74
|
live state local source remote text path test symptom instead before after already actual ad-hoc
|
|
70
|
-
""".split()
|
|
75
|
+
""".split()
|
|
76
|
+
)
|
|
71
77
|
# Paths, URLs, hashes and ids say where something lives, not what it is about.
|
|
72
|
-
_NOISE = re.compile(
|
|
73
|
-
|
|
74
|
-
|
|
75
|
-
|
|
78
|
+
_NOISE = re.compile(
|
|
79
|
+
r"(?:https?://\S+|(?:~|/|\.\.?/)[\w.@%+-]+(?:/[\w.@%+-]*)+"
|
|
80
|
+
r"|\b[\w.-]+\.(?:md|json|jsonl|py|ts|js|html|yaml|yml|toml|txt|sh)\b"
|
|
81
|
+
r"|\b[0-9a-f]{8}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{12}\b|\b[0-9a-f]{7,40}\b"
|
|
82
|
+
r"|\b\d{4}-\d\d-\d\d(?:[T ][\d:.+-]+)?\b)"
|
|
83
|
+
)
|
|
76
84
|
CJK_MAX = 4
|
|
77
|
-
_STOP_CJK = set(
|
|
85
|
+
_STOP_CJK = set(
|
|
86
|
+
"""
|
|
78
87
|
的是 是的 一个 这个 那个 可以 需要 如果 因为 所以 但是 而且 或者 以及 我们 你们 他们 用户 时候 没有 不是 就是
|
|
79
88
|
已经 进行 通过 使用 这样 这些 那些 什么 怎么 为了 之后 之前 然后 还是 一下 一些 这里 那里 其中 以后 以前 不要
|
|
80
89
|
必须 应该 能够 只是 也是 都是 就会 会在 在这 这次 每次 一次 当前 目前 现在 之类 等等 方面 问题 内容 情况
|
|
81
90
|
相关 进行 这种 时候 需要 不能 不会 只有 直接 所有 其他 自己 一样 部分 以上 以下 下来 起来 出来 每个 各个 任何 一定 先给
|
|
82
|
-
""".split()
|
|
91
|
+
""".split()
|
|
92
|
+
)
|
|
83
93
|
# Function characters that start no word: 的了和与… A string beginning with one is a fragment.
|
|
84
|
-
_CJK_BAD_START = set(
|
|
94
|
+
_CJK_BAD_START = set(
|
|
95
|
+
"的了和与及或就都也把被让给并而时在是对向从个件等上不每一这那该各再又还才只很最更已将会能要可使于以之其此"
|
|
96
|
+
)
|
|
85
97
|
_CJK_KEEP = {"完成", "生成", "集成", "构成", "组成", "前后", "最后", "然后", "之后", "背后", "上一", "中文"}
|
|
86
98
|
# ...and characters that end no word: a string ending in one runs into the next word.
|
|
87
99
|
_CJK_BAD_END = set("的了着过是在和与及等上中里成到给把被让后不也都就又再才很一个这那各每将会能要可于以之其此任")
|
|
@@ -89,6 +101,7 @@ _CJK_BAD_END = set("的了着过是在和与及等上中里成到给把被让后
|
|
|
89
101
|
|
|
90
102
|
# ------------------------------------------------------------ keyword vectors
|
|
91
103
|
|
|
104
|
+
|
|
92
105
|
def clean(text):
|
|
93
106
|
return _NOISE.sub(" ", text)
|
|
94
107
|
|
|
@@ -105,7 +118,7 @@ def chinese_words(texts):
|
|
|
105
118
|
grams = set()
|
|
106
119
|
for run in _CJK.findall(text):
|
|
107
120
|
for n in range(2, CJK_MAX + 1):
|
|
108
|
-
grams.update(run[i:i + n] for i in range(len(run) - n + 1))
|
|
121
|
+
grams.update(run[i : i + n] for i in range(len(run) - n + 1))
|
|
109
122
|
df.update(grams)
|
|
110
123
|
frequent = {g for g, d in df.items() if d >= 2}
|
|
111
124
|
words = set()
|
|
@@ -113,8 +126,11 @@ def chinese_words(texts):
|
|
|
113
126
|
longer = [h for h in frequent if len(h) == len(g) + 1 and g in h]
|
|
114
127
|
if not any(df[h] >= 0.8 * df[g] for h in longer):
|
|
115
128
|
words.add(g)
|
|
116
|
-
return {
|
|
117
|
-
|
|
129
|
+
return {
|
|
130
|
+
w
|
|
131
|
+
for w in words - _STOP_CJK
|
|
132
|
+
if (w[0] not in _CJK_BAD_START or w == "时间") and (w[-1] not in _CJK_BAD_END or w in _CJK_KEEP)
|
|
133
|
+
}
|
|
118
134
|
|
|
119
135
|
|
|
120
136
|
def tokens(text, words=frozenset()):
|
|
@@ -136,8 +152,8 @@ def tokens(text, words=frozenset()):
|
|
|
136
152
|
i = 0
|
|
137
153
|
while i < len(run) - 1:
|
|
138
154
|
for n in range(min(CJK_MAX, len(run) - i), 1, -1):
|
|
139
|
-
if run[i:i + n] in words:
|
|
140
|
-
out.append(run[i:i + n])
|
|
155
|
+
if run[i : i + n] in words:
|
|
156
|
+
out.append(run[i : i + n])
|
|
141
157
|
i += n
|
|
142
158
|
break
|
|
143
159
|
else:
|
|
@@ -155,7 +171,8 @@ def _display_forms(texts):
|
|
|
155
171
|
|
|
156
172
|
|
|
157
173
|
# Plain English words that score high in TF-IDF but say little about what a memory is about.
|
|
158
|
-
_GENERIC = set(
|
|
174
|
+
_GENERIC = set(
|
|
175
|
+
"""
|
|
159
176
|
actually specified large small nontrivial declaring declared truth human builds build built pin pinned
|
|
160
177
|
following follow follows needed need needs means mean simple simply clear clearly important exact exactly
|
|
161
178
|
whole entire full fully main mainly certain directly direct proper properly various several general
|
|
@@ -163,7 +180,8 @@ correct correctly wrong instead later earlier often usually rather quite really
|
|
|
163
180
|
item items part parts kind way ways case cases point points detail details thing result results
|
|
164
181
|
come comes edit edits edited anything something everything separate change changes changed
|
|
165
182
|
fail fails failed code example examples
|
|
166
|
-
""".split()
|
|
183
|
+
""".split()
|
|
184
|
+
)
|
|
167
185
|
|
|
168
186
|
|
|
169
187
|
def _term_like(display):
|
|
@@ -271,13 +289,21 @@ def embed(data_dir, texts):
|
|
|
271
289
|
if todo:
|
|
272
290
|
out = cache_file.with_name("new-vectors.npy")
|
|
273
291
|
out.parent.mkdir(parents=True, exist_ok=True)
|
|
274
|
-
job = {
|
|
275
|
-
|
|
292
|
+
job = {
|
|
293
|
+
"model_dir": str(model_dir()),
|
|
294
|
+
"out": str(out),
|
|
295
|
+
"max_tokens": 512,
|
|
296
|
+
"texts": [MODEL["instruction"] + texts[i] for i in todo],
|
|
297
|
+
}
|
|
276
298
|
print(f"embedding {len(todo)} memories with {MODEL['name']}…", flush=True)
|
|
277
|
-
cmd =
|
|
299
|
+
cmd = (
|
|
300
|
+
["uv", "run", "--no-project", "--quiet"]
|
|
301
|
+
+ [a for dep in WORKER_DEPS for a in ("--with", dep)]
|
|
278
302
|
+ ["python", "-I", str(WORKER)]
|
|
279
|
-
|
|
280
|
-
|
|
303
|
+
)
|
|
304
|
+
r = subprocess.run(
|
|
305
|
+
cmd, input=json.dumps(job), text=True, cwd=str(out.parent), env={**os.environ, "PYTHONWARNINGS": "ignore"}
|
|
306
|
+
)
|
|
281
307
|
if r.returncode != 0:
|
|
282
308
|
print("embedding failed; falling back to keywords", file=sys.stderr)
|
|
283
309
|
return None
|
|
@@ -307,9 +333,10 @@ def closeness(vectors):
|
|
|
307
333
|
|
|
308
334
|
# ------------------------------------------------------------ page data
|
|
309
335
|
|
|
336
|
+
|
|
310
337
|
def _short(path):
|
|
311
338
|
home = str(HOME)
|
|
312
|
-
return "~" + path[len(home):] if path and (path == home or path.startswith(home + "/")) else path or ""
|
|
339
|
+
return "~" + path[len(home) :] if path and (path == home or path.startswith(home + "/")) else path or ""
|
|
313
340
|
|
|
314
341
|
|
|
315
342
|
def _place(src):
|
|
@@ -355,31 +382,52 @@ def build(data_dir, semantic=True, vectors_out=None):
|
|
|
355
382
|
for i, (m, raw, meta, body) in enumerate(items):
|
|
356
383
|
order = [int(j) for j in np.argsort(-sim[i]) if j != i][:NEIGHBORS]
|
|
357
384
|
src = m["source"]
|
|
358
|
-
rows.append(
|
|
359
|
-
|
|
360
|
-
|
|
361
|
-
|
|
362
|
-
|
|
363
|
-
|
|
364
|
-
|
|
365
|
-
|
|
366
|
-
|
|
367
|
-
|
|
368
|
-
|
|
369
|
-
|
|
370
|
-
|
|
385
|
+
rows.append(
|
|
386
|
+
{
|
|
387
|
+
"id": m["id"],
|
|
388
|
+
"rel": m["rel"],
|
|
389
|
+
"path": str(mdir / m["rel"]),
|
|
390
|
+
"hash": hashlib.sha1(raw.encode()).hexdigest()[:16],
|
|
391
|
+
"raw": raw,
|
|
392
|
+
"meta": json.loads(json.dumps(meta, default=str)),
|
|
393
|
+
"body": body,
|
|
394
|
+
"description": m["description"],
|
|
395
|
+
"type": m["type"],
|
|
396
|
+
"scope": m["scope"],
|
|
397
|
+
"place": _place(src) if m["scope"] == "here" else "",
|
|
398
|
+
"tool": src.get("tool") or "",
|
|
399
|
+
"host": src.get("host") or "",
|
|
400
|
+
"created": m["created"],
|
|
401
|
+
"updated": m["updated"],
|
|
402
|
+
"similar": [{"i": j, "s": round(float(sim[i, j]), 3)} for j in order if sim[i, j] > 0],
|
|
403
|
+
"keywords": [{"k": vocab[j], "t": forms.get(vocab[j], vocab[j])} for j in picks[i]],
|
|
404
|
+
"terms": [vocab[j] for j in np.flatnonzero(x[i])],
|
|
405
|
+
"issues": [message for _, message in lint.check(m, body, names)],
|
|
406
|
+
}
|
|
407
|
+
)
|
|
371
408
|
if m["scope"] == "here" and (src.get("git_remote") or src.get("cwd")):
|
|
372
409
|
key = _place(src)
|
|
373
|
-
places.setdefault(
|
|
374
|
-
|
|
375
|
-
|
|
410
|
+
places.setdefault(
|
|
411
|
+
key,
|
|
412
|
+
{
|
|
413
|
+
"key": key,
|
|
414
|
+
"count": 0,
|
|
415
|
+
"ctx": {k: src[k] for k in ("cwd", "git_root", "git_remote", "git_branch", "host") if src.get(k)},
|
|
416
|
+
},
|
|
417
|
+
)
|
|
376
418
|
places[key]["count"] += 1
|
|
377
|
-
return {
|
|
378
|
-
|
|
419
|
+
return {
|
|
420
|
+
**base,
|
|
421
|
+
"memories": rows,
|
|
422
|
+
"method": method,
|
|
423
|
+
"semantic": vectors is not None,
|
|
424
|
+
"places": sorted(places.values(), key=lambda p: (-p["count"], p["key"])),
|
|
425
|
+
}
|
|
379
426
|
|
|
380
427
|
|
|
381
428
|
# ------------------------------------------------------------ query embedding
|
|
382
429
|
|
|
430
|
+
|
|
383
431
|
class QueryEncoder:
|
|
384
432
|
"""A long-lived embedding worker for search queries (model loads once)."""
|
|
385
433
|
|
|
@@ -392,12 +440,20 @@ class QueryEncoder:
|
|
|
392
440
|
return None
|
|
393
441
|
with self.lock:
|
|
394
442
|
if self.proc is None or self.proc.poll() is not None:
|
|
395
|
-
cmd =
|
|
396
|
-
[
|
|
397
|
-
[
|
|
398
|
-
|
|
399
|
-
|
|
400
|
-
|
|
443
|
+
cmd = (
|
|
444
|
+
["uv", "run", "--no-project", "--quiet"]
|
|
445
|
+
+ [a for dep in WORKER_DEPS for a in ("--with", dep)]
|
|
446
|
+
+ ["python", "-I", str(WORKER), "--serve", str(model_dir())]
|
|
447
|
+
)
|
|
448
|
+
self.proc = subprocess.Popen(
|
|
449
|
+
cmd,
|
|
450
|
+
stdin=subprocess.PIPE,
|
|
451
|
+
stdout=subprocess.PIPE,
|
|
452
|
+
stderr=subprocess.DEVNULL,
|
|
453
|
+
text=True,
|
|
454
|
+
bufsize=1,
|
|
455
|
+
cwd=str(model_dir()),
|
|
456
|
+
)
|
|
401
457
|
self.proc.stdin.write(json.dumps({"text": SEARCH_INSTRUCTION + text}) + "\n")
|
|
402
458
|
self.proc.stdin.flush()
|
|
403
459
|
line = self.proc.stdout.readline()
|
|
@@ -26,10 +26,11 @@ from .context import detect, hostname
|
|
|
26
26
|
from .util import SCOPES, TYPES, atomic_write, id_path, log_exc, new_id, now_iso, slugify
|
|
27
27
|
|
|
28
28
|
STATIC = Path(__file__).with_name("webui")
|
|
29
|
-
MIME = {".html": "text/html; charset=utf-8", ".css": "text/css; charset=utf-8",
|
|
30
|
-
|
|
31
|
-
|
|
32
|
-
|
|
29
|
+
MIME = {".html": "text/html; charset=utf-8", ".css": "text/css; charset=utf-8", ".js": "text/javascript; charset=utf-8"}
|
|
30
|
+
CSP = (
|
|
31
|
+
"default-src 'self'; script-src 'self'; style-src 'self' 'unsafe-inline'; img-src 'self' data:; "
|
|
32
|
+
"connect-src 'self'; frame-ancestors 'none'; base-uri 'none'; form-action 'none'"
|
|
33
|
+
)
|
|
33
34
|
PLACE_FIELDS = ("cwd", "git_root", "git_remote", "git_branch")
|
|
34
35
|
SEARCH_HITS = 8
|
|
35
36
|
|
|
@@ -94,8 +95,7 @@ class UiApp:
|
|
|
94
95
|
scores = self.vectors @ vec
|
|
95
96
|
order = np.argsort(-scores)[:SEARCH_HITS]
|
|
96
97
|
ids = [self.state["memories"][int(i)]["id"] for i in order]
|
|
97
|
-
return {"hits": [{"id": mid, "s": round(float(scores[i]), 3)} for mid, i in zip(ids, order)],
|
|
98
|
-
"semantic": True}
|
|
98
|
+
return {"hits": [{"id": mid, "s": round(float(scores[i]), 3)} for mid, i in zip(ids, order)], "semantic": True}
|
|
99
99
|
|
|
100
100
|
# ------------------------------------------------------------ writes
|
|
101
101
|
|
|
@@ -109,8 +109,11 @@ class UiApp:
|
|
|
109
109
|
path = self.mdir / self._find(mid)["rel"]
|
|
110
110
|
text = path.read_text("utf-8")
|
|
111
111
|
if base and hashlib.sha1(text.encode()).hexdigest()[:16] != base:
|
|
112
|
-
raise ApiError(
|
|
113
|
-
|
|
112
|
+
raise ApiError(
|
|
113
|
+
409,
|
|
114
|
+
"This memory changed on disk after you opened it (an agent may have "
|
|
115
|
+
"edited it). Close it and open it again to see the new version.",
|
|
116
|
+
)
|
|
114
117
|
meta, body = frontmatter.split(text)
|
|
115
118
|
return path, meta, body
|
|
116
119
|
|
|
@@ -129,8 +132,18 @@ class UiApp:
|
|
|
129
132
|
def _commit(self, paths, message):
|
|
130
133
|
rels = [str(Path(p).relative_to(self.data)) for p in ([paths] if isinstance(paths, (str, Path)) else paths)]
|
|
131
134
|
gitsync.git(self.data, "add", "-A", "--", *rels)
|
|
132
|
-
r = gitsync.git(
|
|
133
|
-
|
|
135
|
+
r = gitsync.git(
|
|
136
|
+
self.data,
|
|
137
|
+
"-c",
|
|
138
|
+
"commit.gpgsign=false",
|
|
139
|
+
"commit",
|
|
140
|
+
"-q",
|
|
141
|
+
"--no-verify",
|
|
142
|
+
"-m",
|
|
143
|
+
message + "\n\nTool: ui",
|
|
144
|
+
"--",
|
|
145
|
+
*rels,
|
|
146
|
+
)
|
|
134
147
|
if r.returncode != 0:
|
|
135
148
|
if "nothing" in r.stdout + r.stderr:
|
|
136
149
|
return None
|
|
@@ -203,13 +216,21 @@ class UiApp:
|
|
|
203
216
|
source.update({k: ctx[k] for k in PLACE_FIELDS if ctx.get(k)})
|
|
204
217
|
name = slugify(p.get("name") or desc)
|
|
205
218
|
mid = new_id(name)
|
|
206
|
-
meta = {
|
|
207
|
-
|
|
219
|
+
meta = {
|
|
220
|
+
"id": mid,
|
|
221
|
+
"name": name,
|
|
222
|
+
"type": typ,
|
|
223
|
+
"scope": scope,
|
|
224
|
+
"description": desc,
|
|
225
|
+
"created": now_iso(),
|
|
226
|
+
"source": source,
|
|
227
|
+
}
|
|
208
228
|
path = self.mdir / id_path(mid)
|
|
209
229
|
|
|
210
230
|
def write():
|
|
211
231
|
atomic_write(path, frontmatter.join(meta, str(p.get("body", ""))))
|
|
212
232
|
return {"id": mid, "commit": self._commit(path, f"memory: add {mid} (ui)")}
|
|
233
|
+
|
|
213
234
|
return self._write(write)
|
|
214
235
|
|
|
215
236
|
def edit(self, p):
|
|
@@ -219,8 +240,11 @@ class UiApp:
|
|
|
219
240
|
if not changed:
|
|
220
241
|
return {"id": p.get("id"), "commit": None}
|
|
221
242
|
atomic_write(path, frontmatter.join(meta, new_body))
|
|
222
|
-
return {
|
|
223
|
-
|
|
243
|
+
return {
|
|
244
|
+
"id": p.get("id"),
|
|
245
|
+
"commit": self._commit(path, f"memory: edit {p.get('id')} ({', '.join(changed)}) (ui)"),
|
|
246
|
+
}
|
|
247
|
+
|
|
224
248
|
return self._write(write)
|
|
225
249
|
|
|
226
250
|
def delete(self, p):
|
|
@@ -237,8 +261,10 @@ class UiApp:
|
|
|
237
261
|
message = f"memory: delete {items[0].get('id')} (ui)\n\n{loaded[0][1].get('description', '')}"
|
|
238
262
|
else:
|
|
239
263
|
message = f"memory: delete {len(loaded)} memories (ui)\n\n" + "\n".join(
|
|
240
|
-
f"- {it.get('id')}: {meta.get('description', '')}" for it, (_, meta, _) in zip(items, loaded)
|
|
264
|
+
f"- {it.get('id')}: {meta.get('description', '')}" for it, (_, meta, _) in zip(items, loaded)
|
|
265
|
+
)
|
|
241
266
|
return {"commit": self._commit([path for path, _, _ in loaded], message)}
|
|
267
|
+
|
|
242
268
|
return self._write(write)
|
|
243
269
|
|
|
244
270
|
def undo(self, p):
|
|
@@ -254,11 +280,21 @@ class UiApp:
|
|
|
254
280
|
if r.returncode != 0:
|
|
255
281
|
gitsync.git(self.data, "revert", "--abort")
|
|
256
282
|
raise ApiError(409, "Could not undo: that memory changed again since. Edit it instead.")
|
|
257
|
-
gitsync.git(
|
|
258
|
-
|
|
283
|
+
gitsync.git(
|
|
284
|
+
self.data,
|
|
285
|
+
"-c",
|
|
286
|
+
"commit.gpgsign=false",
|
|
287
|
+
"commit",
|
|
288
|
+
"-q",
|
|
289
|
+
"--no-verify",
|
|
290
|
+
"-m",
|
|
291
|
+
f"memory: undo {rev} (ui)\n\nTool: ui",
|
|
292
|
+
timeout=10,
|
|
293
|
+
)
|
|
259
294
|
if gitsync.has_remote(self.data):
|
|
260
295
|
gitsync.spawn_sync(self.data, push=True)
|
|
261
296
|
return {"ok": True}
|
|
297
|
+
|
|
262
298
|
return self._write(write)
|
|
263
299
|
|
|
264
300
|
|
|
@@ -272,8 +308,13 @@ class Handler(BaseHTTPRequestHandler):
|
|
|
272
308
|
def _send(self, status, payload, ctype="application/json; charset=utf-8"):
|
|
273
309
|
body = payload if isinstance(payload, bytes) else json.dumps(payload, ensure_ascii=False).encode()
|
|
274
310
|
self.send_response(status)
|
|
275
|
-
for k, v in (
|
|
276
|
-
|
|
311
|
+
for k, v in (
|
|
312
|
+
("Content-Type", ctype),
|
|
313
|
+
("Content-Length", str(len(body))),
|
|
314
|
+
("Cache-Control", "no-store"),
|
|
315
|
+
("X-Content-Type-Options", "nosniff"),
|
|
316
|
+
("Referrer-Policy", "no-referrer"),
|
|
317
|
+
):
|
|
277
318
|
self.send_header(k, v)
|
|
278
319
|
if ctype.startswith("text/html"):
|
|
279
320
|
self.send_header("Content-Security-Policy", CSP)
|
|
@@ -316,8 +357,11 @@ class Handler(BaseHTTPRequestHandler):
|
|
|
316
357
|
return self._send(404, {"error": "not found"})
|
|
317
358
|
return self._send(200, path.read_bytes(), MIME[path.suffix])
|
|
318
359
|
app, q = self.server.app, {k: v[0] for k, v in parse_qs(url.query).items()}
|
|
319
|
-
routes = {
|
|
320
|
-
|
|
360
|
+
routes = {
|
|
361
|
+
"/api/state": app.current,
|
|
362
|
+
"/api/stamp": lambda: {"stamp": app.stamp()},
|
|
363
|
+
"/api/search": lambda: app.search(q.get("q")),
|
|
364
|
+
}
|
|
321
365
|
if url.path not in routes:
|
|
322
366
|
return self._send(404, {"error": "not found"})
|
|
323
367
|
self._run(routes[url.path])
|
|
@@ -353,8 +397,11 @@ def make_server(data_dir, port=8790, semantic=True):
|
|
|
353
397
|
|
|
354
398
|
def run(data_dir, port=8790, open_browser=True, semantic=True):
|
|
355
399
|
if semantic and not ui.model_ready():
|
|
356
|
-
print(
|
|
357
|
-
|
|
400
|
+
print(
|
|
401
|
+
"No local embedding model; similar memories use keywords only. "
|
|
402
|
+
"Run `mem ui --fetch-model` (about 625 MB) to also search by meaning.",
|
|
403
|
+
flush=True,
|
|
404
|
+
)
|
|
358
405
|
server = make_server(data_dir, port, semantic)
|
|
359
406
|
print(f"Memories: {server.url}", flush=True)
|
|
360
407
|
print("Keep this terminal open while you use it; Ctrl+C stops it.", flush=True)
|
|
@@ -15,13 +15,15 @@ from . import config
|
|
|
15
15
|
from .util import HOME, is_under
|
|
16
16
|
|
|
17
17
|
DEFAULT_THROWAWAY = [
|
|
18
|
-
r"/scratch-workspaces/",
|
|
19
|
-
r"^~/Documents/Codex/\d{4}-\d{2}-\d{2}/[^/]+",
|
|
18
|
+
r"/scratch-workspaces/", # Claude Code, no folder chosen
|
|
19
|
+
r"^~/Documents/Codex/\d{4}-\d{2}-\d{2}/[^/]+", # Codex desktop, one folder per thread
|
|
20
20
|
]
|
|
21
21
|
# Folders that only hold other folders; never the answer on their own.
|
|
22
|
-
CONTAINERS = re.compile(
|
|
23
|
-
|
|
24
|
-
|
|
22
|
+
CONTAINERS = re.compile(
|
|
23
|
+
r"^(Library/CloudStorage(/[^/]+)?|Library/Application Support|"
|
|
24
|
+
r"Library/Mobile Documents|Documents|Documents/Codex|"
|
|
25
|
+
r"Documents/Codex/\d{4}-\d{2}-\d{2}|Desktop|Downloads)$"
|
|
26
|
+
)
|
|
25
27
|
TAIL_BYTES = 8 * 1024 * 1024 # new memories are about recent work
|
|
26
28
|
MIN_HITS = 3
|
|
27
29
|
DESCEND_SHARE = 0.6
|
|
@@ -108,8 +110,9 @@ def infer(transcript, cwd=None, exclude=(), home=None):
|
|
|
108
110
|
def descend(n, best):
|
|
109
111
|
limit = MAX_DEPTH + (2 if best[0] == "Library" else 0) # ~/Library/CloudStorage/<drive>/...
|
|
110
112
|
while len(best) < limit and not home.joinpath(*best, ".git").exists():
|
|
111
|
-
kids = [
|
|
112
|
-
|
|
113
|
+
kids = [
|
|
114
|
+
(c, k) for k, c in counts.items() if len(k) == len(best) + 1 and k[: len(best)] == best and usable(k)
|
|
115
|
+
]
|
|
113
116
|
if not kids:
|
|
114
117
|
break
|
|
115
118
|
c, k = max(kids)
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|