abkit 0.1.0__tar.gz → 0.1.2__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- {abkit-0.1.0/src/abkit.egg-info → abkit-0.1.2}/PKG-INFO +31 -19
- {abkit-0.1.0 → abkit-0.1.2}/README.md +29 -17
- {abkit-0.1.0 → abkit-0.1.2}/pyproject.toml +2 -2
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/__init__.py +2 -2
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/cli.py +3 -1
- {abkit-0.1.0 → abkit-0.1.2/src/abkit.egg-info}/PKG-INFO +31 -19
- {abkit-0.1.0 → abkit-0.1.2}/LICENSE +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/setup.cfg +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/audit.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/bootstrap.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/demo.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/io.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/probes.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/py.typed +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/report.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/result.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/schema.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/stats.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit/synthetic.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit.egg-info/SOURCES.txt +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit.egg-info/dependency_links.txt +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit.egg-info/entry_points.txt +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit.egg-info/requires.txt +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/src/abkit.egg-info/top_level.txt +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/tests/test_bootstrap.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/tests/test_cli.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/tests/test_probes.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/tests/test_result.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/tests/test_schema.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/tests/test_stats.py +0 -0
- {abkit-0.1.0 → abkit-0.1.2}/tests/test_synthetic.py +0 -0
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: abkit
|
|
3
|
-
Version: 0.1.
|
|
4
|
-
Summary:
|
|
3
|
+
Version: 0.1.2
|
|
4
|
+
Summary: Sample-ratio, peeking, multiple-testing and winner's-curse checks for experiment readouts
|
|
5
5
|
Author: Hadi Mohammadi
|
|
6
6
|
License: MIT
|
|
7
7
|
Project-URL: Homepage, https://github.com/mohammadi-hadi/abkit
|
|
@@ -28,11 +28,19 @@ Requires-Dist: scipy>=1.12; extra == "dev"
|
|
|
28
28
|
Requires-Dist: statsmodels>=0.14; extra == "dev"
|
|
29
29
|
Dynamic: license-file
|
|
30
30
|
|
|
31
|
-
|
|
31
|
+
<div align="center">
|
|
32
32
|
|
|
33
|
-
|
|
33
|
+
# abkit
|
|
34
34
|
|
|
35
35
|
[](https://github.com/mohammadi-hadi/abkit/actions/workflows/ci.yml)
|
|
36
|
+
[](https://pypi.org/project/abkit/)
|
|
37
|
+
[](https://doi.org/10.5281/zenodo.21809478)
|
|
38
|
+
[](https://www.python.org/downloads/)
|
|
39
|
+
[](https://github.com/mohammadi-hadi/abkit/blob/main/LICENSE)
|
|
40
|
+
|
|
41
|
+
*Sample-ratio, peeking, multiple-testing and winner's-curse checks for experiment readouts.*
|
|
42
|
+
|
|
43
|
+
</div>
|
|
36
44
|
|
|
37
45
|
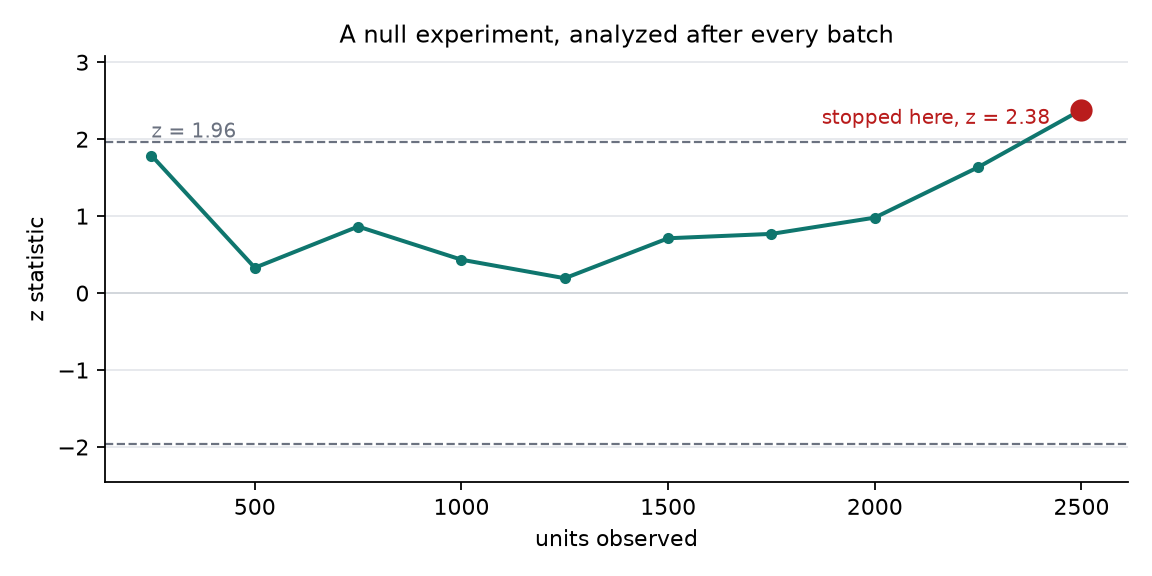
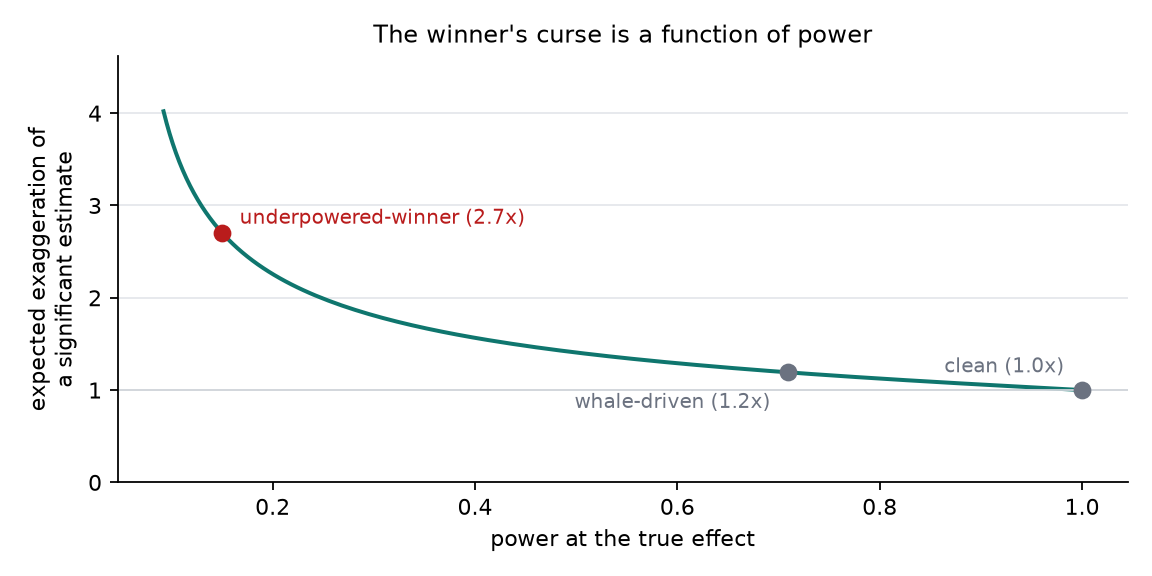
An experiment readout can say "B wins, p = 0.03, ship it" while the traffic
|
|
38
46
|
split was broken, three whale customers carried the whole effect, the analyst
|
|
@@ -67,22 +75,22 @@ is indistinguishable from a real win — p < 0.05, decent sample size — but th
|
|
|
67
75
|
schedule it followed has a 19% false-positive rate, not 5%. The audit flags
|
|
68
76
|
the process, which is the only place that defect lives.
|
|
69
77
|
|
|
70
|
-

|
|
78
|
+
|
|
71
79
|
|
|
72
|
-

|
|
80
|
+
|
|
73
81
|
|
|
74
|
-
`make demo` regenerates the table, the [full report](results/report.md) and
|
|
82
|
+
`make demo` regenerates the table, the [full report](https://github.com/mohammadi-hadi/abkit/blob/main/results/report.md) and
|
|
75
83
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
76
84
|
fails if a committed number differs from what the code produces.
|
|
77
85
|
|
|
78
86
|
## 4,873 real experiments, audited
|
|
79
87
|
|
|
80
|
-
[`examples/upworthy/`](examples/upworthy/) runs abkit's aggregate checks over
|
|
88
|
+
[`examples/upworthy/`](https://github.com/mohammadi-hadi/abkit/tree/main/examples/upworthy/) runs abkit's aggregate checks over
|
|
81
89
|
the exploratory split of the [Upworthy Research Archive](https://doi.org/10.1038/s41597-021-00934-7)
|
|
82
90
|
— 4,873 real headline A/B tests from 2013–2015. Committed results:
|
|
83
|
-
[examples/upworthy/results/upworthy.md](examples/upworthy/results/upworthy.md).
|
|
91
|
+
[examples/upworthy/results/upworthy.md](https://github.com/mohammadi-hadi/abkit/blob/main/examples/upworthy/results/upworthy.md).
|
|
84
92
|
|
|
85
|
-
- **
|
|
93
|
+
- **15% of real tests fail the sample-ratio check** at p < 0.001 against the
|
|
86
94
|
platform's equal-allocation design — and not because packages were added
|
|
87
95
|
mid-test; the rate is, if anything, higher in tests whose variants all
|
|
88
96
|
launched together. Those readouts carried unknown exposure bias.
|
|
@@ -96,7 +104,7 @@ the exploratory split of the [Upworthy Research Archive](https://doi.org/10.1038
|
|
|
96
104
|
## Install
|
|
97
105
|
|
|
98
106
|
```
|
|
99
|
-
pip install
|
|
107
|
+
pip install abkit
|
|
100
108
|
```
|
|
101
109
|
|
|
102
110
|
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib.
|
|
@@ -184,7 +192,7 @@ experiment.
|
|
|
184
192
|
±0.10 — and flag only when the whole 95% bootstrap CI leaves it. Exact
|
|
185
193
|
procedures use the field's conventional thresholds: SRM at p < 0.001,
|
|
186
194
|
contamination at zero tolerance. All constants live in one place
|
|
187
|
-
([`probes.py`](src/abkit/probes.py)) and are easy to disagree with.
|
|
195
|
+
([`probes.py`](https://github.com/mohammadi-hadi/abkit/blob/main/src/abkit/probes.py)) and are easy to disagree with.
|
|
188
196
|
- **The stopping rule is audited, not the final p.** A peeked experiment's
|
|
189
197
|
final test statistic looks ordinary; what is broken is the procedure that
|
|
190
198
|
produced it. The peeking probe Monte-Carlos the analyst's actual look
|
|
@@ -237,22 +245,26 @@ The real-data case study uses the Upworthy Research Archive
|
|
|
237
245
|
abkit's contribution is packaging the checks as one auditable tool with
|
|
238
246
|
uncertainty on every number and validation by implantation.
|
|
239
247
|
|
|
240
|
-
|
|
241
|
-
|
|
242
|
-
[
|
|
243
|
-
measures what
|
|
248
|
+
## Part of evalstack
|
|
249
|
+
|
|
250
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
251
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
252
|
+
and the two chains that run end to end.
|
|
244
253
|
|
|
245
254
|
## Citation
|
|
246
255
|
|
|
247
|
-
|
|
248
|
-
[
|
|
256
|
+
Releases are archived on Zenodo. Cite the concept DOI
|
|
257
|
+
[10.5281/zenodo.21809478](https://doi.org/10.5281/zenodo.21809478), which always
|
|
258
|
+
resolves to the latest version; structured metadata is in
|
|
259
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/abkit/blob/main/CITATION.cff).
|
|
249
260
|
|
|
250
261
|
```bibtex
|
|
251
262
|
@software{mohammadi_abkit,
|
|
252
263
|
author = {Mohammadi, Hadi},
|
|
253
264
|
title = {abkit: audit an A/B-test readout before you ship the decision},
|
|
254
265
|
url = {https://github.com/mohammadi-hadi/abkit},
|
|
255
|
-
|
|
266
|
+
doi = {10.5281/zenodo.21809478},
|
|
267
|
+
version = {0.1.2},
|
|
256
268
|
year = {2026}
|
|
257
269
|
}
|
|
258
270
|
```
|
|
@@ -1,8 +1,16 @@
|
|
|
1
|
-
|
|
1
|
+
<div align="center">
|
|
2
2
|
|
|
3
|
-
|
|
3
|
+
# abkit
|
|
4
4
|
|
|
5
5
|
[](https://github.com/mohammadi-hadi/abkit/actions/workflows/ci.yml)
|
|
6
|
+
[](https://pypi.org/project/abkit/)
|
|
7
|
+
[](https://doi.org/10.5281/zenodo.21809478)
|
|
8
|
+
[](https://www.python.org/downloads/)
|
|
9
|
+
[](https://github.com/mohammadi-hadi/abkit/blob/main/LICENSE)
|
|
10
|
+
|
|
11
|
+
*Sample-ratio, peeking, multiple-testing and winner's-curse checks for experiment readouts.*
|
|
12
|
+
|
|
13
|
+
</div>
|
|
6
14
|
|
|
7
15
|
An experiment readout can say "B wins, p = 0.03, ship it" while the traffic
|
|
8
16
|
split was broken, three whale customers carried the whole effect, the analyst
|
|
@@ -37,22 +45,22 @@ is indistinguishable from a real win — p < 0.05, decent sample size — but th
|
|
|
37
45
|
schedule it followed has a 19% false-positive rate, not 5%. The audit flags
|
|
38
46
|
the process, which is the only place that defect lives.
|
|
39
47
|
|
|
40
|
-

|
|
48
|
+

|
|
41
49
|
|
|
42
|
-

|
|
50
|
+

|
|
43
51
|
|
|
44
|
-
`make demo` regenerates the table, the [full report](results/report.md) and
|
|
52
|
+
`make demo` regenerates the table, the [full report](https://github.com/mohammadi-hadi/abkit/blob/main/results/report.md) and
|
|
45
53
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
46
54
|
fails if a committed number differs from what the code produces.
|
|
47
55
|
|
|
48
56
|
## 4,873 real experiments, audited
|
|
49
57
|
|
|
50
|
-
[`examples/upworthy/`](examples/upworthy/) runs abkit's aggregate checks over
|
|
58
|
+
[`examples/upworthy/`](https://github.com/mohammadi-hadi/abkit/tree/main/examples/upworthy/) runs abkit's aggregate checks over
|
|
51
59
|
the exploratory split of the [Upworthy Research Archive](https://doi.org/10.1038/s41597-021-00934-7)
|
|
52
60
|
— 4,873 real headline A/B tests from 2013–2015. Committed results:
|
|
53
|
-
[examples/upworthy/results/upworthy.md](examples/upworthy/results/upworthy.md).
|
|
61
|
+
[examples/upworthy/results/upworthy.md](https://github.com/mohammadi-hadi/abkit/blob/main/examples/upworthy/results/upworthy.md).
|
|
54
62
|
|
|
55
|
-
- **
|
|
63
|
+
- **15% of real tests fail the sample-ratio check** at p < 0.001 against the
|
|
56
64
|
platform's equal-allocation design — and not because packages were added
|
|
57
65
|
mid-test; the rate is, if anything, higher in tests whose variants all
|
|
58
66
|
launched together. Those readouts carried unknown exposure bias.
|
|
@@ -66,7 +74,7 @@ the exploratory split of the [Upworthy Research Archive](https://doi.org/10.1038
|
|
|
66
74
|
## Install
|
|
67
75
|
|
|
68
76
|
```
|
|
69
|
-
pip install
|
|
77
|
+
pip install abkit
|
|
70
78
|
```
|
|
71
79
|
|
|
72
80
|
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib.
|
|
@@ -154,7 +162,7 @@ experiment.
|
|
|
154
162
|
±0.10 — and flag only when the whole 95% bootstrap CI leaves it. Exact
|
|
155
163
|
procedures use the field's conventional thresholds: SRM at p < 0.001,
|
|
156
164
|
contamination at zero tolerance. All constants live in one place
|
|
157
|
-
([`probes.py`](src/abkit/probes.py)) and are easy to disagree with.
|
|
165
|
+
([`probes.py`](https://github.com/mohammadi-hadi/abkit/blob/main/src/abkit/probes.py)) and are easy to disagree with.
|
|
158
166
|
- **The stopping rule is audited, not the final p.** A peeked experiment's
|
|
159
167
|
final test statistic looks ordinary; what is broken is the procedure that
|
|
160
168
|
produced it. The peeking probe Monte-Carlos the analyst's actual look
|
|
@@ -207,22 +215,26 @@ The real-data case study uses the Upworthy Research Archive
|
|
|
207
215
|
abkit's contribution is packaging the checks as one auditable tool with
|
|
208
216
|
uncertainty on every number and validation by implantation.
|
|
209
217
|
|
|
210
|
-
|
|
211
|
-
|
|
212
|
-
[
|
|
213
|
-
measures what
|
|
218
|
+
## Part of evalstack
|
|
219
|
+
|
|
220
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
221
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
222
|
+
and the two chains that run end to end.
|
|
214
223
|
|
|
215
224
|
## Citation
|
|
216
225
|
|
|
217
|
-
|
|
218
|
-
[
|
|
226
|
+
Releases are archived on Zenodo. Cite the concept DOI
|
|
227
|
+
[10.5281/zenodo.21809478](https://doi.org/10.5281/zenodo.21809478), which always
|
|
228
|
+
resolves to the latest version; structured metadata is in
|
|
229
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/abkit/blob/main/CITATION.cff).
|
|
219
230
|
|
|
220
231
|
```bibtex
|
|
221
232
|
@software{mohammadi_abkit,
|
|
222
233
|
author = {Mohammadi, Hadi},
|
|
223
234
|
title = {abkit: audit an A/B-test readout before you ship the decision},
|
|
224
235
|
url = {https://github.com/mohammadi-hadi/abkit},
|
|
225
|
-
|
|
236
|
+
doi = {10.5281/zenodo.21809478},
|
|
237
|
+
version = {0.1.2},
|
|
226
238
|
year = {2026}
|
|
227
239
|
}
|
|
228
240
|
```
|
|
@@ -4,8 +4,8 @@ build-backend = "setuptools.build_meta"
|
|
|
4
4
|
|
|
5
5
|
[project]
|
|
6
6
|
name = "abkit"
|
|
7
|
-
version = "0.1.
|
|
8
|
-
description = "
|
|
7
|
+
version = "0.1.2"
|
|
8
|
+
description = "Sample-ratio, peeking, multiple-testing and winner's-curse checks for experiment readouts"
|
|
9
9
|
readme = "README.md"
|
|
10
10
|
license = {text = "MIT"}
|
|
11
11
|
authors = [{name = "Hadi Mohammadi"}]
|
|
@@ -1,11 +1,11 @@
|
|
|
1
|
-
"""abkit:
|
|
1
|
+
"""abkit: sample-ratio, peeking, multiple-testing and winner's-curse checks."""
|
|
2
2
|
|
|
3
3
|
from .audit import run_audit
|
|
4
4
|
from .io import dump_design, dump_units, load_design, load_units
|
|
5
5
|
from .result import AuditResult, ProbeResult, SkippedProbe
|
|
6
6
|
from .schema import Design, Look, Unit
|
|
7
7
|
|
|
8
|
-
__version__ = "0.1.
|
|
8
|
+
__version__ = "0.1.2"
|
|
9
9
|
|
|
10
10
|
__all__ = [
|
|
11
11
|
"AuditResult",
|
|
@@ -14,7 +14,9 @@ from .report import inject_readme, write_report
|
|
|
14
14
|
|
|
15
15
|
def main(argv: list[str] | None = None) -> int:
|
|
16
16
|
parser = argparse.ArgumentParser(
|
|
17
|
-
prog="abkit",
|
|
17
|
+
prog="abkit",
|
|
18
|
+
description="Sample-ratio, peeking, multiple-testing and winner's-curse checks "
|
|
19
|
+
"for experiment readouts.",
|
|
18
20
|
)
|
|
19
21
|
parser.add_argument("--version", action="version", version=f"abkit {__version__}")
|
|
20
22
|
sub = parser.add_subparsers(dest="command", required=True)
|
|
@@ -1,7 +1,7 @@
|
|
|
1
1
|
Metadata-Version: 2.4
|
|
2
2
|
Name: abkit
|
|
3
|
-
Version: 0.1.
|
|
4
|
-
Summary:
|
|
3
|
+
Version: 0.1.2
|
|
4
|
+
Summary: Sample-ratio, peeking, multiple-testing and winner's-curse checks for experiment readouts
|
|
5
5
|
Author: Hadi Mohammadi
|
|
6
6
|
License: MIT
|
|
7
7
|
Project-URL: Homepage, https://github.com/mohammadi-hadi/abkit
|
|
@@ -28,11 +28,19 @@ Requires-Dist: scipy>=1.12; extra == "dev"
|
|
|
28
28
|
Requires-Dist: statsmodels>=0.14; extra == "dev"
|
|
29
29
|
Dynamic: license-file
|
|
30
30
|
|
|
31
|
-
|
|
31
|
+
<div align="center">
|
|
32
32
|
|
|
33
|
-
|
|
33
|
+
# abkit
|
|
34
34
|
|
|
35
35
|
[](https://github.com/mohammadi-hadi/abkit/actions/workflows/ci.yml)
|
|
36
|
+
[](https://pypi.org/project/abkit/)
|
|
37
|
+
[](https://doi.org/10.5281/zenodo.21809478)
|
|
38
|
+
[](https://www.python.org/downloads/)
|
|
39
|
+
[](https://github.com/mohammadi-hadi/abkit/blob/main/LICENSE)
|
|
40
|
+
|
|
41
|
+
*Sample-ratio, peeking, multiple-testing and winner's-curse checks for experiment readouts.*
|
|
42
|
+
|
|
43
|
+
</div>
|
|
36
44
|
|
|
37
45
|
An experiment readout can say "B wins, p = 0.03, ship it" while the traffic
|
|
38
46
|
split was broken, three whale customers carried the whole effect, the analyst
|
|
@@ -67,22 +75,22 @@ is indistinguishable from a real win — p < 0.05, decent sample size — but th
|
|
|
67
75
|
schedule it followed has a 19% false-positive rate, not 5%. The audit flags
|
|
68
76
|
the process, which is the only place that defect lives.
|
|
69
77
|
|
|
70
|
-

|
|
78
|
+

|
|
71
79
|
|
|
72
|
-

|
|
80
|
+

|
|
73
81
|
|
|
74
|
-
`make demo` regenerates the table, the [full report](results/report.md) and
|
|
82
|
+
`make demo` regenerates the table, the [full report](https://github.com/mohammadi-hadi/abkit/blob/main/results/report.md) and
|
|
75
83
|
the figures from fixed seeds; CI rebuilds them from pinned dependencies and
|
|
76
84
|
fails if a committed number differs from what the code produces.
|
|
77
85
|
|
|
78
86
|
## 4,873 real experiments, audited
|
|
79
87
|
|
|
80
|
-
[`examples/upworthy/`](examples/upworthy/) runs abkit's aggregate checks over
|
|
88
|
+
[`examples/upworthy/`](https://github.com/mohammadi-hadi/abkit/tree/main/examples/upworthy/) runs abkit's aggregate checks over
|
|
81
89
|
the exploratory split of the [Upworthy Research Archive](https://doi.org/10.1038/s41597-021-00934-7)
|
|
82
90
|
— 4,873 real headline A/B tests from 2013–2015. Committed results:
|
|
83
|
-
[examples/upworthy/results/upworthy.md](examples/upworthy/results/upworthy.md).
|
|
91
|
+
[examples/upworthy/results/upworthy.md](https://github.com/mohammadi-hadi/abkit/blob/main/examples/upworthy/results/upworthy.md).
|
|
84
92
|
|
|
85
|
-
- **
|
|
93
|
+
- **15% of real tests fail the sample-ratio check** at p < 0.001 against the
|
|
86
94
|
platform's equal-allocation design — and not because packages were added
|
|
87
95
|
mid-test; the rate is, if anything, higher in tests whose variants all
|
|
88
96
|
launched together. Those readouts carried unknown exposure bias.
|
|
@@ -96,7 +104,7 @@ the exploratory split of the [Upworthy Research Archive](https://doi.org/10.1038
|
|
|
96
104
|
## Install
|
|
97
105
|
|
|
98
106
|
```
|
|
99
|
-
pip install
|
|
107
|
+
pip install abkit
|
|
100
108
|
```
|
|
101
109
|
|
|
102
110
|
Python 3.11+. Runtime dependencies: numpy, pydantic, matplotlib.
|
|
@@ -184,7 +192,7 @@ experiment.
|
|
|
184
192
|
±0.10 — and flag only when the whole 95% bootstrap CI leaves it. Exact
|
|
185
193
|
procedures use the field's conventional thresholds: SRM at p < 0.001,
|
|
186
194
|
contamination at zero tolerance. All constants live in one place
|
|
187
|
-
([`probes.py`](src/abkit/probes.py)) and are easy to disagree with.
|
|
195
|
+
([`probes.py`](https://github.com/mohammadi-hadi/abkit/blob/main/src/abkit/probes.py)) and are easy to disagree with.
|
|
188
196
|
- **The stopping rule is audited, not the final p.** A peeked experiment's
|
|
189
197
|
final test statistic looks ordinary; what is broken is the procedure that
|
|
190
198
|
produced it. The peeking probe Monte-Carlos the analyst's actual look
|
|
@@ -237,22 +245,26 @@ The real-data case study uses the Upworthy Research Archive
|
|
|
237
245
|
abkit's contribution is packaging the checks as one auditable tool with
|
|
238
246
|
uncertainty on every number and validation by implantation.
|
|
239
247
|
|
|
240
|
-
|
|
241
|
-
|
|
242
|
-
[
|
|
243
|
-
measures what
|
|
248
|
+
## Part of evalstack
|
|
249
|
+
|
|
250
|
+
[evalstack](https://github.com/mohammadi-hadi/evalstack) is the map of these
|
|
251
|
+
eleven evaluation tools: what each one measures, what it found on real data,
|
|
252
|
+
and the two chains that run end to end.
|
|
244
253
|
|
|
245
254
|
## Citation
|
|
246
255
|
|
|
247
|
-
|
|
248
|
-
[
|
|
256
|
+
Releases are archived on Zenodo. Cite the concept DOI
|
|
257
|
+
[10.5281/zenodo.21809478](https://doi.org/10.5281/zenodo.21809478), which always
|
|
258
|
+
resolves to the latest version; structured metadata is in
|
|
259
|
+
[CITATION.cff](https://github.com/mohammadi-hadi/abkit/blob/main/CITATION.cff).
|
|
249
260
|
|
|
250
261
|
```bibtex
|
|
251
262
|
@software{mohammadi_abkit,
|
|
252
263
|
author = {Mohammadi, Hadi},
|
|
253
264
|
title = {abkit: audit an A/B-test readout before you ship the decision},
|
|
254
265
|
url = {https://github.com/mohammadi-hadi/abkit},
|
|
255
|
-
|
|
266
|
+
doi = {10.5281/zenodo.21809478},
|
|
267
|
+
version = {0.1.2},
|
|
256
268
|
year = {2026}
|
|
257
269
|
}
|
|
258
270
|
```
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|
|
File without changes
|