abcopt 0.2.0__tar.gz
This diff represents the content of publicly available package versions that have been released to one of the supported registries. The information contained in this diff is provided for informational purposes only and reflects changes between package versions as they appear in their respective public registries.
- abcopt-0.2.0/LICENSE +21 -0
- abcopt-0.2.0/PKG-INFO +264 -0
- abcopt-0.2.0/README.md +242 -0
- abcopt-0.2.0/abcopt/__init__.py +7 -0
- abcopt-0.2.0/abcopt/core.py +182 -0
- abcopt-0.2.0/abcopt/sklearn_wrapper.py +211 -0
- abcopt-0.2.0/abcopt.egg-info/PKG-INFO +264 -0
- abcopt-0.2.0/abcopt.egg-info/SOURCES.txt +13 -0
- abcopt-0.2.0/abcopt.egg-info/dependency_links.txt +1 -0
- abcopt-0.2.0/abcopt.egg-info/requires.txt +5 -0
- abcopt-0.2.0/abcopt.egg-info/top_level.txt +1 -0
- abcopt-0.2.0/pyproject.toml +35 -0
- abcopt-0.2.0/setup.cfg +4 -0
- abcopt-0.2.0/tests/test_core.py +109 -0
- abcopt-0.2.0/tests/test_sklearn_wrapper.py +127 -0
abcopt-0.2.0/LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
1
|
+
MIT License
|
|
2
|
+
|
|
3
|
+
Copyright (c) 2026 Yusuf Korkmazyiğit
|
|
4
|
+
|
|
5
|
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
|
6
|
+
of this software and associated documentation files (the "Software"), to deal
|
|
7
|
+
in the Software without restriction, including without limitation the rights
|
|
8
|
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
|
9
|
+
copies of the Software, and to permit persons to whom the Software is
|
|
10
|
+
furnished to do so, subject to the following conditions:
|
|
11
|
+
|
|
12
|
+
The above copyright notice and this permission notice shall be included in all
|
|
13
|
+
copies or substantial portions of the Software.
|
|
14
|
+
|
|
15
|
+
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
|
16
|
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
|
17
|
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
|
18
|
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
|
19
|
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
|
20
|
+
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
|
21
|
+
SOFTWARE.
|
abcopt-0.2.0/PKG-INFO
ADDED
|
@@ -0,0 +1,264 @@
|
|
|
1
|
+
Metadata-Version: 2.4
|
|
2
|
+
Name: abcopt
|
|
3
|
+
Version: 0.2.0
|
|
4
|
+
Summary: Canonical Artificial Bee Colony (ABC) optimization with a scikit-learn compatible hyperparameter search
|
|
5
|
+
Author-email: Yusuf Korkmazyiğit <yusuf.korkmazyigit@gmail.com>
|
|
6
|
+
License-Expression: MIT
|
|
7
|
+
Project-URL: Homepage, https://github.com/yusufkorkmazyigit/abc-optimizer-lib
|
|
8
|
+
Project-URL: Issues, https://github.com/yusufkorkmazyigit/abc-optimizer-lib/issues
|
|
9
|
+
Keywords: artificial bee colony,swarm intelligence,metaheuristics,hyperparameter optimization,scikit-learn
|
|
10
|
+
Classifier: Programming Language :: Python :: 3
|
|
11
|
+
Classifier: Operating System :: OS Independent
|
|
12
|
+
Classifier: Intended Audience :: Science/Research
|
|
13
|
+
Classifier: Topic :: Scientific/Engineering :: Artificial Intelligence
|
|
14
|
+
Requires-Python: >=3.9
|
|
15
|
+
Description-Content-Type: text/markdown
|
|
16
|
+
License-File: LICENSE
|
|
17
|
+
Requires-Dist: numpy>=1.21
|
|
18
|
+
Requires-Dist: scikit-learn>=1.0
|
|
19
|
+
Provides-Extra: test
|
|
20
|
+
Requires-Dist: pytest>=7; extra == "test"
|
|
21
|
+
Dynamic: license-file
|
|
22
|
+
|
|
23
|
+
# 🐝 abcopt
|
|
24
|
+
|
|
25
|
+
**Canonical Artificial Bee Colony (ABC) optimization in pure Python, with a scikit-learn compatible hyperparameter search.**
|
|
26
|
+
|
|
27
|
+
[](https://pypi.org/project/abcopt/)
|
|
28
|
+
[](https://github.com/yusufkorkmazyigit/abc-optimizer-lib/actions/workflows/tests.yml)
|
|
29
|
+

|
|
30
|
+

|
|
31
|
+

|
|
32
|
+
|
|
33
|
+
|
|
34
|
+
**abcopt** is a faithful implementation of the **Artificial Bee Colony** algorithm proposed by **Derviş Karaboğa (2005)** at Erciyes University. It is useful for two things:
|
|
35
|
+
|
|
36
|
+
1. **Black-box optimization:** minimize any objective function within box constraints, with no gradients required.
|
|
37
|
+
2. **Hyperparameter tuning:** a drop-in alternative to `GridSearchCV` / `RandomizedSearchCV` for any scikit-learn compatible estimator (scikit-learn, LightGBM, XGBoost, …).
|
|
38
|
+
|
|
39
|
+
---
|
|
40
|
+
|
|
41
|
+
## ✨ Features
|
|
42
|
+
|
|
43
|
+
- **Canonical algorithm:** employed, onlooker (roulette-wheel selection) and scout bee phases, following the original paper; one dimension is perturbed per move.
|
|
44
|
+
- **scikit-learn API:** `ABCSearchCV` exposes `fit`, `predict`, `score`, `best_params_`, `best_score_` and `best_estimator_`.
|
|
45
|
+
- **Mixed search spaces:** `float` (optionally log-scaled), `int` and `categorical` hyperparameters.
|
|
46
|
+
- **Reproducible:** pass `random_state` and every run is identical.
|
|
47
|
+
- **Evaluation budget:** you set `max_evals`, so the run cost is predictable.
|
|
48
|
+
- **Robust:** failing candidates raise a warning instead of being hidden (or stop the search with `error_score="raise"`), and invalid inputs fail fast with clear messages.
|
|
49
|
+
- **Convergence history:** every run returns its best-so-far curve for plotting and comparison.
|
|
50
|
+
- **Tested:** 30 unit tests run on every push via GitHub Actions.
|
|
51
|
+
- **Lightweight:** depends only on `numpy` and `scikit-learn`.
|
|
52
|
+
|
|
53
|
+
---
|
|
54
|
+
|
|
55
|
+
## 📦 Installation
|
|
56
|
+
|
|
57
|
+
```bash
|
|
58
|
+
pip install abcopt
|
|
59
|
+
```
|
|
60
|
+
|
|
61
|
+
```python
|
|
62
|
+
from abcopt import ABCSearchCV, CanonicalABCSolver
|
|
63
|
+
```
|
|
64
|
+
|
|
65
|
+
For development:
|
|
66
|
+
|
|
67
|
+
```bash
|
|
68
|
+
git clone https://github.com/yusufkorkmazyigit/abc-optimizer-lib.git
|
|
69
|
+
cd abc-optimizer-lib
|
|
70
|
+
pip install -e ".[test]"
|
|
71
|
+
```
|
|
72
|
+
|
|
73
|
+
---
|
|
74
|
+
|
|
75
|
+
## 🚀 Quick Start
|
|
76
|
+
|
|
77
|
+
### 1. Hyperparameter tuning with `ABCSearchCV`
|
|
78
|
+
|
|
79
|
+
```python
|
|
80
|
+
import lightgbm as lgb
|
|
81
|
+
from sklearn.datasets import load_breast_cancer
|
|
82
|
+
from abcopt import ABCSearchCV
|
|
83
|
+
|
|
84
|
+
X, y = load_breast_cancer(return_X_y=True)
|
|
85
|
+
|
|
86
|
+
param_space = {
|
|
87
|
+
"learning_rate": {"type": "float", "range": (0.01, 0.3), "log": True},
|
|
88
|
+
"n_estimators": {"type": "int", "range": (50, 500)},
|
|
89
|
+
"num_leaves": {"type": "int", "range": (20, 100)},
|
|
90
|
+
"boosting_type": {"type": "categorical", "choices": ["gbdt", "dart"]},
|
|
91
|
+
}
|
|
92
|
+
|
|
93
|
+
search = ABCSearchCV(
|
|
94
|
+
estimator=lgb.LGBMClassifier(verbosity=-1),
|
|
95
|
+
param_space=param_space,
|
|
96
|
+
cv=3,
|
|
97
|
+
scoring="accuracy",
|
|
98
|
+
pop_size=20, # number of food sources
|
|
99
|
+
max_evals=100, # total objective evaluations (each one = one CV run)
|
|
100
|
+
random_state=42, # reproducible search
|
|
101
|
+
)
|
|
102
|
+
search.fit(X, y)
|
|
103
|
+
|
|
104
|
+
print("Best CV score:", search.best_score_)
|
|
105
|
+
print("Best params: ", search.best_params_)
|
|
106
|
+
y_pred = search.predict(X) # uses best_estimator_, refit on the full data
|
|
107
|
+
```
|
|
108
|
+
|
|
109
|
+
### 2. Function minimization with `CanonicalABCSolver`
|
|
110
|
+
|
|
111
|
+
```python
|
|
112
|
+
import numpy as np
|
|
113
|
+
from abcopt import CanonicalABCSolver
|
|
114
|
+
|
|
115
|
+
def sphere(x):
|
|
116
|
+
return np.sum(x ** 2) # global minimum: 0 at x = 0
|
|
117
|
+
|
|
118
|
+
solver = CanonicalABCSolver(
|
|
119
|
+
objective_func=sphere,
|
|
120
|
+
n_params=3,
|
|
121
|
+
lb=[-10, -10, -10],
|
|
122
|
+
ub=[10, 10, 10],
|
|
123
|
+
max_evals=2000,
|
|
124
|
+
random_state=0,
|
|
125
|
+
)
|
|
126
|
+
best_x, best_cost, history = solver.solve()
|
|
127
|
+
print(f"x* = {best_x}, f(x*) = {best_cost:.5f}")
|
|
128
|
+
```
|
|
129
|
+
|
|
130
|
+
### 3. Plotting convergence
|
|
131
|
+
|
|
132
|
+
```python
|
|
133
|
+
import matplotlib.pyplot as plt
|
|
134
|
+
|
|
135
|
+
evals, costs = zip(*history) # solver: best cost so far
|
|
136
|
+
# evals, scores = zip(*search.history_) # ABCSearchCV: best CV score so far
|
|
137
|
+
plt.plot(evals, costs)
|
|
138
|
+
plt.xlabel("Function evaluations")
|
|
139
|
+
plt.ylabel("Best cost")
|
|
140
|
+
plt.title("ABC convergence")
|
|
141
|
+
plt.show()
|
|
142
|
+
```
|
|
143
|
+
|
|
144
|
+
---
|
|
145
|
+
|
|
146
|
+
## 📖 API Reference
|
|
147
|
+
|
|
148
|
+
### `CanonicalABCSolver`
|
|
149
|
+
|
|
150
|
+
```python
|
|
151
|
+
CanonicalABCSolver(objective_func, n_params, lb, ub,
|
|
152
|
+
pop_size=20, max_evals=1000, limit=None, random_state=None)
|
|
153
|
+
```
|
|
154
|
+
|
|
155
|
+
| Parameter | Description |
|
|
156
|
+
|---|---|
|
|
157
|
+
| `objective_func` | Callable taking a 1-D `np.ndarray` and returning a scalar cost to **minimize** |
|
|
158
|
+
| `n_params` | Number of dimensions |
|
|
159
|
+
| `lb`, `ub` | Lower / upper bounds per dimension |
|
|
160
|
+
| `pop_size` | Number of food sources (SN) |
|
|
161
|
+
| `max_evals` | Total objective-function evaluation budget |
|
|
162
|
+
| `limit` | Trials without improvement before a source is abandoned (default: `pop_size × n_params`) |
|
|
163
|
+
| `random_state` | Seed (or `np.random.Generator`) for reproducible runs |
|
|
164
|
+
|
|
165
|
+
`NaN` objective values are treated as the worst possible cost.
|
|
166
|
+
|
|
167
|
+
`solve()` returns `(best_params, best_cost, history)`, where `history` is a list of `(eval_count, best_cost)` tuples.
|
|
168
|
+
|
|
169
|
+
### `ABCSearchCV`
|
|
170
|
+
|
|
171
|
+
```python
|
|
172
|
+
ABCSearchCV(estimator, param_space, cv=3, scoring="accuracy",
|
|
173
|
+
pop_size=20, max_evals=200, limit=None, random_state=None,
|
|
174
|
+
n_jobs=None, error_score=np.nan, refit=True, verbose=False)
|
|
175
|
+
```
|
|
176
|
+
|
|
177
|
+
**`param_space`**: one entry per hyperparameter:
|
|
178
|
+
|
|
179
|
+
| Spec | Example |
|
|
180
|
+
|---|---|
|
|
181
|
+
| Continuous | `{"type": "float", "range": (0.01, 0.3)}` |
|
|
182
|
+
| Continuous, log scale | `{"type": "float", "range": (1e-4, 1e-1), "log": True}` |
|
|
183
|
+
| Integer (both ends inclusive) | `{"type": "int", "range": (2, 12)}` |
|
|
184
|
+
| Categorical | `{"type": "categorical", "choices": ["gini", "entropy"]}` |
|
|
185
|
+
|
|
186
|
+
- **`scoring`**: any scikit-learn scorer; higher is better, exactly like `GridSearchCV` (use `neg_*` scorers for errors).
|
|
187
|
+
- **`error_score`**: score given to candidates that fail to fit (a `RuntimeWarning` is issued); `"raise"` stops the search instead.
|
|
188
|
+
- **`n_jobs`**: parallel jobs inside each cross-validation.
|
|
189
|
+
- **After `fit`:** `best_params_`, `best_score_`, `best_estimator_` (when `refit=True`), `history_`, `results_` (every candidate with its score), `n_evals_`.
|
|
190
|
+
- **Methods:** `predict`, `predict_proba`, `score`.
|
|
191
|
+
|
|
192
|
+
---
|
|
193
|
+
|
|
194
|
+
## 🧠 How ABC Works
|
|
195
|
+
|
|
196
|
+
ABC models the foraging behaviour of a honey bee colony. Each **food source** is a candidate solution, and its **nectar amount** is the solution's fitness.
|
|
197
|
+
|
|
198
|
+
| Phase | Role |
|
|
199
|
+
|---|---|
|
|
200
|
+
| **Employed bees** | Each one improves its own food source by perturbing one dimension towards or away from a random neighbour: `v_ij = x_ij + φ·(x_ij − x_kj)`, `φ ∈ [−1, 1]`. Greedy selection keeps the better solution. |
|
|
201
|
+
| **Onlooker bees** | Pick sources with probability proportional to fitness (roulette wheel), so promising regions are exploited more. |
|
|
202
|
+
| **Scout bees** | A source that has not improved for `limit` trials is abandoned and replaced by a random one, which keeps exploration alive. |
|
|
203
|
+
|
|
204
|
+
Fitness is derived from cost as `1 / (1 + f)` for `f ≥ 0` and `1 + |f|` otherwise.
|
|
205
|
+
|
|
206
|
+
---
|
|
207
|
+
|
|
208
|
+
## 🔬 Case Study: Federated Learning on MedMNIST
|
|
209
|
+
|
|
210
|
+
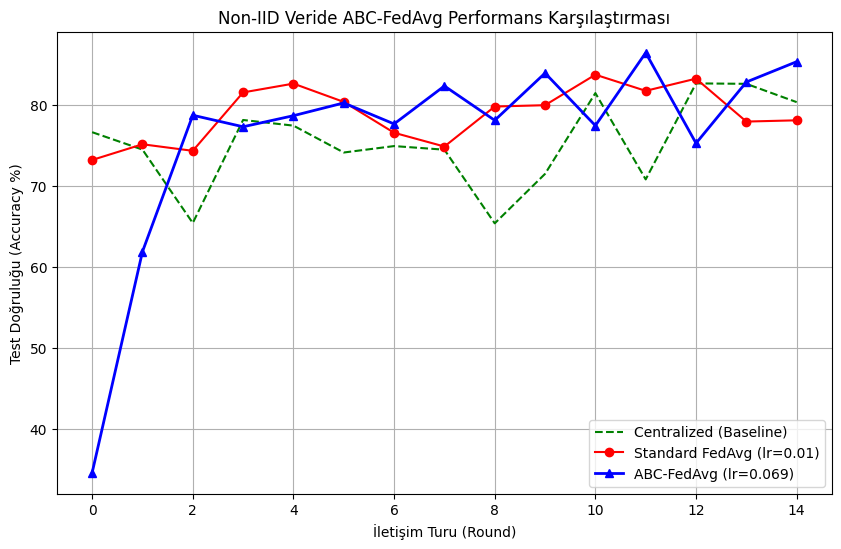
The library was used to tune a **federated learning** setup on **PathMNIST** (colon pathology images, 9 classes). The data is split across **5 simulated hospitals** with a **Dirichlet distribution (α = 0.5)**, a non-IID setting where FedAvg with default hyperparameters struggles.
|
|
211
|
+
|
|
212
|
+
`CanonicalABCSolver` searched the clients' **learning rate** (0.001–0.1) and **SGD momentum** (0.0–0.9), scoring each candidate with a short 3-round FL simulation as a proxy task. The best configuration was then trained for 15 rounds:
|
|
213
|
+
|
|
214
|
+
| Method | LR | Momentum | Test accuracy (round 15) |
|
|
215
|
+
|---|---|---|---|
|
|
216
|
+
| Standard FedAvg | 0.010 | 0.50 | 78.05% |
|
|
217
|
+
| **ABC-tuned FedAvg** | **0.069** | **0.57** | **85.28%** (+7.2 pts) |
|
|
218
|
+
|
|
219
|
+
For reference, centralized training with the default hyperparameters reached 80.29%.
|
|
220
|
+
|
|
221
|
+
|
|
222
|
+
|
|
223
|
+
📓 [Full notebook and analysis](https://github.com/yusufkorkmazyigit/abc-optimizer-lib/blob/main/examples/Federated_Learning_MedMNIST_Optimization.ipynb) · Related repo: [fedLearningwithABC](https://github.com/yusufkorkmazyigit/fedLearningwithABC)
|
|
224
|
+
|
|
225
|
+
---
|
|
226
|
+
|
|
227
|
+
## 🗺️ Roadmap
|
|
228
|
+
|
|
229
|
+
- [x] Categorical and log-scaled hyperparameters
|
|
230
|
+
- [x] `random_state` for reproducibility
|
|
231
|
+
- [x] Unit tests and continuous integration
|
|
232
|
+
- [x] Parallel cross-validation (`n_jobs`)
|
|
233
|
+
- [ ] Benchmarks against `GridSearchCV`, `RandomizedSearchCV` and Optuna
|
|
234
|
+
- [ ] Parallel evaluation of candidates within a colony
|
|
235
|
+
- [x] PyPI release
|
|
236
|
+
|
|
237
|
+
Contributions and issues are welcome.
|
|
238
|
+
|
|
239
|
+
---
|
|
240
|
+
|
|
241
|
+
## 🧪 Development
|
|
242
|
+
|
|
243
|
+
```bash
|
|
244
|
+
pip install -e ".[test]"
|
|
245
|
+
pytest
|
|
246
|
+
```
|
|
247
|
+
|
|
248
|
+
See [CHANGELOG.md](https://github.com/yusufkorkmazyigit/abc-optimizer-lib/blob/main/CHANGELOG.md) for release notes.
|
|
249
|
+
|
|
250
|
+
---
|
|
251
|
+
|
|
252
|
+
## 📚 Reference
|
|
253
|
+
|
|
254
|
+
Karaboğa, D. (2005). *An Idea Based on Honey Bee Swarm for Numerical Optimization*. Technical Report TR06, Erciyes University, Engineering Faculty, Computer Engineering Department.
|
|
255
|
+
|
|
256
|
+
If you use this library in your research, please cite the original paper above and link to this repository.
|
|
257
|
+
|
|
258
|
+
## 📝 License
|
|
259
|
+
|
|
260
|
+
Released under the [MIT License](https://github.com/yusufkorkmazyigit/abc-optimizer-lib/blob/main/LICENSE).
|
|
261
|
+
|
|
262
|
+
---
|
|
263
|
+
|
|
264
|
+
<sub>Developed by [Yusuf Korkmazyiğit](https://github.com/yusufkorkmazyigit), Computer Engineering, Erciyes University.</sub>
|
abcopt-0.2.0/README.md
ADDED
|
@@ -0,0 +1,242 @@
|
|
|
1
|
+
# 🐝 abcopt
|
|
2
|
+
|
|
3
|
+
**Canonical Artificial Bee Colony (ABC) optimization in pure Python, with a scikit-learn compatible hyperparameter search.**
|
|
4
|
+
|
|
5
|
+
[](https://pypi.org/project/abcopt/)
|
|
6
|
+
[](https://github.com/yusufkorkmazyigit/abc-optimizer-lib/actions/workflows/tests.yml)
|
|
7
|
+

|
|
8
|
+

|
|
9
|
+

|
|
10
|
+

|
|
11
|
+
|
|
12
|
+
**abcopt** is a faithful implementation of the **Artificial Bee Colony** algorithm proposed by **Derviş Karaboğa (2005)** at Erciyes University. It is useful for two things:
|
|
13
|
+
|
|
14
|
+
1. **Black-box optimization:** minimize any objective function within box constraints, with no gradients required.
|
|
15
|
+
2. **Hyperparameter tuning:** a drop-in alternative to `GridSearchCV` / `RandomizedSearchCV` for any scikit-learn compatible estimator (scikit-learn, LightGBM, XGBoost, …).
|
|
16
|
+
|
|
17
|
+
---
|
|
18
|
+
|
|
19
|
+
## ✨ Features
|
|
20
|
+
|
|
21
|
+
- **Canonical algorithm:** employed, onlooker (roulette-wheel selection) and scout bee phases, following the original paper; one dimension is perturbed per move.
|
|
22
|
+
- **scikit-learn API:** `ABCSearchCV` exposes `fit`, `predict`, `score`, `best_params_`, `best_score_` and `best_estimator_`.
|
|
23
|
+
- **Mixed search spaces:** `float` (optionally log-scaled), `int` and `categorical` hyperparameters.
|
|
24
|
+
- **Reproducible:** pass `random_state` and every run is identical.
|
|
25
|
+
- **Evaluation budget:** you set `max_evals`, so the run cost is predictable.
|
|
26
|
+
- **Robust:** failing candidates raise a warning instead of being hidden (or stop the search with `error_score="raise"`), and invalid inputs fail fast with clear messages.
|
|
27
|
+
- **Convergence history:** every run returns its best-so-far curve for plotting and comparison.
|
|
28
|
+
- **Tested:** 30 unit tests run on every push via GitHub Actions.
|
|
29
|
+
- **Lightweight:** depends only on `numpy` and `scikit-learn`.
|
|
30
|
+
|
|
31
|
+
---
|
|
32
|
+
|
|
33
|
+
## 📦 Installation
|
|
34
|
+
|
|
35
|
+
```bash
|
|
36
|
+
pip install abcopt
|
|
37
|
+
```
|
|
38
|
+
|
|
39
|
+
```python
|
|
40
|
+
from abcopt import ABCSearchCV, CanonicalABCSolver
|
|
41
|
+
```
|
|
42
|
+
|
|
43
|
+
For development:
|
|
44
|
+
|
|
45
|
+
```bash
|
|
46
|
+
git clone https://github.com/yusufkorkmazyigit/abc-optimizer-lib.git
|
|
47
|
+
cd abc-optimizer-lib
|
|
48
|
+
pip install -e ".[test]"
|
|
49
|
+
```
|
|
50
|
+
|
|
51
|
+
---
|
|
52
|
+
|
|
53
|
+
## 🚀 Quick Start
|
|
54
|
+
|
|
55
|
+
### 1. Hyperparameter tuning with `ABCSearchCV`
|
|
56
|
+
|
|
57
|
+
```python
|
|
58
|
+
import lightgbm as lgb
|
|
59
|
+
from sklearn.datasets import load_breast_cancer
|
|
60
|
+
from abcopt import ABCSearchCV
|
|
61
|
+
|
|
62
|
+
X, y = load_breast_cancer(return_X_y=True)
|
|
63
|
+
|
|
64
|
+
param_space = {
|
|
65
|
+
"learning_rate": {"type": "float", "range": (0.01, 0.3), "log": True},
|
|
66
|
+
"n_estimators": {"type": "int", "range": (50, 500)},
|
|
67
|
+
"num_leaves": {"type": "int", "range": (20, 100)},
|
|
68
|
+
"boosting_type": {"type": "categorical", "choices": ["gbdt", "dart"]},
|
|
69
|
+
}
|
|
70
|
+
|
|
71
|
+
search = ABCSearchCV(
|
|
72
|
+
estimator=lgb.LGBMClassifier(verbosity=-1),
|
|
73
|
+
param_space=param_space,
|
|
74
|
+
cv=3,
|
|
75
|
+
scoring="accuracy",
|
|
76
|
+
pop_size=20, # number of food sources
|
|
77
|
+
max_evals=100, # total objective evaluations (each one = one CV run)
|
|
78
|
+
random_state=42, # reproducible search
|
|
79
|
+
)
|
|
80
|
+
search.fit(X, y)
|
|
81
|
+
|
|
82
|
+
print("Best CV score:", search.best_score_)
|
|
83
|
+
print("Best params: ", search.best_params_)
|
|
84
|
+
y_pred = search.predict(X) # uses best_estimator_, refit on the full data
|
|
85
|
+
```
|
|
86
|
+
|
|
87
|
+
### 2. Function minimization with `CanonicalABCSolver`
|
|
88
|
+
|
|
89
|
+
```python
|
|
90
|
+
import numpy as np
|
|
91
|
+
from abcopt import CanonicalABCSolver
|
|
92
|
+
|
|
93
|
+
def sphere(x):
|
|
94
|
+
return np.sum(x ** 2) # global minimum: 0 at x = 0
|
|
95
|
+
|
|
96
|
+
solver = CanonicalABCSolver(
|
|
97
|
+
objective_func=sphere,
|
|
98
|
+
n_params=3,
|
|
99
|
+
lb=[-10, -10, -10],
|
|
100
|
+
ub=[10, 10, 10],
|
|
101
|
+
max_evals=2000,
|
|
102
|
+
random_state=0,
|
|
103
|
+
)
|
|
104
|
+
best_x, best_cost, history = solver.solve()
|
|
105
|
+
print(f"x* = {best_x}, f(x*) = {best_cost:.5f}")
|
|
106
|
+
```
|
|
107
|
+
|
|
108
|
+
### 3. Plotting convergence
|
|
109
|
+
|
|
110
|
+
```python
|
|
111
|
+
import matplotlib.pyplot as plt
|
|
112
|
+
|
|
113
|
+
evals, costs = zip(*history) # solver: best cost so far
|
|
114
|
+
# evals, scores = zip(*search.history_) # ABCSearchCV: best CV score so far
|
|
115
|
+
plt.plot(evals, costs)
|
|
116
|
+
plt.xlabel("Function evaluations")
|
|
117
|
+
plt.ylabel("Best cost")
|
|
118
|
+
plt.title("ABC convergence")
|
|
119
|
+
plt.show()
|
|
120
|
+
```
|
|
121
|
+
|
|
122
|
+
---
|
|
123
|
+
|
|
124
|
+
## 📖 API Reference
|
|
125
|
+
|
|
126
|
+
### `CanonicalABCSolver`
|
|
127
|
+
|
|
128
|
+
```python
|
|
129
|
+
CanonicalABCSolver(objective_func, n_params, lb, ub,
|
|
130
|
+
pop_size=20, max_evals=1000, limit=None, random_state=None)
|
|
131
|
+
```
|
|
132
|
+
|
|
133
|
+
| Parameter | Description |
|
|
134
|
+
|---|---|
|
|
135
|
+
| `objective_func` | Callable taking a 1-D `np.ndarray` and returning a scalar cost to **minimize** |
|
|
136
|
+
| `n_params` | Number of dimensions |
|
|
137
|
+
| `lb`, `ub` | Lower / upper bounds per dimension |
|
|
138
|
+
| `pop_size` | Number of food sources (SN) |
|
|
139
|
+
| `max_evals` | Total objective-function evaluation budget |
|
|
140
|
+
| `limit` | Trials without improvement before a source is abandoned (default: `pop_size × n_params`) |
|
|
141
|
+
| `random_state` | Seed (or `np.random.Generator`) for reproducible runs |
|
|
142
|
+
|
|
143
|
+
`NaN` objective values are treated as the worst possible cost.
|
|
144
|
+
|
|
145
|
+
`solve()` returns `(best_params, best_cost, history)`, where `history` is a list of `(eval_count, best_cost)` tuples.
|
|
146
|
+
|
|
147
|
+
### `ABCSearchCV`
|
|
148
|
+
|
|
149
|
+
```python
|
|
150
|
+
ABCSearchCV(estimator, param_space, cv=3, scoring="accuracy",
|
|
151
|
+
pop_size=20, max_evals=200, limit=None, random_state=None,
|
|
152
|
+
n_jobs=None, error_score=np.nan, refit=True, verbose=False)
|
|
153
|
+
```
|
|
154
|
+
|
|
155
|
+
**`param_space`**: one entry per hyperparameter:
|
|
156
|
+
|
|
157
|
+
| Spec | Example |
|
|
158
|
+
|---|---|
|
|
159
|
+
| Continuous | `{"type": "float", "range": (0.01, 0.3)}` |
|
|
160
|
+
| Continuous, log scale | `{"type": "float", "range": (1e-4, 1e-1), "log": True}` |
|
|
161
|
+
| Integer (both ends inclusive) | `{"type": "int", "range": (2, 12)}` |
|
|
162
|
+
| Categorical | `{"type": "categorical", "choices": ["gini", "entropy"]}` |
|
|
163
|
+
|
|
164
|
+
- **`scoring`**: any scikit-learn scorer; higher is better, exactly like `GridSearchCV` (use `neg_*` scorers for errors).
|
|
165
|
+
- **`error_score`**: score given to candidates that fail to fit (a `RuntimeWarning` is issued); `"raise"` stops the search instead.
|
|
166
|
+
- **`n_jobs`**: parallel jobs inside each cross-validation.
|
|
167
|
+
- **After `fit`:** `best_params_`, `best_score_`, `best_estimator_` (when `refit=True`), `history_`, `results_` (every candidate with its score), `n_evals_`.
|
|
168
|
+
- **Methods:** `predict`, `predict_proba`, `score`.
|
|
169
|
+
|
|
170
|
+
---
|
|
171
|
+
|
|
172
|
+
## 🧠 How ABC Works
|
|
173
|
+
|
|
174
|
+
ABC models the foraging behaviour of a honey bee colony. Each **food source** is a candidate solution, and its **nectar amount** is the solution's fitness.
|
|
175
|
+
|
|
176
|
+
| Phase | Role |
|
|
177
|
+
|---|---|
|
|
178
|
+
| **Employed bees** | Each one improves its own food source by perturbing one dimension towards or away from a random neighbour: `v_ij = x_ij + φ·(x_ij − x_kj)`, `φ ∈ [−1, 1]`. Greedy selection keeps the better solution. |
|
|
179
|
+
| **Onlooker bees** | Pick sources with probability proportional to fitness (roulette wheel), so promising regions are exploited more. |
|
|
180
|
+
| **Scout bees** | A source that has not improved for `limit` trials is abandoned and replaced by a random one, which keeps exploration alive. |
|
|
181
|
+
|
|
182
|
+
Fitness is derived from cost as `1 / (1 + f)` for `f ≥ 0` and `1 + |f|` otherwise.
|
|
183
|
+
|
|
184
|
+
---
|
|
185
|
+
|
|
186
|
+
## 🔬 Case Study: Federated Learning on MedMNIST
|
|
187
|
+
|
|
188
|
+
The library was used to tune a **federated learning** setup on **PathMNIST** (colon pathology images, 9 classes). The data is split across **5 simulated hospitals** with a **Dirichlet distribution (α = 0.5)**, a non-IID setting where FedAvg with default hyperparameters struggles.
|
|
189
|
+
|
|
190
|
+
`CanonicalABCSolver` searched the clients' **learning rate** (0.001–0.1) and **SGD momentum** (0.0–0.9), scoring each candidate with a short 3-round FL simulation as a proxy task. The best configuration was then trained for 15 rounds:
|
|
191
|
+
|
|
192
|
+
| Method | LR | Momentum | Test accuracy (round 15) |
|
|
193
|
+
|---|---|---|---|
|
|
194
|
+
| Standard FedAvg | 0.010 | 0.50 | 78.05% |
|
|
195
|
+
| **ABC-tuned FedAvg** | **0.069** | **0.57** | **85.28%** (+7.2 pts) |
|
|
196
|
+
|
|
197
|
+
For reference, centralized training with the default hyperparameters reached 80.29%.
|
|
198
|
+
|
|
199
|
+

|
|
200
|
+
|
|
201
|
+
📓 [Full notebook and analysis](https://github.com/yusufkorkmazyigit/abc-optimizer-lib/blob/main/examples/Federated_Learning_MedMNIST_Optimization.ipynb) · Related repo: [fedLearningwithABC](https://github.com/yusufkorkmazyigit/fedLearningwithABC)
|
|
202
|
+
|
|
203
|
+
---
|
|
204
|
+
|
|
205
|
+
## 🗺️ Roadmap
|
|
206
|
+
|
|
207
|
+
- [x] Categorical and log-scaled hyperparameters
|
|
208
|
+
- [x] `random_state` for reproducibility
|
|
209
|
+
- [x] Unit tests and continuous integration
|
|
210
|
+
- [x] Parallel cross-validation (`n_jobs`)
|
|
211
|
+
- [ ] Benchmarks against `GridSearchCV`, `RandomizedSearchCV` and Optuna
|
|
212
|
+
- [ ] Parallel evaluation of candidates within a colony
|
|
213
|
+
- [x] PyPI release
|
|
214
|
+
|
|
215
|
+
Contributions and issues are welcome.
|
|
216
|
+
|
|
217
|
+
---
|
|
218
|
+
|
|
219
|
+
## 🧪 Development
|
|
220
|
+
|
|
221
|
+
```bash
|
|
222
|
+
pip install -e ".[test]"
|
|
223
|
+
pytest
|
|
224
|
+
```
|
|
225
|
+
|
|
226
|
+
See [CHANGELOG.md](https://github.com/yusufkorkmazyigit/abc-optimizer-lib/blob/main/CHANGELOG.md) for release notes.
|
|
227
|
+
|
|
228
|
+
---
|
|
229
|
+
|
|
230
|
+
## 📚 Reference
|
|
231
|
+
|
|
232
|
+
Karaboğa, D. (2005). *An Idea Based on Honey Bee Swarm for Numerical Optimization*. Technical Report TR06, Erciyes University, Engineering Faculty, Computer Engineering Department.
|
|
233
|
+
|
|
234
|
+
If you use this library in your research, please cite the original paper above and link to this repository.
|
|
235
|
+
|
|
236
|
+
## 📝 License
|
|
237
|
+
|
|
238
|
+
Released under the [MIT License](https://github.com/yusufkorkmazyigit/abc-optimizer-lib/blob/main/LICENSE).
|
|
239
|
+
|
|
240
|
+
---
|
|
241
|
+
|
|
242
|
+
<sub>Developed by [Yusuf Korkmazyiğit](https://github.com/yusufkorkmazyigit), Computer Engineering, Erciyes University.</sub>
|